Deep Visual Geo-localization Benchmark

Gabriele Moreno BertonRiccardo MereuGabriele TrivignoCarlo MasoneGabriela CsurkaTorsten SattlerBarbara Caputo

article2022CVPR114 citations

Establishes a modular visual geo-localization benchmarking framework and conducts extensive evaluations across pipeline components, offering practical guidelines that balance retrieval accuracy with real-world computational and memory costs.

Listen

Visual geo-localization involves estimating the geographic position of a query photograph by matching it against a database of geo-tagged imagery. This capability is critical for autonomous systems, robotics, and mapping applications. However, existing research disproportionately focuses on optimizing recognition recall metrics while neglecting practical system constraints such as processing latency, memory usage, and hardware scalability. Furthermore, standard evaluation practices compare off-the-shelf models trained across inconsistent setups, obscuring the actual drivers of performance.

The article aims to systematically evaluate how individual architectural and engineering choices impact visual geo-localization performance and resource consumption under unified conditions. To achieve this, the authors built an open-source modular benchmarking framework and evaluated dozens of pipeline configurations across six diverse, real-world datasets, including Pitts30k and Mapillary Street-Level Sequences. Experiments measured localization accuracy alongside hardware-agnostic computational indicators such as floating-point operations, extraction latency, and memory footprints.

The investigation produced several key findings. First, standard convolutional neural network backbones like ResNet-50 provide an optimal balance of accuracy and efficiency, delivering recall comparable to larger networks with less than half the model size and floating-point operations. Second, Compact Convolutional Transformers combined with NetVLAD feature aggregation outperformed traditional architectures while maintaining low compute costs. Third, partial negative mining reduced training complexity without sacrificing retrieval quality compared to full-database mining. Fourth, downscaling image resolution to 60% or 80% achieved comparable or superior localization accuracy while decreasing extraction latency and data storage requirements by up to 36% or more. Finally, advanced approximate nearest neighbor search techniques reduced matching latency and RAM consumption by approximately 98.5% with only minimal loss in recall.

These results demonstrate that visual geo-localization systems do not necessarily require complex, heavyweight architectures or full-resolution images to achieve state-of-the-art results. Instead, substantial efficiency and cost improvements stem from practical engineering adjustments such as index compression, image downsampling, and robust data augmentations. Neglecting nearest-neighbor indexing optimizations creates severe operational bottlenecks, as retrieval time scales directly with database size and descriptor length.

Organizations developing or deploying visual geo-localization technologies should prioritize end-to-end system optimization over single-metric model selection. Specifically, engineering teams should implement partial database mining during training, resize input images to between 60% and 80% of standard resolution, and adopt indexed search methods like inverted file product quantization for production querying. The conclusions carry high confidence within outdoor urban environments, though decision-makers should note that evaluations were limited to single-image outdoor settings and did not assess extreme viewpoint variations or recent alternative loss formulations.

Cover for Deep Visual Geo-localization Benchmark

Abstract

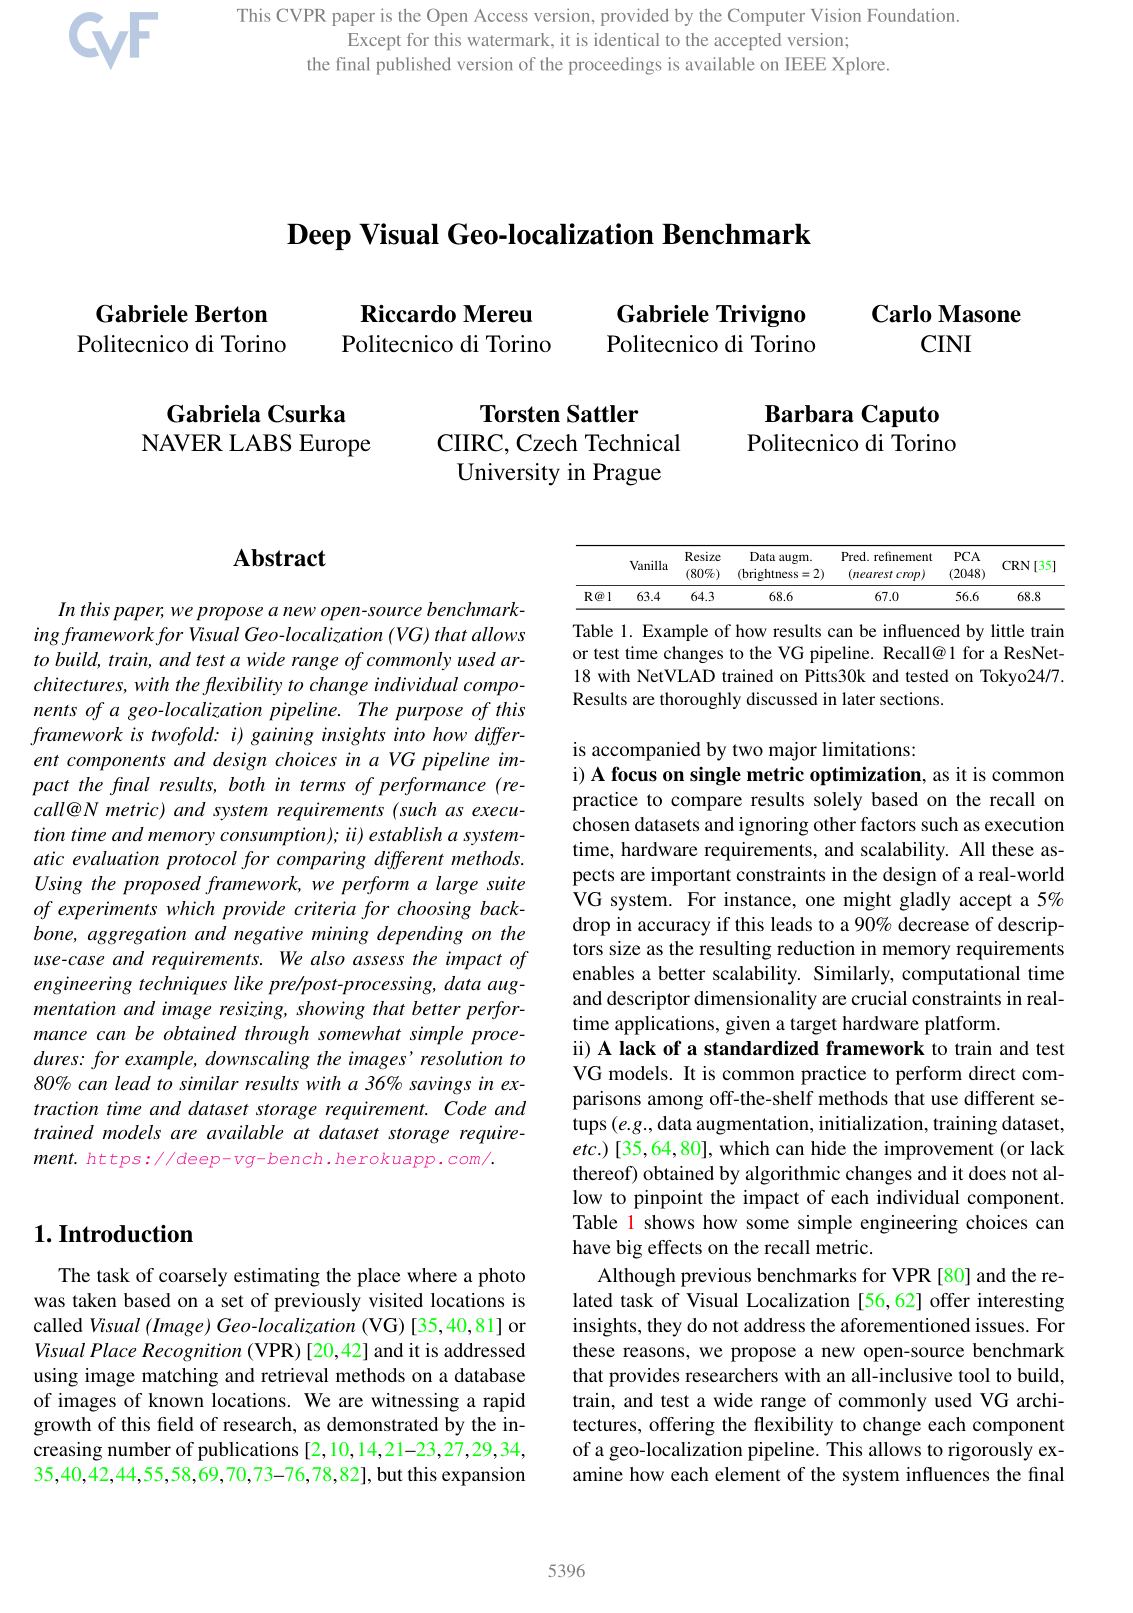
In this paper, we propose a new open-source benchmark-ing framework for Visual Geo-localization (VG) that allows to build, train, and test a wide range of commonly used ar-chitectures, with the flexibility to change individual compo-nents of a geo-localization pipeline. The purpose of this framework is twofold: i) gaining insights into how differ-ent components and design choices in a VG pipeline im-pact the final results, both in terms of performance (re-call@N metric) and system requirements (such as execu-tion time and memory consumption); ii) establish a system-atic evaluation protocol for comparing different methods. Using the proposed framework, we perform a large suite of experiments which provide criteria for choosing back-bone, aggregation and negative mining depending on the use-case and requirements. We also assess the impact of engineering techniques like pre/post-processing, data aug-mentation and image resizing, showing that better perfor-mance can be obtained through somewhat simple proce-dures: for example, downscaling the images' resolution to 80% can lead to similar results with a 36% savings in ex-traction time and dataset storage requirement. Code and trained models are available at dataset storage require-ment. https://deep-vg-bench.herokuapp.com/.

Table of Contents

  • 1. Introduction
  • 2. Related Work
  • 3. Methodology
  • 3.1. Visual Geo-localization System
  • 3.2. Datasets
  • 3.3. Benchmark Protocol
  • 4. Results
  • 4.1. CNN Backbones
  • 4.2. Aggregation and Descriptor Dimensionality
  • 4.3. Visual Transformers
  • 4.4. Negative Mining
  • 4.5. Data Augmentation
  • 4.6. Resize
  • 4.7. Nearest Neighbor Search and Inference Time
  • 5. Discussions and Findings
  • References

Knowls

  1. Knowl 1 — Visual Geo-localization Pipeline and Standard Evaluation Protocol

    experimental setup

    Visual Geo-localization (VG) is formulated as an image retrieval task where a query image qq is localized by finding the nearest neighbor matches within a database of geo-tagged images D={d1,d2,…,d∣D∣}D = \{d_1, d_2, \dots, d_{|D|}\}. Feature representations are extracted via a backbone network and aggregated into a global descriptor vector x∈RD\mathbf{x} \in \mathbb{R}^D, which is subsequently L2L_2-normalized.

    Training is conducted using a triplet metric learning objective with batches containing 4 triplets. Each triplet consists of an anchor (the query image qq), one positive database image pp, and 10 negative database images {n1,…,n10}\{n_1, \dots, n_{10}\}. Positives are selected as the database image nearest to the query in feature space among those located within a 10-meter geographic radius of the query (d(q,p)≤10 md(q, p) \le 10\,\text{m}). Negatives are chosen from database images located further than 25 meters (d(q,ni)>25 md(q, n_i) > 25\,\text{m}). Optimization uses the Adam optimizer. An epoch is defined as 5,000 queries, and training terminates when Recall@5 on the validation set fails to improve for 3 consecutive epochs.

    The standard evaluation metric is Recall@NN (R@NN), defined as the percentage of test queries for which at least one of the top-NN retrieved database images lies within a geographic distance threshold of 25 meters from the ground-truth query position.

  2. Knowl 2 — Convolutional Backbone Performance and Computational Requirements in Visual Geo-localization

    data/table

    The choice of CNN backbone determines the trade-off between feature extraction speed, parameter footprint, and retrieval recall across datasets. For ResNet architectures (ResNet-18, ResNet-50, ResNet-101), feature maps are extracted from the conv4_x layer; for VGG-16, features are extracted from all convolutional layers prior to the classifier pooling layer. The table below presents computational requirements and Recall@1 (R@1, %) on six benchmark datasets (Pitts30k, MSLS, Tokyo 24/7, Revisited San Francisco [R-SF], Eynsham, and St Lucia) when trained on either the small Pitts30k dataset or the large Mapillary Street-Level Sequences (MSLS) dataset.

    Backbone Aggreg. Dim FLOPs Size Time Training on Pitts30k (R@1) Training on MSLS (R@1)
    Method (GF) (MB) (ms) Pitts MSLS Tok R-SF Eyn StL Pitts MSLS Tok R-SF Eyn StL
    VGG-16 GeM 512 188.01 56.13 12.3 78.5 43.4 39.9 40.4 70.2 46.4 70.2 66.7 43.6 32.1 80.4 79.9
    ResNet-18 GeM 256 17.29 10.63 4.1 77.8 35.3 35.3 34.2 64.3 46.2 71.6 65.3 42.8 30.5 80.3 83.2
    ResNet-50 GeM 1024 40.61 32.71 6.7 82.0 38.0 41.5 45.4 66.3 59.0 77.4 72.0 55.4 45.7 83.9 91.2
    ResNet-101 GeM 1024 86.29 105.36 9.6 82.4 39.6 44.0 52.5 69.0 57.6 77.2 72.5 51.0 46.9 83.6 91.6
    VGG-16 NetVLAD 32768 188.09 56.38 13.0 83.2 50.9 61.4 64.6 74.4 50.1 79.0 74.6 61.9 57.1 84.2 86.7
    ResNet-18 NetVLAD 16384 17.27 10.76 4.4 86.4 47.4 63.4 61.4 76.8 57.6 81.6 75.8 62.3 55.1 87.1 92.1
    ResNet-50 NetVLAD 65536 40.51 33.21 8.5 86.0 50.7 69.8 67.1 77.7 60.2 80.9 76.9 62.8 51.5 87.2 93.8
    ResNet-101 NetVLAD 65536 86.06 105.86 11.5 86.5 51.8 72.2 67.5 74.0 63.6 80.8 77.7 59.0 56.1 86.7 95.1

    ResNet-50 matches the Recall@1 of ResNet-101 across benchmarks while requiring less than half the FLOPs (40.51--40.61 GF vs. 86.06--86.29 GF) and less than one-third the parameter memory size (~33 MB vs. ~105 MB). ResNet-18 provides the fastest feature extraction (4.1--4.4 ms) with lowest compute (17.27--17.29 GF). The scale of the training dataset significantly affects generalization: training on MSLS rather than Pitts30k produces an improvement of over 30 percentage points on St Lucia.

  3. Knowl 3 — Visual Transformers and Compact Convolutional Transformers in Visual Geo-localization

    data/table

    Vision Transformers (ViT) and Compact Convolutional Transformers (CCT) serve as alternatives to traditional CNN backbones in visual geo-localization. In ViT and CCT, global image descriptors can be formed directly using the sequence classification token ([CLS]), avoiding specialized aggregation layers, or coupled with aggregation modules such as GeM, SeqPool, and NetVLAD. The table below compares CNN backbones and Transformer architectures trained on the MSLS dataset across six evaluation benchmarks.

    Backbone Aggregation Feature FLOPs Training on MSLS (Recall@1, %)
    Method Dim (GF) Pitts30k MSLS Tokyo 24/7 R-SF Eynsham St Lucia
    ResNet-18 GeM 256 17.29 71.6 65.3 42.8 30.5 80.3 83.2
    ResNet-50 GeM 1024 40.61 77.4 72.0 55.4 45.7 83.9 91.2
    ViT CLS token 768 82.31 82.9 73.5 59.9 65.0 84.5 93.6
    CCT CLS token 384 22.34 79.6 71.1 52.0 49.9 85.6 94.0
    CCT SeqPool 384 26.19 81.4 71.0 59.1 60.5 86.1 92.4
    CCT GeM 384 22.36 78.7 72.0 48.8 48.6 83.9 92.9
    ResNet-18 NetVLAD 16384 17.27 81.6 75.8 62.3 55.1 87.1 92.1
    ResNet-50 NetVLAD 65536 40.51 80.9 76.9 62.3 51.5 87.2 93.8
    CCT NetVLAD 24576 18.53 85.1 79.9 70.3 65.9 87.4 98.4

    CCT with CLS token or SeqPool outperforms ResNet-18 while remaining compute-efficient (~22--26 GF). When paired with NetVLAD, CCT achieves the highest overall accuracy across all evaluation sets (Pitts30k 85.1%, MSLS 79.9%, Tokyo 24/7 70.3%, R-SF 65.9%, Eynsham 87.4%, St Lucia 98.4%) at a computational budget of 18.53 GF, outperforming ResNet-50 + NetVLAD (40.51 GF).

  4. Knowl 4 — Performance and Dimensionality Equalization of Feature Aggregators

    data/table

    Feature aggregation modules convert convolutional feature maps into global image embeddings. Comparing aggregators with differing native dimensionality requires normalizing descriptor lengths using Principal Component Analysis (PCA) or linear Fully Connected (FC) projection layers. The table below reports Recall@1 (R@1, %) for ResNet-50 paired with Generalized Mean (GeM) pooling, NetVLAD, and Contextual Reweighting Network (CRN) across equalized descriptor sizes (1024, 2048, and 65536 dimensions).

    Method Dim Training on Pitts30k (R@1) Training on MSLS (R@1) Avg
    Pitts MSLS Tok R-SF Eyn StL Pitts MSLS Tok R-SF Eyn StL
    GeM 1024 82.0 38.0 41.5 45.4 66.3 59.0 77.4 72.0 55.4 45.7 83.9 91.2 63.2
    NetVLAD + PCA 1024 83.9 46.5 59.4 53.2 72.5 57.7 77.4 74.8 51.3 39.0 85.2 92.9 66.2
    CRN + PCA 1024 84.1 49.9 64.6 58.8 74.3 63.4 77.3 75.6 51.8 38.8 85.7 94.1 68.2
    GeM + FC 2048 80.1 33.7 43.6 48.2 70.0 56.0 79.2 73.5 64.0 55.1 86.1 90.3 65.0
    NetVLAD + PCA 2048 84.4 47.9 62.6 56.0 74.1 58.9 78.5 75.4 52.8 42.6 85.8 93.4 67.7
    CRN + PCA 2048 84.7 51.2 67.1 62.3 75.8 65.0 78.3 76.3 54.3 42.8 86.2 94.4 69.9
    GeM + FC 65536 80.8 35.8 45.6 49.0 72.5 59.6 79.0 74.4 69.2 58.4 86.2 90.8 66.8
    NetVLAD 65536 86.0 50.7 69.8 67.1 77.7 60.2 80.9 76.9 62.8 51.5 87.2 93.8 72.1
    CRN 65536 85.8 54.0 73.1 70.9 79.7 65.9 80.8 77.8 63.6 53.4 87.5 94.8 73.9

    When trained on the smaller Pitts30k dataset, CRN yields the highest average Recall@1 (73.9% at 65536-d, 68.2% at 1024-d). However, training CRN requires a two-stage process that approximately doubles training duration and triples the hyperparameter count compared to NetVLAD. When trained on the larger and more diverse MSLS dataset, GeM generalizes better on out-of-domain datasets with different camera perspectives (Tokyo 24/7 and R-SF). Reducing NetVLAD or CRN dimensionality via PCA causes consistent drops in recall.

  5. Knowl 5 — Negative Mining Strategies and Complexity in Triplet Training

    data/table

    In metric learning for visual geo-localization, mining informative negative database examples during training determines model convergence and representation quality. Triplet caches are rebuilt periodically (typically after 1,000 triplets). Let #db\#\text{db} denote the total number of database images, #q\#\text{q} the total number of queries, kdbk_{\text{db}} and kqk_{\text{q}} predefined subset constants (typically set to 1,000), and #pos\#\text{pos} the number of positives for the considered queries. The table below presents the cache space/time complexity and Recall@1 (%) for ResNet-18 paired with GeM or NetVLAD under three negative mining strategies.

    Backbone Aggreg. Mining Complexity Training on Pitts30k (R@1) Training on MSLS (R@1)
    Method Method Pitts MSLS Tok R-SF Eyn StL Pitts MSLS Tok R-SF Eyn StL
    ResNet-18 GeM Random O(1)\mathcal{O}(1) 73.7 30.5 31.3 24.0 58.2 41.0 62.2 50.6 28.8 17.1 70.2 71.4
    ResNet-18 GeM Full O(#db+#q)\mathcal{O}(\#\text{db} + \#\text{q}) 77.8 35.3 35.3 34.2 64.3 46.2 70.1 61.8 42.8 31.3 79.3 81.0
    ResNet-18 GeM Partial O(kdb+kq+#pos)\mathcal{O}(k_{\text{db}} + k_{\text{q}} + \#\text{pos}) 76.5 34.2 33.9 32.9 64.0 45.6 71.6 65.3 42.8 30.5 80.3 83.2
    ResNet-18 NetVLAD Random O(1)\mathcal{O}(1) 83.9 43.6 55.1 53.8 76.3 53.5 73.3 61.5 45.0 34.8 84.9 79.7
    ResNet-18 NetVLAD Full O(#db+#q)\mathcal{O}(\#\text{db} + \#\text{q}) 86.4 47.4 63.4 61.4 76.8 57.6 — — — — — —
    ResNet-18 NetVLAD Partial O(kdb+kq+#pos)\mathcal{O}(k_{\text{db}} + k_{\text{q}} + \#\text{pos}) 86.2 47.3 61.2 62.9 76.6 57.1 81.6 75.8 62.3 55.1 87.1 92.1

    Random negative sampling degrades R@1 by an average of 5% on Pitts30k and over 10% on MSLS. Partial database mining matches full database mining within approximately 1% R@1 while reducing the cache complexity from linear in the full database size O(#db+#q)\mathcal{O}(\#\text{db} + \#\text{q}) to bounded constant sub-sampling O(kdb+kq+#pos)\mathcal{O}(k_{\text{db}} + k_{\text{q}} + \#\text{pos}), making metric learning tractable on large datasets such as MSLS.

  6. Knowl 6 — Effect of Input Image Downscaling on Accuracy and Computational Cost

    empirical result

    Downscaling input image dimensions during training and testing preserves or improves geo-localization performance while substantially reducing compute and memory footprints.

    Scaling input resolution by a linear factor s∈(0,1]s \in (0, 1] scales the required Floating Point Operations (FLOPs) and image storage memory quadratically by s2s^2: FLOPs(s)=s2⋅FLOPs(1.0)\text{FLOPs}(s) = s^2 \cdot \text{FLOPs}(1.0) Storage(s)=s2⋅Storage(1.0)\text{Storage}(s) = s^2 \cdot \text{Storage}(1.0)

    Empirical evaluations training and testing on Pitts30k with linear scaling factors from 80%80\% down to 20%20\% demonstrate that:

    1. Scaling to 80%80\% (s=0.8s=0.8) achieves equivalent or superior Recall@1 across all test sets while yielding a 36%36\% reduction in FLOPs, extraction time, and raw storage (s2=0.64s^2 = 0.64).
    2. Scaling down to 60%60\% (s=0.6s=0.6, a 64%64\% compute reduction) maintains competitive retrieval performance on in-domain test sets.
    3. Under significant domain shift between training and test sets (e.g., training on Pitts30k panorama crops and testing on St Lucia forward-view images), downscaling to 40%40\% (s=0.4s=0.4, reducing image resolution from 480×640480\times 640 to 192×256192\times 256 and FLOPs by 84%84\%) yields the highest Recall@1. This occurs because aggressive downscaling removes domain-specific high-frequency textures and foliage patterns that cause overfitting.
  7. Knowl 7 — Impact of Data Augmentation Techniques on Visual Geo-localization Robustness

    empirical result

    The effectiveness of data augmentation during training depends on domain similarity between training and evaluation datasets:

    1. In-Domain Evaluation: Applying data augmentation to query images when training and evaluating on the same homogeneous dataset (Pitts30k) slightly degrades or leaves Recall@1 unchanged, as the training distribution already matches the test distribution.
    2. Cross-Domain Transfer: Color jittering transformations (adjusting brightness, contrast, and saturation) significantly boost transfer accuracy to unseen domains. Specifically, setting a color jitter contrast multiplier up to 2.02.0 increases Recall@1 by over 3%3\% on MSLS, 5%5\% on Tokyo 24/7, and 5%5\% on St Lucia for a ResNet-18 + NetVLAD model, with less than a 1%1\% reduction on Pitts30k and Eynsham.
    3. General Augmentations: Random horizontal flipping applied consistently across all images in a triplet (with probability p=0.5p=0.5) and random resized cropping (with crop scales down to 50%50\% of original dimensions, subsequently resized to full resolution) provide consistent performance gains across both in-domain and out-of-domain benchmarks.
  8. Knowl 8 — Inference Bottlenecks and Approximate Nearest Neighbor Indexing Trade-offs

    empirical result

    In visual geo-localization pipelines, inference delay tit_i consists of feature extraction time tet_e and nearest neighbor descriptor matching time tmt_m: ti=te+tmt_i = t_e + t_m

    While feature extraction time tet_e remains constant at approximately 10 ms10\,\text{ms} per image (independent of database scale), exhaustive linear matching time tmt_m scales linearly with database size NdbN_{\text{db}} and descriptor dimensionality DD (tm=O(Ndb⋅D)t_m = \mathcal{O}(N_{\text{db}} \cdot D)). As a general operational threshold, exact kNNk\text{NN} search becomes the dominant latency bottleneck (tm>tet_m > t_e) when the product of database size and descriptor dimension exceeds 200 million (Ndb⋅D>2×10⁸N_{\text{db}} \cdot D > 2 \times 10^8).

    Approximate Nearest Neighbor (ANN) search algorithms provide trade-offs between matching speed, RAM usage, and Recall@1:

    1. Inverted File with Product Quantization (IVFPQ): On the Revisited San Francisco dataset (1.05M images) with ResNet-50 + GeM (D=1024D=1024), IVFPQ reduces matching time and memory footprint by 98.5%98.5\% compared to exhaustive search, while incurring only a minor drop in Recall@1 from 45.4%45.4\% to 41.4%41.4\%.
    2. Inverted Multi-Index (MultiIndex): Achieves an 80%80\% reduction in matching time with only a 0.9%0.9\% decrease in Recall@1 at identical RAM consumption compared to baseline inverted file indexing.
    3. Hierarchical Navigable Small World graphs (HNSW) and Product Quantization (PQ): Substantially reduce query latency, enabling sub-linear retrieval times on large-scale databases.
  9. Knowl 9 — Optimization of Standard ResNet-18 + NetVLAD Pipeline Against Complex SOTA Methods

    data/table

    Combining isolated engineering optimizations—data augmentation (color jittering and horizontal flip), input image downscaling to 80%80\%, and query post-processing via majority voting—enables a standard ResNet-18 + NetVLAD architecture to match or outperform complex state-of-the-art models.

    The table below reports Recall@1 (%) on Pitts30k, Pitts250k, and Tokyo 24/7 comparing published methods against the optimized ResNet-18 + NetVLAD baseline trained on Pitts30k.

    Method Feature Recall@1 (%)
    Dim Pitts30k Pitts250k Tokyo 24/7
    VGG16 + NetVLAD + PCA 4096 85.2 86.5 68.9
    VGG16 + NetVLAD 32768 — 84.1 60.0
    SRALNet 4096 — 87.8 72.1
    SRALNet 32768 85.1 85.8 68.6
    APPSVR 4096 87.4 88.8 77.1
    APPSVR 32768 — 86.6 68.3
    ResNet-18 + NetVLAD + PCA (Optimized) 4096 86.8 87.9 72.2
    ResNet-18 + NetVLAD (Optimized) 16384 87.2 88.1 73.7

    With systematic pipeline optimization, the standard ResNet-18 + NetVLAD model achieves 87.2%87.2\% on Pitts30k, 88.1%88.1\% on Pitts250k, and 73.7%73.7\% on Tokyo 24/7, matching or exceeding specialized attention and residual architectures (such as SRALNet) without requiring custom architectural modules.

Coverage note — Ablations from the supplementary material regarding secondary pooling variants (SPOC, MAC, RRM) and minor pre-training settings were omitted to maintain focus on the main paper's primary contributions.

References

  1. 1.R. Arandjelovic and Andrew Zisserman. Three things every- ´ one should know to improve object retrieval. 2012 IEEE Conference on Computer Vision and Pattern Recognition, pages 2911–2918, 2012.
  2. 2.Relja Arandjelovic, Petr Gronat, Akihiko Torii, Tomas Pa- ´ jdla, and Josef Sivic. NetVLAD: CNN architecture for weakly supervised place recognition. IEEE Transactions on Pattern Analysis and Machine Intelligence, 40(6):1437– 1451, 2018.
  3. 3.Relja Arandjelovic and Andrew Zisserman. Dislocation: ´ Scalable descriptor distinctiveness for location recognition. In Daniel Cremers, Ian D. Reid, Hideo Saito, and Ming- Hsuan Yang, editors, Computer Vision - ACCV 2014 - 12th Asian Conference on Computer Vision, Singapore, Singa- pore, November 1-5, 2014, Revised Selected Papers, Part IV, volume 9006 of Lecture Notes in Computer Science, pages 188–204. Springer, 2014.
  4. 4.Hossein Azizpour, Ali Razavian, Josephine Sullivan, Atsuto Maki, and Stefan Carlsson. Factors of transferability for a generic convnet representation. IEEE Transactions on Pat- tern Analysis and Machine Intelligence, 38, 11 2015.
  5. 5.Artem Babenko and Victor Lempitsky. Aggregating deep convolutional features for image retrieval. ICCV, 10 2015.
  6. 6.Artem Babenko and Victor S. Lempitsky. The inverted multi- index. In CVPR, pages 3069–3076. IEEE Computer Society, 2012.
  7. 7.Artem Babenko, Anton Slesarev, A. Chigorin, and V. Lempitsky. Neural codes for image retrieval. ArXiv, abs/1404.1777, 2014.
  8. 8.Herbert Bay, Andreas Ess, Tinne Tuytelaars, and Luc Van Gool. Speeded-up robust features (surf). Computer Vi- sion and Image Understanding, 110:346–359, 06 2008.
  9. 9.Gabriele Berton, Carlo Masone, Valerio Paolicelli, and Bar- bara Caputo. Viewpoint Invariant Dense Matching for Visual Geolocalization. In IEEE International Conference on Com- puter Vision, 2021.
  10. 10.Gabriele Moreno Berton, Valerio Paolicelli, Carlo Masone, and Barbara Caputo. Adaptive-attentive geolocalization from few queries: A hybrid approach. In IEEE Winter Con- ference on Applications of Computer Vision, pages 2918– 2927, January 2021.
  11. 11.B. Cao, A. Araujo, and J. Sim. Unifying deep local and global features for image search. In European Conference on Computer Vision, pages 726–743. Springer Int. Publishing, 2020.
  12. 12.Mathilde Caron, Hugo Touvron, Ishan Misra, Herve J ´ egou, ´ Julien Mairal, Piotr Bojanowski, and Armand Joulin. Emerg- ing properties in self-supervised vision transformers. In IEEE International Conference on Computer Vision, pages 9650–9660, October 2021.
  13. 13.D. M. Chen, G. Baatz, K. Koser, S. S. Tsai, R. Vedantham, ¨ T. Pylvan¨ ainen, K. Roimela, X. Chen, J. Bach, M. Pollefeys, ¨ B. Girod, and R. Grzeszczuk. City-scale landmark identifi- cation on mobile devices. In IEEE Conference on Computer Vision and Pattern Recognition, pages 737–744, 2011.
  14. 14.Zetao Chen, Adam Jacobson, Niko Sunderhauf, Ben Up- ¨ croft, Lingqiao Liu, Chunhua Shen, Ian Reid, and Michael Milford. Deep learning features at scale for visual place recognition. In 2017 IEEE International Conference on Robotics and Automation (ICRA), pages 3223–3230, 2017.
  15. 15.Gabriela Csurka, Christopher Dance, Lixin Fan, Jutta Willamowski, and Cedric Bray. Visual categorization with ´ bags of keypoints. In European Conference on Computer Vision, volume Vol. 1, 01 2004.
  16. 16.M. Cummins and P. Newman. Highly scalable appearance- only slam - FAB-MAP 2.0. In Robotics: Science and Sys- tems, 2009.
  17. 17.Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Syl- vain Gelly, Jakob Uszkoreit, and Neil Houlsby. An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. ArXiv, abs/2010.11929, 2021.
  18. 18.Alaaeldin El-Nouby, Natalia Neverova, Ivan Laptev, and Herve J ´ egou. Training vision transformers for image re- ´ trieval. ArXiv, abs/2102.05644, 2021.
  19. 19.Matthew Gadd, D. Martini, and P. Newman. Look around you: Sequence-based radar place recognition with learned rotational invariance. 2020 IEEE/ION Position, Location and Navigation Symposium (PLANS), pages 270–276, 2020.
  20. 20.Sourav Garg, Tobias Fischer, and Michael Milford. Where is your place, visual place recognition? In Zhi-Hua Zhou, edi- tor, Proceedings of the Thirtieth International Joint Confer- ence on Artificial Intelligence, IJCAI-21, pages 4416–4425. International Joint Conferences on Artificial Intelligence Or- ganization, 8 2021. Survey Track.
  21. 21.Sourav Garg, Ben Harwood, G. Anand, and Michael Mil- ford. Delta descriptors: Change-based place representation for robust visual localization. IEEE Robotics and Automa- tion Letters, 5:5120–5127, 2020.
  22. 22.Sourav Garg and Michael Milford. Seqnet: Learning de- scriptors for sequence-based hierarchical place recognition. IEEE Robotics and Automation Letters, 6:4305–4312, 2021.
  23. 23.Yixiao Ge, Haibo Wang, Feng Zhu, Rui Zhao, and Hong- sheng Li. Self-supervising fine-grained region similari- ties for large-scale image localization. In Andrea Vedaldi, Horst Bischof, Thomas Brox, and Jan-Michael Frahm, edi- tors, Computer Vision – ECCV 2020, pages 369–386, Cham, 2020. Springer International Publishing.
  24. 24.Albert Gordo, Jon Almazan, J ´ er´ ome Revaud, and Diane Lar- ˆ lus. Deep image retrieval: Learning global representations for image search. In ECCV, 2016.
  25. 25.A. Gordo, J. Almazan, J. Revaud, and D. Larlus. End-to-end learning of deep visual representations for image retrieval. IJCV, 2017.
  26. 26.Ali Hassani, Steven Walton, Nikhil Shah, Abulikemu Abuduweili, Jiachen Li, and Humphrey Shi. Escaping the Big Data Paradigm with Compact Transformers. ArXiv, abs/2104.05704, 2021.
  27. 27.Stephen Hausler, Sourav Garg, Ming Xu, Michael Milford, and Tobias Fischer. Patch-netvlad: Multi-scale fusion of locally-global descriptors for place recognition. In Proceed- ings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 14141–14152, 2021.
  28. 28.K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In IEEE Conference on Computer Vision and Pattern Recognition, pages 770–778, 2016.
  29. 29.Ziyang Hong, Yvan Petillot, David Lane, Yishu Miao, and Sen Wang. Textplace: Visual place recognition and topolog- ical localization through reading scene texts. In Proceedings of the IEEE/CVF International Conference on Computer Vi- sion (ICCV), October 2019.
  30. 30.H. Jegou and Andrew Zisserman. Triangulation embedding ´ and democratic aggregation for image search. 2014 IEEE Conference on Computer Vision and Pattern Recognition, pages 3310–3317, 2014.
  31. 31.H. Jegou, M. Douze, and C. Schmid. Hamming embed- ´ ding and weak geometric consistency for large scale image search. In D. Forsyth, P. Torr, and A. Zisserman, editors, European Conference on Computer Vision, pages 304–317, Berlin, Heidelberg, 2008. Springer Berlin Heidelberg.
  32. 32.Herve J ´ egou, Matthijs Douze, and Cordelia Schmid. Prod- ´ uct quantization for nearest neighbor search. IEEE Trans. Pattern Anal. Mach. Intell., 33(1):117–128, 2011.
  33. 33.Herve J ´ egou, Matthijs Douze, Jorge S ´ anchez, Patrick Perez, ´ and Cordelia Schmid. Aggregating local image descriptors into compact codes. IEEE transactions on pattern analysis and machine intelligence, 34, 12 2011.
  34. 34.A. Khaliq, S. Ehsan, Z. Chen, M. Milford, and K. McDonald-Maier. A holistic visual place recognition ap- proach using lightweight CNNs for significant viewpoint and appearance changes. IEEE Transactions on Robotics, 36(2):561–569, 2020.
  35. 35.Hyo Jin Kim, Enrique Dunn, and Jan-Michael Frahm. Learned contextual feature reweighting for image geo- localization. In 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), pages 3251–3260, 2017.
  36. 36.Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. International Conference on Learn- ing Representations, 12 2014.
  37. 37.Giorgos Kordopatis-Zilos, Panagiotis Galopoulos, S. Pa- padopoulos, and Y. Kompatsiaris. Leveraging efficientnet and contrastive learning for accurate global-scale location estimation. ACM International Conference on Multimedia Retrieval, 2021.
  38. 38.Yunpeng Li, Noah Snavely, Daniel Huttenlocher, and Pascal Fua. Worldwide Pose Estimation using 3D Point Clouds. In European Conference on Computer Vision, 2012.
  39. 39.Dongfang Liu, Yiming Cui, Liqi Yan, Christos Mousas, Bai- jian Yang, and Yingjie Chen. DenserNet: Weakly super- vised visual localization using multi-scale feature aggrega- tion. Proceedings of the AAAI Conference on Artificial Intel- ligence, pages 6101–6109, May 2021.
  40. 40.Liu Liu, Hongdong Li, and Yuchao Dai. Stochastic Attraction-Repulsion Embedding for Large Scale Image Lo- calization. In IEEE International Conference on Computer Vision, 2019.
  41. 41.David G. Lowe. Distinctive image features from scale- invariant keypoints. Int. J. Comput. Vision, 60(2):91–110, 2004.
  42. 42.Stephanie Lowry, Niko Sunderhauf, Paul Newman, John J. ¨ Leonard, David Cox, Peter Corke, and Michael J. Milford. Visual place recognition: A survey. IEEE Transactions on Robotics, 32(1):1–19, 2016.
  43. 43.Yu A. Malkov and D. A. Yashunin. Efficient and robust ap- proximate nearest neighbor search using hierarchical naviga- ble small world graphs. IEEE Transactions on Pattern Anal- ysis and Machine Intelligence, 42:824–836, 2020.
  44. 44.Carlo Masone and Barbara Caputo. A survey on deep visual place recognition. IEEE Access, 9:19516–19547, 2021.
  45. 45.Michael Milford and G. Wyeth. Mapping a suburb with a sin- gle camera using a biologically inspired slam system. IEEE Transactions on Robotics, 24:1038–1053, 2008.
  46. 46.Eva Mohedano, Kevin McGuinness, Xavier Giro i Nieto, and N. O’Connor. Saliency weighted convolutional features for instance search. 2018 International Conference on Content- Based Multimedia Indexing (CBMI), pages 1–6, 2018.
  47. 47.Hyeonwoo Noh, Andre Araujo, Jack Sim, Tobias Weyand, and Bohyung Han. Large-scale image retrieval with attentive deep local features. In IEEE International Conference on Computer Vision, 2017.
  48. 48.A. Oliva and A. Torralba. Building the gist of a scene: the role of global image features in recognition. Progress in brain research, 155:23–36, 2006.
  49. 49.Eng-Jon Ong, Sameed Husain, and Miroslaw Bober. Siamese network of deep fisher-vector descriptors for image retrieval. CoRR, abs/1702.00338, 2017.
  50. 50.Guohao Peng, Yufeng Yue, Jun Zhang, Zhenyu Wu, Xi- aoyu Tang, and Danwei Wang. Semantic reinforced attention learning for visual place recognition. In IEEE International Conference on Robotics and Automation, ICRA 2021, Xi’an, China, May 30 - June 5, 2021, pages 13415–13422. IEEE, 2021.
  51. 51.Guohao Peng, Jun Zhang, Heshan Li, and Danwei Wang. At- tentional pyramid pooling of salient visual residuals for place recognition. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), pages 885–894, Oc- tober 2021.
  52. 52.Florent Perronnin, Yan Liu, Jorge Sanchez, and Herve ´ Poirier. Large-scale image retrieval with compressed fisher vectors. In IEEE Conference on Computer Vision and Pat- tern Recognition, pages 3384–3391, 06 2010.
  53. 53.James Philbin, Ondrej Chum, Michael Isard, Josef Sivic, and Andrew Zisserman. Object retrieval with large vocabular- ies and fast spatial matching. In IEEE Conference on Com- puter Vision and Pattern Recognition. IEEE Computer Soci- ety, 2007.
  54. 54.James Philbin, Ondrej Chum, Michael Isard, Josef Sivic, and Andrew Zisserman. Lost in quantization: Improving par- ticular object retrieval in large scale image databases. In IEEE Conference on Computer Vision and Pattern Recog- nition, June 2008.
  55. 55.Nathan Piasco, Desir ´ e Sidib ´ e, C ´ edric Demonceaux, and ´ Valerie Gouet-Brunet. A survey on visual-based localization: ´ On the benefit of heterogeneous data. Pattern Recognition, 74:90–109, 2018.
  56. 56.Noe Pion, Martin Humenberger, Gabriela Csurka, Yohann ´ Cabon, and Torsten Sattler. Benchmarking image retrieval for visual localization. In 2020 International Conference on 3D Vision (3DV), pages 483–494, 2020.
  57. 57.Filip Radenovic, Giorgos Tolias, and O. Chum. CNN Image ´ Retrieval Learns from BoW: Unsupervised Fine-Tuning with Hard Examples. In ECCV, 2016.
  58. 58.F. Radenovic, G. Tolias, and O. Chum. Fine-tuning CNN ´ Image Retrieval with No Human Annotation. IEEE Trans- actions on Pattern Analysis and Machine Intelligence, 2018.
  59. 59.A. Razavian, Hossein Azizpour, J. Sullivan, and S. Carls- son. Cnn features off-the-shelf: An astounding baseline for recognition. 2014 IEEE Conference on Computer Vision and Pattern Recognition Workshops, pages 512–519, 2014.
  60. 60.A. Razavian, J. Sullivan, A. Maki, and S. Carlsson. Visual In- stance Retrieval with Deep Convolutional Networks. CoRR, abs/1412.6574, 2015.
  61. 61.Jer´ ome Revaud, Jon Almaz ˆ an, R. S. Rezende, and ´ Cesar Roberto de Souza. Learning with average precision: ´ Training image retrieval with a listwise loss. 2019 IEEE/CVF International Conference on Computer Vision (ICCV), pages 5106–5115, 2019.
  62. 62.Torsten Sattler, Will Maddern, Carl Toft, Akihiko Torii, Lars Hammarstrand, Erik Stenborg, Daniel Safari, Masatoshi Okutomi, Marc Pollefeys, Josef Sivic, Fredrik Kahl, and Tomas Pajdla. Benchmarking 6DOF outdoor visual localiza- tion in changing conditions. In 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 8601– 8610, 2018.
  63. 63.Grant Schindler, Matthew Brown, and Richard Szeliski. City-Scale Location Recognition. In IEEE Conference on Computer Vision and Pattern Recognition, 2007.
  64. 64.Zachary Seymour, Karan Sikka, Han-Pang Chiu, S. Sama- rasekera, and Rakesh Kumar. Semantically-aware atten- tive neural embeddings for image-based visual localization. ArXiv, abs/1812.03402, 2018.
  65. 65.Karen Simonyan and Andrew Zisserman. Very deep convo- lutional networks for large-scale image recognition. In In- ternational Conference on Learning Representations, 2015.
  66. 66.Josef Sivic and Andrew Zisserman. Video google: A text retrieval approach to object matching in videos. In ICCV, pages 1470–1477. IEEE Computer Society, 2003.
  67. 67.Elena Stumm, Christopher Mei, and Simon Lacroix. Prob- abilistic place recognition with covisibility maps. In IEEE/RSJ International Conference on Intelligent Robots and Systems, pages 4158–4163. IEEE, 2013.
  68. 68.Giorgos Tolias, R. Sicre, and H. Jegou. Particular object re- ´ trieval with integral max-pooling of CNN activations. CoRR, abs/1511.05879, 2016.
  69. 69.A. Torii, R. Arandjelovic, J. Sivic, M. Okutomi, and T. ´ Pajdla. 24/7 place recognition by view synthesis. IEEE Transactions on Pattern Analysis and Machine Intelligence, 40(2):257–271, 2018.
  70. 70.A. Torii, J. Sivic, M. Okutomi, and T. Pajdla. Visual place recognition with repetitive structures. IEEE Transactions on Pattern Analysis and Machine Intelligence, 37(11):2346– 2359, 2015.
  71. 71.A. Torii, Hajime Taira, Josef Sivic, M. Pollefeys, M. Oku- tomi, T. Pajdla, and Torsten Sattler. Are large-scale 3d mod- els really necessary for accurate visual localization? IEEE Transactions on Pattern Analysis and Machine Intelligence, 43:814–829, 2021.
  72. 72.Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, and Herve J ´ egou. Train- ´ ing data-efficient image transformers & distillation through attention. In Marina Meila and Tong Zhang, editors, Pro- ceedings of the 38th International Conference on Machine Learning, volume 139 of Proceedings of Machine Learning Research, pages 10347–10357. PMLR, July 2021.
  73. 73.O. Vysotska and C. Stachniss. Effective visual place recog- nition using multi-sequence maps. IEEE Robotics and Au- tomation Letters, 4:1730–1736, 2019.
  74. 74.Z. Wang, J. Li, S. Khademi, and J. van Gemert. Attention- aware age-agnostic visual place recognition. In The IEEE International Conference on Computer Vision (ICCV) Work- shops, Oct 2019.
  75. 75.Frederik Warburg, Soren Hauberg, Manuel Lopez- Antequera, Pau Gargallo, Yubin Kuang, and Javier Civera. Mapillary street-level sequences: A dataset for lifelong place recognition. In IEEE Conference on Computer Vision and Pattern Recognition, June 2020.
  76. 76.Isaac Ronald Ward, M. Jalwana, and M. Bennamoun. Im- proving image-based localization with deep learning: The impact of the loss function. In PSIVT Workshops, 2019.
  77. 77.Tobias Weyand, A. Araujo, Bingyi Cao, and Jack Sim. ´ Google landmarks dataset v2 – a large-scale benchmark for instance-level recognition and retrieval. 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pages 2572–2581, 2020.
  78. 78.Zhe Xin, Xiaoguang Cui, Jixiang Zhang, Yiping Yang, and Yanqing Wang. Visual place recognition with cnns: From global to partial. In 2017 Seventh International Conference on Image Processing Theory, Tools and Applications (IPTA), pages 1–6, 2017.
  79. 79.Mubariz Zaffar, Shoaib Ehsan, Michael Milford, and K. Mcdonald-Maier. Cohog: A light-weight, compute-efficient, and training-free visual place recognition technique for changing environments. IEEE Robotics and Automation Let- ters, 5:1835–1842, 2020.
  80. 80.Mubariz Zaffar, Sourav Garg, Michael Milford, Julian Kooij, David Flynn, Klaus McDonald-Maier, and Shoaib Ehsan. VPR-Bench: An open-source visual place recognition eval- uation framework with quantifiable viewpoint and appear- ance change. International Journal of Computer Vision, 129(7):2136–2174, 2021.
  81. 81.Amir R. Zamir, Asaad Hakeem, Luc Van Gool, Mubarak Shah, and Richard Szeliski, editors. Large-Scale Visual Geo-localization. Advances in Computer Vision and Pattern Recognition. Springer, 2016.
  82. 82.Xiwu Zhang, Lei Wang, and Yan Su. Visual place recog- nition: A survey from deep learning perspective. Pattern Recognition, 113, 2021.
  83. 83.Y. Zhu, J. Wang, L. Xie, and L. Zheng. Attention-based pyramid aggregation network for visual place recognition. In Proc. of the 26th ACM Int. Conf. on Multimedia, MM ’18, page 99–107, New York, NY, USA, 2018. Association for Computing Machinery.

Citation

MLA
Berton, G., et al. “Deep Visual Geo-localization Benchmark”. arXiv, 2022, http://arxiv.org/abs/2204.03444v2.
APA
Berton, G., Mereu, R., Trivigno, G., Masone, C., Csurka, G., Sattler, T., & Caputo, B. (2022). Deep Visual Geo-localization Benchmark. arXiv. http://arxiv.org/abs/2204.03444v2
Chicago
Berton, G., R. Mereu, G. Trivigno, et al. 2022. “Deep Visual Geo-localization Benchmark”. arXiv. http://arxiv.org/abs/2204.03444v2.
Harvard
Berton, G. et al. (2022) “Deep Visual Geo-localization Benchmark”, arXiv [Preprint]. Available at: http://arxiv.org/abs/2204.03444v2.
Vancouver
1. Berton G, Mereu R, Trivigno G, Masone C, Csurka G, Sattler T, Caputo B (2022) Deep Visual Geo-localization Benchmark. arXiv

BibTeX

@article{berton2022deep,
  title = {Deep Visual Geo-localization Benchmark},
  author = {Berton, Gabriele and Mereu, Riccardo and Trivigno, Gabriele and Masone, Carlo and Csurka, Gabriela and Sattler, Torsten and Caputo, Barbara},
  year = {2022},
  journal = {arXiv},
  url = {http://arxiv.org/abs/2204.03444v2},
  eprint = {2204.03444}
}
Metadata:arXiv

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: IEEE