Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields

Yifan WangLukas RahmannOlga Sorkine-Hornung

article2022ICLR81 citations

Introduces implicit displacement fields, a neural shape representation that decomposes 3D geometry into smooth base surfaces and high-frequency normal offsets without supervision, enabling geometrically consistent surface reconstruction and detail transfer.

Listen

Representing complex, highly detailed 3D digital shapes is a core requirement across industries like digital manufacturing, virtual simulation, and computer graphics. While modern neural networks can represent 3D geometry continuously without fixed grid resolutions, existing methods struggle to capture fine micro-details. Standard neural approaches either experience severe training instability and divergence when tuned to high frequencies, or they rely on spatial data structures that require excessive memory and compute resources.

The article introduces and evaluates "implicit displacement fields" (IDF), a neural framework that represents complex 3D shapes by decoupling them into a smooth, low-frequency base shape and a high-frequency displacement field constrained along the base surface's normal directions. The main objective was to demonstrate that this geometry-consistent decomposition achieves state-of-the-art detail reconstruction and stable, unsupervised training with a lightweight neural network, while enabling the transfer of surface details onto new 3D models.

To evaluate this approach, the authors performed comparative reconstruction experiments on 16 high-resolution 3D models from standard 3D repositories against leading implicit baseline models, including Fourier feature networks, octree-based level-of-detail networks (NGLOD), and standard sinusoidal neural networks (SIREN). They also conducted ablation studies on key architectural elements—such as bounded displacements, surface-distance attenuation, and progressive coarse-to-fine training schedules—and tested detail transfer across aligned 3D target models.

The findings establish that implicit displacement fields achieve top-tier geometric accuracy while substantially lowering memory overhead. In quantitative benchmarks, the method achieved the lowest reconstruction error (an average point-to-point Chamfer distance of 1.22 and normal cosine error of 1.25), outperforming the baseline methods. The only competing approach with comparable visual fidelity required an octree structure with 256 to 300 times more parameters (roughly 946 megabytes versus 4.8 megabytes for this framework). Unlike standard high-frequency sinusoidal models, which frequently diverged during optimization, the proposed architecture trained stably within roughly 40 minutes on standard hardware. Furthermore, by conditioning the displacement network on scale- and translation-invariant context descriptors rather than fixed coordinates, the model successfully transferred high-frequency surface details to new shapes without retraining the displacement component.

These results demonstrate that incorporating geometric constraints directly into neural architectures avoids the common trade-off between training stability and high-fidelity output. For technical and operational decision-makers, this framework offers a practical path to reduce storage, memory footprint, and bandwidth costs when managing dense 3D assets, while streamlining digital asset production pipelines through reusable geometric details.

Organizations developing 3D modeling, simulation, or rendering pipelines should consider testing continuous displacement representations as a lightweight alternative to dense spatial grids. Future implementation efforts should focus on integrating automatic shape pre-alignment and exploring sparse visual correspondences to support fully automated, cross-category detail transfers across non-aligned objects.

Cover for Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields

Abstract

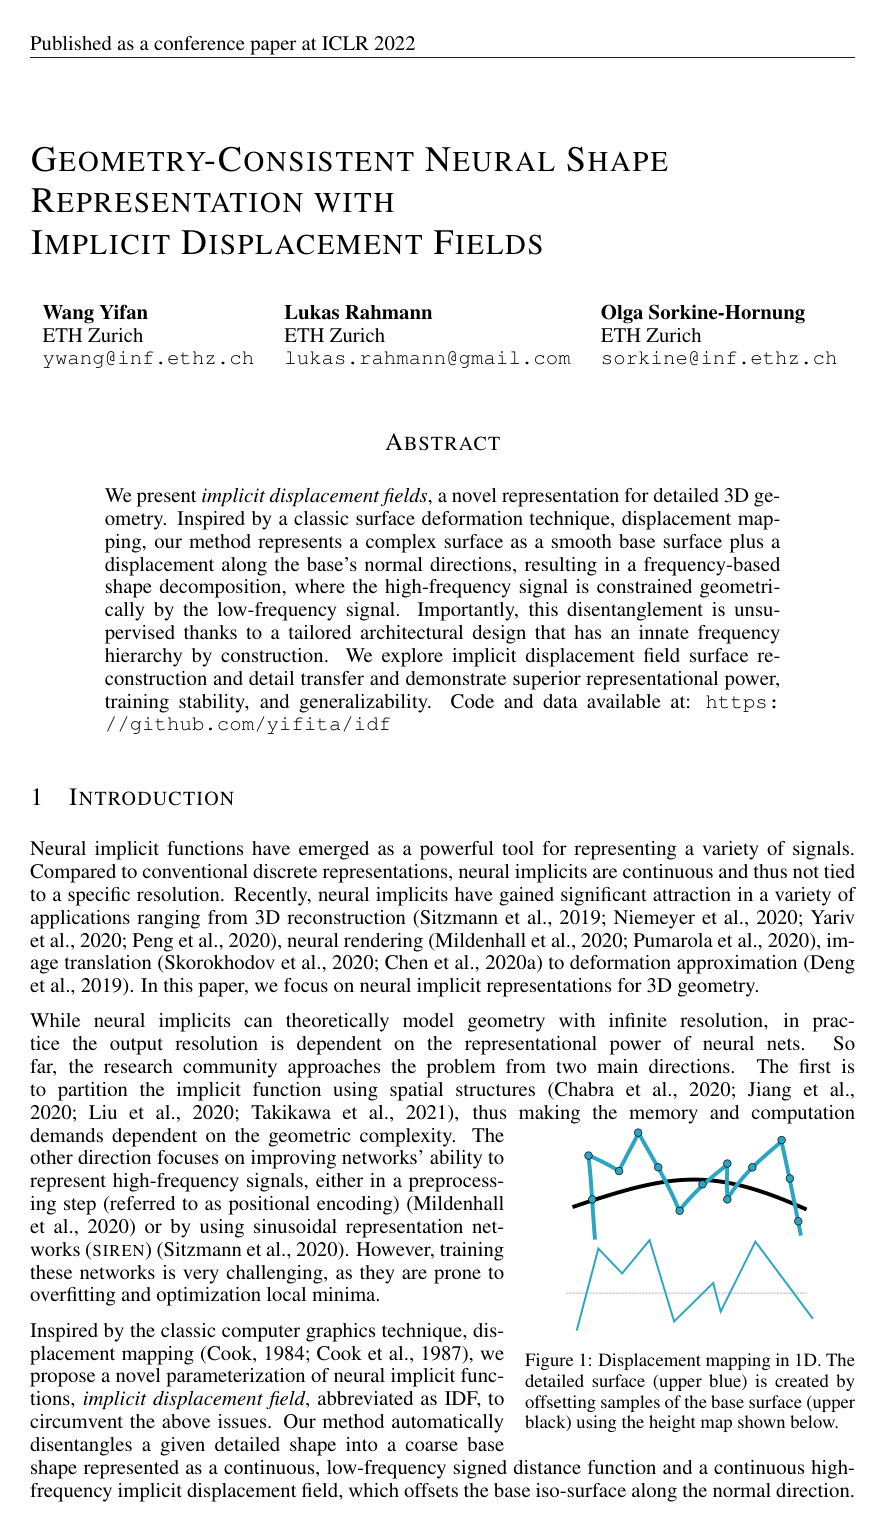
We present implicit displacement fields, a novel representation for detailed 3D geometry. Inspired by a classic surface deformation technique, displacement mapping, our method represents a complex surface as a smooth base surface plus a displacement along the base's normal directions, resulting in a frequency-based shape decomposition, where the high frequency signal is constrained geometrically by the low frequency signal. Importantly, this disentanglement is unsupervised thanks to a tailored architectural design that has an innate frequency hierarchy by construction. We explore implicit displacement field surface reconstruction and detail transfer and demonstrate superior representational power, training stability and generalizability.

Table of Contents

  • 1 Introduction
  • 2 Related work
  • 3 Method
  • 3.1 Implicit displacement fields
  • 3.2 Network design and training
  • 3.3 Transferable implicit displacement field.
  • 4 Results
  • 4.1 Detail representation.
  • 4.2 Ablation study
  • 4.3 Transferability
  • 5 Conclusion and limitations
  • References
  • A Proofs
  • B Additional experiments and results.
  • B.1 Additional information to the comparison in Sec
  • B.1.1 Additional evaluation results
  • B.1.2 Analysis
  • B.2 Discussion about ωB\omega_{B} and ωD\omega_{D}
  • B.3 Stress tests
  • B.4 Detail transfer.
  • B.5 Inference and training time

Knowls

  1. Knowl 1 — Implicit Displacement Field and Inverse Formulation

    definition

    Let f:R3→Rf: \mathbb{R}^3 \to \mathbb{R} and f^:R3→R\hat{f}: \mathbb{R}^3 \to \mathbb{R} denote continuous signed distance functions representing a smooth base surface and a detailed surface, respectively. For any level value τ∈R\tau \in \mathbb{R}, let Sτ={x∈R3∣f(x)=τ}S_\tau = \{x \in \mathbb{R}^3 \mid f(x) = \tau\} and S^τ={x∈R3∣f^(x)=τ}\hat{S}_\tau = \{x \in \mathbb{R}^3 \mid \hat{f}(x) = \tau\} denote their corresponding level sets.

    A forward implicit displacement field (IDF) is a continuous scalar function d:R3→Rd: \mathbb{R}^3 \to \mathbb{R} defining the geometric offset from SτS_\tau to S^τ\hat{S}_\tau along the base surface normal:

    f(x)=f^(x+d(x)n),where n=∇f(x)∥∇f(x)∥f(x) = \hat{f}(x + d(x) n), \quad \text{where } n = \frac{\nabla f(x)}{\|\nabla f(x)\|}

    To allow supervision using presampled query points x^∈R3\hat{x} \in \mathbb{R}^3 without dynamically computing the target signed distance at variable deformed coordinates, the representation is parameterized via the inverse implicit displacement field d^:R3→R\hat{d}: \mathbb{R}^3 \to \mathbb{R}, which maps S^τ\hat{S}_\tau to SτS_\tau:

    f(x^+d^(x^)n^)=f^(x^),where n^=∇f(x^)∥∇f(x^)∥f(\hat{x} + \hat{d}(\hat{x}) \hat{n}) = \hat{f}(\hat{x}), \quad \text{where } \hat{n} = \frac{\nabla f(\hat{x})}{\|\nabla f(\hat{x})\|}

    Under small displacements, the normal direction n^\hat{n} after inverse displacement is approximated by the normal direction at the query point.

  2. Knowl 2 — Surface Normal Difference Bound under Implicit Displacement

    theoretical result

    Let f:Rn→Rf: \mathbb{R}^n \to \mathbb{R} be a differentiable signed distance function that is Lipschitz-continuous with constant LL and Lipschitz-smooth with constant MM (i.e., ∥∇f(x)−∇f(y)∥≤M∥x−y∥\|\nabla f(x) - \nabla f(y)\| \le M \|x - y\|). Then for any offset δ∈R\delta \in \mathbb{R}:

    ∥∇f(x+δ∇f(x))−∇f(x)∥≤∣δ∣LM\|\nabla f(x + \delta \nabla f(x)) - \nabla f(x)\| \le |\delta| L M

    If ff satisfies the Eikonal equation up to an error bound ϵ>0\epsilon > 0 such that ∣∥∇f(x)∥−1∣<ϵ|\|\nabla f(x)\| - 1| < \epsilon, the Lipschitz-continuous constant satisfies L<1+ϵL < 1 + \epsilon, giving:

    ∥∇f(x+δ∇f(x))−∇f(x)∥<(1+ϵ)∣δ∣M\|\nabla f(x + \delta \nabla f(x)) - \nabla f(x)\| < (1 + \epsilon) |\delta| M

    For a point x∈R3x \in \mathbb{R}^3, displaced position x^=x+d(x)n\hat{x} = x + d(x) n with displacement distance d(x)d(x), base normal n=∇f(x)∥∇f(x)∥n = \frac{\nabla f(x)}{\|\nabla f(x)\|}, displaced normal n^=∇f(x^)∥∇f(x^)∥\hat{n} = \frac{\nabla f(\hat{x})}{\|\nabla f(\hat{x})\|}, and scalar δ=d(x)∥∇f(x)∥\delta = \frac{d(x)}{\|\nabla f(x)\|}, the difference between normalized surface normals satisfies:

    ∥n^−n∥≤1+ϵ1−ϵ∣δ∣M\|\hat{n} - n\| \le \frac{1 + \epsilon}{1 - \epsilon} |\delta| M

    Because the normal difference is bounded by a small constant proportional to the displacement magnitude, evaluating the base normal at the sampled query point x^\hat{x} serves as a bounded approximation for the displaced surface normal.

  3. Knowl 3 — Dual-SIREN Architecture with Attenuation for Implicit Displacement Fields

    model/method

    The implicit shape decomposition parameterizes the base shape and displacement field using two sinusoidal representation networks (SIRENs) with distinct frequency hyperparameters: a base network NωB\mathcal{N}^{\omega_B} and a displacement network NωD\mathcal{N}^{\omega_D}, where ωB<ωD\omega_B < \omega_D (default ωB=15\omega_B = 15 and ωD=60\omega_D = 60).

    To constrain the displacement magnitude, the output linear layer of NωD\mathcal{N}^{\omega_D} is activated by a scaled hyperbolic tangent αtanh⁡(⋅)\alpha \tanh(\cdot), where α>0\alpha > 0 is the maximum permitted displacement distance (default α=0.05\alpha = 0.05).

    To suppress high-frequency artifacts in void regions far from the base surface, an attenuation function χ:R→[0,1]\chi: \mathbb{R} \to [0, 1] modulates the displacement magnitude:

    χ(f(x))=11+(f(x)ν)4\chi(f(x)) = \frac{1}{1 + \left(\frac{f(x)}{\nu}\right)^4}

    where ν>0\nu > 0 controls the attenuation transition bandwidth (default ν=0.02\nu = 0.02).

    The detailed surface signed distance f^(x)\hat{f}(x) at any query point x∈R3x \in \mathbb{R}^3 is computed via a two-stage evaluation:

    f(x)=NωB(x)f(x) = \mathcal{N}^{\omega_B}(x)

    f^(x)=NωB(x+χ(f(x)) αtanh⁡(NωD(x))∇f(x)∥∇f(x)∥)\hat{f}(x) = \mathcal{N}^{\omega_B}\left(x + \chi(f(x)) \, \alpha \tanh(\mathcal{N}^{\omega_D}(x)) \frac{\nabla f(x)}{\|\nabla f(x)\|}\right)

  4. Knowl 4 — Loss Function and Progressive Training for Implicit Displacement Fields

    model/method

    Given an oriented point cloud P={(pi,ni)}\mathcal{P} = \{(p_i, n_i)\} and the domain bounding box Ω=[−1,1]3\Omega = [-1, 1]^3, the neural implicit signed distance function is trained by minimizing the loss Lf^\mathcal{L}_{\hat{f}}:

    Lf^=∑x∈Ωλ0∣∥∇f^(x)∥−1∣+∑(p,n)∈P(λ1∣f^(p)∣+λ2(1−⟨∇f^(p),n⟩))+∑x∈Ω∖Pλ3exp⁡(−100f^(x))\mathcal{L}_{\hat{f}} = \sum_{x \in \Omega} \lambda_0 \big|\|\nabla \hat{f}(x)\| - 1\big| + \sum_{(p, n) \in \mathcal{P}} \left(\lambda_1 |\hat{f}(p)| + \lambda_2 (1 - \langle \nabla \hat{f}(p), n \rangle)\right) + \sum_{x \in \Omega \setminus \mathcal{P}} \lambda_3 \exp(-100 \hat{f}(x))

    with loss weighting hyperparameters λ0=5\lambda_0 = 5, λ1=400\lambda_1 = 400, λ2=40\lambda_2 = 40, and λ3=50\lambda_3 = 50.

    To prevent the high-frequency displacement network from destabilizing the base surface during early optimization, training follows a progressive coarse-to-fine schedule across training epochs normalized to t∈[0,1]t \in [0, 1]. For t≤Tmt \le T_m (default threshold Tm=0.2T_m = 0.2), only the base network NωB\mathcal{N}^{\omega_B} is trained using loss Lf\mathcal{L}_f (evaluating L\mathcal{L} on f(x)f(x)). For t>Tmt > T_m, the total objective smoothly transitions via cosine blending:

    Ltotal=κLf+(1−κ)Lf^,where κ=12(1+cos⁡(πt−Tm1−Tm))\mathcal{L}_{\text{total}} = \kappa \mathcal{L}_f + (1 - \kappa) \mathcal{L}_{\hat{f}}, \quad \text{where } \kappa = \frac{1}{2}\left(1 + \cos\left(\pi \frac{t - T_m}{1 - T_m}\right)\right)

    The learning rates for the base and displacement networks follow the same cosine transition schedule.

  5. Knowl 5 — Transferable Implicit Displacement Field Architecture

    model/method

    A transferable implicit displacement field replaces explicit Cartesian coordinates with continuous, coordinate-free local descriptors, enabling details learned from a source shape to be applied to a target shape without UV parameterization.

    The conditioning feature at query point x∈R3x \in \mathbb{R}^3 comprises two components:

    1. A global context descriptor ϕ(x)\phi(x): On-surface point normals are processed by a point cloud encoder to produce sparse features, projected onto a regular 3D or 2D grid, propagated off-surface using 3D/2D convolutional layers, and interpolated at xx via trilinear or bilinear interpolation.
    2. A normalized signed distance value fˉ(x)=tanh⁡(1νf(x))\bar{f}(x) = \tanh\left(\frac{1}{\nu} f(x)\right), where f(x)f(x) is the base signed distance and ν\nu is the attenuation bandwidth parameter.

    The global context descriptor ϕ(x)\phi(x) is mapped by a multi-layer perceptron M\mathcal{M} to layer-wise modulation vectors {γi,βi}i=1L\{\gamma_i, \beta_i\}_{i=1}^L. These vectors modulate the linear layers of the displacement SIREN TωD\mathcal{T}^{\omega_D} using Feature-wise Linear Modulation (FiLM):

    hi+1=sin⁡((1+12γi)∘(Wihi+bi)+βi)h_{i+1} = \sin\left(\left(1 + \frac{1}{2}\gamma_i\right) \circ (W_i h_i + b_i) + \beta_i\right)

    where h0=fˉ(x)h_0 = \bar{f}(x), Wi,biW_i, b_i are weight matrices and bias vectors, and ∘\circ denotes Hadamard (element-wise) multiplication.

    The detailed SDF is evaluated as:

    f^(x)=NωB(x+χ(f(x)) TωD(fˉ(x),M(ϕ(x)))∇f(x)∥∇f(x)∥)\hat{f}(x) = \mathcal{N}^{\omega_B}\left(x + \chi(f(x)) \, \mathcal{T}^{\omega_D}(\bar{f}(x), \mathcal{M}(\phi(x))) \frac{\nabla f(x)}{\|\nabla f(x)\|}\right)

  6. Knowl 6 — Surface Detail Transfer Procedure using Transferable IDF

    algorithm

    The procedure transfers high-frequency geometric displacement fields learned from a source shape Ssrc\mathcal{S}_{\text{src}} onto an aligned target shape Stgt\mathcal{S}_{\text{tgt}}.

    Input: Source point cloud Psrc\mathcal{P}_{\text{src}}, target point cloud Ptgt\mathcal{P}_{\text{tgt}}, optional source/target base meshes, base frequency ωB\omega_B, displacement frequency ωD\omega_D
    Output: Composed target detailed SDF f^tgt\hat{f}_{\text{tgt}}
    1. if source base shape is provided then
    2. Train base SIREN NωB\mathcal{N}^{\omega_B} on source base shape
    3. else
    4. Train base SIREN NωB\mathcal{N}^{\omega_B} (configured with ωB=5\omega_B = 5, 3 hidden layers of 96 channels) on Psrc\mathcal{P}_{\text{src}}
    5. end if
    6. Freeze parameters of NωB\mathcal{N}^{\omega_B}
    7. Train context feature extractor ϕ\phi, mapping network M\mathcal{M}, and displacement SIREN TωD\mathcal{T}^{\omega_D} on Psrc\mathcal{P}_{\text{src}} using the composite detailed SDF loss
    8. if target base shape is provided then
    9. Train target base SIREN NnewωB\mathcal{N}_{\text{new}}^{\omega_B} on target base shape
    10. else
    11. Train target base SIREN NnewωB\mathcal{N}_{\text{new}}^{\omega_B} on Ptgt\mathcal{P}_{\text{tgt}} with ωB=5\omega_B = 5
    12. end if
    13. Synthesize transferred detail on target query points xx by evaluating:
        f^tgt(x)=NnewωB(x+χ(fnew(x)) TωD(fˉnew(x),M(ϕ(x)))∇fnew(x)∥∇fnew(x)∥)\hat{f}_{\text{tgt}}(x) = \mathcal{N}_{\text{new}}^{\omega_B}\left(x + \chi(f_{\text{new}}(x)) \, \mathcal{T}^{\omega_D}(\bar{f}_{\text{new}}(x), \mathcal{M}(\phi(x))) \frac{\nabla f_{\text{new}}(x)}{\|\nabla f_{\text{new}}(x)\|}\right)
    14. return f^tgt\hat{f}_{\text{tgt}}
  7. Knowl 7 — 3D Surface Reconstruction Benchmark across Baselines

    data/table

    Evaluation of single-shape surface reconstruction on 16 high-resolution shapes (14 from Sketchfab, 2 from Stanford 3D Scan Repository). Metrics are two-way point-to-point Chamfer Distance (CD×10−3CD \times 10^{-3}) and normal cosine distance (NC×10−2NC \times 10^{-2}), evaluated on 5 million surface points sampled from meshes extracted via Marching Cubes at 5123512^3 resolution.

    Metric Progressive FFN NGLOD (LOD4) NGLOD (LOD6) SIREN-3 (ω=60\omega=60) SIREN-7 (ω=30\omega=30) SIREN-7 (ω=60\omega=60) Direct Residual D-SDF Ours
    CD ⋅10−3\cdot 10^{-3} 5.47 2.27 1.35 9.85 4.85 – 181.0 2.85 1.22
    NC ⋅10−2\cdot 10^{-2} 3.77 4.24 1.97 6.64 2.56 6.02 59.0 4.39 1.25
    Model Size ∼4.8\sim 4.8 MB 16 MB 946 MB 5.6 MB 5.6 MB 5.6 MB ∼4.8\sim 4.8 MB 7.4 MB 4.8 MB

    Implicit Displacement Fields achieve the lowest reconstruction error while maintaining a compact 4.8 MB footprint. NGLOD with 6 levels of detail achieves competitive accuracy but requires an octree feature structure with 256×256\times more parameters (946 MB). Standard SIREN models with ω=60\omega=60 exhibit optimization divergence on most shapes. Direct residual addition without normal-direction constraints produces severe geometric artifacts (CD=181.0×10⁻³CD = 181.0 \times 10^{-3}).

  8. Knowl 8 — Ablation Study on Network Constraints and Hyperparameters

    data/table

    Ablation experiments evaluate the contribution of individual architectural components and parameter sensitivities. Point-to-point Chamfer Distance (CD×10−3CD \times 10^{-3}) and normal cosine distance (NC×10−2NC \times 10^{-2}) are reported.

    Component Ablation:

    αtanh⁡\alpha \tanh Attenuation χ\chi Progressive Training Average CD⋅10−3CD \cdot 10^{-3}
    1.44
    ✓ 1.41
    ✓ ✓ 1.38
    ✓ ✓ ✓ 1.24

    Hyperparameter Sensitivity for Displacement Bound α\alpha (with ν=0.02\nu = 0.02) and Attenuation Factor ν\nu (with α=0.05\alpha = 0.05):

    α\alpha test (with ν=0.02\nu=0.02) ν\nu test (with α=0.05\alpha=0.05)
    Parameter value 0.01 0.02 0.05 0.1 0.2 0.01 0.02 0.05 0.1 0.2
    CD⋅10−3CD \cdot 10^{-3} 1.178 1.171 1.147 1.146 1.149 1.146 1.147 1.147 1.149 1.152
    NC⋅10−2NC \cdot 10^{-2} 1.525 1.490 1.252 1.251 1.260 1.254 1.253 1.251 1.250 1.274

    Adding displacement bounding, spatial attenuation, and progressive scheduling steadily reduces Chamfer error from 1.44×10−31.44 \times 10^{-3} to 1.24×10−31.24 \times 10^{-3}. Reconstruction remains stable across a wide parameter range, degrading slightly when α\alpha is too small (0.010.01) to cover surface deviations or when ν\nu is too large (0.20.2), which allows off-surface high-frequency noise in void regions.

  9. Knowl 9 — Reconstruction Robustness to Point Sparsity and Measurement Noise

    data/table

    Performance of Implicit Displacement Fields compared to Screened Poisson Surface Reconstruction under varying point cloud sparsity (40,000 and 400,000 points, corresponding to 1% and 10% of standard 4M sample density) and Gaussian noise standard deviations σ∈{0.002,0.005}\sigma \in \{0.002, 0.005\} added to both point positions and surface normals.

    Training Points Noise σ\sigma Ours (CD⋅10−3CD \cdot 10^{-3} / NC⋅10−2NC \cdot 10^{-2}) Poisson Recon (CD⋅10−3CD \cdot 10^{-3} / NC⋅10−2NC \cdot 10^{-2})
    40,000 0.002 1.07 / 7.54 1.08 / 7.78
    40,000 0.005 1.05 / 7.57 1.08 / 7.82
    400,000 0.002 1.00 / 6.01 1.04 / 6.63
    400,000 0.005 1.00 / 5.99 1.04 / 6.60

    Given adequate point density (400k samples), the learned implicit displacement field recovers sharp surface microstructures and normal orientations more faithfully than Poisson reconstruction. When input point clouds are extremely sparse (40k samples), high-frequency fitting can overfit noise in poorly sampled regions.

  10. Knowl 10 — Spatial Alignment Requirement for Detail Transfer

    limitation

    The transferable implicit displacement field requires source and target 3D shapes to be roughly pre-aligned in coordinate space. While the normal-based context descriptor ϕ(x)\phi(x) provides translation and scale invariance and exhibits empirical robustness to small local rotational variations, it is not fully rotation-invariant or deformation-invariant. Consequently, direct detail transfer cannot handle unaligned inputs or large non-rigid geometric transformations without prior shape alignment or sparse correspondence matching.

Coverage note — Omitted material includes per-model individual runtime profiling on Nvidia RTX 2080 GPU hardware, specific names of individual 3D mesh assets from online repositories, and step-by-step intermediate proof derivations (such as Cauchy-Schwarz inequality expansions).

References

  1. 1.Sketchfab. https://sketchfab.com, 2021.
  2. 2.Stanford 3d scan repository. http://graphics.stanford.edu/data/3Dscanrep/, 2021.
  3. 3.Ronen Basri, Meirav Galun, Amnon Geifman, David Jacobs, Yoni Kasten, and Shira Kritchman. Frequency bias in neural networks for input of non-uniform density. In International Conference on Machine Learning, pp. 685–694. PMLR, 2020.
  4. 4.Sema Berkiten, Maciej Halber, Justin Solomon, Chongyang Ma, Hao Li, and Szymon Rusinkiewicz. Learning detail transfer based on geometric features. Computer Graphics Forum, 36(2):361–373, 2017.
  5. 5.Henning Biermann, Ioana Martin, Fausto Bernardini, and Denis Zorin. Cut-and-paste editing of multiresolution surfaces. ACM Transactions on Graphics (TOG), 21(3):312–321, 2002.
  6. 6.Mario Botsch, Leif Kobbelt, Mark Pauly, Pierre Alliez, and Bruno Levy. Polygon mesh processing. CRC press, 2010.
  7. 7.Rohan Chabra, Jan E Lenssen, Eddy Ilg, Tanner Schmidt, Julian Straub, Steven Lovegrove, and Richard Newcombe. Deep local shapes: Learning local sdf priors for detailed 3d reconstruction. In European Conference on Computer Vision, pp. 608–625. Springer, Springer International Publishing, 2020.
  8. 8.Eric R Chan, Marco Monteiro, Petr Kellnhofer, Jiajun Wu, and Gordon Wetzstein. pi-gan: Periodic implicit generative adversarial networks for 3d-aware image synthesis. arXiv preprint arXiv:2012.00926, 2020.
  9. 9.Xiaobai Chen, Tom Funkhouser, Dan B Goldman, and Eli Shechtman. Non-parametric texture transfer using meshmatch. Technical Report Technical Report 2012-2, 2012.
  10. 10.Yinbo Chen, Sifei Liu, and Xiaolong Wang. Learning continuous image representation with local implicit image function. arXiv preprint arXiv:2012.09161, 2020a.
  11. 11.Zhiqin Chen and Hao Zhang. Learning implicit fields for generative shape modeling. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 5939–5948, 2019.
  12. 12.Zhiqin Chen, Andrea Tagliasacchi, and Hao Zhang. Bsp-net: Generating compact meshes via binary space partitioning. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 45–54, 2020b.
  13. 13.Zhiqin Chen, Vladimir Kim, Matthew Fisher, Noam Aigerman, Hao Zhang, and Siddhartha Chaudhuri. DecorGAN: 3d shape detailization by conditional refinement. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2021.
  14. 14.Robert L Cook. Shade trees. In Proceedings of the 11th annual conference on Computer graphics and interactive techniques, pp. 223–231, 1984.
  15. 15.Robert L Cook, Loren Carpenter, and Edwin Catmull. The reyes image rendering architecture. ACM SIGGRAPH Computer Graphics, 21(4):95–102, 1987.
  16. 16.Boyang Deng, John P Lewis, Timothy Jeruzalski, Gerard Pons-Moll, Geoffrey Hinton, Mohammad Norouzi, and Andrea Tagliasacchi. Nasa: neural articulated shape approximation. arXiv preprint arXiv:1912.03207, 2019.
  17. 17.Boyang Deng, Kyle Genova, Soroosh Yazdani, Sofien Bouaziz, Geoffrey Hinton, and Andrea Tagliasacchi. Cvxnet: Learnable convex decomposition. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 31–44, 2020.
  18. 18.Vincent Dumoulin, Ethan Perez, Nathan Schucher, Florian Strub, Harm de Vries, Aaron Courville, and Yoshua Bengio. Feature-wise transformations. Distill, 3(7):e11, 2018.
  19. 19.Sarah F Frisken, Ronald N Perry, Alyn P Rockwood, and Thouis R Jones. Adaptively sampled distance fields: A general representation of shape for computer graphics. In Proceedings of the 27th annual conference on Computer graphics and interactive techniques, pp. 249–254, 2000.
  20. 20.Kyle Genova, Forrester Cole, Daniel Vlasic, Aaron Sarna, William T Freeman, and Thomas Funkhouser. Learning shape templates with structured implicit functions. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pp. 7154–7164, 2019.
  21. 21.Kyle Genova, Forrester Cole, Avneesh Sud, Aaron Sarna, and Thomas Funkhouser. Local deep implicit functions for 3d shape. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 4857–4866, 2020.
  22. 22.Zekun Hao, Hadar Averbuch-Elor, Noah Snavely, and Serge Belongie. Dualsdf: Semantic shape manipulation using a two-level representation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 7631–7641, 2020.
  23. 23.Amir Hertz, Rana Hanocka, Raja Giryes, and Daniel Cohen-Or. Deep geometric texture synthesis. ACM Trans. Graph., 39(4), July 2020. ISSN 0730-0301. doi: 10.1145/3386569.3392471. URL https://doi.org/10.1145/3386569.3392471.
  24. 24.Amir Hertz, Or Perel, Raja Giryes, Olga Sorkine-Hornung, and Daniel Cohen-Or. Progressive encoding for neural optimization. arXiv preprint arXiv:2104.09125, 2021.
  25. 25.Chiyu Jiang, Avneesh Sud, Ameesh Makadia, Jingwei Huang, Matthias Niener, Thomas Funkhouser, et al. Local implicit grid representations for 3d scenes. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 6001–6010, 2020.
  26. 26.Manyi Li and Hao Zhang. D2im-net: Learning detail disentangled implicit fields from single images. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2021.
  27. 27.Lingjie Liu, Jiatao Gu, Kyaw Zaw Lin, Tat-Seng Chua, and Christian Theobalt. Neural sparse voxel fields. In H. Larochelle, M. Ranzato, R. Hadsell, M. F. Balcan, and H. Lin (eds.), Advances in Neural Information Processing Systems, volume 33, pp. 15651–15663. Curran Associates, Inc., 2020. URL https://proceedings.neurips.cc/paper/2020/file/b4b758962f17808746e9bb832a6fa4b8-Paper.pdf.
  28. 28.Ilya Loshchilov and Frank Hutter. Sgdr: Stochastic gradient descent with warm restarts. arXiv preprint arXiv:1608.03983, 2016.
  29. 29.Julien NP Martel, David B Lindell, Connor Z Lin, Eric R Chan, Marco Monteiro, and Gordon Wetzstein. Acorn: Adaptive coordinate networks for neural scene representation. arXiv preprint arXiv:2105.02788, 2021.
  30. 30.Lars Mescheder, Michael Oechsle, Michael Niemeyer, Sebastian Nowozin, and Andreas Geiger. Occupancy networks: Learning 3d reconstruction in function space. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 4460–4470, 2019.
  31. 31.Ben Mildenhall, Pratul P Srinivasan, Matthew Tancik, Jonathan T Barron, Ravi Ramamoorthi, and Ren Ng. Nerf: Representing scenes as neural radiance fields for view synthesis. In European Conference on Computer Vision, pp. 405–421. Springer, Springer International Publishing, 2020.
  32. 32.Michael Niemeyer, Lars Mescheder, Michael Oechsle, and Andreas Geiger. Differentiable volumetric rendering: Learning implicit 3d representations without 3d supervision. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 3504–3515, 2020.
  33. 33.Yutaka Ohtake, Alexander Belyaev, Marc Alexa, Greg Turk, and Hans-Peter Seidel. Multi-level partition of unity implicits. ACM Trans. Graph., 22(3):463–470, 2003. ISSN 0730-0301. doi: 10.1145/882262.882293. URL https://doi.org/10.1145/882262.882293.
  34. 34.Jeong Joon Park, Peter Florence, Julian Straub, Richard Newcombe, and Steven Lovegrove. Deepsdf: Learning continuous signed distance functions for shape representation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 165–174, 2019.
  35. 35.Keunhong Park, Utkarsh Sinha, Jonathan T Barron, Sofien Bouaziz, Dan B Goldman, Steven M Seitz, and Ricardo Martin-Brualla. Deformable neural radiance fields. arXiv preprint arXiv:2011.12948, 2020a.
  36. 36.Keunhong Park, Utkarsh Sinha, Jonathan T. Barron, Sofien Bouaziz, Dan B Goldman, Steven M. Seitz, and Ricardo Martin-Brualla. Deformable neural radiance fields. arXiv preprint arXiv:2011.12948, 2020b.
  37. 37.Songyou Peng, Michael Niemeyer, Lars Mescheder, Marc Pollefeys, and Andreas Geiger. Convolutional occupancy networks. In European Conference on Computer Vision (ECCV), Cham, August 2020. Springer International Publishing.
  38. 38.Ethan Perez, Florian Strub, Harm De Vries, Vincent Dumoulin, and Aaron Courville. Film: Visual reasoning with a general conditioning layer. In Proceedings of the AAAI Conference on Artificial Intelligence, 2018.
  39. 39.Albert Pumarola, Enric Corona, Gerard Pons-Moll, and Francesc Moreno-Noguer. D-nerf: Neural radiance fields for dynamic scenes. arXiv preprint arXiv:2011.13961, 2020.
  40. 40.Albert Pumarola, Enric Corona, Gerard Pons-Moll, and Francesc Moreno-Noguer. D-nerf: Neural radiance fields for dynamic scenes. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 10318–10327, 2021.
  41. 41.Nasim Rahaman, Aristide Baratin, Devansh Arpit, Felix Draxler, Min Lin, Fred Hamprecht, Yoshua Bengio, and Aaron Courville. On the spectral bias of neural networks. In International Conference on Machine Learning, pp. 5301–5310. PMLR, 2019.
  42. 42.Shunsuke Saito, Zeng Huang, Ryota Natsume, Shigeo Morishima, Angjoo Kanazawa, and Hao Li. Pifu: Pixel-aligned implicit function for high-resolution clothed human digitization. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pp. 2304–2314, 2019.
  43. 43.Shunsuke Saito, Tomas Simon, Jason Saragih, and Hanbyul Joo. Pifuhd: Multi-level pixel-aligned implicit function for high-resolution 3d human digitization. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 84–93, 2020.
  44. 44.Vincent Sitzmann, Michael Zollhofer, and Gordon Wetzstein. Scene representation networks: Continuous 3d-structure-aware neural scene representations. arXiv preprint arXiv:1906.01618, 2019.
  45. 45.Vincent Sitzmann, Julien Martel, Alexander Bergman, David Lindell, and Gordon Wetzstein. Implicit neural representations with periodic activation functions. In H. Larochelle, M. Ranzato, R. Hadsell, M. F. Balcan, and H. Lin (eds.), Advances in Neural Information Processing Systems, volume 33, pp. 7462–7473. Curran Associates, Inc., 2020. URL https://proceedings.neurips.cc/paper/2020/file/53c04118df112c13a8c34b38343b9c10-Paper.pdf.
  46. 46.Ivan Skorokhodov, Savva Ignatyev, and Mohamed Elhoseiny. Adversarial generation of continuous images. arXiv preprint arXiv:2011.12026, 2020.
  47. 47.Olga Sorkine and Mario Botsch. Tutorial: Interactive shape modeling and deformation. In EUROGRAPHICS, 2009.
  48. 48.Olga Sorkine, Daniel Cohen-Or, Yaron Lipman, Marc Alexa, Christian Rossl, and H-P Seidel. Laplacian surface editing. In Proceedings of the 2004 Eurographics/ACM SIGGRAPH symposium on Geometry processing, pp. 175–184, 2004.
  49. 49.Kenshi Takayama, Ryan Schmidt, Karan Singh, Takeo Igarashi, Tamy Boubekeur, and Olga Sorkine. Geobrush: Interactive mesh geometry cloning. Computer Graphics Forum, 30(2):613–622, 2011.
  50. 50.Towaki Takikawa, Joey Litalien, Kangxue Yin, Karsten Kreis, Charles Loop, Derek Nowrouzezahrai, Alec Jacobson, Morgan McGuire, and Sanja Fidler. Neural geometric level of detail: Real-time rendering with implicit 3D shapes. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2021.
  51. 51.Matthew Tancik, Pratul Srinivasan, Ben Mildenhall, Sara Fridovich-Keil, Nithin Raghavan, Utkarsh Singhal, Ravi Ramamoorthi, Jonathan Barron, and Ren Ng. Fourier features let networks learn high frequency functions in low dimensional domains. In H. Larochelle, M. Ranzato, R. Hadsell, M. F. Balcan, and H. Lin (eds.), Advances in Neural Information Processing Systems, volume 33, pp. 7537–7547. Curran Associates, Inc., 2020. URL https://proceedings.neurips.cc/paper/2020/file/55053683268957697aa39fba6f231c68-Paper.pdf.
  52. 52.Edgar Tretschk, Ayush Tewari, Vladislav Golyanik, Michael Zollhofer, Carsten Stoll, and Christian Theobalt. Patchnets: Patch-based generalizable deep implicit 3d shape representations. In European Conference on Computer Vision, pp. 293–309. Springer, Springer International Publishing, 2020.
  53. 53.Zhi-Qin John Xu, Yaoyu Zhang, and Yanyang Xiao. Training behavior of deep neural network in frequency domain. In International Conference on Neural Information Processing, pp. 264–274. Springer, 2019.
  54. 54.Zhiqin John Xu. Understanding training and generalization in deep learning by fourier analysis. arXiv preprint arXiv:1808.04295, 2018.
  55. 55.Haotian Yang, Hao Zhu, Yanru Wang, Mingkai Huang, Qiu Shen, Ruigang Yang, and Xun Cao. Facescape: a large-scale high quality 3d face dataset and detailed riggable 3d face prediction. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2020.
  56. 56.Lior Yariv, Yoni Kasten, Dror Moran, Meirav Galun, Matan Atzmon, Basri Ronen, and Yaron Lipman. Multiview neural surface reconstruction by disentangling geometry and appearance. Advances in Neural Information Processing Systems, 33, 2020.
  57. 57.Wang Yifan, Noam Aigerman, Vladimir G Kim, Siddhartha Chaudhuri, and Olga Sorkine-Hornung. Neural cages for detail-preserving 3d deformations. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 75–83, 2020.
  58. 58.Lexing Ying, Aaron Hertzmann, Henning Biermann, and Denis Zorin. Texture and shape synthesis on surfaces. In Eurographics Workshop on Rendering Techniques, pp. 301–312. Springer, 2001.
  59. 59.Howard Zhou, Jie Sun, Greg Turk, and James M Rehg. Terrain synthesis from digital elevation models. IEEE transactions on visualization and computer graphics, 13(4):834–848, 2007.
  60. 60.Kun Zhou, Xin Huang, Xi Wang, Yiying Tong, Mathieu Desbrun, Baining Guo, and Heung-Yeung Shum. Mesh quilting for geometric texture synthesis. In ACM SIGGRAPH 2006 Papers, SIGGRAPH ’06, pp. 690–697, New York, NY, USA, 2006. Association for Computing Machinery. ISBN 1595933646. doi: 10.1145/1179352.1141942. URL https://doi.org/10.1145/1179352.1141942.
  61. 61.Qingnan Zhou and Alec Jacobson. Thingi10k: A dataset of 10,000 3d-printing models. arXiv preprint arXiv:1605.04797, 2016.

Citation

MLA
Yifan, W., et al. “Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields”. arXiv, 2021, http://arxiv.org/abs/2106.05187v3.
APA
Yifan, W., Rahmann, L., & Sorkine-Hornung, O. (2021). Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields. arXiv. http://arxiv.org/abs/2106.05187v3
Chicago
Yifan, W., L. Rahmann, and O. Sorkine-Hornung. 2021. “Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields”. arXiv. http://arxiv.org/abs/2106.05187v3.
Harvard
Yifan, W., Rahmann, L. and Sorkine-Hornung, O. (2021) “Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields”, arXiv [Preprint]. Available at: http://arxiv.org/abs/2106.05187v3.
Vancouver
1. Yifan W, Rahmann L, Sorkine-Hornung O (2021) Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields. arXiv

BibTeX

@article{yifan2021geometry,
  title = {Geometry-Consistent Neural Shape Representation with Implicit Displacement Fields},
  author = {Yifan, Wang and Rahmann, Lukas and Sorkine-Hornung, Olga},
  year = {2021},
  journal = {arXiv},
  url = {http://arxiv.org/abs/2106.05187v3},
  eprint = {2106.05187}
}
Metadata:arXiv

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: Authors