DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation

Wendi LiXiao YangWeiqing LiuYingce XiaJiang Bian

article2022AAAI77 citations

Proposes DDG-DA, a proactive adaptation framework that forecasts future streaming data distributions and resamples historical samples via a differentiable distribution distance to train predictive models before concept drift occurs.

Listen

Real-world machine learning systems frequently process streaming data that changes over time due to shifting operating environments, a challenge known as concept drift. Standard industry approaches reactively adapt models only after a shift occurs by retraining or fine-tuning them on the newest observed data. However, in many operational settings—such as energy networks and financial markets—environmental changes follow recurrent cycles or gradual, nonrandom patterns. Because conventional reactive techniques suffer from an inherent lag, models often degrade immediately when applied to upcoming data.

The article demonstrates and evaluates a proactive framework called DDG-DA (Data Distribution Generation for Predictable Concept Drift Adaptation). The primary objective is to forecast the upcoming data distribution and generate a synthetic, resampled historical dataset that mirrors future conditions, allowing models to train proactively before new data arrives.

The researchers designed a model-agnostic system that predicts sample-reweighting probabilities across historical records to construct the target future distribution. To make this optimization computationally efficient and differentiable, the framework incorporates a lightweight linear proxy model with a closed-form mathematical solution. The approach was evaluated against leading reactive baselines across three real-world domain benchmarks: stock price trend forecasting (spanning 2011 to 2020), electricity load forecasting, and solar irradiance prediction. The evaluation tested multiple underlying machine learning architectures, including linear models, neural networks, gradient-boosted decision trees, and recurrent networks.

The findings show that DDG-DA consistently outperforms standard reactive adaptation strategies across both classification and regression tasks. In financial forecasting, when paired with a gradient-boosted tree model, the method increased annualized investment returns to 25.65% compared to 17.49% for standard rolling retraining and 21.57% for the best reactive ensemble benchmark, while also improving risk-adjusted metrics like the Sharpe ratio. In physical utility forecasting, the approach reduced normalized mean absolute error from 0.1877 to 0.1622 in electricity demand and decreased mean absolute error from 21.77 to 18.80 in solar irradiance. Across all evaluated model types, proactively aligning training distributions yielded consistent performance gains.

These results indicate that accounting for predictable, cyclical shifts provides substantial operational advantages over standard reactive pipelines. Proactive adaptation reduces operational risk, improves predictive reliability, and avoids the performance drops typically caused by delayed model updates. Organizations managing time-sensitive forecasting systems can improve accuracy without replacing their preferred core prediction algorithms, as the data generation framework functions independently of the underlying model.

Organizations operating streaming prediction pipelines in structured environments should consider shifting from purely reactive retraining schedules to proactive distribution-weighting strategies. Development teams can pilot resampled training pipelines on existing historical data where predictable seasonal or cyclic patterns exist. Because the current framework assumes a stable, recurring drift pattern, future technical efforts should focus on dynamic updates to handle varying drift speeds and unexpected shocks.

  • Paper: Learning under Concept Drift: A Review, Jie Lu et al. (2019). This survey establishes the fundamental taxonomies of concept drift detection, understanding, and adaptation in streaming data that DDG-DA builds upon and contrasts itself against.
  • Paper: Learning with Drift Detection, João Gama et al. (2004). It introduces foundational statistical drift-detection mechanisms that trigger reactive model retraining, representing the traditional paradigm that DDG-DA aims to surpass with proactive distribution forecasting.
  • Paper: Learning from Time-Changing Data with Adaptive Windowing, Albert Bifet et al. (2007). It defines standard adaptive windowing algorithms for detecting distribution changes on streaming data, providing direct context for reactive streaming adaptation.
  • Paper: Mining concept-drifting data streams using ensemble classifiers, Haixun Wang et al. (2003). This work demonstrates how ensemble methods adapt to shifting data streams, serving as essential background on classical drift-handling methodologies.
  • Paper: Time-series Generative Adversarial Networks, Jinsung Yoon et al. (2019). It introduces generative methods tailored for sequential and temporal data dynamics, underpinning DDG-DA's strategy of generating synthetic streaming distributions.
  • Paper: Learning in the Presence of Concept Drift and Hidden Contexts, G. Widmer et al. (1996). It provides foundational principles for handling concept drift and recurrent contexts in dynamic data environments.
Cover for DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation

Abstract

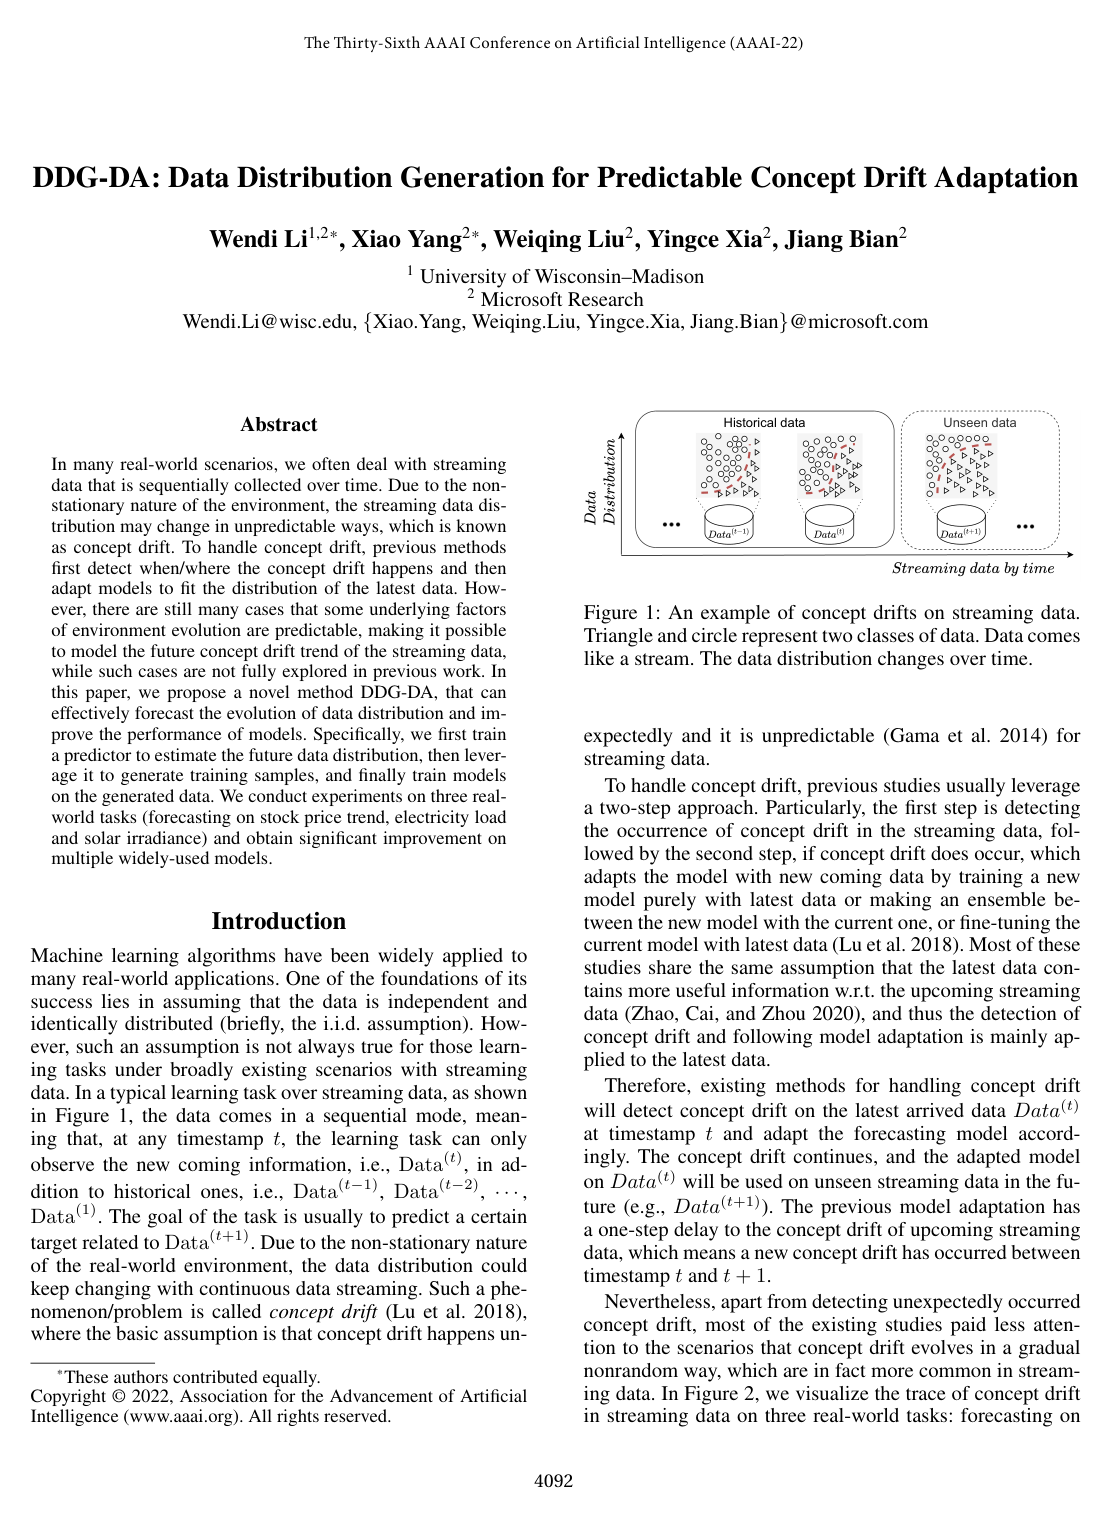
In many real-world scenarios, we often deal with streaming data that is sequentially collected over time. Due to the non-stationary nature of the environment, the streaming data distribution may change in unpredictable ways, which is known as concept drift. To handle concept drift, previous methods first detect when/where the concept drift happens and then adapt models to fit the distribution of the latest data. However, there are still many cases that some underlying factors of environment evolution are predictable, making it possible to model the future concept drift trend of the streaming data, while such cases are not fully explored in previous work. In this paper, we propose a novel method DDG-DA, that can effectively forecast the evolution of data distribution and improve the performance of models. Specifically, we first train a predictor to estimate the future data distribution, then leverage it to generate training samples, and finally train models on the generated data. We conduct experiments on three real-world tasks (forecasting on stock price trend, electricity load and solar irradiance) and obtain significant improvement on multiple widely-used models.

Table of Contents

  • Introduction
  • Background and Related Work Streaming Data and Concept Drift
  • Related Work
  • Method Design
  • Overall Design
  • Model Design and Learning Process
  • Experiments
  • Experiment Setup
  • Experiments Results
  • Conclusions and Future Works
  • References

Knowls

  1. Knowl 1 — Data Distribution Generation for Predictable Concept Drift Adaptation

    model/method

    Data Distribution Generation for Predictable Concept Drift Adaptation (DDG-DA) is a model-agnostic framework designed to handle predictable concept drift in streaming data. In a streaming setup, an algorithm at timestamp tt observes historical training data Dtrain(t)={(x(i),y(i))}i=t−kt−1\mathcal{D}_{\text{train}}^{(t)} = \{(\mathbf{x}^{(i)}, y^{(i)})\}_{i=t-k}^{t-1} of sliding memory window size kk, drawn from training distribution ptrain(t)(x,y)p_{\text{train}}^{(t)}(\mathbf{x}, y), and aims to predict on future unseen test data Dtest(t)={(x(i),y(i))}i=tt+τ\mathcal{D}_{\text{test}}^{(t)} = \{(\mathbf{x}^{(i)}, y^{(i)})\}_{i=t}^{t+\tau} drawn from test distribution ptest(t)(x,y)p_{\text{test}}^{(t)}(\mathbf{x}, y). Because of non-stationary environments, ptrain(t)(x,y)≠ptest(t)(x,y)p_{\text{train}}^{(t)}(\mathbf{x}, y) \neq p_{\text{test}}^{(t)}(\mathbf{x}, y).

    Rather than solely adapting reactively to the most recent historical data, DDG-DA proactively forecasts the future data distribution. DDG-DA parameterizes a generator model MΘM_\Theta that takes summary distribution features g(Dtrain(t))g(\mathcal{D}_{\text{train}}^{(t)}) as input (where g(⋅)g(\cdot) is a feature extractor) and generates sample resampling probabilities qtrain(t)=MΘ(g(Dtrain(t)))\mathbf{q}_{\text{train}}^{(t)} = M_\Theta(g(\mathcal{D}_{\text{train}}^{(t)})) for each instance in Dtrain(t)\mathcal{D}_{\text{train}}^{(t)}. These probabilities define a weighted resampled dataset Dresam(t)(Θ)\mathcal{D}_{\text{resam}}^{(t)}(\Theta) with joint distribution presam(t)(x,y;Θ)p_{\text{resam}}^{(t)}(\mathbf{x}, y; \Theta), which serves as the predicted distribution of Dtest(t)\mathcal{D}_{\text{test}}^{(t)}.

    The generator MΘM_\Theta is trained on a set of historical tasks Tasktrain={task(1),…,task(τ)}\mathcal{T}\text{ask}_{\text{train}} = \{\text{task}^{(1)}, \dots, \text{task}^{(\tau)}\} by minimizing the distribution distance between presam(t)(x,y;Θ)p_{\text{resam}}^{(t)}(\mathbf{x}, y; \Theta) and ptest(t)(x,y)p_{\text{test}}^{(t)}(\mathbf{x}, y). When deployed on unseen future test tasks Tasktest\mathcal{T}\text{ask}_{\text{test}}, any arbitrary downstream forecasting model is trained directly on the newly generated dataset Dresam(t)(Θ)\mathcal{D}_{\text{resam}}^{(t)}(\Theta) to evaluate on Dtest(t)\mathcal{D}_{\text{test}}^{(t)}.

  2. Knowl 2 — Bi-Level Optimization Objective of DDG-DA

    equation

    The training objective of DDG-DA minimizes the discrepancy between the resampled historical data distribution presam(t)(x,y;Θ)p_{\text{resam}}^{(t)}(\mathbf{x}, y; \Theta) and the true future test data distribution ptest(t)(x,y)p_{\text{test}}^{(t)}(\mathbf{x}, y) across training tasks task(t)∈Tasktrain\text{task}^{(t)} \in \mathcal{T}\text{ask}_{\text{train}}. Formulated via Kullback–Leibler divergence focusing on p(y∣x)p(y \mid \mathbf{x}) and assuming minor shifts in the marginal feature distribution p(x)p(\mathbf{x}):

    LΘ(task(t))=DKL(ptest(t)(x,y)∥presam(t)(x,y;Θ))=Ex∼ptest(t)(x)[DKL(ptest(t)(y∣x)∥presam(t)(y∣x;Θ))]\mathcal{L}_\Theta(\text{task}^{(t)}) = D_{\text{KL}}\left(p_{\text{test}}^{(t)}(\mathbf{x}, y) \parallel p_{\text{resam}}^{(t)}(\mathbf{x}, y; \Theta)\right) = \mathbb{E}_{\mathbf{x} \sim p_{\text{test}}^{(t)}(\mathbf{x})}\left[ D_{\text{KL}}\left(p_{\text{test}}^{(t)}(y \mid \mathbf{x}) \parallel p_{\text{resam}}^{(t)}(y \mid \mathbf{x}; \Theta)\right) \right]

    Under Gaussian conditional distribution assumptions ptest(t)(y∣x)=N(ytest(t)(x),σ)p_{\text{test}}^{(t)}(y \mid \mathbf{x}) = \mathcal{N}(y_{\text{test}}^{(t)}(\mathbf{x}), \sigma) and presam(t)(y∣x)=N(yresam(t)(x;Θ),σ)p_{\text{resam}}^{(t)}(y \mid \mathbf{x}) = \mathcal{N}(y_{\text{resam}}^{(t)}(\mathbf{x}; \Theta), \sigma) with constant variance σ\sigma, the task loss reduces to a mean squared error surrogate over Dtest(t)\mathcal{D}_{\text{test}}^{(t)} approximated by a proxy model yproxy(x;ϕ(t))y_{\text{proxy}}(\mathbf{x}; \boldsymbol{\phi}^{(t)}):

    LΘ(task(t))=12∑(x,y)∈Dtest(t)∥yproxy(x;ϕ(t))−y∥2\mathcal{L}_\Theta(\text{task}^{(t)}) = \frac{1}{2} \sum_{(\mathbf{x}, y) \in \mathcal{D}_{\text{test}}^{(t)}} \left\| y_{\text{proxy}}(\mathbf{x}; \boldsymbol{\phi}^{(t)}) - y \right\|^2

    The full model optimization is posed as a bi-level optimization problem:

    Θ∗=arg⁡min⁡Θ∑task(t)∈Tasktrain(∑(x,y)∈Dtest(t)∥yproxy(x;ϕ(t))−y∥2)\Theta^* = \arg\min_\Theta \sum_{\text{task}^{(t)} \in \mathcal{T}\text{ask}_{\text{train}}} \left( \sum_{(\mathbf{x}, y) \in \mathcal{D}_{\text{test}}^{(t)}} \left\| y_{\text{proxy}}(\mathbf{x}; \boldsymbol{\phi}^{(t)}) - y \right\|^2 \right)

    s.t.ϕ(t)=arg⁡min⁡ϕ∑(x′,y′)∈Dresam(t)(Θ)∥yproxy(x′;ϕ)−y′∥2\text{s.t.} \quad \boldsymbol{\phi}^{(t)} = \arg\min_{\boldsymbol{\phi}} \sum_{(\mathbf{x}', y') \in \mathcal{D}_{\text{resam}}^{(t)}(\Theta)} \left\| y_{\text{proxy}}(\mathbf{x}'; \boldsymbol{\phi}) - y' \right\|^2

  3. Knowl 3 — Closed-Form Proxy Model for Differentiable Distribution Matching

    model/method

    To render the bi-level optimization objective end-to-end differentiable and computationally efficient, DDG-DA employs a linear proxy model yproxy(x;ϕ(t))=xϕ(t)y_{\text{proxy}}(\mathbf{x}; \boldsymbol{\phi}^{(t)}) = \mathbf{x} \boldsymbol{\phi}^{(t)} in the lower-level optimization.

    The sample resampling probabilities qtrain(t)\mathbf{q}_{\text{train}}^{(t)} generated by MΘM_\Theta act as sample weights in a weighted least-squares regression over the historical data Dtrain(t)\mathcal{D}_{\text{train}}^{(t)}:

    lϕ(t)(Dresam(t)(Θ))=12∑(x,y)∈Dtrain(t)qtrain(t)(xϕ(t)−y)2=12(X(t)ϕ(t)−y(t))⊤Q(t)(X(t)ϕ(t)−y(t))l_{\boldsymbol{\phi}^{(t)}}(\mathcal{D}_{\text{resam}}^{(t)}(\Theta)) = \frac{1}{2} \sum_{(\mathbf{x}, y) \in \mathcal{D}_{\text{train}}^{(t)}} q_{\text{train}}^{(t)} \left( \mathbf{x}\boldsymbol{\phi}^{(t)} - y \right)^2 = \frac{1}{2} \left( \mathbf{X}^{(t)}\boldsymbol{\phi}^{(t)} - \mathbf{y}^{(t)} \right)^\top \mathbf{Q}^{(t)} \left( \mathbf{X}^{(t)}\boldsymbol{\phi}^{(t)} - \mathbf{y}^{(t)} \right)

    where X(t)\mathbf{X}^{(t)} and y(t)\mathbf{y}^{(t)} denote the concatenated feature matrix and label vector of Dtrain(t)\mathcal{D}_{\text{train}}^{(t)}, and Q(t)=diag⁡(qtrain(t))\mathbf{Q}^{(t)} = \operatorname{diag}(\mathbf{q}_{\text{train}}^{(t)}) is the diagonal weighting matrix.

    The lower-level problem admits an exact closed-form solution:

    ϕ(t)=((X(t))⊤Q(t)X(t))−1(X(t))⊤Q(t)y(t)\boldsymbol{\phi}^{(t)} = \left( (\mathbf{X}^{(t)})^\top \mathbf{Q}^{(t)} \mathbf{X}^{(t)} \right)^{-1} (\mathbf{X}^{(t)})^\top \mathbf{Q}^{(t)} \mathbf{y}^{(t)}

    Because ϕ(t)\boldsymbol{\phi}^{(t)} is an explicit, differentiable function of Q(t)\mathbf{Q}^{(t)} (and thus of the generator parameters Θ\Theta), gradients of the upper-level loss on Dtest(t)\mathcal{D}_{\text{test}}^{(t)} can be computed directly via standard backpropagation and optimized using stochastic gradient descent.

  4. Knowl 4 — Marginal Feature Invariance and Gaussian Conditional Distribution Assumptions

    assumption

    The derivation of the differentiable surrogate loss function for DDG-DA rests on two key mathematical assumptions:

    1. Marginal Feature Invariance: The difference between the marginal feature distributions ptest(t)(x)p_{\text{test}}^{(t)}(\mathbf{x}) of future data and presam(t)(x;Θ)p_{\text{resam}}^{(t)}(\mathbf{x}; \Theta) of the resampled training dataset is assumed to be minor, allowing the joint distribution KL divergence DKL(ptest(t)(x,y)∥presam(t)(x,y;Θ))D_{\text{KL}}(p_{\text{test}}^{(t)}(\mathbf{x}, y) \parallel p_{\text{resam}}^{(t)}(\mathbf{x}, y; \Theta)) to be reduced strictly to the expectation over the conditional label distribution shift Ex∼ptest(t)(x)[DKL(ptest(t)(y∣x)∥presam(t)(y∣x;Θ))]\mathbb{E}_{\mathbf{x} \sim p_{\text{test}}^{(t)}(\mathbf{x})}[D_{\text{KL}}(p_{\text{test}}^{(t)}(y \mid \mathbf{x}) \parallel p_{\text{resam}}^{(t)}(y \mid \mathbf{x}; \Theta))].

    2. Gaussian Conditional Distributions with Equal Variance: The conditional distributions are assumed to follow normal distributions with identical constant variance σ\sigma:

    ptest(t)(y∣x)=N(ytest(t)(x),σ)andpresam(t)(y∣x;Θ)=N(yresam(t)(x;Θ),σ)p_{\text{test}}^{(t)}(y \mid \mathbf{x}) = \mathcal{N}(y_{\text{test}}^{(t)}(\mathbf{x}), \sigma) \quad \text{and} \quad p_{\text{resam}}^{(t)}(y \mid \mathbf{x}; \Theta) = \mathcal{N}(y_{\text{resam}}^{(t)}(\mathbf{x}; \Theta), \sigma)

    Under this assumption, the KL divergence between the two Gaussians is proportional to the squared Euclidean distance between their mean predictions (yresam(t)(x;Θ)−ytest(t)(x))2(y_{\text{resam}}^{(t)}(\mathbf{x}; \Theta) - y_{\text{test}}^{(t)}(\mathbf{x}))^2.

  5. Knowl 5 — Performance Comparison Across Concept Drift Adaptation Baselines

    data/table

    Performance of DDG-DA evaluated against standard and state-of-the-art concept drift adaptation methods across three streaming data tasks: Stock Price Trend Forecasting (evaluated by Information Coefficient [IC], Information Ratio of IC [ICIR], Annualized Return [Ann.Ret.], Sharpe Ratio, and Maximum Drawdown [MDD]), Electricity Load Forecasting (evaluated by Normalized Mean Absolute Error [NMAE] and Normalized Root Mean Squared Error [NRMSE]), and Solar Irradiance Forecasting (evaluated by Skill Score (%), Mean Absolute Error [MAE], and Root Mean Squared Error [RMSE]). LightGBM is used as the base forecasting model for all model-agnostic methods.

    Method Stock Price Trend Forecasting Electricity Load Solar Irradiance
    IC ICIR Ann.Ret. Sharpe MDD NMAE NRMSE Skill (%) MAE RMSE
    RR 0.1178 1.0658 0.1749 1.5105 -0.2907 0.1877 0.9265 7.3047 21.7704 48.0117
    GF-Lin 0.1227 1.0804 0.1739 1.4590 -0.2690 0.1843 0.9109 9.3503 21.6878 46.9522
    GF-Exp 0.1234 1.0613 0.1854 1.5906 -0.2984 0.1839 0.9084 9.2652 21.6841 46.9963
    ARF 0.1240 1.0657 0.1994 1.8844 -0.1176 0.1733 0.8901 8.6267 21.0962 47.3270
    Condor 0.1273 1.0635 0.2157 2.1105 -0.1624 — — — — —
    DDG-DA 0.1312 1.1299 0.2565 2.4063 -0.1381 0.1622 0.8498 12.1327 18.7997 45.5110

    DDG-DA outperforms simple rolling retraining (RR), linear/exponential gradual forgetting (GF-Lin, GF-Exp), Adaptive Random Forest (ARF), and Condor across all three domains by generating resampled training sets tailored to anticipated future distributions rather than merely fitting recent historical data.

  6. Knowl 6 — Performance of DDG-DA Across Multiple Downstream Forecasting Model Architectures

    data/table

    Empirical validation demonstrating that DDG-DA is model-agnostic and consistently enhances the performance of diverse forecasting model backbones (Linear model, Multi-Layer Perceptron [MLP], LightGBM, Long Short-Term Memory [LSTM], and Gated Recurrent Unit [GRU]) compared to Rolling Retraining (RR) and Exponential Gradual Forgetting (GF-Exp).

    Model Method Stock Price Trend Forecasting Electricity Load Solar Irradiance
    IC ICIR Ann.Ret. Sharpe MDD NMAE NRMSE Skill (%) MAE RMSE
    Linear RR 0.0859 0.7946 0.1578 1.4211 -0.1721 0.2080 1.0207 1.4133 24.0910 51.0632
    GF-Exp 0.0863 0.8018 0.1632 1.4373 -0.1462 0.2009 0.9787 1.3660 24.1391 51.0877
    DDG-DA 0.0971 0.9193 0.1763 1.5733 -0.2130 0.1973 0.9702 3.7378 23.6901 49.8592
    MLP RR 0.1092 0.8647 0.1803 1.5200 -0.1797 0.1928 0.9682 8.2145 22.1285 47.5405
    GF-Exp 0.1091 0.8654 0.1889 1.6121 -0.1738 0.1898 0.9588 8.4668 21.6236 47.4098
    DDG-DA 0.1211 0.9921 0.2181 1.9409 -0.1864 0.1882 0.9537 10.0341 20.3422 46.5980
    LightGBM RR 0.1178 1.0658 0.1749 1.5105 -0.2907 0.1877 0.9265 7.3047 21.7704 48.0117
    GF-Exp 0.1234 1.0613 0.1854 1.5906 -0.2984 0.1839 0.9084 9.2652 21.6841 46.9963
    DDG-DA 0.1312 1.1299 0.2565 2.4063 -0.1381 0.1622 0.8498 12.1327 18.7997 45.5110
    LSTM RR 0.1003 0.7066 0.1899 1.8919 -0.1264 0.1494 0.8386 7.5990 21.7948 49.8593
    GF-Exp 0.1008 0.7110 0.1928 1.9238 -0.1450 0.1370 0.7369 11.4428 18.5193 45.8684
    DDG-DA 0.1049 0.7456 0.2122 2.0334 -0.1745 0.1298 0.7290 12.4905 18.3295 45.3257
    GRU RR 0.1122 0.9638 0.1841 1.6645 -0.1740 0.1352 0.7090 8.5684 21.0297 47.3572
    GF-Exp 0.1182 1.0007 0.1872 1.7588 -0.1207 0.1281 0.6688 8.4578 21.0399 47.4145
    DDG-DA 0.1183 1.0091 0.1928 1.7906 -0.1182 0.1250 0.6588 10.5918 20.1891 46.3092

    The results show that DDG-DA consistently improves performance across diverse downstream model classes, indicating that it captures intrinsic data concept drift patterns independently of the downstream forecasting architecture.

  7. Knowl 7 — Optimization Solver Comparison: Closed-Form Proxy vs. Iterative Gradient-Based Hyperparameter Optimization

    data/table

    Comparison between the proposed closed-form linear proxy optimization in DDG-DA and an alternative bi-level optimization approach (extDDG−DA† ext{DDG-DA}^\dagger) that employs an MLP proxy model solved iteratively via kk-step Gradient-based Hyperparameter Optimization (GHO) on the stock price trend forecasting task.

    Method IC ICIR Ann.Ret. Sharpe MDD
    RR 0.1092 0.8647 0.1803 1.5200 -0.1797
    GF-Lin 0.1090 0.8641 0.1880 1.5682 -0.1656
    GF-Exp 0.1091 0.8654 0.1889 1.6121 -0.1738
    DDG-DA†\text{DDG-DA}^\dagger 0.1204 0.9732 0.2065 1.9243 -0.1705
    DDG-DA 0.1211 0.9921 0.2181 1.9409 -0.1864

    While DDG-DA†\text{DDG-DA}^\dagger outperforms traditional baselines (RR, GF-Lin, GF-Exp) due to its larger model capacity, it slightly underperforms standard DDG-DA. This occurs because the number of gradient steps kk in GHO introduces optimization sensitivity: smaller kk leads to underfitting the proxy model, while larger kk increases computational overhead and the risk of overfitting.

  8. Knowl 8 — Assumption of Static Concept Drift Patterns Across Task Splits

    limitation

    A primary limitation of DDG-DA is its assumption that the underlying pattern and frequency of concept drift remain static across temporal task splits. Specifically, it assumes that the drift dynamics observed during the training tasks Tasktrain\mathcal{T}\text{ask}_{\text{train}} persist unchanged into future deployment tasks Tasktest\mathcal{T}\text{ask}_{\text{test}}. If the nature or frequency of concept drift undergoes abrupt structural shifts between training and test horizons, the static generator MΘM_\Theta cannot dynamically adjust its distribution estimation strategy.

Coverage note — None was omitted.

References

  1. 1.Alippi, C.; and Roveri, M. 2008. Just-in-time adaptive classifiers—Part II: Designing the classifier. IEEE Transactions on Neural Networks, 19(12): 2053–2064.
  2. 2.Bach, S. H.; and Maloof, M. A. 2008. Paired learners for concept drift. In 2008 Eighth IEEE International Conference on Data Mining, 23–32. IEEE.
  3. 3.Baydin, A. G.; Cornish, R.; Rubio, D. M.; Schmidt, M.; and Wood, F. 2017. Online learning rate adaptation with hypergradient descent. arXiv preprint arXiv:1703.04782.
  4. 4.Baydin, A. G.; and Pearlmutter, B. A. 2014. Automatic differentiation of algorithms for machine learning. arXiv preprint arXiv:1404.7456.
  5. 5.Bengio, Y. 2000. Gradient-based optimization of hyperparameters. Neural computation, 12(8): 1889–1900.
  6. 6.Bertinetto, L.; Henriques, J. F.; Torr, P. H.; and Vedaldi, A. 2018. Meta-learning with differentiable closed-form solvers. arXiv preprint arXiv:1805.08136.
  7. 7.Chung, J.; Gulcehre, C.; Cho, K.; and Bengio, Y. 2014. Empirical evaluation of gated recurrent neural networks on sequence modeling. arXiv preprint arXiv:1412.3555.
  8. 8.Fan, Y.; Xia, Y.; Wu, L.; Xie, S.; Liu, W.; Bian, J.; Qin, T.; Li, X.-Y.; and Liu, T.-Y. 2020. Learning to teach with deep interactions. arXiv preprint arXiv:2007.04649.
  9. 9.Gama, J.; Žliobaitė, I.; Bifet, A.; Pechenizkiy, M.; and Bouchachia, A. 2014. A survey on concept drift adaptation. ACM computing surveys (CSUR), 46(4): 1–37.
  10. 10.Gardner, M. W.; and Dorling, S. 1998. Artificial neural networks (the multilayer perceptron)—a review of applications in the atmospheric sciences. Atmospheric environment, 32(14-15): 2627–2636.
  11. 11.Gomes, H. M.; Barddal, J. P.; Ferreira, L. E. B.; and Bifet, A. 2018. Adaptive random forests for data stream regression. In ESANN.
  12. 12.Gomes, H. M.; Bifet, A.; Read, J.; Barddal, J. P.; Enembreck, F.; Pfharinger, B.; Holmes, G.; and Abdessalem, T. 2017. Adaptive random forests for evolving data stream classification. Machine Learning, 106(9-10): 1469–1495.
  13. 13.Goodfellow, I.; Bengio, Y.; Courville, A.; and Bengio, Y. 2016. Deep learning. 2. MIT press Cambridge.
  14. 14.Gould, S.; Fernando, B.; Cherian, A.; Anderson, P.; Cruz, R. S.; and Guo, E. 2016. On differentiating parameterized argmin and argmax problems with application to bi-level optimization. arXiv preprint arXiv:1607.05447.
  15. 15.Graybill, F. A. 1976. Theory and application of the linear model, volume 183. Duxbury press North Scituate, MA.
  16. 16.Grinold, R. C.; and Kahn, R. N. 2000. Active portfolio management. McGraw Hill New York.
  17. 17.Hochreiter, S.; and Schmidhuber, J. 1997. Long short-term memory. Neural computation, 9(8): 1735–1780.
  18. 18.Ke, G.; Meng, Q.; Finley, T.; Wang, T.; Chen, W.; Ma, W.; Ye, Q.; and Liu, T.-Y. 2017. Lightgbm: A highly efficient gradient boosting decision tree. In Advances in neural information processing systems, 3146–3154.
  19. 19.Kelly, M. G.; Hand, D. J.; and Adams, N. M. 1999. The impact of changing populations on classifier performance. In Proceedings of the fifth ACM SIGKDD international conference on Knowledge discovery and data mining, 367–371.
  20. 20.Khamassi, I.; Sayed-Mouchaweh, M.; Hammami, M.; and Ghédira, K. 2018. Discussion and review on evolving data streams and concept drift adapting. Evolving systems, 9(1): 1–23.
  21. 21.Kleinbaum, D. G.; Dietz, K.; Gail, M.; Klein, M.; and Klein, M. 2002. Logistic regression. Springer.
  22. 22.Klinkenberg, R. 2004. Learning drifting concepts: Example selection vs. example weighting. Intelligent data analysis, 8(3): 281–300.
  23. 23.Koychev, I. 2000. Gradual forgetting for adaptation to concept drift. In Proceedings of ECAI 2000 Workshop on Current Issues in Spatio-Temporal Reasoning.
  24. 24.Koychev, I. 2002. Tracking changing user interests through prior-learning of context. In International Conference on Adaptive Hypermedia and Adaptive Web-Based Systems, 223–232. Springer.
  25. 25.Lee, K.; Maji, S.; Ravichandran, A.; and Soatto, S. 2019. Meta-learning with differentiable convex optimization. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 10657–10665.
  26. 26.Liu, B. 2003. Kernel-based nonlinear discriminator with closed-form solution. In International Conference on Neural Networks and Signal Processing, 2003. Proceedings of the 2003, volume 1, 41–44. IEEE.
  27. 27.Lu, J.; Liu, A.; Dong, F.; Gu, F.; Gama, J.; and Zhang, G. 2018. Learning under concept drift: A review. IEEE Transactions on Knowledge and Data Engineering, 31(12): 2346–2363.
  28. 28.Maclaurin, D.; Duvenaud, D.; and Adams, R. 2015. Gradient-based hyperparameter optimization through reversible learning. In International conference on machine learning, 2113–2122. PMLR.
  29. 29.Minku, L. L.; White, A. P.; and Yao, X. 2009. The impact of diversity on online ensemble learning in the presence of concept drift. IEEE Transactions on knowledge and Data Engineering, 22(5): 730–742.
  30. 30.Pedro, H. T.; Larson, D. P.; and Coimbra, C. F. 2019. A comprehensive dataset for the accelerated development and benchmarking of solar forecasting methods. Journal of Renewable and Sustainable Energy, 11(3): 036102.
  31. 31.Ren, S.; Liao, B.; Zhu, W.; and Li, K. 2018. Knowledge-maximized ensemble algorithm for different types of concept drift. Information Sciences, 430: 261–281.
  32. 32.Ruppert, D.; and Wand, M. P. 1994. Multivariate locally weighted least squares regression. The annals of statistics, 1346–1370.
  33. 33.Van der Maaten, L.; and Hinton, G. 2008. Visualizing data using t-SNE. Journal of machine learning research, 9(11).
  34. 34.Webb, G. I.; Hyde, R.; Cao, H.; Nguyen, H. L.; and Petitjean, F. 2016. Characterizing concept drift. Data Mining and Knowledge Discovery, 30(4): 964–994.
  35. 35.Yang, Y.; Wu, X.; and Zhu, X. 2005. Combining proactive and reactive predictions for data streams. In Proceedings of the eleventh ACM SIGKDD international conference on Knowledge discovery in data mining, 710–715.
  36. 36.Zhao, P.; Cai, L.-W.; and Zhou, Z.-H. 2020. Handling concept drift via model reuse. Machine Learning, 109(3): 533–568.
  37. 37.Žliobaitė, I. 2009. Combining time and space similarity for small size learning under concept drift. In International Symposium on Methodologies for Intelligent Systems, 412–421. Springer.
  38. 38.Žliobaitė, I.; Pechenizkiy, M.; and Gama, J. 2016. An overview of concept drift applications. Big data analysis: new algorithms for a new society, 91–114.

Citation

MLA
Li, W., et al. “DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation”. arXiv, 2022, http://arxiv.org/abs/2201.04038v2.
APA
Li, W., Yang, X., Liu, W., Xia, Y., & Bian, J. (2022). DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation. arXiv. http://arxiv.org/abs/2201.04038v2
Chicago
Li, W., X. Yang, W. Liu, Y. Xia, and J. Bian. 2022. “DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation”. arXiv. http://arxiv.org/abs/2201.04038v2.
Harvard
Li, W. et al. (2022) “DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation”, arXiv [Preprint]. Available at: http://arxiv.org/abs/2201.04038v2.
Vancouver
1. Li W, Yang X, Liu W, Xia Y, Bian J (2022) DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation. arXiv

BibTeX

@article{li2022ddg,
  title = {DDG-DA: Data Distribution Generation for Predictable Concept Drift Adaptation},
  author = {Li, Wendi and Yang, Xiao and Liu, Weiqing and Xia, Yingce and Bian, Jiang},
  year = {2022},
  journal = {arXiv},
  url = {http://arxiv.org/abs/2201.04038v2},
  eprint = {2201.04038}
}
Metadata:arXiv

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF