Task-specific Inconsistency Alignment for Domain Adaptive Object Detection

Liang ZhaoLimin Wang

article2022CVPR109 citations

Proposes a domain adaptive object detection framework that uses auxiliary predictors to independently measure and minimize task-specific inconsistencies across domains, effectively decoupling feature alignment for classification and bounding box regression.

Listen

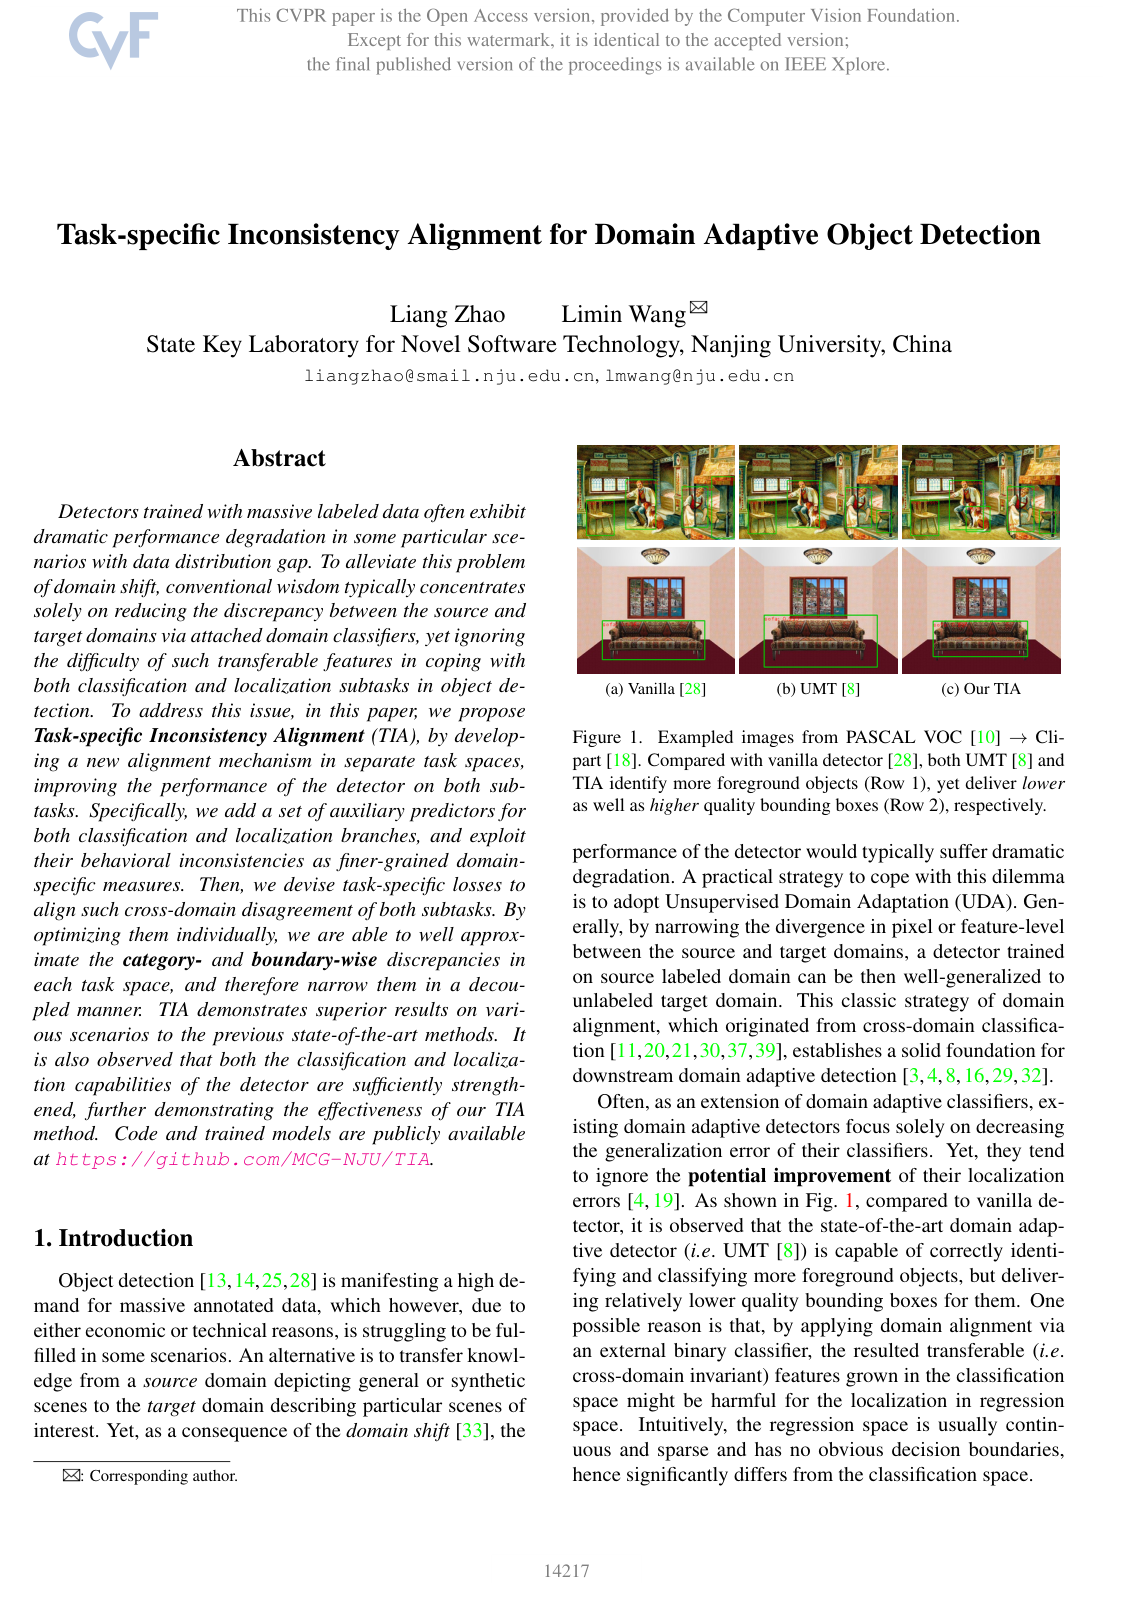
Modern computer vision models require large amounts of labeled data to detect objects accurately, but acquiring manual annotations across every real-world operating environment is prohibitively costly. When deployed in new target environments featuring different visual styles, adverse weather, or distinct sensor hardware, standard models suffer severe performance drops due to domain shift. Existing adaptation techniques attempt to make internal image features cross-domain invariant using global classifiers. However, because object detection simultaneously requires identifying categories and drawing precise bounding boxes, conventional adaptation often improves category recognition while degrading spatial localization quality.

The main objective of the article is to demonstrate and evaluate Task-specific Inconsistency Alignment (TIA), a framework designed to decouple the adaptation of classification and localization into separate task spaces. This approach aims to minimize both category and boundary errors independently without requiring target-domain labels.

The authors conducted extensive experimental evaluations using a standard two-stage object detector across three benchmark adaptation scenarios: natural photos to artistic illustrations (PASCAL VOC to Clipart), clear weather to foggy driving conditions (Cityscapes to Foggy Cityscapes), and cross-camera sensor transitions (KITTI and Cityscapes). The method adds auxiliary prediction heads—multiple auxiliary classifiers and localizers—and optimizes dedicated disagreement metrics. Category differences are evaluated using Shannon Entropy across auxiliary classifier outputs, while localization dispersion is measured using the standard deviation across auxiliary boundary predictions.

The key findings demonstrate that TIA consistently outperforms prior state-of-the-art adaptation techniques. In the real-to-artistic shift, TIA achieved a mean average precision of 46.3%, exceeding the previous best method by 2.2 percentage points. In normal-to-foggy conditions, the framework scored 42.3% mean average precision, surpassing both existing domain adaptation methods and the model trained directly on labeled target data. In cross-camera adaptations, the method attained benchmark-leading scores of 44.0% and 75.9%. Furthermore, detailed error analysis showed that TIA reduces false background detections while achieving lower bounding box localization error than non-adapted models, solving a long-standing trade-off in cross-domain detection.

These results indicate that independent, task-specific alignment allows organizations to deploy robust vision systems into unannotated, high-variance operational environments without sacrificing bounding box precision. This capability reduces deployment risks and operational labeling costs across automated perception tasks, such as autonomous vehicles operating in unseen weather conditions or camera systems running on novel sensor hardware.

Organizations developing perception models for heterogeneous deployment environments should adopt decoupled, inconsistency-based alignment strategies rather than relying on global, single-space domain adaptation. Before full-scale deployment, technical teams should run pilot tests to calibrate the ratio of auxiliary predictors and loss weighting parameters for their specific sensor configurations.

The primary limitations noted in the article include sensitivity to extreme label distribution shifts across domains and potential optimization instability inherent in adversarial single-stage training. Within the evaluated scenarios, confidence in the reported performance gains is high due to consistent, cross-benchmark validation against established baselines.

  • Paper: Domain Adaptive Faster R-CNN for Object Detection in the Wild, Yuhua Chen et al. (2018). This foundational paper establishes adversarial domain adaptation specifically for object detection at both image and instance levels, providing the direct baseline architecture that the source paper builds upon and decouples.
  • Paper: Maximum Classifier Discrepancy for Unsupervised Domain Adaptation, Kuniaki Saito et al. (2017). It introduces the concept of utilizing auxiliary classifiers and prediction discrepancies to align target distributions near task-specific decision boundaries, directly inspiring the source paper's inconsistency alignment mechanism.
  • Paper: TOOD: Task-aligned One-stage Object Detection, Chengjian Feng et al. (2021). This work explores the intrinsic misalignment and competition between classification and localization branches in modern object detectors, directly informing the source paper's decoupled task-space approach.
  • Paper: Conditional Adversarial Domain Adaptation, Mingsheng Long et al. (2017). It formulates conditional adversarial alignment across complex multi-class structures, establishing prerequisite theory for conditioned cross-domain feature adaptation.
  • Paper: Unsupervised Domain Adaptation by Backpropagation, Yaroslav Ganin et al. (2015). This landmark publication introduced adversarial gradient reversal for learning domain-invariant representations, forming the underlying mechanism used across domain adaptive detectors.
Cover for Task-specific Inconsistency Alignment for Domain Adaptive Object Detection

Abstract

Detectors trained with massive labeled data often exhibit dramatic performance degradation in some particular scenarios with data distribution gap. To alleviate this problem of domain shift, conventional wisdom typically concentrates solely on reducing the discrepancy between the source and target domains via attached domain classifiers, yet ignoring the difficulty of such transferable features in coping with both classification and localization subtasks in object detection. To address this issue, in this paper, we propose Task-specific Inconsistency Alignment (TIA), by developing a new alignment mechanism in separate task spaces, improving the performance of the detector on both subtasks. Specifically, we add a set of auxiliary predictors for both classification and localization branches, and exploit their behavioral inconsistencies as finer-grained domain-specific measures. Then, we devise task-specific losses to align such cross-domain disagreement of both subtasks. By optimizing them individually, we are able to well approximate the category- and boundary-wise discrepancies in each task space, and therefore narrow them in a decoupled manner. TIA demonstrates superior results on various scenarios to the previous state-of-the-art methods. It is also observed that both the classification and localization capabilities of the detector are sufficiently strengthened, further demonstrating the effectiveness of our TIA method. Code and trained models are publicly available at https://github.com/MCG-NJU/TIA.

Table of Contents

  • 1. Introduction
  • 2. Related Work
  • 3. Methodology
  • 3.1. Baseline Model
  • 3.2. Task-specific Inconsistency Alignment
  • 3.2.1 Inconsistency Alignment Mechanism
  • 3.2.2 Classification-specific Loss
  • 3.2.3 Localization-specific Loss
  • 3.2.4 Overall Objective
  • 3.3. Theoretical Insights
  • 4. Experiments
  • 4.1. Experimental Setup
  • 4.2. Real to Artistic
  • 4.3. Normal to Foggy
  • 4.4. Cross Camera
  • 5. Analysis
  • 5.1. Ablation Study
  • 5.2. Error Analysis
  • 6. Conclusions and Limitations
  • Acknowledgments
  • References

Knowls

  1. Knowl 1 — Baseline detector and task-specific training objective

    model/method

    The framework is built on Faster R-CNN. A backbone produces image-level features, a region proposal network produces proposals, and ROI Align followed by fully connected layers produces one ROI feature used by the classification and bounding-box regression heads. The detection loss is

    Ldet=Lrpn+Lroi.\mathcal{L}_{\mathrm{det}}=\mathcal{L}_{\mathrm{rpn}}+\mathcal{L}_{\mathrm{roi}}.

    The baseline also applies domain-adversarial alignment to KK image-level and ROI-level feature sets. Each feature set is passed through a gradient-reversal layer to a binary domain discriminator. With fk,if_{k,i} denoting feature ii from alignment level kk, dk,isd_{k,i}^{s} and dk,itd_{k,i}^{t} denoting its source and target domain labels, nsn_s and ntn_t denoting the numbers of source and target features in a minibatch, and ℓBCE\ell_{\mathrm{BCE}} denoting binary cross-entropy, the feature-alignment loss is

    Lda=∑k=1K(1ns∑i=1nsℓBCE ⁣(Dk(fk,i),dk,is)+1nt∑i=1ntℓBCE ⁣(Dk(fk,i),dk,it)).\mathcal{L}_{\mathrm{da}}=\sum_{k=1}^{K}\left(\frac{1}{n_s}\sum_{i=1}^{n_s}\ell_{\mathrm{BCE}}\!\left(D_k(f_{k,i}),d_{k,i}^{s}\right)+\frac{1}{n_t}\sum_{i=1}^{n_t}\ell_{\mathrm{BCE}}\!\left(D_k(f_{k,i}),d_{k,i}^{t}\right)\right).

    The proposed Task-specific Inconsistency Alignment (TIA) module is attached to the shared ROI representation and adds separate classification- and localization-specific alignment losses. With trade-off weights λ1,λ2,λ3\lambda_1,\lambda_2,\lambda_3, the final objective is

    L=Ldet+λ1Lda+λ2Ldacls+λ3Ldaloc.\mathcal{L}=\mathcal{L}_{\mathrm{det}}+\lambda_1\mathcal{L}_{\mathrm{da}}+\lambda_2\mathcal{L}_{\mathrm{da}}^{\mathrm{cls}}+\lambda_3\mathcal{L}_{\mathrm{da}}^{\mathrm{loc}}.

    The source images are additionally mixed with target-like source images generated by CycleGAN to encourage pixel-level consistency.

  2. Knowl 2 — Auxiliary predictors create separate classification and localization task spaces

    model/method

    For each ROI representation r^\hat r, TIA retains the primary classifier CpC^p and localizer LpL^p, and adds two independent sets of auxiliary predictors: NN auxiliary classifiers {Cja}j=1N\{C_j^a\}_{j=1}^{N} and MM auxiliary localizers {Lja}j=1M\{L_j^a\}_{j=1}^{M}. In the reported experiments, N=8N=8 and M=4M=4.

    The auxiliary classifiers and localizers receive the same higher-level ROI feature but form separate prediction spaces. Gradient-reversal layers are inserted between the fully connected ROI representation and the auxiliary predictors. The auxiliary predictors therefore act as task-specific inconsistency discriminators rather than as external binary domain classifiers. Their outputs measure category-wise disagreement for classification and boundary-wise disagreement for localization, allowing the two tasks to be aligned independently even though the detector initially produces a coupled ROI feature.

  3. Knowl 3 — Source supervision of auxiliary classifiers and localizers

    equation

    All auxiliary predictors are trained on labeled source ROIs. For source ROI ii, r^i\hat r_i is the fully connected ROI feature, yisy_i^s is its category label, and bisb_i^s is its four-coordinate bounding-box target. The auxiliary classification loss Lcls\mathcal{L}^{\mathrm{cls}} is cross-entropy and the auxiliary localization loss Lloc\mathcal{L}^{\mathrm{loc}} is smooth-L1L_1. The source-supervision objective is

    Laux=1ns∑i=1ns[∑j=1NLcls ⁣(Cja(r^i),yis)+∑j=1MLloc ⁣(Lja(r^i),bis)].\mathcal{L}_{\mathrm{aux}}=\frac{1}{n_s}\sum_{i=1}^{n_s}\left[\sum_{j=1}^{N}\mathcal{L}^{\mathrm{cls}}\!\left(C_j^a(\hat r_i),y_i^s\right)+\sum_{j=1}^{M}\mathcal{L}^{\mathrm{loc}}\!\left(L_j^a(\hat r_i),b_i^s\right)\right].

    Here nsn_s is the number of source ROIs in the minibatch, NN is the number of auxiliary classifiers, and MM is the number of auxiliary localizers. Gradients from the auxiliary predictors are detached when propagating into the primary predictors, so auxiliary supervision does not directly alter the training of the primitive classification and localization heads.

  4. Knowl 4 — Adversarial alignment of task-specific inconsistency

    equation

    TIA uses the disagreement of auxiliary predictors as a domain signal. Let Liatask\mathcal{L}_{\mathrm{ia}}^{\mathrm{task}} be the inconsistency-aware loss for either classification or localization, let PraP_r^a denote auxiliary predictor rr, and let R=NR=N for classification or R=MR=M for localization. For target ROI features r^it\hat r_i^t, source ROI features r^is\hat r_i^s, and source and target minibatch sizes ns,ntn_s,n_t, the task-specific domain-adaptation objective is

    Ldatask=−1nt∑i=1ntLiatask ⁣(P1a(r^it),…,PRa(r^it))−1ns∑i=1ns[−Liatask ⁣(P1a(r^is),…,PRa(r^is))].\mathcal{L}_{\mathrm{da}}^{\mathrm{task}} =-\frac{1}{n_t}\sum_{i=1}^{n_t}\mathcal{L}_{\mathrm{ia}}^{\mathrm{task}}\!\left(P_1^a(\hat r_i^t),\ldots,P_R^a(\hat r_i^t)\right) -\frac{1}{n_s}\sum_{i=1}^{n_s}\left[-\mathcal{L}_{\mathrm{ia}}^{\mathrm{task}}\!\left(P_1^a(\hat r_i^s),\ldots,P_R^a(\hat r_i^s)\right)\right].

    For target ROIs, the auxiliary predictors are driven to maximize behavioral disagreement, while gradient reversal makes the ROI feature generator reduce that disagreement. For source ROIs, the opposite-sign inconsistency objective encourages consistent source predictions and strengthens the auxiliary predictors. The resulting single-stage adversarial game diversifies the auxiliary predictors while learning ROI features that make source and target task behavior harder to distinguish. The classification and localization versions use separate predictor sets and separate losses.

  5. Knowl 5 — Shannon-entropy loss for classification inconsistency

    equation

    For a classification ROI, let Z∈RN×CZ\in\mathbb{R}^{N\times C} contain the predicted class probabilities from NN auxiliary classifiers over CC classes. Let z:c∈RNz_{:c}\in\mathbb{R}^{N} be the vector of predictions for class cc, let z^:c=softmax⁡(z:c)\hat z_{:c}=\operatorname{softmax}(z_{:c}), and define the class-weight vector q∈RCq\in\mathbb{R}^{C} by qc=1N∑j=1Nzjcq_c=\frac{1}{N}\sum_{j=1}^{N}z_{jc}. The entropy-weighted classification inconsistency loss is

    Liacls=−∑c=1C[(∑j=1N−z^jclog⁡z^jc)(1N∑j=1Nzjc)].\mathcal{L}_{\mathrm{ia}}^{\mathrm{cls}} =-\sum_{c=1}^{C}\left[\left(\sum_{j=1}^{N}-\hat z_{jc}\log \hat z_{jc}\right)\left(\frac{1}{N}\sum_{j=1}^{N}z_{jc}\right)\right].

    The first factor is the Shannon entropy of the auxiliary predictions for class cc; the second factor weights that entropy by the average confidence assigned to the class. Maximizing this loss for target features encourages auxiliary classifiers to develop sharper and more diverse class decisions, whereas the gradient-reversed feature generator minimizes it and thereby flattens cross-domain category-wise discrepancies. The confidence weighting prevents low-probability classes from dominating the inconsistency signal.

  6. Knowl 6 — Standard-deviation loss for localization inconsistency

    equation

    For a localization ROI, let Z∈RM×4Z\in\mathbb{R}^{M\times 4} contain the four bounding-box coordinate predictions from MM auxiliary localizers. Let z:r∈RMz_{:r}\in\mathbb{R}^{M} be the vector of predictions for coordinate r∈{1,2,3,4}r\in\{1,2,3,4\}, let zˉr=1M∑j=1Mzjr\bar z_r=\frac{1}{M}\sum_{j=1}^{M}z_{jr} be its mean, and let ∥⋅∥2\|\cdot\|_2 denote the Euclidean norm. TIA measures localizer disagreement with

    Lialoc=14M∑r=14∥z:r−zˉr1M∥2,\mathcal{L}_{\mathrm{ia}}^{\mathrm{loc}} =\frac{1}{4\sqrt{M}}\sum_{r=1}^{4}\left\|z_{:r}-\bar z_r\mathbf{1}_{M}\right\|_2,

    where 1M∈RM\mathbf{1}_{M}\in\mathbb{R}^{M} is the all-ones vector. This standard-deviation-like statistic is applied independently to the four box coordinates. It is chosen because the detector's regression space is continuous and sparse, while the L2L_2 norm makes the inconsistency signal sensitive to outlying localizer predictions, which are informative for boundary ambiguity. Adversarial optimization maximizes disagreement for target ROIs and uses gradient reversal to reduce it in the generated task features.

  7. Knowl 7 — Decoupled domain-adaptation bound for classification and localization

    theoretical result

    Let Ds\mathcal{D}_s and Dt\mathcal{D}_t be source and target input distributions with labeling functions fsf_s and ftf_t, let H\mathcal{H} be a hypothesis space, and let εs(h,fs)\varepsilon_s(h,f_s) and εt(h,ft)\varepsilon_t(h,f_t) denote source and target disagreement errors of hypothesis hh. The standard domain-adaptation bound used by the paper is

    εt(h,ft)≤εs(h,fs)+12dHΔH(Ds,Dt)+λ∗,\varepsilon_t(h,f_t)\leq \varepsilon_s(h,f_s)+\frac{1}{2}d_{\mathcal{H}\Delta\mathcal{H}}(\mathcal{D}_s,\mathcal{D}_t)+\lambda^*,

    where dHΔHd_{\mathcal{H}\Delta\mathcal{H}} is the domain divergence and λ∗\lambda^* is the error of an ideal joint hypothesis. Applying one such divergence to both detector tasks gives separate bounds for a classifier labeling function fcf^c and a localizer labeling function flf^l, but the same divergence must serve two structurally different spaces.

    TIA instead uses task-specific hypotheses h1h_1 and h2h_2 and task-specific multi-class scoring disagreement divergences. The resulting bounds are

    εt(h1,ftc)≤εs(h1,fsc)+12dMCSDcls(Ds,Dt)+λ∗,\varepsilon_t(h_1,f_t^c)\leq \varepsilon_s(h_1,f_s^c)+\frac{1}{2}d_{\mathrm{MCSD}}^{\mathrm{cls}}(\mathcal{D}_s,\mathcal{D}_t)+\lambda^*, εt(h2,ftl)≤εs(h2,fsl)+12dMCSDloc(Ds,Dt)+λ∗.\varepsilon_t(h_2,f_t^l)\leq \varepsilon_s(h_2,f_s^l)+\frac{1}{2}d_{\mathrm{MCSD}}^{\mathrm{loc}}(\mathcal{D}_s,\mathcal{D}_t)+\lambda^*.

    Here dMCSDclsd_{\mathrm{MCSD}}^{\mathrm{cls}} and dMCSDlocd_{\mathrm{MCSD}}^{\mathrm{loc}} are respectively the classification- and localization-specific multi-class scoring disagreement divergences. The paper connects maximizing the corresponding inconsistency-aware losses to narrowing these two divergences independently, which provides a theoretical rationale for separately improving category and boundary transferability.

  8. Knowl 8 — Training protocol and evaluation settings

    experimental setup

    All experiments use Faster R-CNN with ROI Align and resize each input image so that its shorter side is 600 pixels. Optimization uses SGD with initial learning rate 0.0010.001; the learning rate is divided by 1010 every 50,000 iterations. Each minibatch contains one source-domain image and one target-domain image. VGG16 pretrained on ImageNet is used for Normal-to-Foggy and Cross-Camera experiments, with 70,000 total training iterations. ResNet101 pretrained on ImageNet is used for Real-to-Artistic experiments, with 120,000 total iterations.

    TIA uses N=8N=8 auxiliary classifiers, M=4M=4 auxiliary localizers, and trade-off parameters λ1=1.0\lambda_1=1.0, λ2=1.0\lambda_2=1.0, and λ3=0.01\lambda_3=0.01. Performance is measured by mean average precision at an IoU threshold of 0.50.5. The evaluated transfers are PASCAL VOC →\rightarrow Clipart, Cityscapes →\rightarrow Foggy Cityscapes, and both KITTI →\rightarrow Cityscapes and Cityscapes →\rightarrow KITTI; the Cross-Camera evaluation uses their common car category.

  9. Knowl 9 — TIA improves detection across three domain-shift scenarios

    data/table

    The reported mean average precision values compare domain-adaptive detectors, the source-only detector, the authors' baseline, and TIA under the same evaluation protocol. A dash indicates that the cited method did not report that transfer direction.

    Could not parse LaTeX table

    TIA is the best reported method in all four transfers. Relative to the authors' baseline, it improves mAP by 5.25.2 points on VOC →\rightarrow Clipart, 3.13.1 points on Cityscapes →\rightarrow Foggy Cityscapes, 1.61.6 points on KITTI →\rightarrow Cityscapes, and 2.92.9 points on Cityscapes →\rightarrow KITTI. It also exceeds the cited previous best by 2.22.2 points on VOC →\rightarrow Clipart and 0.50.5 points on Cityscapes →\rightarrow Foggy Cityscapes. On Foggy Cityscapes, TIA reaches 42.3%42.3\%, which is 0.40.4 points higher than the detector trained using annotated target images only.

  10. Knowl 10 — Ablations show complementary task gains and fewer localization errors

    data/table

    On PASCAL VOC →\rightarrow Clipart, the baseline obtains 41.1%41.1\% mAP. Applying classification-specific TIA alone gives 44.7%44.7\% mAP, a 3.63.6-point improvement, while localization-specific TIA alone gives 43.2%43.2\%, a 2.12.1-point improvement. Combining the two proposed losses gives 46.3%46.3\% mAP.

    The loss comparison is:

    Could not parse LaTeX table

    Varying the number of auxiliary predictors shows that increasing the number of auxiliary classifiers generally contributes more than increasing the number of localizers. The paper attributes the limited benefit of many localizers to the sparsity and heterogeneous clustering of regression outputs.

    For the Foggy Cityscapes →\rightarrow Cityscapes error analysis, the authors select the top-KK predictions in each class, where KK is the number of ground-truth boxes in that class. A detection is Correct when IoU ≥0.5\geq 0.5, MisLocalization when 0.3≤0.3\leq IoU <0.5<0.5, and Background when IoU <0.3<0.3. The percentages are:

    Could not parse LaTeX table

    TIA produces the highest fraction of correct high-confidence detections and the lowest mislocalization rate among the compared adaptive detectors, indicating that its gains are not limited to classification confidence but also improve bounding-box quality.

Coverage note — The paper's brief limitation statement—that label shift and training instability remain unresolved—is omitted as a separate knowl because it contains no further analysis or proposed remedy; full per-class AP values are also omitted in favor of the comparative mAP results that establish the contribution.

References

  1. 1.Shai Ben-David, John Blitzer, Koby Crammer, Alex Kulesza, Fernando Pereira, and Jennifer Wortman Vaughan. A theory of learning from different domains. Machine learning, 79(1):151–175, 2010. 2, 5
  2. 2.Chaoqi Chen, Jiongcheng Li, Zebiao Zheng, Yue Huang, Xinghao Ding, and Yizhou Yu. Dual bipartite graph learning: A general approach for domain adaptive object detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 2703–2712, 2021. 2, 6
  3. 3.Chaoqi Chen, Zebiao Zheng, Xinghao Ding, Yue Huang, and Qi Dou. Harmonizing transferability and discriminability for adapting object detectors. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 8869–8878, 2020. 1, 2, 3, 4, 6, 7, 8
  4. 4.Yuhua Chen, Wen Li, Christos Sakaridis, Dengxin Dai, and Luc Van Gool. Domain adaptive faster r-cnn for object detection in the wild. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 3339–3348, 2018. 1, 2, 3, 6, 7, 8
  5. 5.Marius Cordts, Mohamed Omran, Sebastian Ramos, Timo Rehfeld, Markus Enzweiler, Rodrigo Benenson, Uwe Franke, Stefan Roth, and Bernt Schiele. The cityscapes dataset for semantic urban scene understanding. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 3213–3223, 2016. 7
  6. 6.Shuhao Cui, Shuhui Wang, Junbao Zhuo, Liang Li, Qingming Huang, and Qi Tian. Towards discriminability and diversity: Batch nuclear-norm maximization under label insufficient situations. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 3941–3950, 2020. 5
  7. 7.Jia Deng, Wei Dong, Richard Socher, Li-Jia Li, Kai Li, and Li Fei-Fei. Imagenet: A large-scale hierarchical image database. In 2009 IEEE conference on computer vision and pattern recognition, pages 248–255. Ieee, 2009. 6
  8. 8.Jinhong Deng, Wen Li, Yuhua Chen, and Lixin Duan. Unbiased mean teacher for cross-domain object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 4091–4101, 2021. 1, 2, 4, 6, 7, 8
  9. 9.Ur¨un Dogan, Tobias Glasmachers, and Christian Igel. A¨ unified view on multi-class support vector classification. J. Mach. Learn. Res., 17(45):1–32, 2016. 4
  10. 10.Mark Everingham, Luc Van Gool, Christopher KI Williams, John Winn, and Andrew Zisserman. The pascal visual object classes (voc) challenge. International journal of computer vision, 88(2):303–338, 2010. 1, 7
  11. 11.Yaroslav Ganin, Evgeniya Ustinova, Hana Ajakan, Pascal Germain, Hugo Larochelle, François Laviolette, Mario Marchand, and Victor Lempitsky. Domain-adversarial training of neural networks. The journal of machine learning research, 17(1):2096–2030, 2016. 1, 2, 3, 4, 6, 8
  12. 12.Andreas Geiger, Philip Lenz, and Raquel Urtasun. Are we ready for autonomous driving? the kitti vision benchmark suite. In 2012 IEEE conference on computer vision and pattern recognition, pages 3354–3361. IEEE, 2012. 7
  13. 13.Ross Girshick, Jeff Donahue, Trevor Darrell, and Jitendra Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 580–587, 2014. 1, 5
  14. 14.Kaiming He, Georgia Gkioxari, Piotr Dollar, and Ross Girshick. Mask r-cnn. In Proceedings of the IEEE international conference on computer vision, pages 2961–2969, 2017. 1, 3, 6
  15. 15.Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 770–778, 2016. 6
  16. 16.Zhenwei He and Lei Zhang. Multi-adversarial faster-rcnn for unrestricted object detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 6668–6677, 2019. 1, 2, 6, 7
  17. 17.Han-Kai Hsu, Chun-Han Yao, Yi-Hsuan Tsai, Wei-Chih Hung, Hung-Yu Tseng, Maneesh Singh, and Ming-Hsuan Yang. Progressive domain adaptation for object detection. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision, pages 749–757, 2020. 2
  18. 18.Naoto Inoue, Ryosuke Furuta, Toshihiko Yamasaki, and Kiyoharu Aizawa. Cross-domain weakly-supervised object detection through progressive domain adaptation. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 5001–5009, 2018. 1, 2, 7
  19. 19.Junguang Jiang, Yifei Ji, Ximei Wang, Yufeng Liu, Jianmin Wang, and Mingsheng Long. Regressive domain adaptation for unsupervised keypoint detection. arXiv preprint arXiv:2103.06175, 2021. 1, 2, 5
  20. 20.Abhishek Kumar, Prasanna Sattigeri, Kahini Wadhawan, Leonid Karlinsky, Rogerio Feris, William T Freeman, and Gregory Wornell. Co-regularized alignment for unsupervised domain adaptation. arXiv preprint arXiv:1811.05443, 2018. 1, 2
  21. 21.Chen-Yu Lee, Tanmay Batra, Mohammad Haris Baig, and Daniel Ulbricht. Sliced wasserstein discrepancy for unsupervised domain adaptation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 10285–10295, 2019. 1, 2, 4, 8
  22. 22.Congcong Li, Dawei Du, Libo Zhang, Longyin Wen, Tiejian Luo, Yanjun Wu, and Pengfei Zhu. Spatial attention pyramid network for unsupervised domain adaptation. In European Conference on Computer Vision, pages 481–497. Springer, 2020. 2, 6, 7
  23. 23.Xiang Li, Wenhai Wang, Xiaolin Hu, Jun Li, Jinhui Tang, and Jian Yang. Generalized focal loss v2: Learning reliable localization quality estimation for dense object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 11632–11641, 2021. 5
  24. 24.Xiang Li, Wenhai Wang, Lijun Wu, Shuo Chen, Xiaolin Hu, Jun Li, Jinhui Tang, and Jian Yang. Generalized focal loss: Learning qualified and distributed bounding boxes for dense object detection. arXiv preprint arXiv:2006.04388, 2020. 5
  25. 25.Tsung-Yi Lin, Priya Goyal, Ross Girshick, Kaiming He, and Piotr Dollar. Focal loss for dense object detection. In Proceedings of the IEEE international conference on computer vision, pages 2980–2988, 2017. 1
  26. 26.Ping Luo, Fuzhen Zhuang, Hui Xiong, Yuhong Xiong, and Qing He. Transfer learning from multiple source domains via consensus regularization. In Proceedings of the 17th ACM conference on Information and knowledge management, pages 103–112, 2008. 2
  27. 27.Yawei Luo, Liang Zheng, Tao Guan, Junqing Yu, and Yi Yang. Taking a closer look at domain shift: Category-level adversaries for semantics consistent domain adaptation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 2507–2516, 2019. 2
  28. 28.Shaoqing Ren, Kaiming He, Ross Girshick, and Jian Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. arXiv preprint arXiv:1506.01497, 2015. 1, 3, 6, 8
  29. 29.Kuniaki Saito, Yoshitaka Ushiku, Tatsuya Harada, and Kate Saenko. Strong-weak distribution alignment for adaptive object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 6956–6965, 2019. 1, 2, 6, 7, 8
  30. 30.Kuniaki Saito, Kohei Watanabe, Yoshitaka Ushiku, and Tatsuya Harada. Maximum classifier discrepancy for unsupervised domain adaptation. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 3723–3732, 2018. 1, 2, 4, 8
  31. 31.Christos Sakaridis, Dengxin Dai, and Luc Van Gool. Semantic foggy scene understanding with synthetic data. International Journal of Computer Vision, 126(9):973–992, 2018. 7
  32. 32.Zhiqiang Shen, Harsh Maheshwari, Weichen Yao, and Marios Savvides. Scl: Towards accurate domain adaptive object detection via gradient detach based stacked complementary losses. arXiv preprint arXiv:1911.02559, 2019. 1, 2, 3, 6, 7
  33. 33.Hidetoshi Shimodaira. Improving predictive inference under covariate shift by weighting the log-likelihood function. Journal of statistical planning and inference, 90(2):227–244, 2000. 1
  34. 34.Rui Shu, Hung H Bui, Hirokazu Narui, and Stefano Ermon. A dirt-t approach to unsupervised domain adaptation. arXiv preprint arXiv:1802.08735, 2018. 5
  35. 35.Changjian Shui, Qi Chen, Jun Wen, Fan Zhou, Christian Gagné, and Boyu Wang. Beyond H-divergence: Domain adaptation theory with jensen-shannon divergence. arXiv preprint arXiv:2007.15567, 2020. 6
  36. 36.Karen Simonyan and Andrew Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556, 2014. 6
  37. 37.Eric Tzeng, Judy Hoffman, Kate Saenko, and Trevor Darrell. Adversarial discriminative domain adaptation. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 7167–7176, 2017. 1, 2
  38. 38.Vibashan VS, Vikram Gupta, Poojan Oza, Vishwanath A Sindagi, and Vishal M Patel. Mega-cda: Memory guided attention for category-aware unsupervised domain adaptive object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 4516–4526, 2021. 2, 6, 7
  39. 39.Yabin Zhang, Bin Deng, Hui Tang, Lei Zhang, and Kui Jia. Unsupervised multi-class domain adaptation: Theory, algorithms, and practice. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2020. 1, 2, 4, 6, 8
  40. 40.Yuchen Zhang, Tianle Liu, Mingsheng Long, and Michael Jordan. Bridging theory and algorithm for domain adaptation. In International Conference on Machine Learning, pages 7404–7413. PMLR, 2019. 4
  41. 41.Yabin Zhang, Hui Tang, Kui Jia, and Mingkui Tan. Domain-symmetric networks for adversarial domain adaptation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 5031–5040, 2019. 2, 4
  42. 42.Yixin Zhang, Zilei Wang, and Yushi Mao. Rpn prototype alignment for domain adaptive object detector. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 12425–12434, 2021. 2, 6, 7
  43. 43.Ganlong Zhao, Guanbin Li, Ruijia Xu, and Liang Lin. Collaborative training between region proposal localization and classification for domain adaptive object detection. In European Conference on Computer Vision, pages 86–102. Springer, 2020. 2, 6, 7
  44. 44.Zhedong Zheng and Yi Yang. Rectifying pseudo label learning via uncertainty estimation for domain adaptive semantic segmentation. International Journal of Computer Vision, 129(4):1106–1120, 2021. 2
  45. 45.Xingyi Zhou, Arjun Karpur, Chuang Gan, Linjie Luo, and Qixing Huang. Unsupervised domain adaptation for 3d keypoint estimation via view consistency. In Proceedings of the European conference on computer vision (ECCV), pages 137–153, 2018. 2, 5
  46. 46.Jun-Yan Zhu, Taesung Park, Phillip Isola, and Alexei A Efros. Unpaired image-to-image translation using cycle-consistent adversarial networks. In Proceedings of the IEEE international conference on computer vision, pages 2223–2232, 2017. 2, 4

Citation

MLA
Zhao, L., and L. Wang. “Task-specific Inconsistency Alignment for Domain Adaptive Object Detection”. arXiv, 2022, http://arxiv.org/abs/2203.15345v1.
APA
Zhao, L., & Wang, L. (2022). Task-specific Inconsistency Alignment for Domain Adaptive Object Detection. arXiv. http://arxiv.org/abs/2203.15345v1
Chicago
Zhao, L., and L. Wang. 2022. “Task-specific Inconsistency Alignment for Domain Adaptive Object Detection”. arXiv. http://arxiv.org/abs/2203.15345v1.
Harvard
Zhao, L. and Wang, L. (2022) “Task-specific Inconsistency Alignment for Domain Adaptive Object Detection”, arXiv [Preprint]. Available at: http://arxiv.org/abs/2203.15345v1.
Vancouver
1. Zhao L, Wang L (2022) Task-specific Inconsistency Alignment for Domain Adaptive Object Detection. arXiv

BibTeX

@article{zhao2022task,
  title = {Task-specific Inconsistency Alignment for Domain Adaptive Object Detection},
  author = {Zhao, Liang and Wang, Limin},
  year = {2022},
  journal = {arXiv},
  url = {http://arxiv.org/abs/2203.15345v1},
  eprint = {2203.15345}
}
Metadata:arXiv

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: IEEE