Unified Training of Universal Time Series Forecasting Transformers
Gerald WooChenghao LiuAkshat KumarCaiming XiongSilvio SavareseDoyen Sahoo
Presents Moirai, a universal time series transformer trained on the 27-billion-observation LOTSA archive, which handles arbitrary variate counts and frequencies to match or outperform dataset-specific models in zero-shot forecasting.
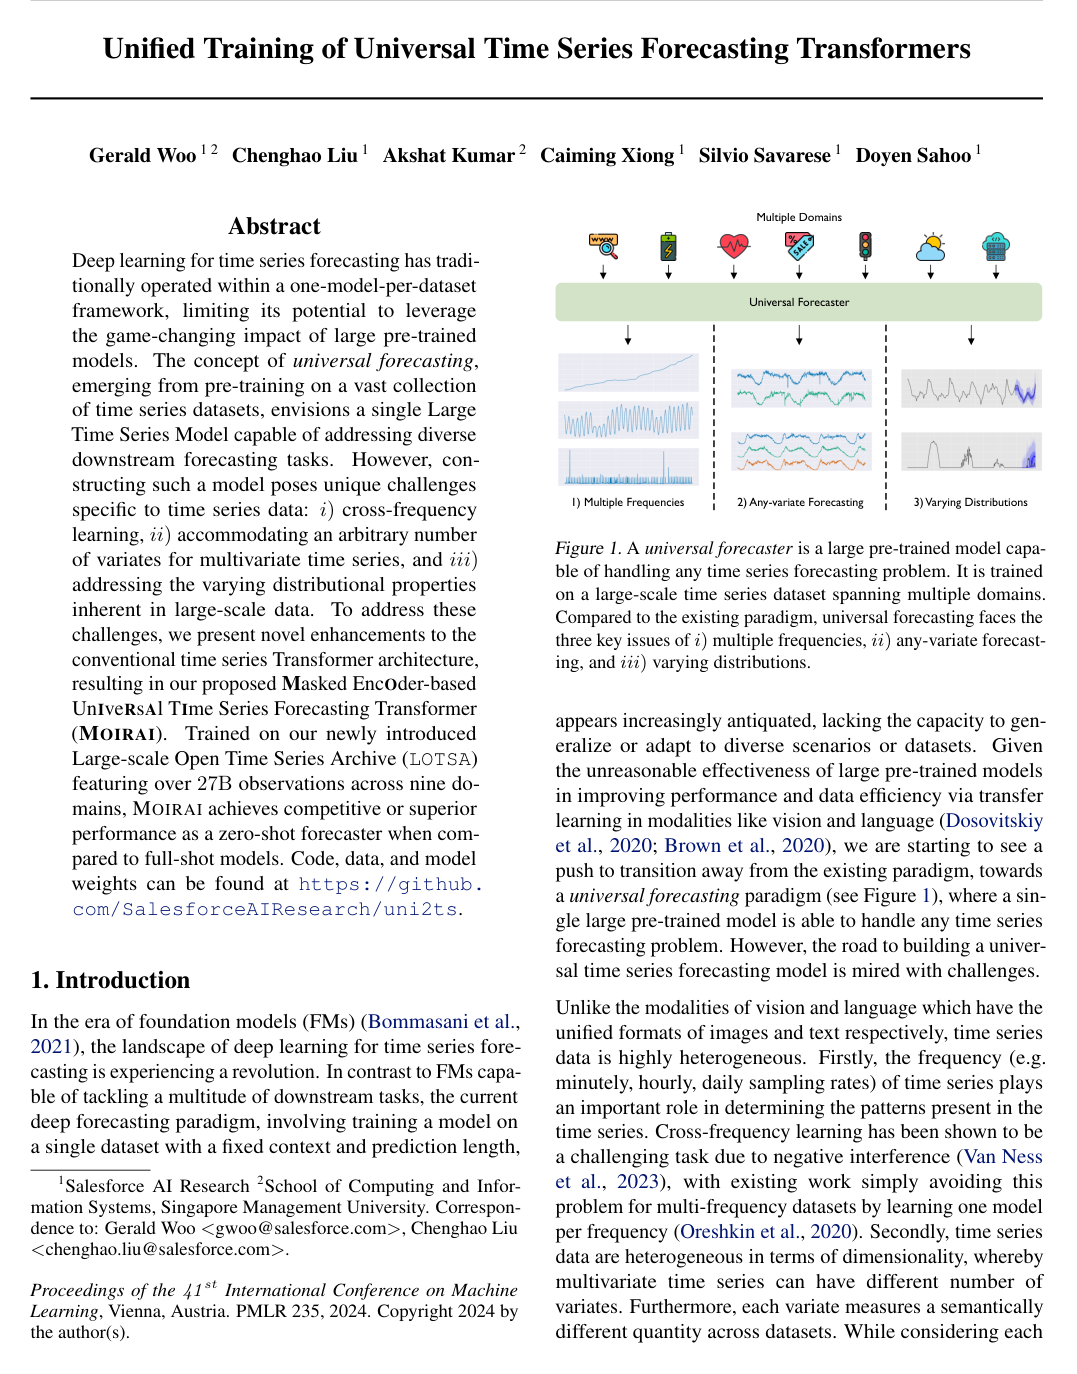
Deep learning for time series forecasting has traditionally required training a specialized, individual model for every dataset and forecasting task. This one-model-per-dataset approach prevents organizations from exploiting large pre-trained foundation models that can generalize across varied scenarios, leading to high training costs and slow adaptation to new business problems. Constructing a single universal model is difficult because time series data are highly heterogeneous: recording frequencies vary widely, multivariate series contain arbitrary numbers of variates, and data distributions differ significantly across domains.
The article designs and demonstrates MOIRAI, a universal time series forecasting model powered by a masked encoder architecture. Its core objective is to evaluate whether a single pre-trained model can accurately forecast across diverse frequencies, dimensions, and domains without task-specific training, operating as an off-the-shelf zero-shot forecaster.
The approach introduces three architectural mechanisms to resolve data heterogeneity: multi-patch-size projection layers that scale patch lengths to recording frequencies, an any-variate attention mechanism that processes flattened multivariate sequences using positional embeddings and attention biases, and a mixture of parametric distributions that models positive, skewed, and heavy-tailed data. To train MOIRAI, the authors compiled the Large-scale Open Time Series Archive (LOTSA), an open repository spanning nine domains and over 27 billion observations. MOIRAI was trained across three sizes (14 million, 91 million, and 311 million parameters) using random sampling of context and horizon windows alongside sequence packing to maximize throughput. Evaluations spanned in-distribution benchmark tests as well as zero-shot evaluations on unseen datasets for both probabilistic and long-horizon forecasting.
The investigation produced four central findings. First, across standard in-distribution benchmark datasets, MOIRAI outperformed all classical, statistical, and specialized deep learning baselines while operating as a single unified system. Second, in zero-shot probabilistic forecasting across diverse domains like energy, climate, and sales, MOIRAI matched or beat specialized models that were custom-trained directly on those target datasets. Third, on long-horizon forecasting tasks, MOIRAI generated competitive or superior mean squared error metrics relative to state-of-the-art models without requiring local fine-tuning. Fourth, architectural ablations showed that removing multi-frequency patching, any-variate attention, mixture distributions, or large-scale data diversity caused severe performance degradation, while sequence packing reduced token padding from approximately 61% to less than 0.4% and improved model performance by 16% at equal compute.
These results demonstrate that universal time series models are commercially viable and can replace fragmented, dataset-specific modeling pipelines. Shifting toward large pre-trained forecasters amortizes initial training costs across thousands of downstream tasks, cuts continuous model maintenance expenses, and reduces operational deployment time from days to milliseconds per inference. Moreover, producing principled probabilistic outputs allows leaders to quantify operational risks and uncertainty far more reliably than deterministic point forecasters.
Organizations evaluating forecasting architecture should consider adopting pre-trained universal forecasters for new deployment environments to avoid expensive, bespoke model pipelines. For existing deployments, teams should run pilot side-by-side evaluations comparing zero-shot universal models against fine-tuned specialized models on high-value business metrics. Continued work should explore hyperparameter optimization, the integration of multimodal inputs such as tabular features and text, and the establishment of formal scaling laws across larger parameter counts.
Confidence in these findings is high for standard operational frequencies and horizons up to several thousand steps, as verified by extensive multi-domain testing. However, readers should note limitations: the model relies on heuristic rules for frequency-to-patch mapping, exhibits limited scaling gains from the base to the largest parameter size on select long-sequence tasks, and faces token length constraints when handling extremely high-dimensional multivariate series.
- Paper: A Time Series is Worth 64 Words: Long-term Forecasting with Transformers, Yuqi Nie et al. (2023). Introduces patch-based tokenization and channel-independence for time series Transformers, foundational design principles directly adapted and generalized in Moirai.
- Paper: iTransformer: Inverted Transformers Are Effective for Time Series Forecasting, Yong Liu et al. (2023). Establishes an inverted attention architecture for multivariate time series that underpins modern Transformer designs for arbitrary variates.
- Paper: A Transformer-based Framework for Multivariate Time Series Representation Learning, George Zerveas et al. (2020). Pioneers unsupervised masked pre-training for multivariate time series Transformer encoders, which Moirai builds upon for universal forecasting.
- Paper: Reversible Instance Normalization for Accurate Time-Series Forecasting against Distribution Shift, Taesung Kim et al. (2022). Introduces reversible instance normalization (RevIN) to combat distribution shifts in time series, addressing a key challenge handled in universal pre-training.
- Paper: Non-stationary Transformers: Exploring the Stationarity in Time Series Forecasting, Yong Liu et al. (2022). Analyzes non-stationarity and attention degradation in time series Transformers, providing critical context for modeling diverse cross-domain distributions.
- Paper: Transformers in Time Series: A Survey, Qingsong Wen et al. (2022). Surveys the core architectural adaptations and tokenization strategies of Transformers in time series, framing the structural challenges tackled by Moirai.
- Paper: Autoformer: Decomposition Transformers with Auto-Correlation for Long-Term Series Forecasting, Haixu Wu et al. (2021). Provides a benchmark architecture for long-term time series forecasting using decomposition and temporal sub-series attention.
- Paper: Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting, Haoyi Zhou et al. (2021). Introduces efficient long-sequence Transformer mechanisms for time series forecasting, serving as an essential architectural predecessor.
No sufficiently relevant recommendations were found.