Stochastic Interpolants with Data-Dependent Couplings

Michael S. AlbergoMark GoldsteinNicholas Matthew BoffiRajesh RanganathEric Vanden-Eijnden

article2024ICML72 citations

Proposes a framework for building continuous-time generative models by coupling base and target distributions conditioned on data, enabling efficient simulation-free training for conditional image super-resolution and in-painting tasks.

Listen

Modern generative artificial intelligence models, such as continuous flows and diffusions, synthesize complex data by transforming simple, unstructured random noise into realistic samples. Historically, these systems treat the initial noise distribution and the target data distribution as completely independent. This conventional design ignores available contextual structure, leading to curved, inefficient mathematical trajectories and computationally intensive sampling routines. The article addresses this operational inefficiency by investigating how directly coupling the initial starting point to the target data can streamline generative processes for image restoration tasks.

The main objective of the article is to establish and evaluate a unified mathematical framework for continuous generative models that incorporates data-dependent pairings between the base density and the target data. The authors demonstrate how to train these transport maps efficiently and evaluate their performance on high-resolution image restoration tasks, specifically image completion and super-resolution.

The researchers formulated their approach using stochastic interpolants, constructing continuous-time paths between correlated pairs rather than independent noise. To optimize the system, they designed a simulation-free, square-loss regression training objective that estimates velocity fields using standard neural network architectures. The method was evaluated on standard benchmark datasets, including ImageNet at resolutions of 256x256 and 512x512 pixels, comparing performance against leading diffusion models and uncoupled interpolant baselines using standard image quality metrics.

The evaluation revealed several key findings in order of importance. First, incorporating data-dependent couplings substantially improved visual quality and consistency; for 64x64 to 256x256 image super-resolution, the proposed method achieved a validation Fréchet Inception Distance score of 2.05, outperforming advanced diffusion baselines such as Cascaded Diffusion (4.63) and Image-to-Image Schrödinger Bridges (2.70). Second, in image completion tasks, the coupled approach achieved an improved score of 1.13 compared to 1.35 for the uncoupled baseline. Third, the framework eliminated the need for complex, ad-hoc sampling corrections—such as iterative pixel replacement or Monte Carlo adjustments—because structural constraints like fixed known pixels are maintained naturally. Finally, the theoretical analysis demonstrated that data-dependent pairing directly minimizes transport costs, ensuring straighter transformation trajectories and improved numerical stability.

These findings indicate that adapting the initial noise base directly to the task at hand yields higher output fidelity while simplifying the generative pipeline. By avoiding iterative simulation steps during training and discarding complex post-processing during sampling, this framework offers a practical path toward reducing computational overhead, infrastructure costs, and latency in production deployments. Furthermore, this method demonstrates that tailoring initial states is mathematically sound and superior to treating generation purely as standard noise removal.

Organizations developing or deploying continuous generative pipelines should consider adopting data-dependent pairings to improve model performance and sampling efficiency in restoration workflows. Potential immediate applications highlighted by the source include image restoration, molecular generation with fixed chemical scaffolding, and autoencoder error correction. Before broad deployment, teams should run targeted pilot benchmarks on their domain-specific datasets to identify the most effective base constructions and noise parameters.

The primary limitations noted in the article center on its experimental scope, which focuses heavily on image domains. Adapting the method to other complex data structures may require specialized mathematical configurations for each task. Additionally, broader risks common to generative models—such as the potential generation of biased or misleading content—remain an important governance consideration when deploying these systems into production.

  • Paper: Flow Matching for Generative Modeling, Yaron Lipman et al. (2023). Flow Matching introduces the simulation-free vector-field regression framework and probability paths that provide essential context for the source’s stochastic-interpolant training objective.
  • Paper: Multisample Flow Matching: Straightening Flows with Minibatch Couplings, Aram-Alexandre Pooladian et al. (2023). Multisample Flow Matching shows how coupling noise and data through minibatch optimal transport can straighten generative paths, a direct precursor to the source’s data-dependent couplings.
Cover for Stochastic Interpolants with Data-Dependent Couplings

Abstract

Generative models inspired by dynamical transport of measure – such as flows and diffusions – construct a continuous-time map between two probability densities. Conventionally, one of these is the target density, only accessible through samples, while the other is taken as a simple base density that is data-agnostic. In this work, using the framework of stochastic interpolants, we formalize how to couple the base and the target densities, whereby samples from the base are computed conditionally given samples from the target in a way that is different from (but does not preclude) incorporating information about class labels or continuous embeddings. This enables us to construct dynamical transport maps that serve as conditional generative models. We show that these transport maps can be learned by solving a simple square loss regression problem analogous to the standard independent setting. We demonstrate the usefulness of constructing dependent couplings in practice through experiments in super-resolution and in-painting. The code is available at https://github.com/interpolants/couplings.

Table of Contents

  • 1. Introduction
  • 2. Related Work
  • 3. Stochastic interpolants with couplings
  • 3.1. Transport equations and conditional generative models
  • 3.2. Designing data-dependent couplings
  • 3.3. Reducing transport costs via coupling
  • 3.4. Learning and Sampling
  • 4. Numerical experiments
  • 4.1. In-painting
  • 4.2. Super-resolution on Imagenet
  • 5. Discussion, challenges, and future work
  • Acknowledgements
  • Impact Statement
  • References
  • A. Omitted proofs with conditioning variables incorporated
  • B. Further experimental details

Knowls

  1. Knowl 1 — Data-dependent coupling is distinct from conditioning

    definition

    Let x1x_1 be a target sample with density ρ1\rho_1 and x0x_0 a base sample with density ρ0\rho_0. A coupling specifies their joint distribution while preserving both marginals; the paper’s data-dependent construction is ρ(x0,x1)=ρ1(x1)ρ0(x0∣x1)\rho(x_0,x_1)=\rho_1(x_1)\rho_0(x_0\mid x_1), with ∫ρ1(x1)ρ0(x0∣x1) dx1=ρ0(x0)\int \rho_1(x_1)\rho_0(x_0\mid x_1)\,dx_1=\rho_0(x_0). This makes the base sample depend on the particular target sample. Separately, a conditioning variable ξ\xi—such as a class label, text embedding, or geometric input—can be supplied to the velocity field to define conditional generation. Conditioning the velocity and coupling x0x_0 to x1x_1 play different roles: conditioning specifies which conditional distribution to generate from, whereas the coupling specifies how base and target samples are paired. The framework allows both roles to be used together.

  2. Knowl 2 — Stochastic interpolant for a coupled pair of distributions

    definition

    For dd-dimensional random vectors x0,x1x_0,x_1 drawn jointly from a density ρ(x0,x1)\rho(x_0,x_1) with finite second moments and marginals ρ0\rho_0 and ρ1\rho_1, define the stochastic interpolant ItI_t by

    It=αtx0+βtx1+γtz,0≤t≤1,I_t=\alpha_t x_0+\beta_t x_1+\gamma_t z,\qquad 0\le t\le1,

    where z∼N(0,Id)z\sim\mathcal{N}(0,I_d) is independent of (x0,x1)(x_0,x_1). The time-dependent coefficients have differentiable αt,βt,γt2\alpha_t,\beta_t,\gamma_t^2, satisfy α0=β1=1\alpha_0=\beta_1=1, α1=β0=γ0=γ1=0\alpha_1=\beta_0=\gamma_0=\gamma_1=0, and obey αt2+βt2+γt2>0\alpha_t^2+\beta_t^2+\gamma_t^2>0 for every tt. Thus I0=x0I_0=x_0 and I1=x1I_1=x_1, regardless of whether the endpoint samples are independent. One example is αt=1−t\alpha_t=1-t, βt=t\beta_t=t, and γt=2t(1−t)\gamma_t=\sqrt{2t(1-t)}.

  3. Knowl 3 — Transport equation and regression characterization

    theoretical result

    For the interpolant It=αtx0+βtx1+γtzI_t=\alpha_t x_0+\beta_t x_1+\gamma_t z, let ρt\rho_t denote its density and define the velocity and auxiliary vector fields by bt(x)=E[I˙t∣It=x]b_t(x)=\mathbb{E}[\dot I_t\mid I_t=x] and gt(x)=E[z∣It=x]g_t(x)=\mathbb{E}[z\mid I_t=x]. The density interpolates between ρ0\rho_0 and ρ1\rho_1 and satisfies the continuity equation

    ∂tρt(x)+∇⋅(bt(x)ρt(x))=0.\partial_t\rho_t(x)+\nabla\cdot\bigl(b_t(x)\rho_t(x)\bigr)=0.

    Whenever γt≠0\gamma_t\ne0, its score satisfies ∇log⁡ρt(x)=−γt−1gt(x)\nabla\log\rho_t(x)=-\gamma_t^{-1}g_t(x). Both fields can be learned as unique minimizers of sample-estimable quadratic objectives:

    Lb(b^)=∫01E[∣b^t(It)∣2−2I˙t⋅b^t(It)]dt,Lg(g^)=∫01E[∣g^t(It)∣2−2z⋅g^t(It)]dt.\mathcal{L}_b(\widehat b)=\int_0^1\mathbb{E}\left[|\widehat b_t(I_t)|^2-2\dot I_t\cdot\widehat b_t(I_t)\right]dt, \qquad \mathcal{L}_g(\widehat g)=\int_0^1\mathbb{E}\left[|\widehat g_t(I_t)|^2-2z\cdot\widehat g_t(I_t)\right]dt.

    Here the expectations are over the coupled pair (x0,x1)(x_0,x_1) and independent standard Gaussian zz. The same characterization applies conditionally: for a fixed conditioning value ξ\xi, replace the fields and densities by their conditional versions and condition the expectations on ξ\xi.

  4. Knowl 4 — Coupled interpolants induce probability flows and diffusions

    theoretical result

    For a coupled stochastic interpolant, define bt(x)=E[I˙t∣It=x]b_t(x)=\mathbb{E}[\dot I_t\mid I_t=x] and gt(x)=E[z∣It=x]g_t(x)=\mathbb{E}[z\mid I_t=x]. The probability-flow ODE X˙t=bt(Xt)\dot X_t=b_t(X_t) transports the base law ρ0\rho_0 at t=0t=0 to the target law ρ1\rho_1 at t=1t=1; solving the ODE backward transports ρ1\rho_1 to ρ0\rho_0. The same endpoint laws are obtained from the forward and backward SDEs, respectively:

    dXtF=[bt(XtF)−ϵtγt−1gt(XtF)]dt+2ϵt dWt,dX_t^F=\left[b_t(X_t^F)-\epsilon_t\gamma_t^{-1}g_t(X_t^F)\right]dt+\sqrt{2\epsilon_t}\,dW_t, dXtR=[bt(XtR)+ϵtγt−1gt(XtR)]dt+2ϵt dWt.dX_t^R=\left[b_t(X_t^R)+\epsilon_t\gamma_t^{-1}g_t(X_t^R)\right]dt+\sqrt{2\epsilon_t}\,dW_t.

    Here WtW_t is standard Brownian motion and ϵt≥0\epsilon_t\ge0 is a chosen diffusion coefficient; the forward equation is run from the base endpoint and the backward equation from the target endpoint. For conditional generation, the fields are conditioned on ξ\xi and the endpoint laws are the corresponding conditional marginals.

  5. Knowl 5 — A coupling-dependent bound on probability-flow transport cost

    theoretical result

    Let Xt(x0)X_t(x_0) solve the probability-flow ODE X˙t=bt(Xt)\dot X_t=b_t(X_t) with X0=x0∼ρ0X_0=x_0\sim\rho_0, where bt(x)=E[I˙t∣It=x]b_t(x)=\mathbb{E}[\dot I_t\mid I_t=x]. The expected squared endpoint displacement is bounded by the time-integrated squared speed of the stochastic interpolant:

    Ex0∼ρ0[∣X1(x0)−x0∣2]≤∫01E[∣I˙t∣2]dt<∞.\mathbb{E}_{x_0\sim\rho_0}\left[|X_1(x_0)-x_0|^2\right]\le\int_0^1\mathbb{E}[|\dot I_t|^2]dt<\infty.

    The expectation on the right is over the coupled endpoints and any interpolant noise. Consequently, the choice of coupling can change this upper bound and can be designed to reduce it, without adding a separate coupling-optimization procedure. For example, for x0=x1+σzx_0=x_1+\sigma z, with scalar σ>0\sigma>0, standard Gaussian z∈Rdz\in\mathbb{R}^d, and the linear interpolant It=(1−t)x0+tx1I_t=(1-t)x_0+tx_1 with γt=0\gamma_t=0, the interpolant’s integrated squared speed is dσ2d\sigma^2.

  6. Knowl 6 — Gaussian base distributions adapted to target samples

    model/method

    A general construction of the data-dependent base is x0=m(x1)+Σζx_0=m(x_1)+\Sigma\zeta, where m(x1)∈Rdm(x_1)\in\mathbb{R}^d is a task-specific, possibly random corrupted observation, Σ∈Rd×d\Sigma\in\mathbb{R}^{d\times d}, and ζ∼N(0,Id)\zeta\sim\mathcal{N}(0,I_d) is independent of m(x1)m(x_1). If m(x1)m(x_1) is deterministic given x1x_1, then x0∣x1x_0\mid x_1 is Gaussian with mean m(x1)m(x_1) and covariance C=ΣΣTC=\Sigma\Sigma^{\mathsf T}. The joint law is formed as ρ1(x1)ρ0(x0∣x1)\rho_1(x_1)\rho_0(x_0\mid x_1), so its base marginal is generally not Gaussian even though each conditional base is Gaussian. Choosing mm to encode a noisy, partial, or low-resolution version of the target makes the initial sample task-adapted; Σζ\Sigma\zeta can be designed for the application and can depend on conditioning information. At generation time, this construction requires access to the corresponding corrupted observation or another way to produce a sample from the base.

  7. Knowl 7 — Training and sampling with a coupled interpolant

    algorithm

    The method learns a velocity field by regression on minibatches of coupled base–target pairs, then integrates the learned probability-flow ODE from a base sample. For the Gaussian-base construction, training samples x0=m(x1)+Σζx_0=m(x_1)+\Sigma\zeta; the interpolant may also include the independent Gaussian term γtz\gamma_t z.

    Input: Target data sampler, coupling map m, noise matrix Σ, coefficients α_t, β_t, γ_t, velocity model b̂, batch size n_b
    repeat
        Draw n_b target samples x_1 and independent standard Gaussian noises ζ and z
        Draw n_b times t uniformly from [0, 1]
        For each example, set x_0 = m(x_1) + Σζ
        For each example, set I_t = α_t x_0 + β_t x_1 + γ_t z
        Compute dot I_t = dot α_t x_0 + dot β_t x_1 + dot γ_t z
        Compute the minibatch loss mean of |b̂_t(I_t)|² − 2 dot I_t · b̂_t(I_t)
        Take a stochastic-gradient step on the velocity model
    until training converges
    Return the fitted velocity model b̂
    Input: Fitted velocity model b̂, available corrupted observation m(x_1), number of Euler steps N
    Draw ζ from the standard Gaussian and initialize X̂_0 = m(x_1) + Σζ
    For n = 0, ..., N − 1
        Set X̂_{n+1} = X̂_n + N^{-1} b̂_{n/N}(X̂_n)
    Return X̂_N
  8. Knowl 8 — Image inpainting with a mask-dependent base

    experimental setup

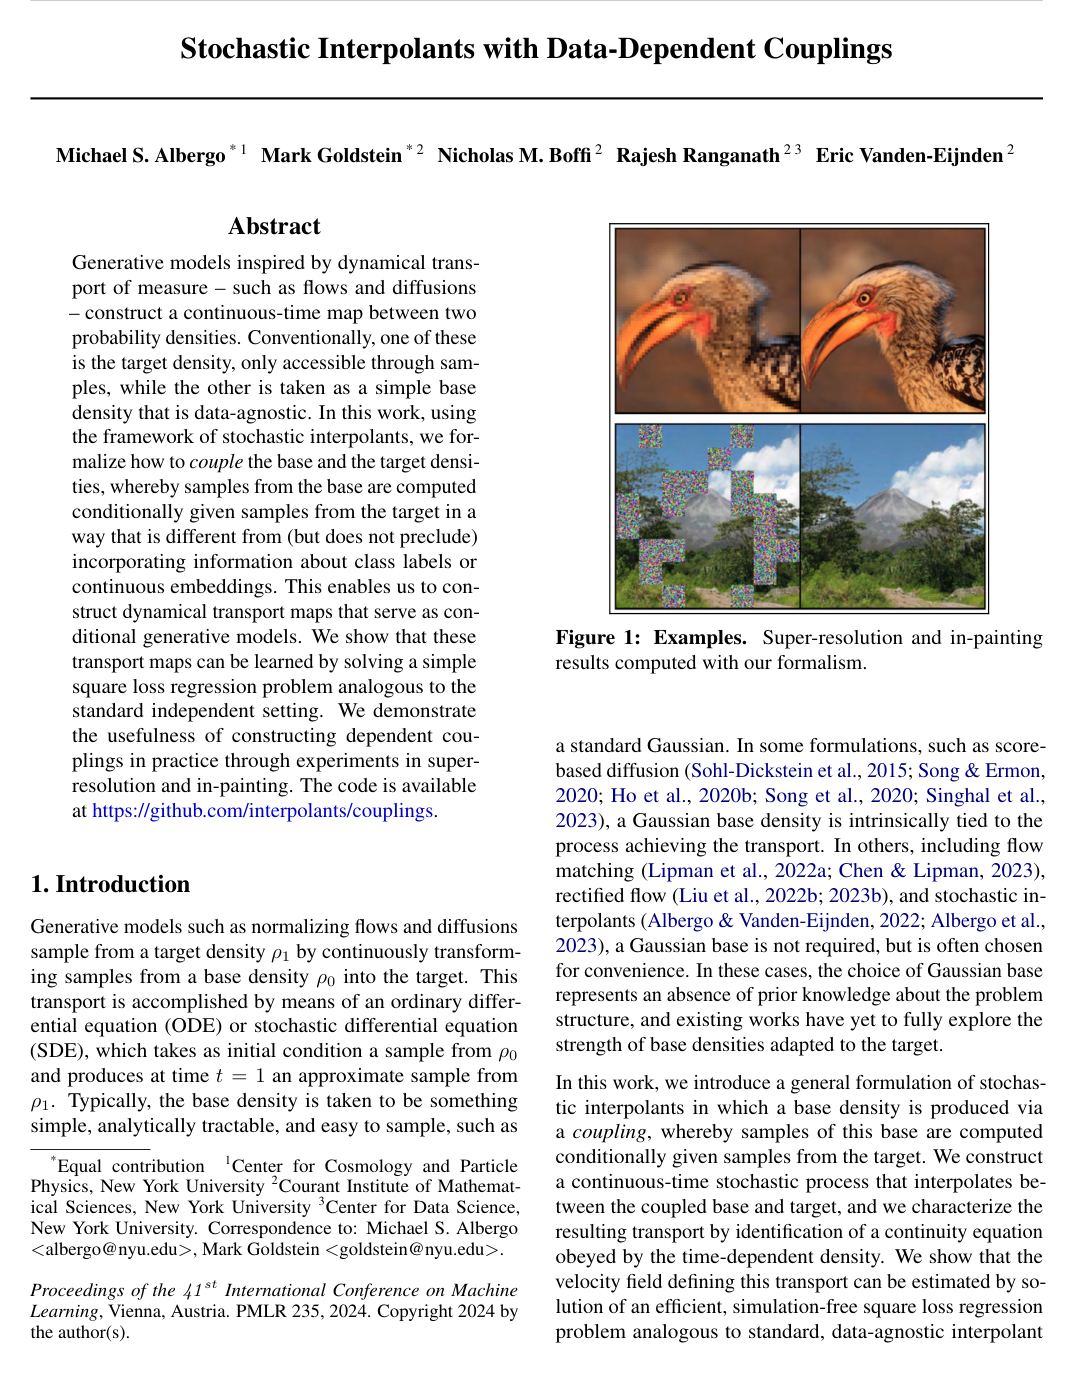
    For an image x1∈RC×W×Hx_1\in\mathbb{R}^{C\times W\times H} and a binary mask MM shared across color channels, the inpainting base is x0=M∘x1+(1−M)∘ζx_0=M\circ x_1+(1-M)\circ\zeta, where ∘\circ denotes elementwise multiplication and the masked pixels of ζ\zeta are independent standard Gaussian noise. Thus the observed pixels are present, unchanged, in both endpoints of the interpolation, and the velocity is zero on those pixels; the implementation masks the predicted velocity there so that they remain fixed without inference-time replacement or MCMC corrections. During training, images are divided into 64 tiles and each tile is selected for the mask with probability 0.30.3. Experiments use ImageNet images at 256×256256\times256 and 512×512512\times512 resolution, with the mask and optional class labels supplied to a U-Net velocity model. The generated fill is intended to be a plausible conditional completion, not necessarily a reconstruction of the exact held-out pixels.

    The reported FID-50k compares the data-dependent coupling with an independently coupled Gaussian-base interpolant:

    ModelFID-50k
    Uncoupled interpolant (baseline)1.35
    Dependent coupling (paper method)1.13

    The dependent-coupling result has the lower reported FID in this inpainting comparison.

  9. Knowl 9 — ImageNet super-resolution with upsampled observations

    experimental setup

    For a high-resolution target image x1x_1, let DD downsample it and UU upsample the result. The base is x0=U(D(x1))+σζx_0=U(D(x_1))+\sigma\zeta, with ζ∼N(0,I)\zeta\sim\mathcal{N}(0,I) and σ>0\sigma>0; adding noise avoids restricting the base distribution to the lower-dimensional set of upsampled images. The upsampled low-resolution image ξ=U(D(x1))\xi=U(D(x_1)) is supplied to the velocity model at every time step, together with ImageNet class labels. The experiments use ImageNet for 64×64→256×25664\times64\to256\times256 and 256×256→512×512256\times256\to512\times512 super-resolution. For the 64×64→256×25664\times64\to256\times256 task, the paper reports the following FID-50k values, quoting baseline results from prior work and its own dependent-coupling results:

    ModelTrain FID-50kValid FID-50k
    Improved DDPM12.26–
    SR311.305.20
    ADM7.493.10
    Cascaded Diffusion4.884.63
    I2I^2SB–2.70
    Dependent coupling (paper method)2.132.05

    The reported dependent-coupling values are lower than the listed baselines on the corresponding train and validation columns; the table combines results reported by this paper with baseline numbers drawn from prior work.

  10. Knowl 10 — Shared implementation configuration for image experiments

    experimental setup

    The image experiments parameterize the velocity with a U-Net using channel dimension 256, dimension multipliers (1,1,2,3,4)(1,1,2,3,4), 8 residual-block groups, learned sinusoidal conditioning enabled with dimension 32, attention head dimension 64, and 4 attention heads; random Fourier features are disabled. Image-shaped conditioning, including low-resolution images or inpainting masks, is appended to the input channels, and the architecture also supports class-label conditioning. Optimization uses Adam with initial learning rate 2×10−42\times10^{-4} and a StepLR schedule multiplying the learning rate by 0.990.99 every 1,000 steps; there is no weight decay, and gradient norms are clipped at 10,000. The paper’s generic sampling procedure presents forward Euler integration, while the reported image experiments use the Dopri solver from torchdiffeq.

Coverage note — The additional image galleries are omitted because they illustrate qualitative examples and intermediate flow states rather than adding distinct quantitative findings; speculative future applications are not treated as established contributions.

References

  1. 1.Albergo, M. S. and Vanden-Eijnden, E. Building normalizing flows with stochastic interpolants. arXiv preprint arXiv:2209.15571, 2022.
  2. 2.Albergo, M. S., Boffi, N. M., and Vanden-Eijnden, E. Stochastic interpolants: A unifying framework for flows and diffusions. arXiv preprint arXiv:2303.08797, 2023.
  3. 3.Benamou, J.-D. and Brenier, Y. A computational fluid mechanics solution to the monge-kantorovich mass transfer problem. Numerische Mathematik, 84(3):375–393, 2000. doi: 10.1007/s002110050002. URL https://doi.org/10.1007/s002110050002.
  4. 4.Chen, R. T. and Lipman, Y. Riemannian flow matching on general geometries. arXiv preprint arXiv:2302.03660, 2023.
  5. 5.Chen, R. T. Q. torchdiffeq, 2018. URL https://github.com/rtqichen/torchdiffeq.
  6. 6.Cuturi, M. Sinkhorn distances: Lightspeed computation of optimal transport. Advances in neural information processing systems, 26, 2013.
  7. 7.Dao, Q., Phung, H., Nguyen, B., and Tran, A. Flow matching in latent space. arXiv preprint arXiv:2307.08698, 2023.
  8. 8.De Bortoli, V., Thornton, J., Heng, J., and Doucet, A. Diffusion schrodinger bridge with applications to score-based generative modeling. In Ranzato, M., Beygelzimer, A., Dauphin, Y., Liang, P., and Vaughan, J. W. (eds.), Advances in Neural Information Processing Systems, volume 34, pp. 17695–17709. Curran Associates, Inc., 2021. URL https://proceedings.neurips.cc/paper_files/paper/2021/file/940392f5f32a7ade1cc201767cf83e31-Paper.pdf.
  9. 9.Dhariwal, P. and Nichol, A. Diffusion models beat gans on image synthesis. Advances in neural information processing systems, 34:8780–8794, 2021.
  10. 10.Dinh, L., Sohl-Dickstein, J., and Bengio, S. Density Estimation Using Real NVP. In International Conference on Learning Representations, pp. 32, 2017.
  11. 11.Durkan, C., Bekasov, A., Murray, I., and Papamakarios, G. Neural spline flows. In Wallach, H., Larochelle, H., Beygelzimer, A., d'Alche-Buc, F., Fox, E., and Garnett, R. (eds.), Advances in Neural Information Processing Systems, volume 32. Curran Associates, Inc., 2019. URL https://proceedings.neurips.cc/paper/2019/file/7ac71d433f282034e088473244df8c02-Paper.pdf.
  12. 12.Ho, J. and Salimans, T. Classifier-free diffusion guidance. arXiv Preprint arXiv:2207.12598, 2022.
  13. 13.Ho, J., Jain, A., and Abbeel, P. Denoising diffusion probabilistic models. In Larochelle, H., Ranzato, M., Hadsell, R., Balcan, M., and Lin, H. (eds.), Advances in Neural Information Processing Systems, volume 33, pp. 6840–6851. Curran Associates, Inc., 2020a. URL https://proceedings.neurips.cc/paper/2020/file/4c5bcfec8584af0d967f1ab10179ca4b-Paper.pdf.
  14. 14.Ho, J., Jain, A., and Abbeel, P. Denoising diffusion probabilistic models. Advances in neural information processing systems, 33:6840–6851, 2020b.
  15. 15.Ho, J., Saharia, C., Chan, W., Fleet, D. J., Norouzi, M., and Salimans, T. Cascaded diffusion models for high fidelity image generation. The Journal of Machine Learning Research, 23(1):2249–2281, 2022a.
  16. 16.Ho, J., Salimans, T., Gritsenko, A., Chan, W., Norouzi, M., and Fleet, D. J. Video diffusion models. arXiv:2204.03458, 2022b.
  17. 17.Hu, V. T., Zhang, D. W., Tang, M., Mettes, P., Zhao, D., and Snoek, C. G. Latent space editing in transformer-based flow matching. In ICML Workshop on New Frontiers in Learning, Control, and Dynamical Systems, 2023.
  18. 18.Huang, G., Sun, Y., Liu, Z., Sedra, D., and Weinberger, K. Deep Networks with Stochastic Depth. arXiv:1603.09382 [cs], July 2016.
  19. 19.Kingma, D. P. and Ba, J. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
  20. 20.Kingma, D. P. and Welling, M. Auto-Encoding Variational Bayes. arXiv [Preprint], 0, 2013. URL https://arxiv.org/1312.6114v10.
  21. 21.Klein, L., Krämer, A., and Noé, F. Equivariant flow matching, 2023.
  22. 22.Lee, S., Kim, B., and Ye, J. C. Minimizing trajectory curvature of ode-based generative models. arXiv preprint arXiv:2301.12003, 2023.
  23. 23.Lipman, Y., Chen, R. T., Ben-Hamu, H., Nickel, M., and Le, M. Flow matching for generative modeling. arXiv preprint arXiv:2210.02747, 2022a.
  24. 24.Lipman, Y., Chen, R. T. Q., Ben-Hamu, H., Nickel, M., and Le, M. Flow matching for generative modeling, 2022b. URL https://arxiv.org/abs/2210.02747.
  25. 25.Liu, G.-H., Vahdat, A., Huang, D.-A., Theodorou, E. A., Nie, W., and Anandkumar, A. I 2 sb: Image-to-image schr\” odinger bridge. arXiv preprint arXiv:2302.05872, 2023a.
  26. 26.Liu, Q. Rectified flow: A marginal preserving approach to optimal transport, 2022. URL https://arxiv.org/abs/2209.14577.
  27. 27.Liu, X., Gong, C., and Liu, Q. Flow straight and fast: Learning to generate and transfer data with rectified flow, 2022a. URL https://arxiv.org/abs/2209.03003.
  28. 28.Liu, X., Gong, C., and Liu, Q. Flow straight and fast: Learning to generate and transfer data with rectified flow. arXiv preprint arXiv:2209.03003, 2022b.
  29. 29.Liu, X., Zhang, X., Ma, J., Peng, J., and Liu, Q. Instaflow: One step is enough for high-quality diffusion-based text-to-image generation. arXiv preprint arXiv:2309.06380, 2023b.
  30. 30.Nichol, A. Q. and Dhariwal, P. Improved denoising diffusion probabilistic models. In International Conference on Machine Learning, pp. 8162–8171. PMLR, 2021.
  31. 31.Pooladian, A.-A., Ben-Hamu, H., Domingo-Enrich, C., Amos, B., Lipman, Y., and Chen, R. Multisample flow matching: Straightening flows with minibatch couplings. arXiv preprint arXiv:2304.14772, 2023.
  32. 32.Rezende, D. and Mohamed, S. Variational Inference with Normalizing Flows. In International Conference on Machine Learning, pp. 1530–1538. PMLR, June 2015.
  33. 33.Saharia, C., Ho, J., Chan, W., Salimans, T., Fleet, D. J., and Norouzi, M. Image super-resolution via iterative refinement. IEEE Transactions on Pattern Analysis and Machine Intelligence, 45(4):4713–4726, 2022.
  34. 34.Schneuing, A., Du, Y., Harris, C., Jamasb, A., Igashov, I., Du, W., Blundell, T., Lio, P., Gomes, C., Welling, M., et al. Structure-based drug design with equivariant diffusion models. arXiv preprint arXiv:2210.13695, 2022.
  35. 35.Shi, Y., Bortoli, V. D., Deligiannidis, G., and Doucet, A. Conditional simulation using diffusion schrodinger bridges. In The 38th Conference on Uncertainty in Artificial Intelligence, 2022. URL https://openreview.net/forum?id=H9Lu6P8sqec.
  36. 36.Shi, Y., Bortoli, V. D., Campbell, A., and Doucet, A. Diffusion schrodinger bridge matching, 2023.
  37. 37.Singhal, R., Goldstein, M., and Ranganath, R. Where to diffuse, how to diffuse, and how to get back: Automated learning for multivariate diffusions. In The Eleventh International Conference on Learning Representations, 2023.
  38. 38.Sohl-Dickstein, J., Weiss, E., Maheswaranathan, N., and Ganguli, S. Deep unsupervised learning using nonequilibrium thermodynamics. In International conference on machine learning, pp. 2256–2265. PMLR, 2015.
  39. 39.Somnath, V. R., Pariset, M., Hsieh, Y.-P., Martinez, M. R., Krause, A., and Bunne, C. Aligned diffusion schrodinger bridges. In The 39th Conference on Uncertainty in Artificial Intelligence, 2023. URL https://openreview.net/forum?id=BkWFJN7_bQ.
  40. 40.Song, Y. and Ermon, S. Improved techniques for training score-based generative models. Advances in neural information processing systems, 33:12438–12448, 2020.
  41. 41.Song, Y., Sohl-Dickstein, J., Kingma, D. P., Kumar, A., Ermon, S., and Poole, B. Score-based generative modeling through stochastic differential equations. arXiv preprint arXiv:2011.13456, 2020.
  42. 42.Song, Y., Durkan, C., Murray, I., and Ermon, S. Maximum likelihood training of score-based diffusion models. In Ranzato, M., Beygelzimer, A., Dauphin, Y., Liang, P., and Vaughan, J. W. (eds.), Advances in Neural Information Processing Systems, volume 34, pp. 1415–1428. Curran Associates, Inc., 2021a. URL https://proceedings.neurips.cc/paper/2021/file/0a9fdbb17feb6ccb7ec405cfb85222c4-Paper.pdf.
  43. 43.Song, Y., Sohl-Dickstein, J., Kingma, D. P., Kumar, A., Ermon, S., and Poole, B. Score-based generative modeling through stochastic differential equations. In International Conference on Learning Representations, 2021b.
  44. 44.Tabak, E. G. and Turner, C. V. A family of non-parametric density estimation algorithms. Communications on Pure and Applied Mathematics, 66(2):145–164, 2013. doi: https://doi.org/10.1002/cpa.21423. URL https://onlinelibrary.wiley.com/doi/abs/10.1002/cpa.21423.
  45. 45.Tabak, E. G. and Vanden-Eijnden, E. Density estimation by dual ascent of the log-likelihood. Communications in Mathematical Sciences, 8(1):217–233, 2010. ISSN 15396746, 19450796. doi: 10.4310/CMS.2010.v8.n1.a11.
  46. 46.Tong, A., Malkin, N., Huguet, G., Zhang, Y., Rector-Brooks, J., Fatras, K., Wolf, G., and Bengio, Y. Improving and generalizing flow-based generative models with minibatch optimal transport. In ICML Workshop on New Frontiers in Learning, Control, and Dynamical Systems, 2023.
  47. 47.Trippe, B. L., Yim, J., Tischer, D., Baker, D., Broderick, T., Barzilay, R., and Jaakkola, T. Diffusion probabilistic modeling of protein backbones in 3d for the motif-scaffolding problem. arXiv preprint arXiv:2206.04119, 2022.
  48. 48.Wu, L., Trippe, B. L., Naesseth, C. A., Blei, D. M., and Cunningham, J. P. Practical and asymptotically exact conditional sampling in diffusion models. arXiv preprint arXiv:2306.17775, 2023.

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: https://creativecommons.org/licenses/by/4.0/