Frequency-Adaptive Dilated Convolution for Semantic Segmentation

Linwei ChenLin GuDezhi ZhengYing Fu

article2024CVPR114 citations

Proposes Frequency-Adaptive Dilated Convolution to dynamically adjust dilation rates and kernel weights based on local spectral analysis, mitigating aliasing artifacts while balancing receptive field size and effective bandwidth in semantic segmentation.

Listen

Modern computer vision systems rely heavily on dilated convolutions to expand their visual receptive field without incurring massive computational costs. This capability is essential for safety-critical and high-precision tasks such as autonomous driving and robotic surgery. However, standard dilated convolutions apply a fixed sampling rate globally across an entire image. This design forces an undesirable engineering trade-off: capturing large contexts reduces the model's bandwidth, resulting in aliasing artifacts and the loss of fine, high-frequency boundary details.

The article aims to evaluate and demonstrate Frequency-Adaptive Dilated Convolution (FADC), a principled framework that dynamically balances receptive field size and effective bandwidth using spatial frequency analysis. To achieve this, the authors introduce three core components: an adaptive dilation rate mechanism that dynamically assigns sampling rates based on local image complexity; an adaptive kernel module that adjusts high- and low-frequency filter weights per channel; and a frequency selection module that spatially reweights features into four distinct frequency bands to suppress unnecessary background high frequencies. The authors evaluated the approach across standard semantic segmentation and object detection benchmarks, including Cityscapes, ADE20K, and COCO, applying it to multiple state-of-the-art vision backbones.

The experimental findings show significant performance improvements across all tested configurations with minimal computational overhead. On the Cityscapes dataset, integrating FADC improved standard segmentation models by up to 2.6 mean Intersection over Union (mIoU) while outperforming existing deformable convolution techniques with fewer parameters and lower computational cost. In real-time segmentation, pairing FADC with the PIDNet-M model achieved a state-of-the-art 81.0 mIoU at 37.7 frames per second, surpassing the heavier PIDNet-L model while running faster. On the ADE20K dataset, FADC increased the performance of a standard ResNet-50 backbone by 3.7 mIoU, allowing the smaller model to outperform the substantially heavier ResNet-101. Furthermore, integrating the framework's plug-in modules into deformable convolutions and vision transformer architectures yielded consistent gains across both segmentation and object detection tasks.

These results demonstrate that treating convolutional sampling as a dynamic, frequency-dependent operation resolves fundamental visual aliasing issues without introducing spatial distortion. For technical leaders and practitioners, the framework offers a direct path to deploying lighter, faster neural networks in latency-sensitive, edge environments without sacrificing spatial precision or accuracy. Next steps supported by the article include integrating these frequency-adaptive modules directly into existing computer vision pipelines and developing dedicated, purpose-built model architectures designed around frequency-adaptive operations. The empirical evidence provides high confidence in the method's effectiveness across standard vision benchmarks, though future work is recommended to formally extend this quantitative frequency analysis directly to advanced attention mechanisms.

No sufficiently relevant recommendations were found.
Cover for Frequency-Adaptive Dilated Convolution for Semantic Segmentation

Abstract

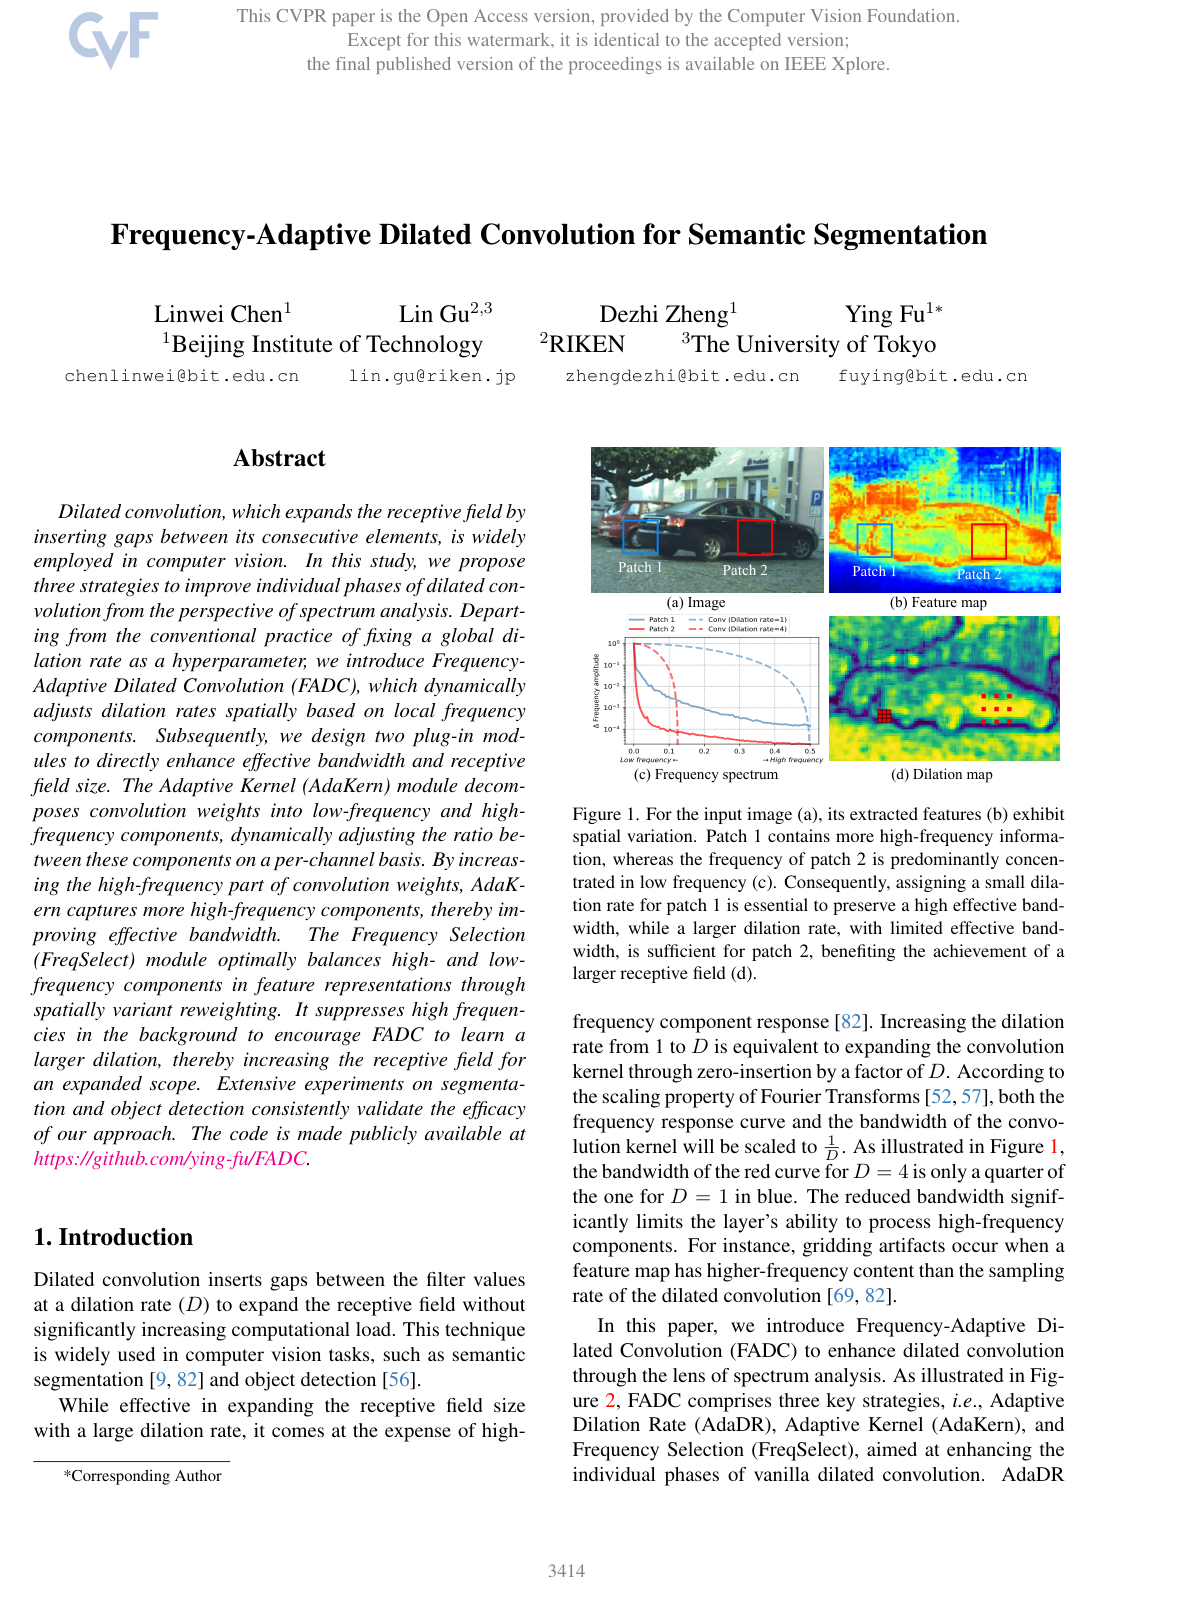
Dilated convolution, which expands the receptive field by inserting gaps between its consecutive elements, is widely employed in computer vision. In this study, we propose three strategies to improve individual phases of dilated convolution from the perspective of spectrum analysis. Departing from the conventional practice of fixing a global dilation rate as a hyperparameter, we introduce Frequency-Adaptive Dilated Convolution (FADC), which dynamically adjusts dilation rates spatially based on local frequency components. Subsequently, we design two plug-in modules to directly enhance effective bandwidth and receptive field size. The Adaptive Kernel (AdaKern) module decomposes convolution weights into low-frequency and high-frequency components, dynamically adjusting the ratio between these components on a per-channel basis. By increasing the high-frequency part of convolution weights, AdaKern captures more high-frequency components, thereby improving effective bandwidth. The Frequency Selection (FreqSelect) module optimally balances high- and low-frequency components in feature representations through spatially variant reweighting. It suppresses high frequencies in the background to encourage FADC to learn a larger dilation, thereby increasing the receptive field for an expanded scope. Extensive experiments on segmentation and object detection consistently validate the efficacy of our approach. The code is made publicly available at https://github.com/ying-fu/FADC.

Table of Contents

  • 1. Introduction
  • 2. Related work
  • 3. Frequency Adaptive Dilated Convolution
  • 3.1. Adaptive Dilation Rate
  • 3.2. Adaptive Kernel
  • 3.3. Frequency Selection
  • 4. Experiments
  • 4.1. Experiments Settings
  • 4.2. Main Results
  • 5. Analysis and Discussion
  • 6. Conclusion
  • Acknowledgments
  • References

Knowls

  1. Knowl 1 — Frequency Domain Bandwidth Degradation and Nyquist Limit in Dilated Convolutions

    theoretical result

    Standard dilated convolution with a dilation rate DD inserts D−1D-1 zeros between consecutive elements of a spatial kernel. Under the scaling property of the Fourier Transform, expanding the spatial domain filter by a factor of DD scales down its continuous frequency response curve and kernel bandwidth by a factor of 1/D1/D.

    Furthermore, dilated convolution with dilation rate DD samples an input feature map at an effective spatial sampling rate of 1/D1/D. By the Nyquist-Shannon sampling theorem, the maximum spatial frequency that can be captured without aliasing is bounded by the Nyquist frequency: fNyquist=12Df_{\text{Nyquist}} = \frac{1}{2D} For an input feature map X∈RH×WX \in \mathbb{R}^{H \times W} with Discrete Fourier Transform (DFT) XF=F(X)X_F = \mathcal{F}(X) defined by: XF(u,v)=1HW∑h=0H−1∑w=0W−1X(h,w)e−2πj(uhH+vwW)X_F(u, v) = \frac{1}{HW} \sum_{h=0}^{H-1} \sum_{w=0}^{W-1} X(h, w) e^{-2\pi j \left(\frac{uh}{H} + \frac{vw}{W}\right)} where u∈{−H2,…,H−12}u \in \{-\frac{H}{2}, \dots, \frac{H-1}{2}\} and v∈{−W2,…,W−12}v \in \{-\frac{W}{2}, \dots, \frac{W-1}{2}\} denote normalized frequency coordinates shifted so that zero frequency is centered, high frequencies belonging to the set: HD+={(u,v)  |  ∣u∣>12D or ∣v∣>12D}\mathcal{H}_D^+ = \left\{(u, v) \;\middle|\; |u| > \frac{1}{2D} \text{ or } |v| > \frac{1}{2D}\right\} cannot be accurately captured. Consequently, increasing DD to enlarge the receptive field directly reduces the effective bandwidth of the layer, causing high-frequency components to fold over as gridding or aliasing artifacts.

  2. Knowl 2 — Adaptive Dilation Rate (AdaDR) Formulation and Optimization

    model/method

    Adaptive Dilation Rate (AdaDR) replaces a globally fixed dilation rate with spatially variant, continuous dilation rates D^(p)\hat{D}(p) conditioned on the local spectral characteristics of the feature map. For an input feature map XX, the output feature map YY at pixel location pp is: Y(p)=∑i=1K×KWiX(p+Δpi×D^(p))Y(p) = \sum_{i=1}^{K \times K} W_i X(p + \Delta p_i \times \hat{D}(p)) where KK is the kernel size, WiW_i is the ii-th kernel weight parameter, Δpi∈{(−1,−1),(−1,0),…,(+1,+1)}\Delta p_i \in \{(-1, -1), (-1, 0), \dots, (+1, +1)\} represents the standard regular grid offsets for a K×KK \times K kernel, and D^(p)\hat{D}(p) is the predicted dilation rate at position pp. The dilation map D^(p)\hat{D}(p) is predicted by a convolutional layer with parameters θ\theta followed by a ReLU activation to ensure non-negativity (D^(p)≥0\hat{D}(p) \ge 0), alongside spatial modulation.

    The theoretical receptive field size at location pp is RF(p)=(K−1)×D^(p)+1\text{RF}(p) = (K-1) \times \hat{D}(p) + 1. Because dilations exceeding the local Nyquist limit HD^(p)+\mathcal{H}_{\hat{D}(p)}^+ lose high-frequency power HP(p)=∑(u,v)∈HD^(p)+∣XF(p,s)(u,v)∣2\text{HP}(p) = \sum_{(u, v) \in \mathcal{H}_{\hat{D}(p)}^+} |X_F^{(p,s)}(u,v)|^2 within a local window of size ss, AdaDR optimizes the trade-off by encouraging high dilation in low-frequency regions and low dilation in high-frequency regions: max⁡θ(∑p∈HP−D^(p)−∑p∈HP+D^(p))\max_\theta \left( \sum_{p \in \text{HP}^-} \hat{D}(p) - \sum_{p \in \text{HP}^+} \hat{D}(p) \right) where HP+\text{HP}^+ and HP−\text{HP}^- represent pixel sets with the highest and lowest high-frequency spectral power (e.g., top and bottom 25%), respectively. Unlike deformable convolutions, AdaDR uses a single isotropic dilation scalar per pixel, eliminating asymmetrical spatial coordinate deviations.

  3. Knowl 3 — Adaptive Kernel (AdaKern) Weight Decomposition

    model/method

    The Adaptive Kernel (AdaKern) module dynamically adjusts the frequency response of static convolutional kernels on a per-channel basis without changing the underlying kernel shape. Given a static convolutional kernel W∈RCout×Cin×K×KW \in \mathbb{R}^{C_{\text{out}} \times C_{\text{in}} \times K \times K}, it is decomposed into a low-frequency component Wˉ\bar{W} and a high-frequency residual component W^\hat{W}: W=Wˉ+W^W = \bar{W} + \hat{W} Here, Wˉ\bar{W} is computed via kernel-wise spatial averaging: Wˉ=1K×K∑i=1K×KWi\bar{W} = \frac{1}{K \times K} \sum_{i=1}^{K \times K} W_i which acts as a low-pass K×KK \times K mean filter followed by a 1×11 \times 1 convolution. The residual term W^=W−Wˉ\hat{W} = W - \bar{W} acts as a high-pass filter capturing local spatial differences.

    Dynamic channel-specific scaling factors λl∈RC\lambda_l \in \mathbb{R}^C and λh∈RC\lambda_h \in \mathbb{R}^C are predicted from input features using global average pooling followed by convolution and sigmoid operations. The modulated kernel W′W' is formed by: W′=λlWˉ+λhW^W' = \lambda_l \bar{W} + \lambda_h \hat{W} Adjusting the channel ratio λh/λl\lambda_h / \lambda_l dynamically shifts the frequency response curve of the convolution: increasing λh/λl\lambda_h / \lambda_l elevates high-frequency gain and expands the effective bandwidth, allowing the model to preserve fine details.

  4. Knowl 4 — Frequency Selection (FreqSelect) Module

    model/method

    The Frequency Selection (FreqSelect) module balances high- and low-frequency components in feature representations before dilation operations. By attenuating high-frequency power in non-boundary regions (e.g., background and object interiors), FreqSelect allows the network to learn larger dilation rates and expand receptive field size.

    FreqSelect decomposes an input feature map X∈RC×H×WX \in \mathbb{R}^{C \times H \times W} into BB frequency bands XbX_b using the 2D Discrete Fourier Transform F\mathcal{F} and binary spectral masks MbM_b: Xb=F−1(MbXF)for b∈{0,1,…,B−1}X_b = \mathcal{F}^{-1}(M_b X_F) \quad \text{for } b \in \{0, 1, \dots, B-1\} where XF=F(X)X_F = \mathcal{F}(X), F−1\mathcal{F}^{-1} is the inverse DFT, and Mb(u,v)M_b(u, v) is defined using B+1B+1 frequency thresholds {0=ϕ0,ϕ1,…,ϕB=1/2}\{0 = \phi_0, \phi_1, \dots, \phi_B = 1/2\}: Mb(u,v)={1if ϕb≤max⁡(∣u∣,∣v∣)<ϕb+10otherwiseM_b(u, v) = \begin{cases} 1 & \text{if } \phi_b \le \max(|u|, |v|) < \phi_{b+1} \\ 0 & \text{otherwise} \end{cases} In a 4-band configuration (B=4B=4), the bands are partitioned octave-wise into [0,1/16)[0, 1/16), [1/16,1/8)[1/16, 1/8), [1/8,1/4)[1/8, 1/4), and [1/4,1/2][1/4, 1/2].

    A spatial selection map Ab∈RH×WA_b \in \mathbb{R}^{H \times W} is predicted for each frequency band via a convolutional subnet, yielding the frequency-balanced output X^\hat{X}: X^(i,j)=∑b=0B−1Ab(i,j)Xb(i,j)\hat{X}(i, j) = \sum_{b=0}^{B-1} A_b(i, j) X_b(i, j)

  5. Knowl 5 — Frequency-Adaptive Dilated Convolution (FADC) Architecture

    model/method

    Frequency-Adaptive Dilated Convolution (FADC) is an integrated convolutional operator designed as a drop-in replacement for standard dilated convolutions. FADC consists of three complementary strategies:

    1. Frequency Selection (FreqSelect): Operates on input features XX by decomposing them into octave frequency bands via Fourier masks and spatially reweighting them with dynamic selection maps AbA_b to produce a frequency-balanced feature X^\hat{X}.
    2. Adaptive Kernel (AdaKern): Operates on kernel weights WW by separating them into low-pass average Wˉ\bar{W} and high-pass residual W^\hat{W}, dynamically scaling them per channel via global pooling to produce a modulated kernel W′=λlWˉ+λhW^W' = \lambda_l \bar{W} + \lambda_h \hat{W}.
    3. Adaptive Dilation Rate (AdaDR): Predicts a spatially variant continuous dilation map D^(p)≥0\hat{D}(p) \ge 0 conditioned on local frequency content to sample X^\hat{X} with kernel W′W' without inducing asymmetrical spatial grid distortions.

    Together, AdaDR spatially balances receptive field and bandwidth, AdaKern broadens effective bandwidth per channel, and FreqSelect suppresses unnecessary high frequencies to maximize average dilation.

  6. Knowl 6 — Semantic Segmentation Benchmark Results on Cityscapes and ADE20K

    data/table

    Replacing standard dilated convolutions with Frequency-Adaptive Dilated Convolution (FADC) yields consistent performance improvements across multiple backbone networks and segmentation heads on Cityscapes validation (1024×20481024 \times 2048) and ADE20K validation datasets.

    Dataset / Method #Params #FLOPs mIoU (SS) mIoU (MS)
    Cityscapes Validation
    Dilated-ResNet-50 + PSPNet 49.0M 1427.5G 77.8 -
    Dilated-ResNet-50 + PSPNet + DCNv2 +0.7M +24.5G 79.7 -
    Dilated-ResNet-50 + PSPNet + FADC (Ours) +0.5M +9.2G 80.4 -
    Dilated-ResNet-50 + DeepLabV3+ 43.6M 1410.9G 79.2 -
    Dilated-ResNet-50 + DeepLabV3+ + DCNv2 +0.7M +24.5G 79.9 -
    Dilated-ResNet-50 + DeepLabV3+ + FADC (Ours) +0.5M +9.2G 80.3 -
    Dilated-ResNet-101 + DeepLabV3+ + ADC 62.8M 2032.3G 80.7 -
    Dilated-ResNet-101 + DeepLabV3+ + FADC (Ours) 63.9M 2067.0G 81.5 -
    ResNet-50 + Mask2Former 44.0M - 79.4 -
    ResNet-50 + Mask2Former + DCNv2 +0.9M +7.7G 80.4 -
    ResNet-50 + Mask2Former + FADC (Ours) +0.5M +4.3G 80.6 -
    ADE20K Validation (UPerNet)
    ResNet-50 66M 947G 40.7 41.8
    ResNet-101 85M 1029G 42.9 44.0
    ResNet-50-FADC (Ours) 67M 949G 44.4 45.5
    HorNet-B 126M 1171G 50.5 50.9
    HorNet-B-FADC (Ours) 128M 1176G 51.1 51.5

    SS and MS denote single-scale and multi-scale testing mIoU (%), respectively. ResNet-50 equipped with FADC (+3.7 mIoU on ADE20K) outperforms the heavier standard ResNet-101 baseline (44.4 vs 42.9 mIoU).

  7. Knowl 7 — Real-Time Semantic Segmentation with PIDNet-M-FADC on Cityscapes

    data/table

    Incorporating FADC into the bottleneck convolution of the real-time semantic segmentation network PIDNet-M achieves an optimal balance between inference latency and segmentation accuracy on the Cityscapes benchmark (evaluated on an NVIDIA RTX 3090 at 1024×20481024 \times 2048 resolution).

    Model #Params #FLOPs FPS Val mIoU Test mIoU
    BiSeNet (Res18) 49.0M 55.3G 65.5 74.8 74.7
    BiSeNetV2-L - 118.5G 47.3 75.8 75.3
    STDC2-Seg75 - - 58.2 77.0 76.8
    PP-LiteSeg-B2 - - 68.2 78.2 77.5
    HyperSeg-S 10.2M 17.0G 45.7 78.2 78.1
    SFNet (ResNet-18) 12.87M 247.0G 30.4 - 78.9
    DDRNet-23 20.1M 143.1G 51.4 79.5 79.4
    PIDNet-S 7.6M 47.6G 93.2 78.8 78.6
    PIDNet-M 34.4M 197.4G 39.8 80.1 80.1
    PIDNet-L 36.9M 275.8G 31.1 80.9 80.6
    PIDNet-M-FADC (Ours) 34.6M 198.4G 37.7 81.0 80.6

    PIDNet-M-FADC achieves 81.0% validation mIoU at 37.7 FPS, surpassing the larger PIDNet-L model (80.9% validation mIoU at 31.1 FPS) with lower computation and higher frame rates.

  8. Knowl 8 — Generalization of AdaKern and FreqSelect to Deformable Convolutions and Dilated Attention

    data/table

    The AdaKern and FreqSelect modules integrate directly with other adaptive coordinate-sampling mechanisms, including Deformable Convolution v2 (DCNv2), InternImage (DCNv3-based), and Dilated Neighborhood Attention Transformer (DiNAT).

    Task / Model Params FLOPs APbox\text{AP}^{\text{box}} AP50box\text{AP}_{50}^{\text{box}} AP75box\text{AP}_{75}^{\text{box}}
    COCO Object Detection (Faster R-CNN, 1×\times Schedule)
    ResNet-50 Baseline 41.7M 207.1G 37.4 58.1 40.4
    ResNet-50 + DCNv2 +0.9M +3.9G 41.3 62.8 45.1
    ResNet-50 + DCNv2 + AdaKern + FreqSelect +1.0M +4.6G 42.2 63.5 46.2
    COCO Instance Segmentation (Mask R-CNN, 3×\times Schedule) Params FLOPs APbox\text{AP}^{\text{box}} APmask\text{AP}^{\text{mask}}
    DiNAT-S 70M 330G 49.3 43.9
    DiNAT-S + FreqSelect 71M 331G 49.8 44.5
    ADE20K Semantic Segmentation (UPerNet) Params FLOPs SS mIoU MS mIoU
    InternImage-T 59M 944G 47.9 48.1
    InternImage-T + FreqSelect 60M 948G 48.7 48.9

    Adding AdaKern and FreqSelect to DCNv2 improves object detection by +0.9 APbox\text{AP}^{\text{box}} on COCO. Adding FreqSelect to DiNAT-S increases mask AP by +0.6 APmask\text{AP}^{\text{mask}} on COCO, and improves InternImage-T by +0.8 single-scale mIoU on ADE20K.

  9. Knowl 9 — Receptive Field Expansion and Frequency Selection Weight Distribution

    empirical result

    Theoretical receptive field calculations on Dilated-ResNet-50 demonstrate that FADC increases receptive field size relative to standard fixed-dilation models:

    • Standard Dilated Convolution: theoretical receptive field of 441441 pixels.
    • FADC without FreqSelect: theoretical receptive field of 10071007 pixels.
    • FADC with FreqSelect: theoretical receptive field of 11001100 pixels.

    Statistical analysis of the spatial selection maps AbA_b produced by FreqSelect across the Cityscapes validation set reveals that the average attention weight decreases monotonically across higher frequency bands:

    • Frequency band [0,1/16)×2π[0, 1/16) \times 2\pi: average weight =1.00= 1.00
    • Frequency band [1/16,1/8)×2π[1/16, 1/8) \times 2\pi: average weight =0.66= 0.66
    • Frequency band [1/8,1/4)×2π[1/8, 1/4) \times 2\pi: average weight =0.50= 0.50
    • Frequency band [1/4,1/2]×2π[1/4, 1/2] \times 2\pi: average weight =0.34= 0.34

    This distribution follows the natural image inverse power law (1/fα1/f^\alpha). FreqSelect assigns higher weights to high frequencies specifically along object boundaries while suppressing high frequencies in background areas, allowing FADC to safely increase dilation rates in those areas.

Coverage note — None was omitted; all primary theoretical foundations, architectural mechanisms (AdaDR, AdaKern, FreqSelect), main benchmark results (Cityscapes, ADE20K, COCO), real-time experiments (PIDNet), generalization integrations (DCNv2, InternImage, DiNAT), and receptive field analyses from the paper are represented.

References

  1. 1.Shuai Bai, Zhiqun He, Yu Qiao, Hanzhe Hu, Wei Wu, and Junjie Yan. Adaptive dilated network with self-correction supervision for counting. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 4594–4603, 2020. 3
  2. 2.Gregory A Baxes. Digital image processing: principles and applications. John Wiley & Sons, Inc., 1994. 3
  3. 3.Chun-Fu Chen, Rameswar Panda, and Quanfu Fan. Regionvit: Regional-to-local attention for vision transformers. In Proceedings of International Conference on Learning Representations, pages 1–15, 2021. 7
  4. 4.Linwei Chen, Zheng Fang, and Ying Fu. Consistency-aware map generation at multiple zoom levels using aerial image. IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing, 15:5953–5966, 2022. 5
  5. 5.Linwei Chen, Ying Fu, Kaixuan Wei, Dezhi Zheng, and Felix Heide. Instance segmentation in the dark. International Journal of Computer Vision, 131(8):2198–2218, 2023. 5
  6. 6.Linwei Chen, Ying Fu, Shaodi You, and Hongzhe Liu. Efficient hybrid supervision for instance segmentation in aerial images. Remote Sensing, 13(2):252, 2021.
  7. 7.Linwei Chen, Ying Fu, Shaodi You, and Hongzhe Liu. Hybrid supervised instance segmentation by learning label noise suppression. Neurocomputing, 496:131–146, 2022. 5
  8. 8.Linwei Chen, Lin Gu, and Ying Fu. When semantic segmentation meets frequency aliasing. In Proceedings of International Conference on Learning Representations, 2024. 5
  9. 9.Liang-Chieh Chen, Yukun Zhu, George Papandreou, Florian Schroff, and Hartwig Adam. Encoder-decoder with atrous separable convolution for semantic image segmentation. In Proceedings of European Conference on Computer Vision, pages 801–818, 2018. 1, 6
  10. 10.Bowen Cheng, Ishan Misra, Alexander G Schwing, Alexander Kirillov, and Rohit Girdhar. Masked-attention mask transformer for universal image segmentation. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 1290–1299, 2022. 5, 6
  11. 11.Lu Chi, Borui Jiang, and Yadong Mu. Fast fourier convolution. In Proceedings of Advances in Neural Information Processing Systems, volume 33, pages 4479–4488, 2020. 3
  12. 12.Marius Cordts, Mohamed Omran, Sebastian Ramos, Timo Rehfeld, Markus Enzweiler, Rodrigo Benenson, Uwe Franke, Stefan Roth, and Bernt Schiele. The cityscapes dataset for semantic urban scene understanding. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 3213–3223, 2016. 5, 6, 7, 8
  13. 13.Jifeng Dai, Haozhi Qi, Yuwen Xiong, Yi Li, Guodong Zhang, Han Hu, and Yichen Wei. Deformable convolutional networks. In Proceedings of IEEE International Conference on Computer Vision, pages 764–773, 2017. 3, 7
  14. 14.Xiaohan Ding, Xiangyu Zhang, Jungong Han, and Guiguang Ding. Scaling up your kernels to 31x31: Revisiting large kernel design in cnns. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 11963–11975, 2022. 8
  15. 15.Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, et al. An image is worth 16x16 words: Transformers for image recognition at scale. In Proceedings of International Conference on Learning Representations, pages 1–12, 2020. 3, 8
  16. 16.Mingyuan Fan, Shenqi Lai, Junshi Huang, Xiaoming Wei, Zhenhua Chai, Junfeng Luo, and Xiaolin Wei. Rethinking bisenet for real-time semantic segmentation. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 9716–9725, 2021. 6
  17. 17.Di Feng, Christian Haase-Sch¨utz, Lars Rosenbaum, Heinz Hertlein, Claudius Glaeser, Fabian Timm, Werner Wiesbeck, and Klaus Dietmayer. Deep multi-modal object detection and semantic segmentation for autonomous driving: Datasets, methods, and challenges. IEEE Transactions on Intelligent Transportation Systems, 22(3):1341–1360, 2020. 6
  18. 18.Ying Fu, Jian Chen, Tao Zhang, and Yonggang Lin. Residual scale attention network for arbitrary scale image super-resolution. Neurocomputing, 427:201–211, 2021. 3
  19. 19.Ying Fu, Zheng Fang, Linwei Chen, Tao Song, and Defu Lin. Level-aware consistent multilevel map translation from satellite imagery. IEEE Transactions on Geoscience and Remote Sensing, 61:1–14, 2022. 5
  20. 20.John Guibas, Morteza Mardani, Zongyi Li, Andrew Tao, Anima Anandkumar, and Bryan Catanzaro. Adaptive fourier neural operators: Efficient token mixers for transformers. In Proceedings of International Conference on Learning Representations, pages 1–12, 2022. 3
  21. 21.Qi Han, Zejia Fan, Qi Dai, Lei Sun, Ming-Ming Cheng, Jiaying Liu, and Jingdong Wang. On the connection between local attention and dynamic depth-wise convolution. In International Conference on Learning Representations, pages 1–14, 2021. 3
  22. 22.Ali Hassani and Humphrey Shi. Dilated neighborhood attention transformer. 2022. 5, 6, 7
  23. 23.Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi. Neighborhood attention transformer. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 6185–6194, 2023. 3, 6, 7
  24. 24.Kaiming He, Georgia Gkioxari, Piotr Doll´ar, and Ross Girshick. Mask r-cnn. In Proceedings of IEEE International Conference on Computer Vision, pages 2961–2969, 2017. 5, 7
  25. 25.Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 770–778, 2016. 6, 7
  26. 26.Yuanduo Hong, Huihui Pan, Weichao Sun, and Yisong Jia. Deep dual-resolution networks for real-time and accurate semantic segmentation of road scenes. arXiv preprint arXiv:2101.06085, 2021. 6
  27. 27.Yang Hong, Kaixuan Wei, Linwei Chen, and Ying Fu. Crafting object detection in very low light. In Proceedings of the British Machine Vision Conference, volume 1, pages 1–15, 2021. 5
  28. 28.Md Tahmid Hossain, Shyh Wei Teng, Guojun Lu, Mohammad Arifur Rahman, and Ferdous Sohel. Anti-aliasing deep image classifiers using novel depth adaptive blurring and activation function. Neurocomputing, 536:164–174, 2023. 3
  29. 29.Zhipeng Huang, Zhizheng Zhang, Cuiling Lan, Zheng-Jun Zha, Yan Lu, and Baining Guo. Adaptive frequency filters as efficient global token mixers. In Proceedings of IEEE International Conference on Computer Vision, pages 1–11, 2023. 3
  30. 30.Tero Karras, Miika Aittala, Samuli Laine, Erik H¨ark¨onen, Janne Hellsten, Jaakko Lehtinen, and Timo Aila. Alias-free generative adversarial networks. Proceedings of Advances in Neural Information Processing Systems, 34:852–863, 2021. 3
  31. 31.Ismail Khalfaoui-Hassani, Thomas Pellegrini, and Timoth´ee Masquelier. Dilated convolution with learnable spacings. In Proceedings of International Conference on Learning Representations, pages 1–13, 2023. 3, 6
  32. 32.Saumya Kumaar, Ye Lyu, Francesco Nex, and Michael Ying Yang. Cabinet: Efficient context aggregation network for low-latency semantic segmentation. In IEEE International Conference on Robotics and Automation, pages 13517–13524. IEEE, 2021. 6
  33. 33.Qiufu Li, Linlin Shen, Sheng Guo, and Zhihui Lai. Wavecnet: Wavelet integrated cnns to suppress aliasing effect for noise-robust image classification. IEEE Transaction on Image Process., 30:7074–7089, 2021. 3
  34. 34.Xiangtai Li, Ansheng You, Zhen Zhu, Houlong Zhao, Maoke Yang, Kuiyuan Yang, Shaohua Tan, and Yunhai Tong. Semantic flow for fast and accurate scene parsing. In Proceedings of European Conference on Computer Vision, pages 775–793. Springer, 2020. 6
  35. 35.Xin Li, Yiming Zhou, Zheng Pan, and Jiashi Feng. Partial order pruning: for best speed/accuracy trade-off in neural architecture search. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 9145–9153, 2019. 6
  36. 36.Zongyi Li, Nikola Kovachki, Kamyar Azizzadenesheli, Burigede Liu, Kaushik Bhattacharya, Andrew Stuart, and Anima Anandkumar. Fourier neural operator for parametric partial differential equations. In Proceedings of International Conference on Learning Representations, pages 1–12, 2021. 3
  37. 37.Shiqi Lin, Zhizheng Zhang, Zhipeng Huang, Yan Lu, Cuiling Lan, Peng Chu, Quanzeng You, Jiang Wang, Zicheng Liu, Amey Parulkar, et al. Deep frequency filtering for domain generalization. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 11797–11807, 2023. 3
  38. 38.Tsung-Yi Lin, Michael Maire, Serge Belongie, James Hays, Pietro Perona, Deva Ramanan, Piotr Doll´ar, and C Lawrence Zitnick. Microsoft coco: Common objects in context. In European conference on computer vision, pages 740–755. Springer, 2014. 5
  39. 39.Tsung-Yi Lin, Michael Maire, Serge Belongie, James Hays, Pietro Perona, Deva Ramanan, Piotr Doll´ar, and C Lawrence Zitnick. Microsoft coco: Common objects in context. In Proceedings of European Conference on Computer Vision, pages 740–755, 2014. 6, 7
  40. 40.Songlin Liu, Linwei Chen, Li Zhang, Jun Hu, and Ying Fu. A large-scale climate-aware satellite image dataset for domain adaptive land-cover semantic segmentation. ISPRS Journal of Photogrammetry and Remote Sensing, 205:98–114, 2023. 5
  41. 41.Shiwei Liu, Tianlong Chen, Xiaohan Chen, Xuxi Chen, Qiao Xiao, Boqian Wu, Tommi K¨arkk¨ainen, Mykola Pechenizkiy, Decebal Constantin Mocanu, and Zhangyang Wang. More convnets in the 2020s: Scaling up kernels beyond 51x51 using sparsity. In Proceedings of International Conference on Learning Representations, 2023. 7
  42. 42.Sun-Ao Liu, Hongtao Xie, Hai Xu, Yongdong Zhang, and Qi Tian. Partial class activation attention for semantic segmentation. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 16836–16845, 2022. 2
  43. 43.Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, and Baining Guo. Swin transformer: Hierarchical vision transformer using shifted windows. In Proceedings of IEEE International Conference on Computer Vision, pages 10012–10022, 2021. 3, 6, 7
  44. 44.Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, and Saining Xie. A convnet for the 2020s. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 11976–11986, 2022. 6, 7
  45. 45.Jonathan Long, Evan Shelhamer, and Trevor Darrell. Fully convolutional networks for semantic segmentation. In Proceedings of IEEE International Conference on Computer Vision, pages 3431–3440, 2015. 5
  46. 46.Jinlai Ning and Michael Spratling. The importance of anti-aliasing in tiny object detection. In Asian Conference on Machine Learning, 2023. 3
  47. 47.Yuval Nirkin, Lior Wolf, and Tal Hassner. Hyperseg: Patch-wise hypernetwork for real-time semantic segmentation. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 4061–4070, 2021. 6
  48. 48.Marin Orsic, Ivan Kreso, Petra Bevandic, and Sinisa Segvic. In defense of pre-trained imagenet architectures for real-time semantic segmentation of road-driving images. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 12607–12616, 2019. 6
  49. 49.Namuk Park and Songkuk Kim. How do vision transformers work? In Proceedings of International Conference on Learning Representations, pages 1–14, 2021. 2, 3, 5
  50. 50.Juncai Peng, Yi Liu, Shiyu Tang, Yuying Hao, Lutao Chu, Guowei Chen, Zewu Wu, Zeyu Chen, Zhiliang Yu, Yuning Du, et al. Pp-liteseg: A superior real-time semantic segmentation model. arXiv preprint arXiv:2204.02681, 2022. 6
  51. 51.Ioannis Pitas. Digital image processing algorithms and applications. John Wiley & Sons, 2000. 3
  52. 52.John G Proakis and Dimitris G Manolakis. Digital signal processing: Pearson new international edition. Pearson Higher Ed, 2013. 1, 4
  53. 53.Shengju Qian, Hao Shao, Yi Zhu, Mu Li, and Jiaya Jia. Blending anti-aliasing into vision transformer. Proceedings of Advances in Neural Information Processing Systems, 34:5416–5429, 2021. 3
  54. 54.Yongming Rao, Wenliang Zhao, Yansong Tang, Jie Zhou, Ser Nam Lim, and Jiwen Lu. Hornet: Efficient high-order spatial interactions with recursive gated convolutions. Proceedings of Advances in Neural Information Processing Systems, 35:10353–10366, 2022. 5, 6
  55. 55.Yongming Rao, Wenliang Zhao, Zheng Zhu, Jiwen Lu, and Jie Zhou. Global filter networks for image classification. In Proceedings of Advances in Neural Information Processing Systems, volume 34, pages 980–993, 2021. 3
  56. 56.Shaoqing Ren, Kaiming He, Ross Girshick, and Jian Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. In Proceedings of Advances in Neural Information Processing Systems, pages 91–99, 2015. 1, 7
  57. 57.Richard A Roberts and Clifford T Mullis. Digital signal processing. Addison-Wesley Longman Publishing Co., Inc., 1987. 1, 4
  58. 58.David W Romero, Robert-Jan Bruintjes, Jakub M Tomczak, Erik J Bekkers, Mark Hoogendoorn, and Jan C van Gemert. Flexconv: Continuous kernel convolutions with differentiable kernel sizes. In Proceedings of International Conference on Learning Representations, pages 1–14, 2021. 3, 8
  59. 59.Ruizhi Shao, Gaochang Wu, Yuemei Zhou, Ying Fu, Lu Fang, and Yebin Liu. Localtrans: A multiscale local transformer network for cross-resolution homography estimation. In Proceedings of IEEE International Conference on Computer Vision. 3
  60. 60.Alexey A Shvets, Alexander Rakhlin, Alexandr A Kalinin, and Vladimir I Iglovikov. Automatic instrument segmentation in robot-assisted surgery using deep learning. In IEEE international conference on machine learning and applications, pages 624–628. IEEE, 2018. 6
  61. 61.Hang Su, Varun Jampani, Deqing Sun, Orazio Gallo, Erik Learned-Miller, and Jan Kautz. Pixel-adaptive convolutional neural networks. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 11166–11175, 2019. 3
  62. 62.Ajay Subramanian, Elena Sizikova, Najib J Majaj, and Denis G Pelli. Spatial-frequency channels, shape bias, and adversarial robustness. pages 1–10, 2023. 5
  63. 63.Naoya Takahashi and Yuki Mitsufuji. Densely connected multi-dilated convolutional networks for dense prediction tasks. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 993–1002, 2021. 3, 8
  64. 64.Ling Tang, Wen Shen, Zhanpeng Zhou, Yuefeng Chen, and Quanshi Zhang. Defects of convolutional decoder networks in frequency representation. arXiv preprint arXiv:2210.09020, 2022. 5
  65. 65.Antonio Torralba and Aude Oliva. Statistics of natural image categories. Network: computation in neural systems, 14(3):391, 2003. 7
  66. 66.Cristina Vasconcelos, Hugo Larochelle, Vincent Dumoulin, Rob Romijnders, Nicolas Le Roux, and Ross Goroshin. Impact of aliasing on generalization in deep convolutional networks. In Proceedings of IEEE International Conference on Computer Vision, pages 10529–10538, 2021. 3
  67. 67.Thomas Verelst and Tinne Tuytelaars. Dynamic convolutions: Exploiting spatial sparsity for faster inference. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 2320–2329, 2020. 3
  68. 68.Haohan Wang, Xindi Wu, Zeyi Huang, and Eric P Xing. High-frequency component helps explain the generalization of convolutional neural networks. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 8684–8694, 2020. 3
  69. 69.Panqu Wang, Pengfei Chen, Ye Yuan, Ding Liu, Zehua Huang, Xiaodi Hou, and Garrison Cottrell. Understanding convolution for semantic segmentation. In Proceedings of IEEE Winter Conference on Applications of Computer Vision, pages 1451–1460. Ieee, 2018. 1, 3, 4, 8
  70. 70.Wenhai Wang, Jifeng Dai, Zhe Chen, Zhenhang Huang, Zhiqi Li, Xizhou Zhu, Xiaowei Hu, Tong Lu, Lewei Lu, Hongsheng Li, et al. Internimage: Exploring large-scale vision foundation models with deformable convolutions. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 14408–14419, 2023. 3, 5, 6, 7
  71. 71.Zhengyang Wang and Shuiwang Ji. Smoothed dilated convolutions for improved dense prediction. In Proceedings of ACM SIGKDD International Conference on Knowledge Discovery & Data Mining, pages 2486–2495, 2018. 3, 4
  72. 72.Kaixuan Wei, Angelica I Avil´es-Rivero, Jingwei Liang, Ying Fu, Hua Huang, and Carola-Bibiane Sch¨onlieb. Tfpnp: Tuning-free plug-and-play proximal algorithms with applications to inverse imaging problems. Journal of Machine Learning Research, 23(16):1–48, 2022. 3
  73. 73.Zhuofan Xia, Xuran Pan, Shiji Song, Li Erran Li, and Gao Huang. Vision transformer with deformable attention. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition. 6, 7
  74. 74.Ye Xiang, Ying Fu, and Hua Huang. Global topology constraint network for fine-grained vehicle recognition. IEEE Transactions on Intelligent Transportation Systems, 21(7):2918–2929, 2019. 3
  75. 75.Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, and Jian Sun. Unified perceptual parsing for scene understanding. In Proceedings of European Conference on Computer Vision, pages 418–434, 2018. 6
  76. 76.Jiacong Xu, Zixiang Xiong, and Shankar P Bhattacharyya. Pidnet: A real-time semantic segmentation network inspired by pid controllers. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 19529–19539, 2023. 5, 6
  77. 77.Jianwei Yang, Chunyuan Li, Xiyang Dai, and Jianfeng Gao. Focal modulation networks. Proceedings of Advances in Neural Information Processing Systems, 35:4203–4217, 2022. 6
  78. 78.Jie Yao, Dongdong Wang, Hao Hu, Weiwei Xing, and Liqiang Wang. Adcnn: Towards learning adaptive dilation for convolutional neural networks. Pattern Recognition, 123:108369, 2022. 3, 5, 6
  79. 79.Dong Yin, Raphael Gontijo Lopes, Jon Shlens, Ekin Dogus Cubuk, and Justin Gilmer. A fourier perspective on model robustness in computer vision. In Proceedings of Advances in Neural Information Processing Systems, volume 32, 2019. 3
  80. 80.Changqian Yu, Changxin Gao, Jingbo Wang, Gang Yu, Chunhua Shen, and Nong Sang. Bisenet v2: Bilateral network with guided aggregation for real-time semantic segmentation. International Journal of Computer Vision, 129(11):3051–3068, 2021. 6
  81. 81.Changqian Yu, Jingbo Wang, Chao Peng, Changxin Gao, Gang Yu, and Nong Sang. Bisenet: Bilateral segmentation network for real-time semantic segmentation. In Proceedings of European Conference on Computer Vision, pages 325–341, 2018. 6
  82. 82.Fisher Yu, Vladlen Koltun, and Thomas Funkhouser. Dilated residual networks. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 472–480, 2017. 1, 2, 3, 4, 5, 6, 7, 8
  83. 83.Guhnoo Yun, Juhan Yoo, Kijung Kim, Jeongho Lee, and Dong Hwan Kim. Spanet: Frequency-balancing token mixer using spectral pooling aggregation modulation. In Proceedings of IEEE International Conference on Computer Vision, pages 1–16, 2023. 3
  84. 84.Richard Zhang. Making convolutional networks shift-invariant again. In Proceedings of International Conference on Machine Learning, pages 7324–7334, 2019. 3
  85. 85.S. Zhang, H. Huang, and Y. Fu. Fast parallel implementation of dual-camera compressive hyperspectral imaging system. IEEE Transactions on Circuits and Systems for Video Technology, 29(11):3404–3414, 2019. 3
  86. 86.Tao Zhang, Ying Fu, and Cheng Li. Deep spatial adaptive network for real image demosaicing. In Association for the Advancement of Artificial Intelligence, volume 36, pages 3326–3334, 2022.
  87. 87.Tao Zhang, Ying Fu, and Jun Zhang. Guided hyperspectral image denoising with realistic data. International Journal of Computer Vision, 130(11):2885–2901, 2022. 3
  88. 88.Hengshuang Zhao, Jianping Shi, Xiaojuan Qi, Xiaogang Wang, and Jiaya Jia. Pyramid scene parsing network. In Proceedings of IEEE International Conference on Computer Vision, pages 2881–2890, 2017. 6
  89. 89.Bolei Zhou, Hang Zhao, Xavier Puig, Sanja Fidler, Adela Barriuso, and Antonio Torralba. Scene parsing through ade20k dataset. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 633–641, 2017. 5
  90. 90.Jingkai Zhou, Varun Jampani, Zhixiong Pi, Qiong Liu, and Ming-Hsuan Yang. Decoupled dynamic filter networks. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 6647–6656, 2021. 3
  91. 91.Xizhou Zhu, Han Hu, Stephen Lin, and Jifeng Dai. Deformable convnets v2: More deformable, better results. In Proceedings of IEEE Conference on Computer Vision and Pattern Recognition, pages 9308–9316, 2019. 3, 4, 5, 6, 7
  92. 92.Xueyan Zou, Fanyi Xiao, Zhiding Yu, and Yong Jae Lee. Delving deeper into anti-aliasing in convnets. In Proceedings of the British Machine Vision Conference, pages 1–13, 2020. 3

Citation

MLA
Chen, L., et al. “Frequency-Adaptive Dilated Convolution for Semantic Segmentation”. arXiv, 2024, http://arxiv.org/abs/2403.05369v7.
APA
Chen, L., Gu, L., & Fu, Y. (2024). Frequency-Adaptive Dilated Convolution for Semantic Segmentation. arXiv. http://arxiv.org/abs/2403.05369v7
Chicago
Chen, L., L. Gu, and Y. Fu. 2024. “Frequency-Adaptive Dilated Convolution for Semantic Segmentation”. arXiv. http://arxiv.org/abs/2403.05369v7.
Harvard
Chen, L., Gu, L. and Fu, Y. (2024) “Frequency-Adaptive Dilated Convolution for Semantic Segmentation”, arXiv [Preprint]. Available at: http://arxiv.org/abs/2403.05369v7.
Vancouver
1. Chen L, Gu L, Fu Y (2024) Frequency-Adaptive Dilated Convolution for Semantic Segmentation. arXiv

BibTeX

@article{chen2024frequency,
  title = {Frequency-Adaptive Dilated Convolution for Semantic Segmentation},
  author = {Chen, Linwei and Gu, Lin and Fu, Ying},
  year = {2024},
  journal = {arXiv},
  url = {http://arxiv.org/abs/2403.05369v7},
  eprint = {2403.05369}
}
Metadata:arXiv

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: IEEE