Chart-to-Text: A Large-Scale Benchmark for Chart Summarization

Shankar KantharajRixie Tiffany Ko LeongXiang LinAhmed MasryMegh ThakkarEnamul HoqueShafiq R. Joty

article2022ACL224 citations

Presents a large-scale benchmark of over 44,000 diverse charts alongside state-of-the-art neural baselines to evaluate automated chart summarization from both raw images and underlying data tables.

Listen

Visual data representations such as bar, line, and pie charts are essential across modern organizations for communicating insights and supporting decision-making. However, extracting key takeaways directly from charts requires significant cognitive effort, and charts often lack clear explanatory captions. Generating natural language summaries automatically can assist report writers, improve document indexing, and enhance accessibility for individuals who rely on screen readers. Existing methods remain limited because they rely heavily on rigid templates, lack large-scale benchmark data, or focus narrowly on raw tables without addressing the unique visual structures and high-level trends conveyed by charts.

The article introduces a large-scale benchmark and establishes baseline models to advance automated chart summarization. It evaluates text generation across two practical scenarios: one where the underlying structured data table is available, and a more realistic and difficult scenario where models must interpret chart images directly without access to raw data.

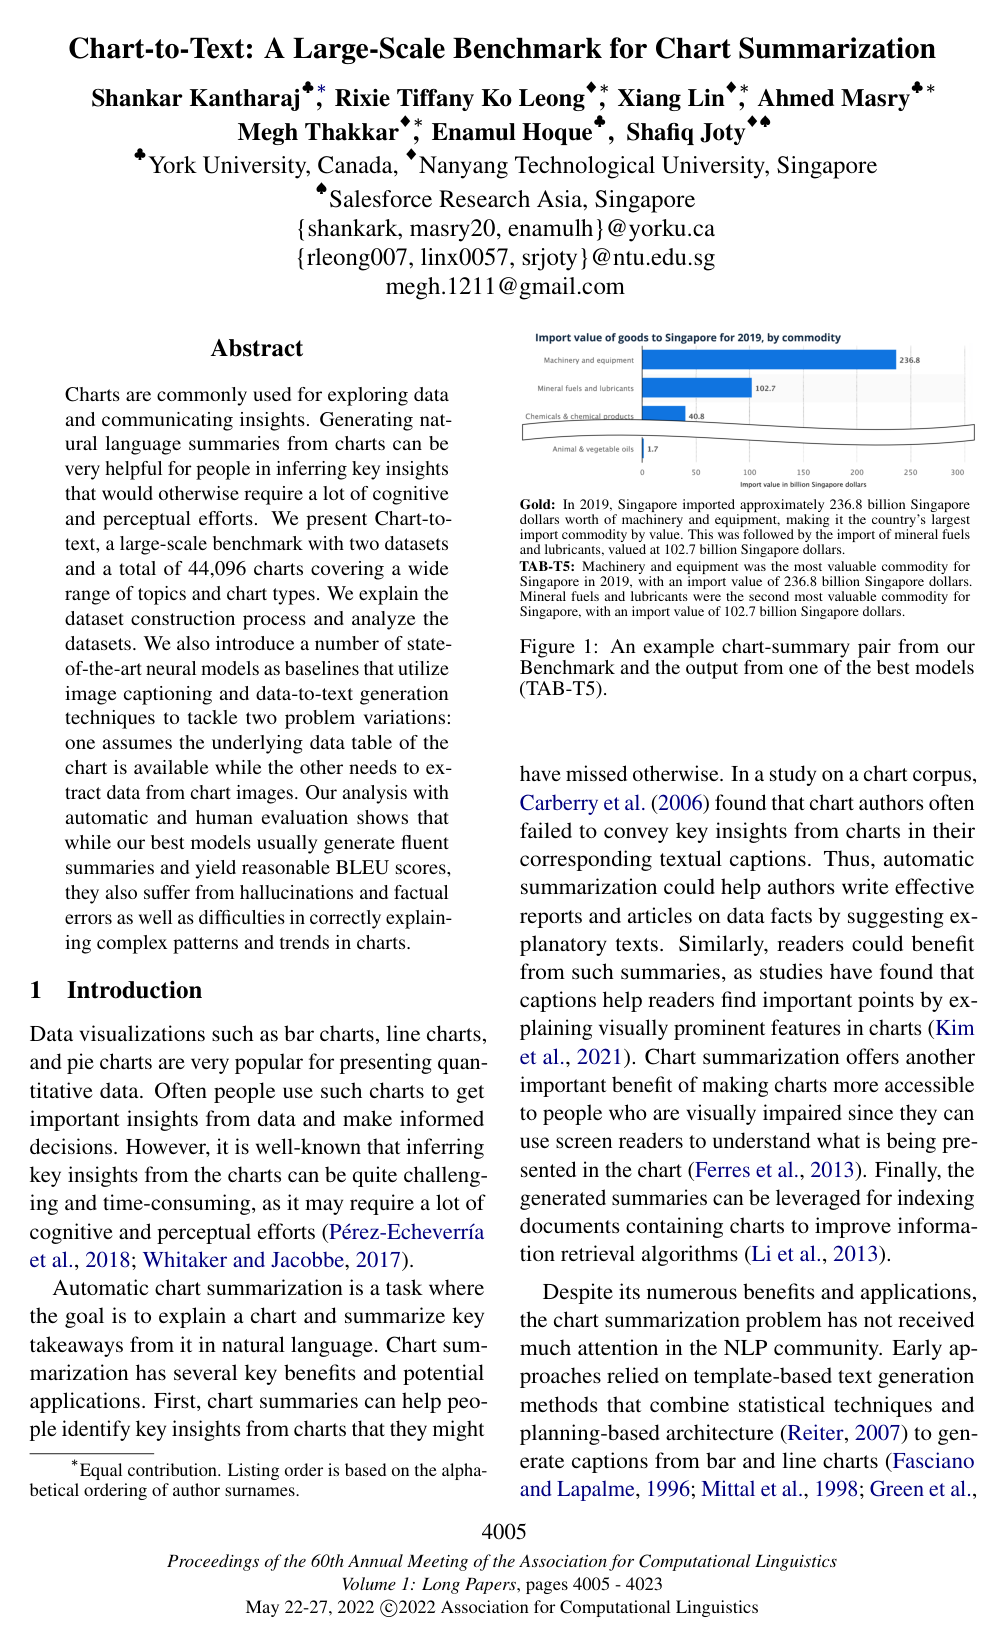
To conduct this evaluation, the authors compiled a comprehensive benchmark of 44,096 charts and natural language descriptions drawn from two major sources: Statista (34,811 charts with structured tables) and Pew Research (9,285 charts without raw tables). They established baseline architectures across three distinct technical categories: pure image captioning models, structured data-to-text models, and combined vision-text pipelines that extract visual data using optical character recognition (OCR) and deep learning. The models were evaluated using both standard automatic language metrics and human evaluations on factual correctness, coherence, and fluency.

The findings show that pretrained transformer language models—specifically T5 and BART—substantially outperform standard image captioning and non-pretrained models. When structured data tables are available, these models achieve strong fluency and content selection scores, reaching a BLEU quality score of 37.01. However, when models must rely solely on chart images through OCR pipelines, performance drops significantly, resulting in a BLEU score of 10.49 on complex charts. Furthermore, both automatic and human evaluations revealed that current models frequently suffer from hallucinations and factual errors, particularly struggling to accurately interpret visual trends, complex patterns, and relationships between numbers and visual marks.

These results demonstrate that while current language models can generate fluent summaries, automated chart-to-text systems are not yet sufficiently reliable for unmonitored decision-making. In high-stakes environments, publishing unedited model outputs introduces significant compliance and operational risks by potentially spreading incorrect facts or misleading trend analyses. The findings also emphasize that pretraining models on general table data yields only marginal improvements, underscoring that chart interpretation requires fundamentally distinct visual and logical reasoning capabilities.

Organizations and researchers pursuing automated visualization reporting should avoid deploying pure image captioning architectures and focus instead on hybrid vision-language systems with structured intermediate extraction. Before adopting these systems in production, organizations should establish robust human-in-the-loop verification processes to catch factual distortions. Future technical development should prioritize improving chart-specific data extraction, developing graph representations to map visual marks to data points, and expanding benchmarks to cover more visual styles and chart formats.

arXiv: 2203.06486
Cover for Chart-to-Text: A Large-Scale Benchmark for Chart Summarization

Abstract

Charts are commonly used for exploring data and communicating insights. Generating natural language summaries from charts can be very helpful for people in inferring key insights that would otherwise require a lot of cognitive and perceptual efforts. We present Chart-to-text, a large-scale benchmark with two datasets and a total of 44,096 charts covering a wide range of topics and chart types. We explain the dataset construction process and analyze the datasets. We also introduce a number of state-of-the-art neural models as baselines that utilize image captioning and data-to-text generation techniques to tackle two problem variations: one assumes the underlying data table of the chart is available while the other needs to extract data from chart images. Our analysis with automatic and human evaluation shows that while our best models usually generate fluent summaries and yield reasonable BLEU scores, they also suffer from hallucinations and factual errors as well as difficulties in correctly explaining complex patterns and trends in charts.

Table of Contents

  • 1 Introduction
  • 2 Related Work
  • 3 Chart-to-text Datasets
  • 3.1 Data Collection
  • 3.2 Data Annotation
  • 3.3 Dataset Analysis
  • 4 Chart-to-text Baseline Models
  • 4.1 Image Captioning Models
  • 4.2 Data-to-text Models
  • 5 Evaluation
  • 5.1 Automatic Evaluation
  • 5.2 Human Evaluation
  • 5.3 Error Analysis and Challenges
  • 6 Conclusion
  • Acknowledgement
  • Ethical Considerations
  • References
  • A Appendices
  • A.1 Additional Details on Data Annotation
  • A.1.1 Example Webpage from Statista
  • A.1.2 Annotation of x-axis Labels in Statista
  • A.1.3 Identify Candidate Paragraphs in Pew
  • A.1.4 Relevant Paragraph Selection in Pew
  • A.2 Dataset Analysis
  • A.3 Chart-to-text Baseline Models
  • A.4 Additional Results from Evaluation
  • A.4.1 Transfer Results
  • A.4.2 Performance by Chart Types
  • A.4.3 Human Evaluation
  • A.5 Automatic Data Extraction from Charts
  • A.6 Additional Examples from Statista and Pew datasets

Knowls

  1. Knowl 1 — Chart-to-Text benchmark composition and coverage

    data/table

    Chart-to-Text is a benchmark for generating natural-language summaries of quantitative charts, containing 44,096 chart–summary pairs from two sources. The Statista portion was collected in December 2020 by crawling 34,810 publicly accessible webpages, yielding 34,811 charts. Each example includes a chart image, underlying data table, title, axis labels, and human-written description. Statista charts were called simple when their data table had two columns and complex when it had at least three columns, including stacked and grouped bar charts and multi-line charts. The Pew portion was collected from 3,999 publicly accessible webpages in January 2021, yielding 9,285 charts. Pew examples include chart images, surrounding text, and available image alternative text; only 143 Pew charts had underlying data tables, so their simple/complex labels were assigned manually.

    The chart-type distribution reported on page 4 is: Statista—bar: 24,591 simple and 5,616 complex; line: 2,646 simple and 902 complex; pie: 409 simple and 0 complex; table: 223 simple and 424 complex; area and scatter: 0. Pew—bar: 807 simple and 5,497 complex; line: 325 simple and 2,129 complex; area: 29 simple and 105 complex; scatter: 0 simple and 68 complex; pie: 325 simple and 0 complex; table: 0. The resulting totals are 27,869 simple and 6,942 complex Statista charts, and 1,486 simple and 7,799 complex Pew charts. Bar charts therefore dominate both datasets, while Pew contains a larger proportion of line, area, and scatter charts and substantially more complex examples.

  2. Knowl 2 — Dataset annotation and relevant-paragraph selection pipeline

    algorithm

    The benchmark uses different annotation procedures for Statista and Pew. For Statista, the chart summary is the first portion of the webpage text, beginning at the chart icon and ending at the next heading; later text was treated as background information. When x-axis labels were missing, regular expressions were first applied to column values to identify entity types such as years or locations. Of the 32,660 Statista charts without x-axis labels, 7,170 still lacked labels after this step; Wikidata was then used to propose entity-type labels, which annotators either accepted or replaced with more specific labels.

    For Pew, CRAFT OCR was applied to chart images. Text bounding boxes and normalized geometric features were used by separate gradient-boosting classifiers for each chart type to assign text roles among title, axis label, legend, and data label. The classifiers were trained from 319 manually labeled charts—171 bar, 68 line, and 80 pie—with an 8:1:1 train/validation/test split. They achieved 95.0% overall precision and 97.6% precision for title classification. If alternative text was available, the longer of the alternative text and extracted title was retained.

    For each Pew chart, the paragraph adjacent to the chart and the five paragraphs before and after it were selected as candidate paragraphs, giving at most 11 candidates. For sentence ii, let lil_i be the number of lexical-token matches with chart OCR text, nin_i the number of matching numerical tokens excluding years, yiy_i the number of matching year tokens, and uiu_i the number of numerical tokens in the sentence absent from the chart. The sentence score is si=0.58li+1.4ni−0.5uis_i=0.58l_i+1.4n_i-0.5u_i. For a paragraph with cc sentences, its content score is content=1/[1+exp⁡(0.3(−max⁡isi+1.7))]\mathrm{content}=1/[1+\exp(0.3(-\max_i s_i+1.7))]. If dist\mathrm{dist} is the paragraph’s signed distance from the chart, with −5≤dist≤5-5\leq\mathrm{dist}\leq5, its proximity score is proximity=0.4exp⁡(−0.1∣dist∣2)+0.6\mathrm{proximity}=0.4\exp(-0.1|\mathrm{dist}|^2)+0.6. The relevance score is rel=content×proximity\mathrm{rel}=\mathrm{content}\times\mathrm{proximity}.

    A candidate paragraph was automatically retained when ∑ili>3\sum_i l_i>3, ∑i(ni+yi)>0\sum_i(n_i+y_i)>0, ∑iui=0\sum_i u_i=0, rel>0.72\mathrm{rel}>0.72, and c>0c>0. On a sample of 95 charts and 769 surrounding paragraphs, this heuristic achieved 100% precision and 21.1% recall. Human annotation was then performed for 5,478 charts and 13,237 paragraphs, with two workers per chart; 2,888 disagreements were resolved internally. Inter-annotator agreement was 78.2%.

  3. Knowl 3 — Linguistic and semantic properties of the datasets

    data/table

    The benchmark’s linguistic statistics show that Pew summaries are substantially longer than Statista summaries, and complex-chart summaries are longer than simple-chart summaries. The reported values are:

    • Statista simple: vocabulary 39,191; average 295 characters, 54 tokens, and 2.56 sentences.
    • Statista complex: vocabulary 18,621; average 334 characters, 61 tokens, and 2.62 sentences.
    • Pew simple: vocabulary 9,905; average 571 characters, 110 tokens, and 3.84 sentences.
    • Pew complex: vocabulary 18,067; average 635 characters, 124 tokens, and 4.27 sentences.

    A manual analysis of 100 randomly sampled chart–summary pairs from each dataset categorized sentence content into four levels. Statista summaries contained 32.03% visual-encoding content, 50.00% statistical/comparative content, 8.98% perceptual/cognitive content, and 10.94% contextual/domain-specific content. Pew summaries contained 0.98%, 54.63%, 30.49%, and 12.93% in the same categories. Statistical and comparative statements such as minima, maxima, averages, and rankings are therefore the most common content in both datasets, whereas Pew summaries contain many more trend- and causal-reasoning statements. Statista summaries more often explain axes or visual encodings. Statista topics are relatively evenly distributed, while U.S. Politics & Policy accounts for 45.4% of Pew charts. Each dataset was randomly divided into 70% training, 15% validation, and 15% test examples.

  4. Knowl 4 — Two chart-to-text problem settings

    definition

    The benchmark defines each chart–summary example as a tuple ⟨C,T,M,S⟩\langle C,T,M,S\rangle, where CC is the chart image, TT is the underlying data table, MM is chart metadata, and SS is the human-written textual summary. Each cell in TT stores its string value, row position, column position, and whether it is a header cell. Metadata is M=(Ctitle,Ctype,Clabels)M=(C_{\mathrm{title}},C_{\mathrm{type}},C_{\mathrm{labels}}), consisting of the chart title, chart type, and axis labels.

    The first task setting supplies X=⟨C,T,M⟩X=\langle C,T,M\rangle and asks a model to generate a summary S^\hat S. The second, more realistic setting withholds the data table and supplies only X=⟨C,M⟩X=\langle C,M\rangle; the model must infer relevant chart content from the image and metadata. The benchmark evaluates three model families: image-captioning systems that use only the chart image, data-to-text systems that use structured or extracted table content, and vision-plus-text systems that first extract chart text with OCR and then generate a summary.

  5. Knowl 5 — Neural baseline model suite

    model/method

    The image-captioning baseline adapts Show, Attend, and Tell by using ResNet-50 as the image encoder and a unidirectional LSTM as the text decoder. Because an ImageNet object-detection encoder performed poorly on chart images and chart object labels were unavailable, a separate ResNet-50 encoder was pretrained for each dataset with the self-supervised Barlow Twins objective and then used for caption generation.

    The Chart2text data-to-text baseline represents each table record as tuples such as column header, cell value, and column index, adds positional encodings, and trains an auxiliary binary objective indicating whether each input record appears in the output. It also uses target-text templates containing data variables to reduce hallucination. The Field-Infusing baseline encodes each cell with an LSTM, concatenates row-index and column-heading embeddings, and feeds the resulting representations to a three-layer Transformer encoder–decoder. For OCR inputs, both models additionally concatenate bounding-box information to the text representations.

    BART and T5 provide pretrained sequence-to-sequence baselines. BART receives the chart title followed by the table flattened row by row; when no table is available, it receives OCR-extracted text ordered from top to bottom. T5 uses the same serialization with the prefix ‘translate Chart to Text:’. An OCR-T5 spatial variant projects each detected token’s bounding-box coordinates through a linear layer and adds the resulting positional embedding to the token embedding. These models test whether large-scale language-model pretraining and, for OCR inputs, spatial information improve chart summarization.

  6. Knowl 6 — Automatic evaluation and baseline performance

    empirical result

    The benchmark evaluates summaries with BLEU, CIDEr, BLEURT, content selection (CS), and GPT-2 perplexity (PPL). BLEU and CIDEr measure n-gram overlap, with CIDEr using TF–IDF weighting; BLEURT measures grammaticality and semantic agreement with the reference; CS measures matching of selected chart records; and lower PPL indicates greater language-model fluency. The complete test-set results reported on page 7 are listed as BLEU, CS, BLEURT, CIDEr, and PPL in that order.

    On Statista: Image Caption achieved 15.94, 25.70%, -0.76, 0.95, 10.53; TAB-Chart2text 21.10, 56.10%, 0.06, 2.61, 28.79; TAB-Field-Infuse 12.09, 42.07%, -0.32, 1.78, 17.01; TAB-BART 36.36, 77.14%, 0.12, 4.40, 12.55; TAB-T5 37.01, 75.72%, 0.15, 4.68, 10.00; OCR-T5 35.29, 73.77%, 0.10, 4.43, 8.66; OCR-T5 with bounding-box information 34.55, 73.55%, 0.09, 4.37, 8.59; TAB_OCR-Chart2text 7.64, 47.58%, -0.44, 1.09, 54.98; TAB_OCR-Field-Infuse 7.03, 37.63%, -0.49, 1.18, 14.76; TAB_OCR-BART 35.83, 72.15%, 0.09, 3.97, 13.99; and TAB_OCR-T5 36.74, 72.22%, 0.13, 4.33, 10.20.

    On Pew: Image Caption achieved 4.09, 2.14%, -0.96, 0.38, 16.43; OCR-Chart2Text with bounding-box information 7.20, 24.49%, -0.56, 0.65, 12.11; OCR-Field-Infuse with bounding-box information 0.19, 10.12%, -1.01, 0.26, 9.57; OCR-BART 9.09, 39.99%, -0.38, 1.97, 11.04; OCR-T5 10.49, 40.87%, -0.35, 2.20, 10.11; and OCR-T5 with bounding-box information 10.42, 40.31%, -0.42, 2.13, 8.65.

    The results show that pretrained BART and T5 models substantially outperform the non-pretrained baselines on Statista. TAB-T5 is the strongest overall Statista model by BLEU, BLEURT, and CIDEr, while image captioning produces fluent but poorly content-selected text. OCR-based models remain fluent but lose content-selection quality because OCR introduces noise. Pew is much harder: all scores fall sharply, although OCR-based vision-plus-text models still improve substantially over image-only captioning.

  7. Knowl 7 — Structured table extraction from chart images

    algorithm

    To support the no-table setting, the authors extend ChartOCR to recover a fully structured table rather than only raw numerical values. A key-point detector identifies chart regions and marks, including plot area, axes, legends, bars, line points, pie slices, textual labels, and legend marks. Rectangular marks are grouped from detected top-left and bottom-right points; line points are grouped by color; and pie slices are represented by separating points along the pie perimeter. The chart scale is estimated from y-axis values and their image coordinates, after which bar and line-point values are calculated from the scale and pie values from slice angles.

    CRAFT recognizes x-axis and legend text. Each numerical mark is associated with its closest x-axis label, while each data series is associated with a legend label using color matching. This converts detected marks into rows and columns with labels, values, and series identities. The resulting automatic table-extraction accuracy was 77.31%.

    For ground-truth value gtgt and predicted value prpr, the point distance is D(gt,pr)=min⁡(1,∥gt−prgt∥)D(gt,pr)=\min\left(1,\left\|\frac{gt-pr}{gt}\right\|\right). For NN ground-truth values and MM predicted values, the cost matrix is Cn,m=D(gtn,prm)C_{n,m}=D(gt_n,pr_m). Let K=max⁡(N,M)K=\max(N,M) and let XX be a binary assignment matrix selected by the linear sum assignment problem. The extraction score for one chart is score=1−cost/K\mathrm{score}=1-\mathrm{cost}/K, where cost=∑i=1K∑j=1KCi,jXi,j\mathrm{cost}=\sum_{i=1}^{K}\sum_{j=1}^{K}C_{i,j}X_{i,j}. The reported overall score is the average across charts. Models using these automatically extracted tables were less effective at selecting relevant information than models using gold tables.

  8. Knowl 8 — Human comparison of generated summaries

    empirical result

    A human evaluation used 150 randomly sampled Statista charts, four native-English annotators, and 450 pairwise comparisons among TAB-T5, OCR-T5, and the original gold summary. Annotators judged factual correctness, coherence, and fluency; the first 150 comparisons had two annotations, producing 74.3% agreement after ties were excluded. The pairwise results reported on page 8 were:

    • TAB-T5 versus OCR-T5: TAB-T5 won on factual correctness in 55.3% of comparisons, coherence in 23.3%, and fluency in 20.0%; OCR-T5 won in 12.0%, 11.3%, and 11.3%; ties occurred in 32.7%, 65.3%, and 68.7%. Sign-test p-values were 1.86×10−111.86\times10^{-11}, 8.77×10−38.77\times10^{-3}, and 0.03950.0395.
    • Gold versus TAB-T5: the gold summary won on factual correctness in 30.0% of comparisons, coherence in 36.7%, and fluency in 22.0%; TAB-T5 won in 13.3%, 16.7%, and 14.0%; ties occurred in 56.7%, 46.7%, and 64.0%. Sign-test p-values were 1.31×10−31.31\times10^{-3}, 5.26×10−45.26\times10^{-4}, and 0.06680.0668.
    • Gold versus OCR-T5: the gold summary won on factual correctness in 59.3% of comparisons, coherence in 43.3%, and fluency in 28.7%; OCR-T5 won in 7.33%, 15.3%, and 17.3%; ties occurred in 33.3%, 41.3%, and 54.0%. Sign-test p-values were 1.27×10−161.27\times10^{-16}, 4.25×10−64.25\times10^{-6}, and 0.02660.0266.

    Thus TAB-T5 was preferred to OCR-T5 on all three criteria, especially factual correctness. Model fluency was comparatively close to the gold summaries, but factual correctness and coherence were significantly worse, particularly when the model had to rely on OCR rather than a structured data table.

  9. Knowl 9 — Observed failure modes and chart-understanding limitations

    limitation

    A manual analysis of 200 random examples examined TAB-T5 and OCR-T5 on Statista and OCR-BART and OCR-T5 on Pew. The models often generated fluent text containing hallucinated facts or chart-irrelevant statements. Factual errors were more frequent for OCR-based systems because OCR text does not reliably preserve associations between values and the corresponding categories or series; TAB-T5, which receives the table, produced fewer such errors.

    The models also struggled with perceptual and reasoning content, especially complex trends and relationships that are visually apparent to people but difficult to infer from a sequence of raw values. OCR systems additionally fail when data values are not printed as text on the chart, and even recognized values can be assigned to the wrong category. The authors identify structured chart-data extraction and richer representations, such as semantic graphs encoding numerical and logical relations among chart objects, as needed improvements. Although the benchmark spans many topics, chart types, layouts, colors, and typographic styles, the authors note that more sources and cross-domain evaluations are needed to establish generalizability. Because fluent outputs can still contain unsupported or incorrect claims, the systems require factual correction before publication.

  10. Knowl 10 — Transferability and performance by chart type

    empirical result

    Transfer experiments fine-tuned T5 models on one dataset after pretraining on another chart-to-text dataset or on ToTTo, a large open-domain table-to-text dataset. The resulting BLEU scores were: ToTTo→Pew, 10.66; ToTTo→Statista, 37.19; Pew→Statista, 37.32; and Statista→Pew, 10.73. Pretraining on another dataset produced only marginal improvements, indicating limited cross-dataset transfer under the reported setup.

    The best Statista model, TAB-T5, was also evaluated by chart type. Its results were:

    • Bar: BLEU 36.46, PPL 10.08, CIDEr 4.62, BLEURT 0.14.
    • Line: BLEU 45.28, PPL 7.53, CIDEr 5.59, BLEURT 0.27.
    • Pie: BLEU 21.35, PPL 8.79, CIDEr 3.27, BLEURT -0.13.
    • Table: BLEU 26.12, PPL 11.34, CIDEr 3.67, BLEURT -0.22.

    TAB-T5 performs best on frequent and relatively simple chart types, especially line charts, and is substantially less effective on less frequent or structurally complex types such as pie charts.

Coverage note — No substantial contributed material was omitted; detailed hardware, optimizer, and training-duration settings were excluded as reproducibility details rather than load-bearing contributions.

References

  1. 1.
    1. Wikidata knowledge base.
  2. 2.Harsh Agrawal, Karan Desai, Yufei Wang, Xinlei Chen, Rishabh Jain, Mark Johnson, Dhruv Batra, Devi Parikh, Stefan Lee, and Peter Anderson. 2019. nocaps: novel object captioning at scale. In Proceedings of the IEEE International Conference on Computer Vision, pages 8948–8957.
  3. 3.Jeonghun Baek, Geewook Kim, Junyeop Lee, Sungrae Park, Dongyoon Han, Sangdoo Yun, Seong Joon Oh, and Hwalsuk Lee. 2019a. What is wrong with scene text recognition model comparisons? dataset and model analysis. In International Conference on Computer Vision (ICCV).
  4. 4.Youngmin Baek, Bado Lee, Dongyoon Han, Sangdoo Yun, and Hwalsuk Lee. 2019b. Character region awareness for text detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 9365–9374.
  5. 5.Regina Barzilay and Mirella Lapata. 2005. Collective content selection for concept-to-text generation. In Proceedings of Human Language Technology Conference and Conference on Empirical Methods in Natural Language Processing, pages 331–338, Vancouver, British Columbia, Canada. Association for Computational Linguistics.
  6. 6.Sandra Carberry, Stephanie Elzer, and Seniz Demir. 2006. Information graphics: an untapped resource for digital libraries. In Proceedings of the 29th annual international ACM SIGIR conference on Research and development in information retrieval, pages 581–588.
  7. 7.Charles Chen, Ruiyi Zhang, Eunyee Koh, Sungchul Kim, Scott Cohen, Tong Yu, Ryan A. Rossi, and Razvan C. Bunescu. 2019. Figure captioning with reasoning and sequence-level training. CoRR, abs/1906.02850.
  8. 8.Wenhu Chen, Jianshu Chen, Yu Su, Zhiyu Chen, and William Yang Wang. 2020a. Logical natural language generation from open-domain tables. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 7929–7942, Online. Association for Computational Linguistics.
  9. 9.Xinlei Chen, Hao Fang, Tsung-Yi Lin, Ramakrishna Vedantam, Saurabh Gupta, Piotr Dollar, and C. Lawrence Zitnick. 2015. Microsoft coco captions: Data collection and evaluation server.
  10. 10.Zhiyu Chen, Wenhu Chen, Hanwen Zha, Xiyou Zhou, Yunkai Zhang, Sairam Sundaresan, and William Yang Wang. 2020b. Logic2Text: High-fidelity natural language generation from logical forms. In Findings of the Association for Computational Linguistics: EMNLP 2020, pages 2096–2111, Online. Association for Computational Linguistics.
  11. 11.J. Choi, Sanghun Jung, Deok Gun Park, J. Choo, and N. Elmqvist. 2019. Visualizing for the non-visual: Enabling the visually impaired to use visualization. Computer Graphics Forum, 38.
  12. 12.Zhe Cui, Sriram Karthik Badam, M Adil Yalçin, and Niklas Elmqvist. 2019. Datasite: Proactive visual data exploration with computation of insight-based recommendations. Information Visualization, 18(2):251–267.
  13. 13.Seniz Demir, Sandra Carberry, and Kathleen F. McCoy. 2012. Summarizing information graphics textually. Computational Linguistics, 38(3):527–574.
  14. 14.Jia Deng, Wei Dong, Richard Socher, Li-Jia Li, Kai Li, and Li Fei-Fei. 2009. Imagenet: A large-scale hierarchical image database. In 2009 IEEE Conference on Computer Vision and Pattern Recognition, pages 248–255.
  15. 15.Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. 2019. BERT: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers), pages 4171–4186, Minneapolis, Minnesota. Association for Computational Linguistics.
  16. 16.Massimo Fasciano and Guy Lapalme. 1996. Postgraphe: a system for the generation of statistical graphics and text. In Eighth International Natural Language Generation Workshop.
  17. 17.Leo Ferres, Gitte Lindgaard, Livia Sumegi, and Bruce Tsuji. 2013. Evaluating a tool for improving accessibility to charts and graphs. ACM Trans. Comput.-Hum. Interact., 20(5).
  18. 18.Li Gong, Josep Crego, and Jean Senellart. 2019. Enhanced transformer model for data-to-text generation. In Proceedings of the 3rd Workshop on Neural Generation and Translation, pages 148–156, Hong Kong. Association for Computational Linguistics.
  19. 19.Nancy L Green, Giuseppe Carenini, Stephan Kerpedjiev, Joe Mattis, Johanna D Moore, and Steven F Roth. 2004. Autobrief: an experimental system for the automatic generation of briefings in integrated text and information graphics. International Journal of Human-Computer Studies, 61(1):32–70.
  20. 20.Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. 2016. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 770–778.
  21. 21.Sepp Hochreiter and Jürgen Schmidhuber. 1997. Long short-term memory. Neural Comput., 9(8):1735–1780.
  22. 22.Ting-Yao E. Hsu, C. Lee Giles, and Ting-Hao K. Huang. 2021. Scicap: Generating captions for scientific figures. In Findings of 2021 Conference on Empirical Methods in Natural Language Processing (EMNLP 2021 Findings).
  23. 23.Dae Hyun Kim, Vidya Setlur, and Maneesh Agrawala. 2021. Towards understanding how readers integrate charts and captions: A case study with line charts. In Proceedings of the CHI Conference on Human Factors in Computing Systems, pages 1–11.
  24. 24.Rémi Lebret, David Grangier, and Michael Auli. 2016. Neural text generation from structured data with application to the biography domain. In Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing, pages 1203–1213, Austin, Texas. Association for Computational Linguistics.
  25. 25.Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Veselin Stoyanov, and Luke Zettlemoyer. 2020. BART: Denoising sequence-to-sequence pre-training for natural language generation, translation, and comprehension. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 7871–7880, Online. Association for Computational Linguistics.
  26. 26.Zhuo Li, Matthew Stagitis, Sandra Carberry, and Kathleen F McCoy. 2013. Towards retrieving relevant information graphics. In Proceedings of the 36th international ACM SIGIR conference on Research and development in information retrieval, pages 789–792.
  27. 27.Alan Lundgard and Arvind Satyanarayan. 2022. Accessible Visualization via Natural Language Descriptions: A Four-Level Model of Semantic Content. IEEE Trans. Visualization & Comp. Graphics (Proc. IEEE VIS).
  28. 28.Junyu Luo, Zekun Li, Jinpeng Wang, and Chin-Yew Lin. 2021. Chartocr: Data extraction from charts images via a deep hybrid framework. 2021 IEEE Winter Conference on Applications of Computer Vision (WACV), pages 1916–1924.
  29. 29.Hongyuan Mei, TTI UChicago, Mohit Bansal, and Matthew R Walter. 2016. What to talk about and how? selective generation using lstms with coarse-to-fine alignment. In Proceedings of NAACL-HLT, pages 720–730.
  30. 30.Vibhu O. Mittal, Johanna D. Moore, Giuseppe Carenini, and Steven Roth. 1998. Describing complex charts in natural language: A caption generation system. Computational Linguistics, 24(3):431–467.
  31. 31.Jason Obeid and Enamul Hoque. 2020. Chart-to-text: Generating natural language descriptions for charts by adapting the transformer model. In Proceedings of the 13th International Conference on Natural Language Generation, pages 138–147. Association for Computational Linguistics.
  32. 32.Ankur Parikh, Xuezhi Wang, Sebastian Gehrmann, Manaal Faruqui, Bhuwan Dhingra, Diyi Yang, and Dipanjan Das. 2020. Totto: A controlled table-to-text generation dataset. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 1173–1186.
  33. 33.Matt Post. 2018. A call for clarity in reporting BLEU scores. In Proceedings of the Third Conference on Machine Translation: Research Papers, pages 186–191, Belgium, Brussels. Association for Computational Linguistics.
  34. 34.Mª del Puy Pérez-Echeverría, Yolanda Postigo, and Cristina Marín. 2018. Understanding of graphs in social science undergraduate students: selection and interpretation of graphs. Irish Educational Studies, 37(1):89–111.
  35. 35.Alec Radford, Jeff Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. 2019. Language models are unsupervised multitask learners. Open-AI Blog.
  36. 36.Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. 2020. Exploring the limits of transfer learning with a unified text-to-text transformer. Journal of Machine Learning Research, 21(140):1–67.
  37. 37.Ehud Reiter. 2007. An architecture for data-to-text systems. In Proceedings of the Eleventh European Workshop on Natural Language Generation, pages 97–104. Association for Computational Linguistics.
  38. 38.Ehud Reiter, Somayajulu Sripada, Jim Hunter, Jin Yu, and Ian Davy. 2005. Choosing words in computer-generated weather forecasts. Artificial Intelligence, 167(1-2):137–169.
  39. 39.Thibault Sellam, Dipanjan Das, and Ankur P Parikh. 2020. Bleurt: Learning robust metrics for text generation. arXiv preprint arXiv:2004.04696.
  40. 40.Oleksii Sidorov, Ronghang Hu, Marcus Rohrbach, and Amanpreet Singh. 2020. Textcaps: a dataset for image captioning with reading comprehension.
  41. 41.Andrea Spreafico and Giuseppe Carenini. 2020. Neural data-driven captioning of time-series line charts. In Proceedings of the International Conference on Advanced Visual Interfaces, AVI ’20, New York, NY, USA. Association for Computing Machinery.
  42. 42.Arjun Srinivasan, Steven M Drucker, Alex Endert, and John Stasko. 2018. Augmenting visualizations with interactive data facts to facilitate interpretation and communication. IEEE transactions on visualization and computer graphics, 25(1):672–681.
  43. 43.Yixuan Su, David Vandyke, Sihui Wang, Yimai Fang, and Nigel Collier. 2021. Plan-then-generate: Controlled data-to-text generation via planning. In Findings of the Association for Computational Linguistics: EMNLP 2021. Association for Computational Linguistics.
  44. 44.Hao Tan and Mohit Bansal. 2019. Lxmert: Learning cross-modality encoder representations from transformers. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing.
  45. 45.Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, and Herve Jegou. 2021. Training data-efficient image transformers & distillation through attention. In Proceedings of the 38th International Conference on Machine Learning, volume 139 of Proceedings of Machine Learning Research, pages 10347–10357. PMLR.
  46. 46.Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Ł ukasz Kaiser, and Illia Polosukhin. 2017. Attention is all you need. In Advances in Neural Information Processing Systems, volume 30. Curran Associates, Inc.
  47. 47.Ramakrishna Vedantam, C Lawrence Zitnick, and Devi Parikh. 2015. Cider: Consensus-based image description evaluation. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 4566–4575.
  48. 48.Douglas Whitaker and Tim Jacobbe. 2017. Students’ understanding of bar graphs and histograms: Results from the locus assessments. Journal of Statistics Education, 25(2):90–102.
  49. 49.Sam Wiseman, Stuart M Shieber, and Alexander M Rush. 2017. Challenges in data-to-document generation. arXiv preprint arXiv:1707.08052.
  50. 50.Kelvin Xu, Jimmy Ba, Ryan Kiros, Kyunghyun Cho, Aaron Courville, Ruslan Salakhutdinov, Richard Zemel, and Yoshua Bengio. 2015. Show, attend and tell: Neural image caption generation with visual attention. arXiv preprint arXiv:1502.03044.
  51. 51.Zichao Yang, Phil Blunsom, Chris Dyer, and Wang Ling. 2017. Reference-aware language models. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, pages 1850–1859.
  52. 52.Jure Zbontar, Li Jing, Ishan Misra, Yann LeCun, and Stéphane Deny. 2021. Barlow twins: Self-supervised learning via redundancy reduction. arXiv preprint arXiv:2103.03230.
  53. 53.Pengchuan Zhang, Xiujun Li, Xiaowei Hu, Jianwei Yang, Lei Zhang, Lijuan Wang, Yejin Choi, and Jianfeng Gao. 2021. Vinvl: Making visual representations matter in vision-language models. CVPR 2021.

Citation

MLA
Kantharaj, S., et al. “Chart-to-Text: A Large-Scale Benchmark for Chart Summarization”. Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 2022, pp. 4005–23, https://doi.org/10.18653/v1/2022.acl-long.277.
APA
Kantharaj, S., Leong, R. T., Lin, X., Masry, A., Thakkar, M., Hoque, E., & Joty, S. (2022). Chart-to-Text: A Large-Scale Benchmark for Chart Summarization. Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 4005–4023. https://doi.org/10.18653/v1/2022.acl-long.277
Chicago
Kantharaj, S., R. T. Leong, X. Lin, et al. 2022. “Chart-to-Text: A Large-Scale Benchmark for Chart Summarization”. Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 4005–23. https://doi.org/10.18653/v1/2022.acl-long.277.
Harvard
Kantharaj, S. et al. (2022) “Chart-to-Text: A Large-Scale Benchmark for Chart Summarization”, Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). Association for Computational Linguistics, pp. 4005–4023. Available at: https://doi.org/10.18653/v1/2022.acl-long.277.
Vancouver
1. Kantharaj S, Leong RT, Lin X, Masry A, Thakkar M, Hoque E, Joty S (2022) Chart-to-Text: A Large-Scale Benchmark for Chart Summarization. In: Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). Association for Computational Linguistics, pp 4005–4023

BibTeX

@inproceedings{kantharaj-etal-2022-chart,
    title = "Chart-to-Text: A Large-Scale Benchmark for Chart Summarization",
    author = "Kantharaj, Shankar  and
      Leong, Rixie Tiffany  and
      Lin, Xiang  and
      Masry, Ahmed  and
      Thakkar, Megh  and
      Hoque, Enamul  and
      Joty, Shafiq",
    editor = "Muresan, Smaranda  and
      Nakov, Preslav  and
      Villavicencio, Aline",
    booktitle = "Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month = may,
    year = "2022",
    address = "Dublin, Ireland",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2022.acl-long.277/",
    doi = "10.18653/v1/2022.acl-long.277",
    pages = "4005--4023"
}
Metadata:ACL Anthology

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: https://creativecommons.org/licenses/by/4.0/