
keyword
face verification
Face verification is a biometric and computer vision task that determines whether two facial images belong to the same person, functioning as a one-to-one matching process to confirm or reject a claimed identity. Unlike face identification, which searches across a database to discover a subject among many possibilities, verification compares a specific pair of face images directly. Modern systems typically employ deep neural networks to extract compact feature embeddings from detected faces, projecting them into a metric space where the distance or similarity between vectors is measured against a decision threshold. By striving to minimize intra-personal variations caused by pose, lighting, or aging while maximizing differences between distinct identities, face verification serves as a fundamental technology for secure authentication, smartphone unlocking, and digital identity management.
18 items
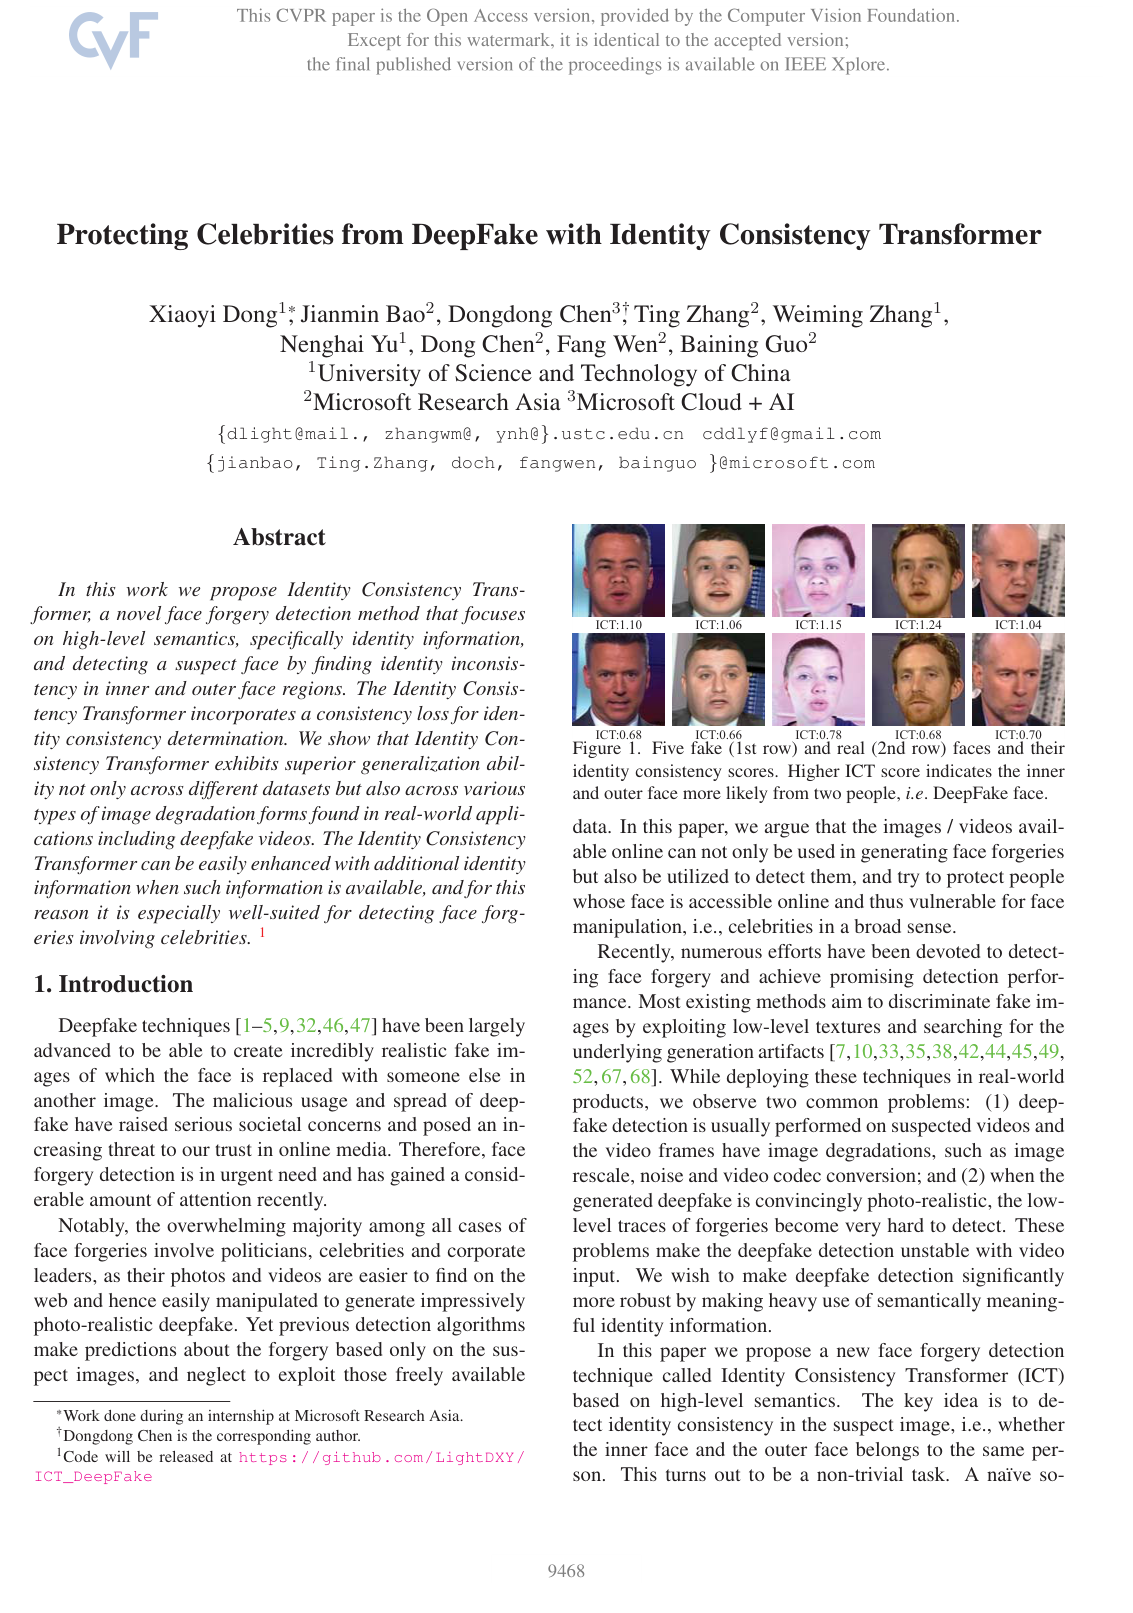
Protecting Celebrities from DeepFake with Identity Consistency Transformer
Xiaoyi Dong, Jianmin Bao, Dongdong Chen, Ting Zhang, Weiming Zhang, Nenghai Yu, Dong Chen, Fang Wen, Baining Guo
Why you should read this
Proposes an identity-consistency vision transformer that detects deepfakes by exposing semantic identity mismatches between inner and outer face regions, achieving high detection generalization under real-world video degradations without relying on fragile low-level texture artifacts.
In this work we propose Identity Consistency Transformer, a novel face forgery detection method that focuses on high-level semantics, specifically identity information, and detecting a suspect face by finding identity inconsistency in inner and outer face regions. The Identity Consistency Transformer incorporates a consistency loss for identity consistency determination. We show that Identity Consistency Transformer exhibits superior generalization ability not only across different datasets but also across various types of image degradation forms found in real-world applications including deepfake videos. The Identity Consistency Transformer can be easily enhanced with additional identity information when such information is available, and for this reason it is especially well-suited for detecting face forgeries involving celebrities.
Added
2026-09-26
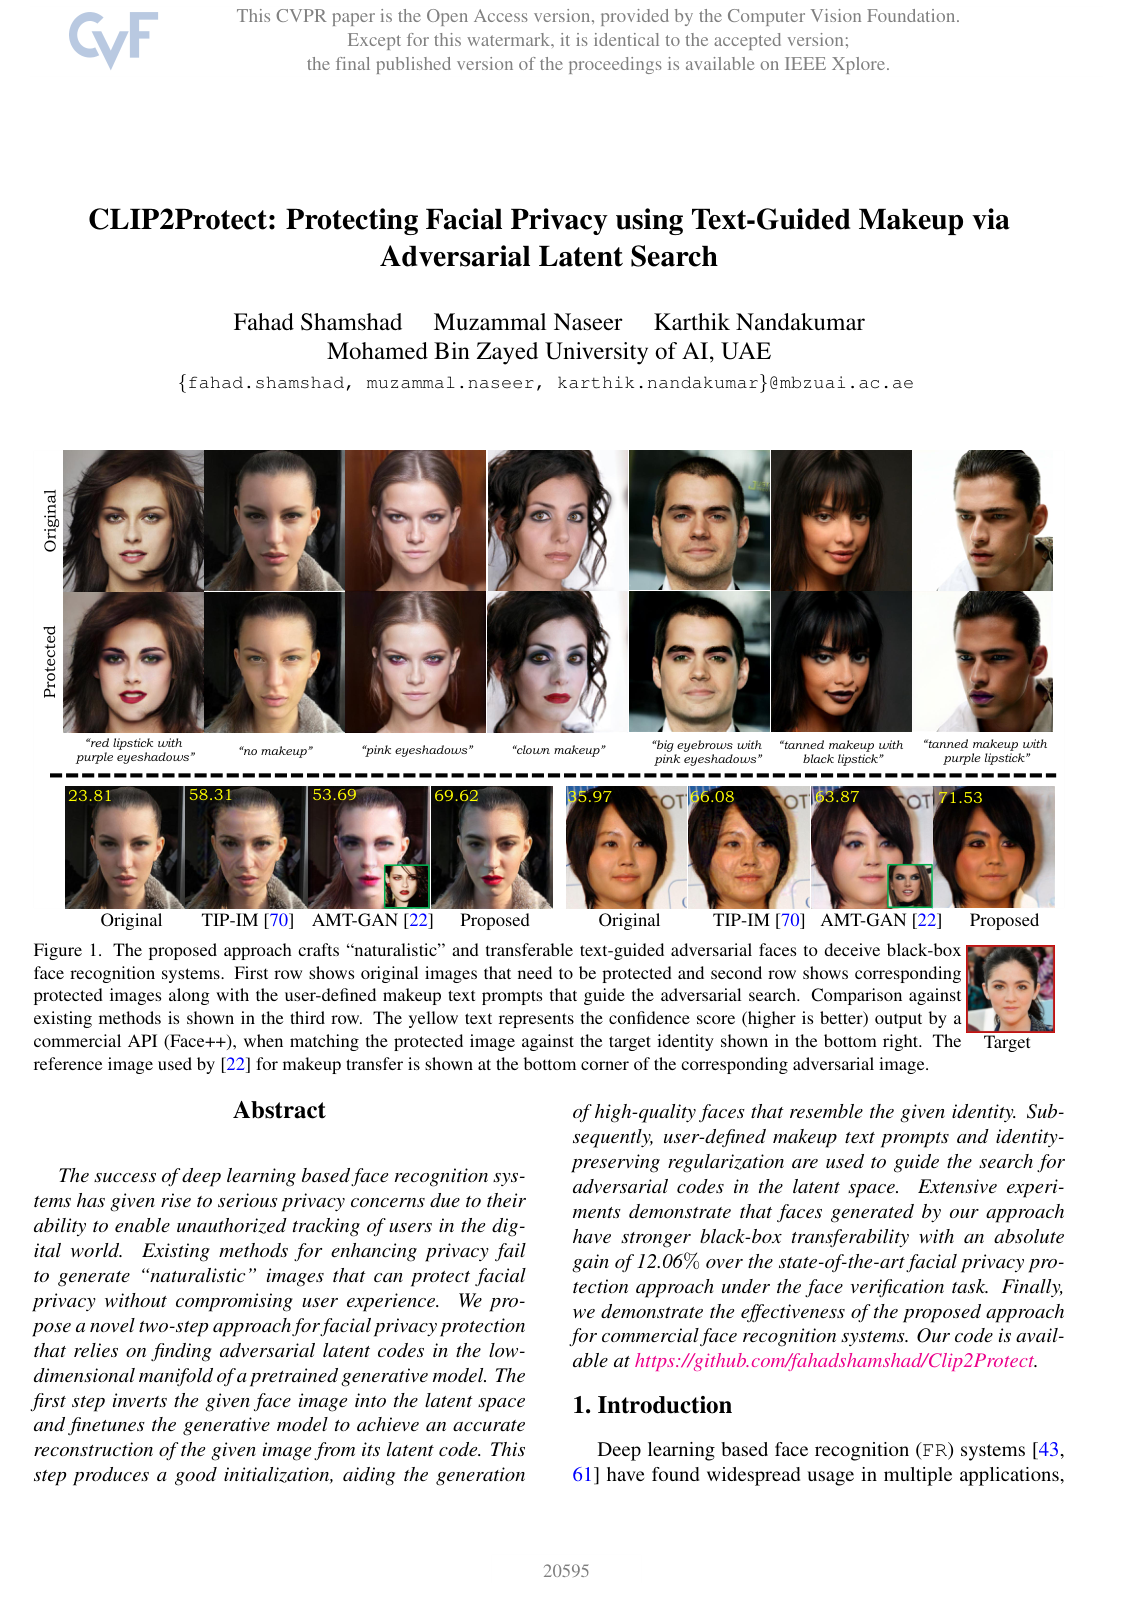
CLIP2Protect: Protecting Facial Privacy Using Text-Guided Makeup via Adversarial Latent Search
Fahad Shamshad, Muzammal Naseer, Karthik Nandakumar
Why you should read this
Proposes a text-guided generative framework that applies natural-looking adversarial makeup to face images, effectively deceiving commercial black-box face recognition systems while preserving human-perceived identity.
The success of deep learning based face recognition systems has given rise to serious privacy concerns due to their ability to enable unauthorized tracking of users in the digital world. Existing methods for enhancing privacy fail to generate “naturalistic” images that can protect facial privacy without compromising user experience. We propose a novel two-step approach for facial privacy protection that relies on finding adversarial latent codes in the low-dimensional manifold of a pretrained generative model. The first step inverts the given face image into the latent space and finetunes the generative model to achieve an accurate reconstruction of the given image from its latent code. This step produces a good initialization, aiding the generation of high-quality faces that resemble the given identity. Subsequently, user-defined makeup text prompts and identity-preserving regularization are used to guide the search for adversarial codes in the latent space. Extensive experiments demonstrate that faces generated by our approach have stronger black-box transferability with an absolute gain of 12.06% over the state-of-the-art facial privacy protection approach under the face verification task. Finally, we demonstrate the effectiveness of the proposed approach for commercial face recognition systems. Our code is available at https://github.com/fahadshamshad/Clip2Protect.
Added
2026-09-26
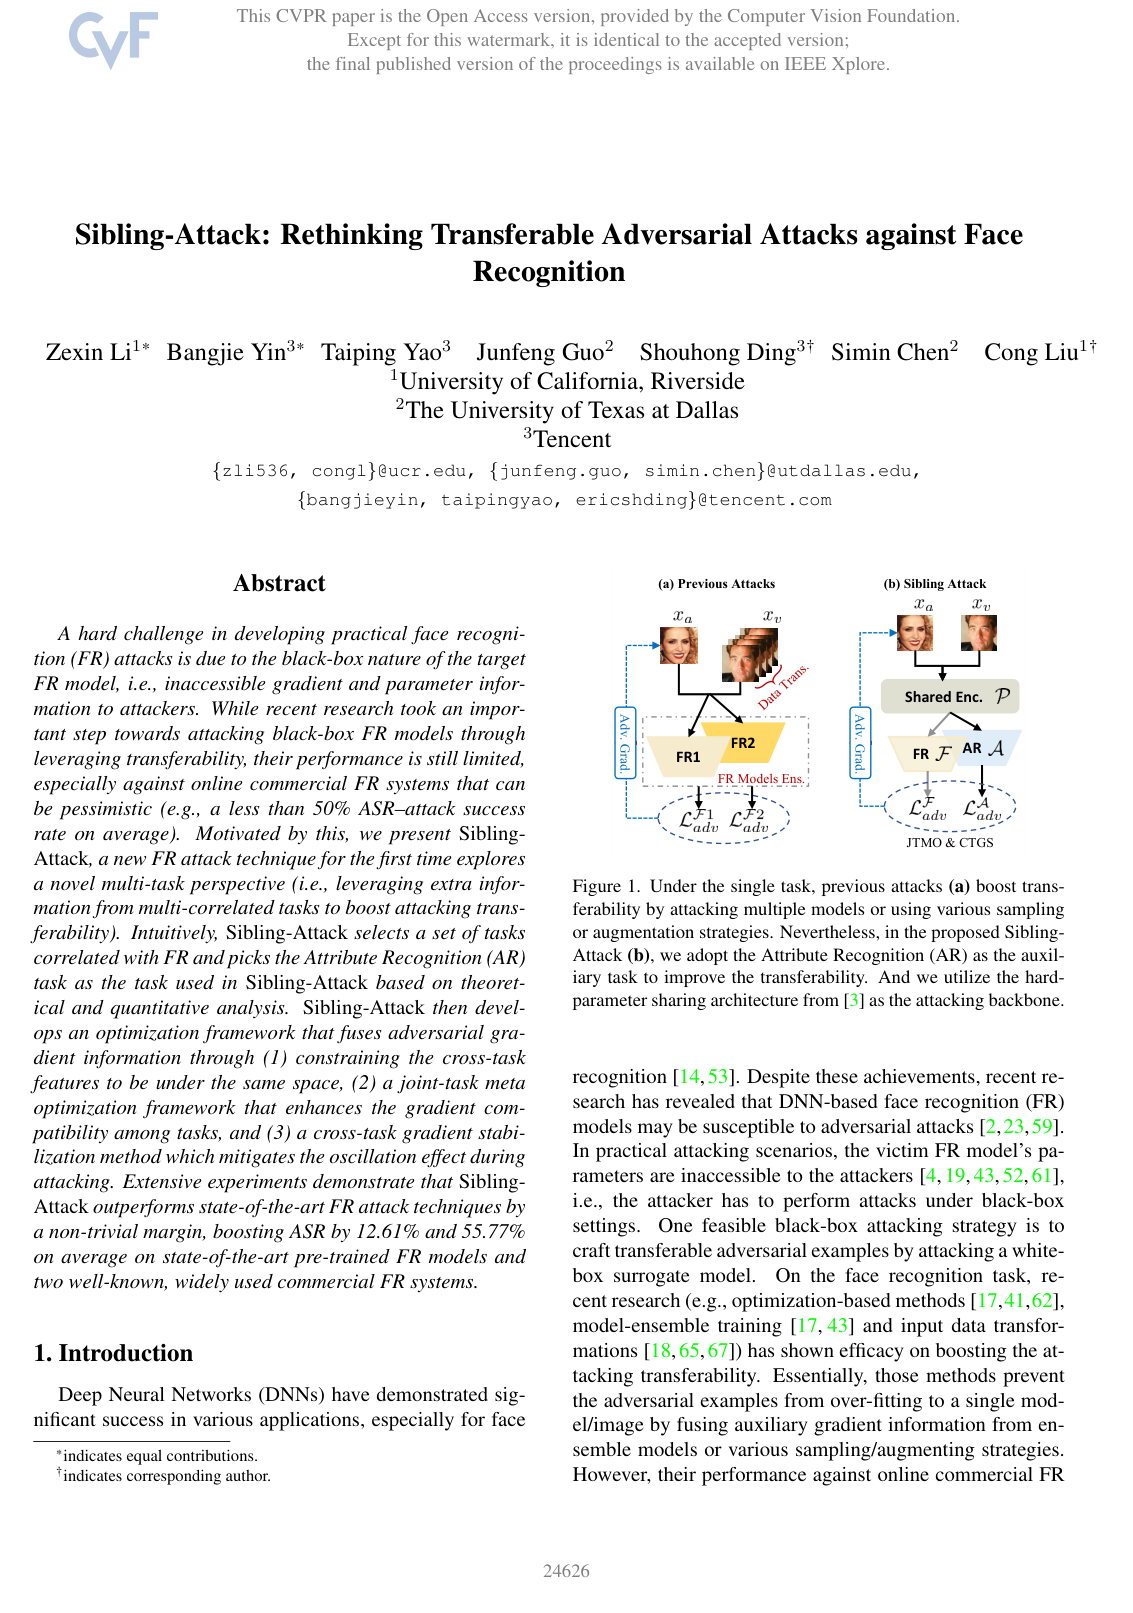
Sibling-Attack: Rethinking Transferable Adversarial Attacks against Face Recognition
Zexin Li, Bangjie Yin, Taiping Yao, Junfeng Guo, Shouhong Ding, Simin Chen, Cong Liu
Why you should read this
Proposes a multi-task adversarial framework that leverages gradient information from face attribute recognition to substantially improve black-box attack transferability against commercial face recognition systems.
A hard challenge in developing practical face recognition (FR) attacks is due to the black-box nature of the target FR model, i.e., inaccessible gradient and parameter information to attackers. While recent research took an important step towards attacking black-box FR models through leveraging transferability, their performance is still limited, especially against online commercial FR systems that can be pessimistic (e.g., a less than 50% ASR–attack success rate on average). Motivated by this, we present Sibling-Attack, a new FR attack technique for the first time explores a novel multi-task perspective (i.e., leveraging extra information from multi-correlated tasks to boost attacking transferability). Intuitively, Sibling-Attack selects a set of tasks correlated with FR and picks the Attribute Recognition (AR) task as the task used in Sibling-Attack based on theoretical and quantitative analysis. Sibling-Attack then develops an optimization framework that fuses adversarial gradient information through (1) constraining the cross-task features to be under the same space, (2) a joint-task meta optimization framework that enhances the gradient compatibility among tasks, and (3) a cross-task gradient stabilization method which mitigates the oscillation effect during attacking. Extensive experiments demonstrate that Sibling-Attack outperforms state-of-the-art FR attack techniques by a non-trivial margin, boosting ASR by 12.61% and 55.77% on average on state-of-the-art pre-trained FR models and two well-known, widely used commercial FR systems.
Added
2026-09-26
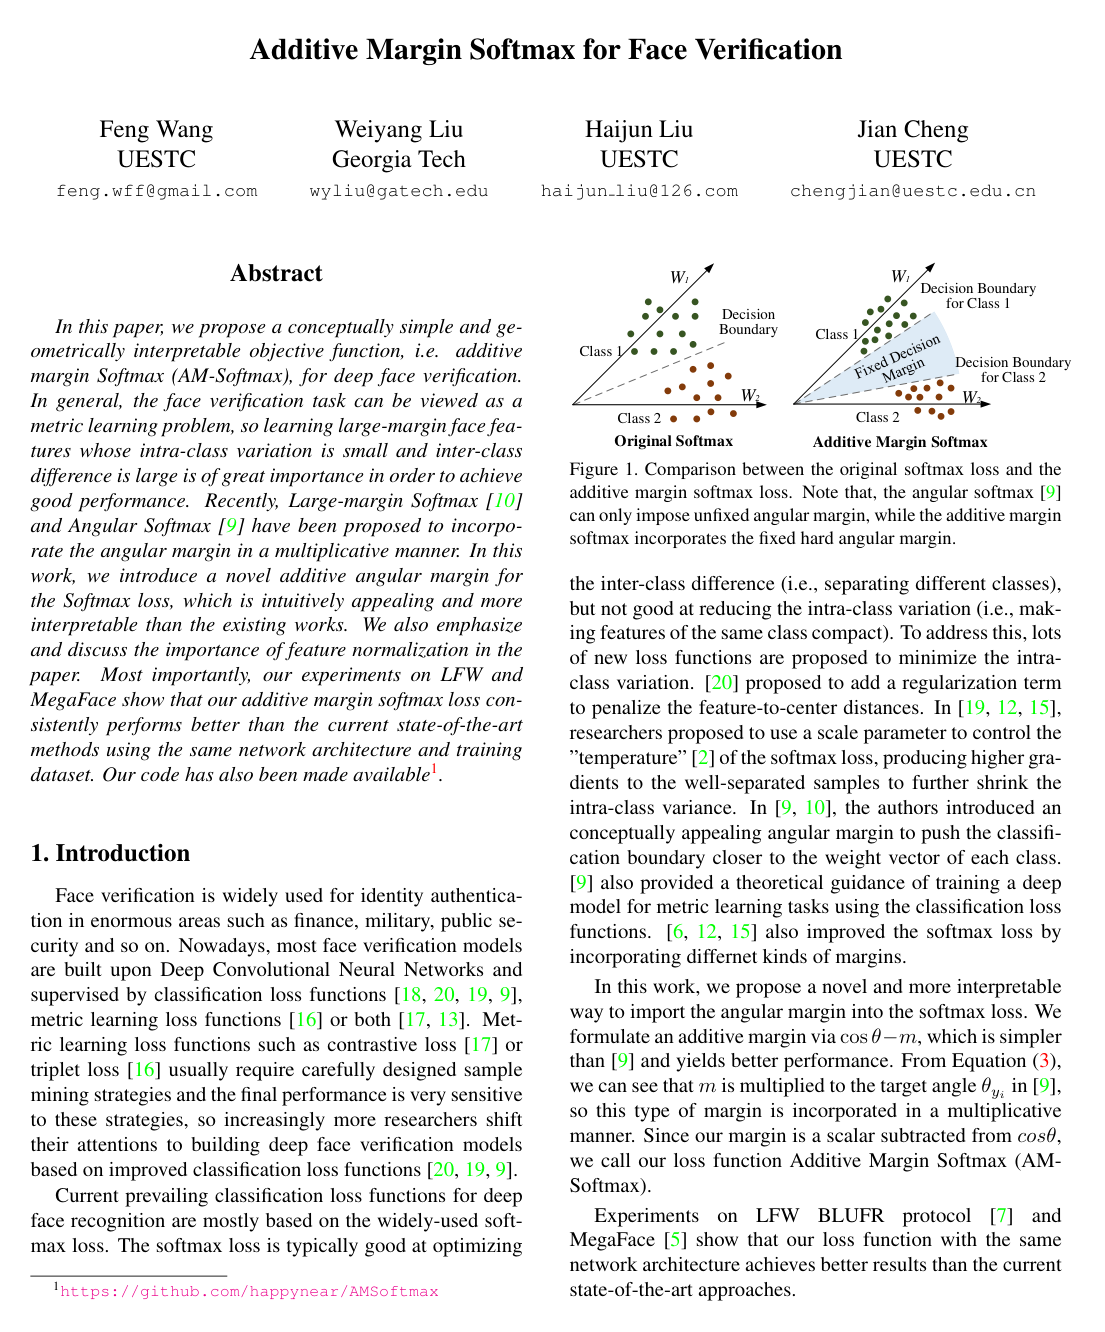
Additive Margin Softmax for Face Verification
Feng Wang, Jian Cheng, Weiyang Liu, Haijun Liu
Why you should read this
Proposes an additive margin Softmax loss function with feature normalization that simplifies angular margin learning and improves deep face verification accuracy on standard benchmarks such as MegaFace and LFW.
In this paper, we propose a conceptually simple and geometrically interpretable objective function, i.e. additive margin Softmax (AM-Softmax), for deep face verification. In general, the face verification task can be viewed as a metric learning problem, so learning large-margin face features whose intra-class variation is small and inter-class difference is large is of great importance in order to achieve good performance. Recently, Large-margin Softmax and Angular Softmax have been proposed to incorporate the angular margin in a multiplicative manner. In this work, we introduce a novel additive angular margin for the Softmax loss, which is intuitively appealing and more interpretable than the existing works. We also emphasize and discuss the importance of feature normalization in the paper. Most importantly, our experiments on LFW BLUFR and MegaFace show that our additive margin softmax loss consistently performs better than the current state-of-the-art methods using the same network architecture and training dataset. Our code has also been made available at this https URL
Added
2026-09-25
Deep Face Recognition: A Survey
Mei Wang, Weihong Deng
Why you should read this
Systematizes the rapid evolution of deep face recognition by organizing network architectures, loss functions, data processing strategies, and benchmark datasets to address technical challenges across diverse practical scenarios.
Deep learning applies multiple processing layers to learn representations of data with multiple levels of feature extraction. This emerging technique has reshaped the research landscape of face recognition (FR) since 2014, launched by the breakthroughs of DeepFace and DeepID. Since then, deep learning technique, characterized by the hierarchical architecture to stitch together pixels into invariant face representation, has dramatically improved the state-of-the-art performance and fostered successful real-world applications. In this survey, we provide a comprehensive review of the recent developments on deep FR, covering broad topics on algorithm designs, databases, protocols, and application scenes. First, we summarize different network architectures and loss functions proposed in the rapid evolution of the deep FR methods. Second, the related face processing methods are categorized into two classes: "one-to-many augmentation" and "many-to-one normalization". Then, we summarize and compare the commonly used databases for both model training and evaluation. Third, we review miscellaneous scenes in deep FR, such as cross-factor, heterogenous, multiple-media and industrial scenes. Finally, the technical challenges and several promising directions are highlighted.
Added
2026-09-25
Attribute and simile classifiers for face verification
Neeraj Kumar, A. Berg, P. Belhumeur, S. Nayar
Why you should read this
Proposes novel attribute and simile classifiers that capture high-level visual traits and reference similarities, dramatically cutting face verification error rates on unconstrained benchmarks without requiring image pair alignment.
We present two novel methods for face verification. Our first method – “attribute” classifiers – uses binary classifiers trained to recognize the presence or absence of describable aspects of visual appearance (e.g., gender, race, and age). Our second method – “simile” classifiers – removes the manual labeling required for attribute classification and instead learns the similarity of faces, or regions of faces, to specific reference people. Neither method requires costly, often brittle, alignment between image pairs; yet, both methods produce compact visual descriptions, and work on real-world images. Furthermore, both the attribute and simile classifiers improve on the current state-of-the-art for the LFW data set, reducing the error rates compared to the current best by 23.92% and 26.34%, respectively, and 31.68% when combined. For further testing across pose, illumination, and expression, we introduce a new data set – termed PubFig – of real-world images of public figures (celebrities and politicians) acquired from the internet. This data set is both larger (60,000 images) and deeper (300 images per individual) than existing data sets of its kind. Finally, we present an evaluation of human performance.
Added
2026-09-24
Learning Face Representation from Scratch
Dong Yi, Zhen Lei, Shengcai Liao, Stan Z. Li
Why you should read this
Introduces CASIA-WebFace, a publicly accessible dataset of 500,000 images across 10,000 identities, alongside a deep neural network architecture that allows researchers to train competitive face recognition models without relying on proprietary industrial data.
Pushing by big data and deep convolutional neural network (CNN), the performance of face recognition is becoming comparable to human. Using private large scale training datasets, several groups achieve very high performance on LFW, i.e., 97% to 99%. While there are many open source implementations of CNN, none of large scale face dataset is publicly available. The current situation in the field of face recognition is that data is more important than algorithm. To solve this problem, this paper proposes a semi-automatical way to collect face images from Internet and builds a large scale dataset containing about 10,000 subjects and 500,000 images, called CASIAWebFace. Based on the database, we use a 11-layer CNN to learn discriminative representation and obtain state-of-theart accuracy on LFW and YTF. The publication of CASIAWebFace will attract more research groups entering this field and accelerate the development of face recognition in the wild.
Added
2026-09-16
MS-Celeb-1M: A Dataset and Benchmark for Large-Scale Face Recognition
Yandong Guo, Lei Zhang, Yuxiao Hu, Xiaodong He, Jianfeng Gao
Why you should read this
Introduces MS-Celeb-1M, a dataset of ten million images spanning one million celebrities linked to a knowledge base, providing the scale and evaluation protocol needed to train and benchmark real-world face recognition models.
In this paper, we design a benchmark task and provide the associated datasets for recognizing face images and link them to corresponding entity keys in a knowledge base. More specifically, we propose a benchmark task to recognize one million celebrities from their face images, by using all the possibly collected face images of this individual on the web as training data. The rich information provided by the knowledge base helps to conduct disambiguation and improve the recognition accuracy, and contributes to various real-world applications, such as image captioning and news video analysis. Associated with this task, we design and provide concrete measurement set, evaluation protocol, as well as training data. We also present in details our experiment setup and report promising baseline results. Our benchmark task could lead to one of the largest classification problems in computer vision. To the best of our knowledge, our training dataset, which contains 10M images in version 1, is the largest publicly available one in the world.
Added
2026-09-16
Deep Learning Face Representation by Joint Identification-Verification
Yi Sun, Yuheng Chen, Xiaogang Wang, Xiaoou Tang
Why you should read this
Introduces DeepID2, a deep learning approach that jointly optimizes identification and verification supervisory signals to simultaneously minimize intra-identity variation and enlarge inter-identity differences, reducing error rates on the LFW benchmark by 67%.
The key challenge of face recognition is to develop effective feature representations for reducing intra-personal variations while enlarging inter-personal differences. In this paper, we show that it can be well solved with deep learning and using both face identification and verification signals as supervision. The Deep IDentification-verification features (DeepID2) are learned with carefully designed deep convolutional networks. The face identification task increases the inter-personal variations by drawing DeepID2 extracted from different identities apart, while the face verification task reduces the intra-personal variations by pulling DeepID2 extracted from the same identity together, both of which are essential to face recognition. The learned DeepID2 features can be well generalized to new identities unseen in the training data. On the challenging LFW dataset, 99.15% face verification accuracy is achieved. Compared with the best deep learning result on LFW, the error rate has been significantly reduced by 67%.
Added
2026-09-15
CosFace: Large Margin Cosine Loss for Deep Face Recognition
Hao Wang, Yitong Wang, Zheng Zhou, Xing Ji, Dihong Gong, Jingchao Zhou, Zhifeng Li, Wei Liu
Why you should read this
Introduces the Large Margin Cosine Loss (CosFace), which reformulates traditional softmax loss through vector normalization and an angular margin penalty to maximize feature discrimination for deep face recognition.
Face recognition has made extraordinary progress owing to the advancement of deep convolutional neural networks (CNNs). The central task of face recognition, including face verification and identification, involves face feature discrimination. However, the traditional softmax loss of deep CNNs usually lacks the power of discrimination. To address this problem, recently several loss functions such as center loss, large margin softmax loss, and angular softmax loss have been proposed. All these improved losses share the same idea: maximizing inter-class variance and minimizing intra-class variance. In this paper, we propose a novel loss function, namely large margin cosine loss (LMCL), to realize this idea from a different perspective. More specifically, we reformulate the softmax loss as a cosine loss by normalizing both features and weight vectors to remove radial variations, based on which a cosine margin term is introduced to further maximize the decision margin in the angular space. As a result, minimum intra-class variance and maximum inter-class variance are achieved by virtue of normalization and cosine decision margin maximization. We refer to our model trained with LMCL as CosFace. Extensive experimental evaluations are conducted on the most popular public-domain face recognition datasets such as MegaFace Challenge, Youtube Faces (YTF) and Labeled Face in the Wild (LFW). We achieve the state-of-the-art performance on these benchmarks, which confirms the effectiveness of our proposed approach.
Added
2026-09-13
VGGFace2: A Dataset for Recognising Faces across Pose and Age
Qiong Cao, Li Shen, Weidi Xie, Omkar M. Parkhi, Andrew Zisserman
Why you should read this
Introduces VGGFace2, a large-scale dataset of 3.31 million images across 9,131 identities designed to train deep neural networks across wide variations in pose and age, achieving state-of-the-art accuracy on the IARPA Janus benchmarks.
In this paper, we introduce a new large-scale face dataset named VGGFace2. The dataset contains 3.31 million images of 9131 subjects, with an average of 362.6 images for each subject. Images are downloaded from Google Image Search and have large variations in pose, age, illumination, ethnicity and profession (e.g. actors, athletes, politicians). The dataset was collected with three goals in mind: (i) to have both a large number of identities and also a large number of images for each identity; (ii) to cover a large range of pose, age and ethnicity; and (iii) to minimize the label noise. We describe how the dataset was collected, in particular the automated and manual filtering stages to ensure a high accuracy for the images of each identity. To assess face recognition performance using the new dataset, we train ResNet-50 (with and without Squeeze-and-Excitation blocks) Convolutional Neural Networks on VGGFace2, on MS- Celeb-1M, and on their union, and show that training on VGGFace2 leads to improved recognition performance over pose and age. Finally, using the models trained on these datasets, we demonstrate state-of-the-art performance on all the IARPA Janus face recognition benchmarks, e.g. IJB-A, IJB-B and IJB-C, exceeding the previous state-of-the-art by a large margin. Datasets and models are publicly available.
Added
2026-09-12

SphereFace: Deep Hypersphere Embedding for Face Recognition
Weiyang Liu, Yandong Wen, Zhiding Yu, Ming Li, Bhiksha Raj, Le Song
Why you should read this
Introduces the angular softmax loss to enforce adjustable angular margins on hypersphere embeddings, establishing a geometric formulation for learning highly discriminative features in open-set face recognition.
This paper addresses deep face recognition (FR) problem under open-set protocol, where ideal face features are expected to have smaller maximal intra-class distance than minimal inter-class distance under a suitably chosen metric space. However, few existing algorithms can effectively achieve this criterion. To this end, we propose the angular softmax (A-Softmax) loss that enables convolutional neural networks (CNNs) to learn angularly discriminative features. Geometrically, A-Softmax loss can be viewed as imposing discriminative constraints on a hypersphere manifold, which intrinsically matches the prior that faces also lie on a manifold. Moreover, the size of angular margin can be quantitatively adjusted by a parameter . We further derive specific to approximate the ideal feature criterion. Extensive analysis and experiments on Labeled Face in the Wild (LFW), Youtube Faces (YTF) and MegaFace Challenge show the superiority of A-Softmax loss in FR tasks. The code has also been made publicly available.
Added
2026-09-12
A Discriminative Feature Learning Approach for Deep Face Recognition
Yandong Wen, Kaipeng Zhang, Zhifeng Li, Yu Qiao
Why you should read this
Proposes center loss, an easily optimizable supervision function that penalizes distances between deep features and their learned class centers to minimize intra-class variance alongside softmax loss, achieving state-of-the-art face recognition accuracy without complex sample-pair mining.
Convolutional neural networks (CNNs) have been widely used in computer vision community, significantly improving the state-of-the-art. In most of the available CNNs, the softmax loss function is used as the supervision signal to train the deep model. In order to enhance the discriminative power of the deeply learned features, this paper proposes a new supervision signal, called center loss, for face recognition task. Specifically, the center loss simultaneously learns a center for deep features of each class and penalizes the distances between the deep features and their corresponding class centers. More importantly, we prove that the proposed center loss function is trainable and easy to optimize in the CNNs. With the joint supervision of softmax loss and center loss, we can train a robust CNNs to obtain the deep features with the two key learning objectives, inter-class dispension and intra-class compactness as much as possible, which are very essential to face recognition. It is encouraging to see that our CNNs (with such joint supervision) achieve the state-of-the-art accuracy on several important face recognition benchmarks, Labeled Faces in the Wild (LFW), YouTube Faces (YTF), and MegaFace Challenge. Especially, our new approach achieves the best results on MegaFace (the largest public domain face benchmark) under the protocol of small training set (contains under 500000 images and under 20000 persons), significantly improving the previous results and setting new state-of-the-art for both face recognition and face verification tasks.
Added
2026-09-11
Learning a similarity metric discriminatively, with application to face verification
Sumit Chopra, Raia Hadsell, Yann LeCun
Why you should read this
Proposes a discriminative metric learning method using convolutional neural networks to map images into a semantic distance space, enabling effective face verification across extreme variations in lighting, pose, and occlusion when training data per subject is scarce.
We present a method for training a similarity metric from data. The method can be used for recognition or verification applications where the number of categories is very large and not known during training, and where the number of training samples for a single category is very small. The idea is to learn a function that maps input patterns into a target space such that the L1 norm in the target space approximates the “semantic” distance in the input space. The method is applied to a face verification task. The learning process minimizes a discriminative loss function that drives the similarity metric to be small for pairs of faces from the same person, and large for pairs from different persons. The mapping from raw to the target space is a convolutional network whose architecture is designed for robustness to geometric distortions. The system is tested on the Purdue/AR face database which has a very high degree of variability in the pose, lighting, expression, position, and artificial occlusions such as dark glasses and obscuring scarves.
Added
2026-09-10
Deep Face Recognition
Omkar M. Parkhi, Andrea Vedaldi, Andrew Zisserman
Why you should read this
Presents a practical pipeline for building a 2.6-million-image dataset alongside training strategies that enable deep convolutional networks to achieve state-of-the-art face recognition accuracy on the LFW and YTF benchmarks.
The goal of this paper is face recognition – from either a single photograph or from a set of faces tracked in a video. Recent progress in this area has been due to two factors: (i) end to end learning for the task using a convolutional neural network (CNN), and (ii) the availability of very large scale training datasets. We make two contributions: first, we show how a very large scale dataset (2.6M images, over 2.6K people) can be assembled by a combination of automation and human in the loop, and discuss the trade off between data purity and time; second, we traverse through the complexities of deep network training and face recognition to present methods and procedures to achieve comparable state of the art results on the standard LFW and YTF face benchmarks.
Added
2026-09-09
ArcFace: Additive Angular Margin Loss for Deep Face Recognition
Jiankang Deng, J. Guo, Stefanos Zafeiriou
Why you should read this
Proposes an additive angular margin loss that enforces geometric constraints on feature embeddings to maximize class separability in face recognition, effectively isolate training noise, and generate identity-preserving faces without extra models.
Recently, a popular line of research in face recognition is adopting margins in the well-established softmax loss function to maximize class separability. In this paper, we first introduce an Additive Angular Margin Loss (ArcFace), which not only has a clear geometric interpretation but also significantly enhances the discriminative power. Since ArcFace is susceptible to the massive label noise, we further propose sub-center ArcFace, in which each class contains sub-centers and training samples only need to be close to any of the positive sub-centers. Sub-center ArcFace encourages one dominant sub-class that contains the majority of clean faces and non-dominant sub-classes that include hard or noisy faces. Based on this self-propelled isolation, we boost the performance through automatically purifying raw web faces under massive real-world noise. Besides discriminative feature embedding, we also explore the inverse problem, mapping feature vectors to face images. Without training any additional generator or discriminator, the pre-trained ArcFace model can generate identity-preserved face images for both subjects inside and outside the training data only by using the network gradient and Batch Normalization (BN) priors. Extensive experiments demonstrate that ArcFace can enhance the discriminative feature embedding as well as strengthen the generative face synthesis.
Added
2026-09-07
Deep Learning Face Attributes in the Wild
Ziwei Liu, Ping Luo, Xiaogang Wang, Xiaoou Tang
Why you should read this
Develops a cascaded deep convolutional framework that accurately predicts facial attributes in unconstrained images by learning to localize faces using only image-level tags without bounding box or landmark annotations.
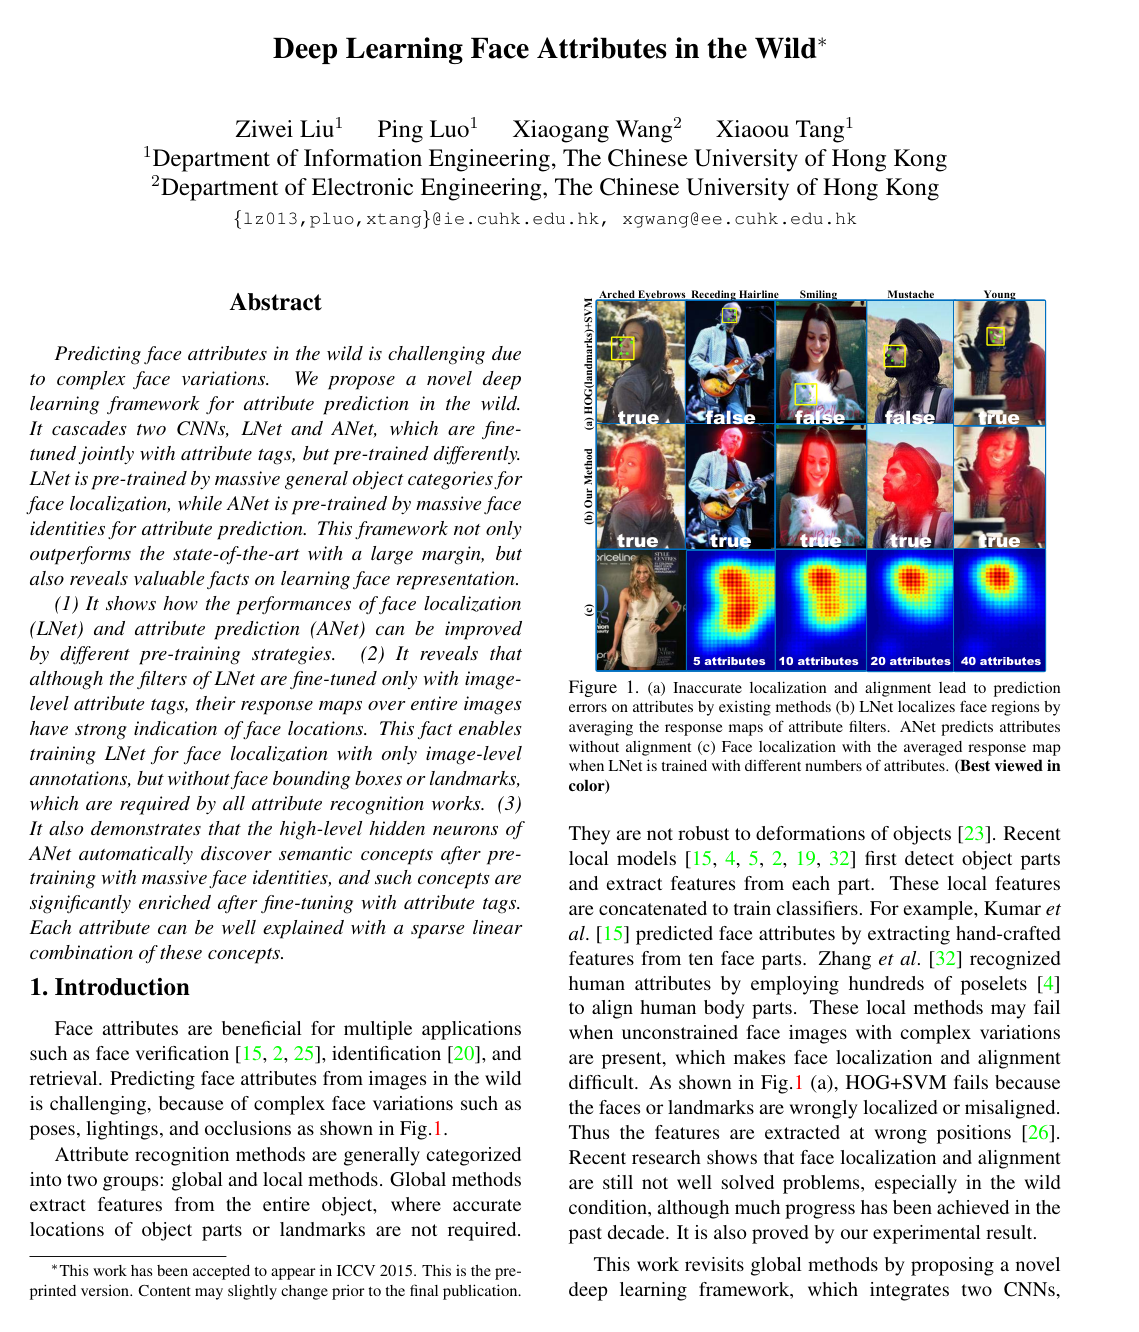
Predicting face attributes in the wild is challenging due to complex face variations. We propose a novel deep learning framework for attribute prediction in the wild. It cascades two CNNs, LNet and ANet, which are fine-tuned jointly with attribute tags, but pre-trained differently. LNet is pre-trained by massive general object categories for face localization, while ANet is pre-trained by massive face identities for attribute prediction. This framework not only outperforms the state-of-the-art with a large margin, but also reveals valuable facts on learning face representation. (1) It shows how the performances of face localization (LNet) and attribute prediction (ANet) can be improved by different pre-training strategies. (2) It reveals that although the filters of LNet are fine-tuned only with image-level attribute tags, their response maps over entire images have strong indication of face locations. This fact enables training LNet for face localization with only image-level annotations, but without face bounding boxes or landmarks, which are required by all attribute recognition works. (3) It also demonstrates that the high-level hidden neurons of ANet automatically discover semantic concepts after pre-training with massive face identities, and such concepts are significantly enriched after fine-tuning with attribute tags. Each attribute can be well explained with a sparse linear combination of these concepts.
Added
2026-09-07
FaceNet: A unified embedding for face recognition and clustering
Florian Schroff, Dmitry Kalenichenko, James Philbin
Why you should read this
Introduces a deep neural network that trains directly on face image triplets to produce compact 128-dimensional embeddings, setting benchmark accuracy records while unifying face verification, recognition, and clustering within a single Euclidean space.
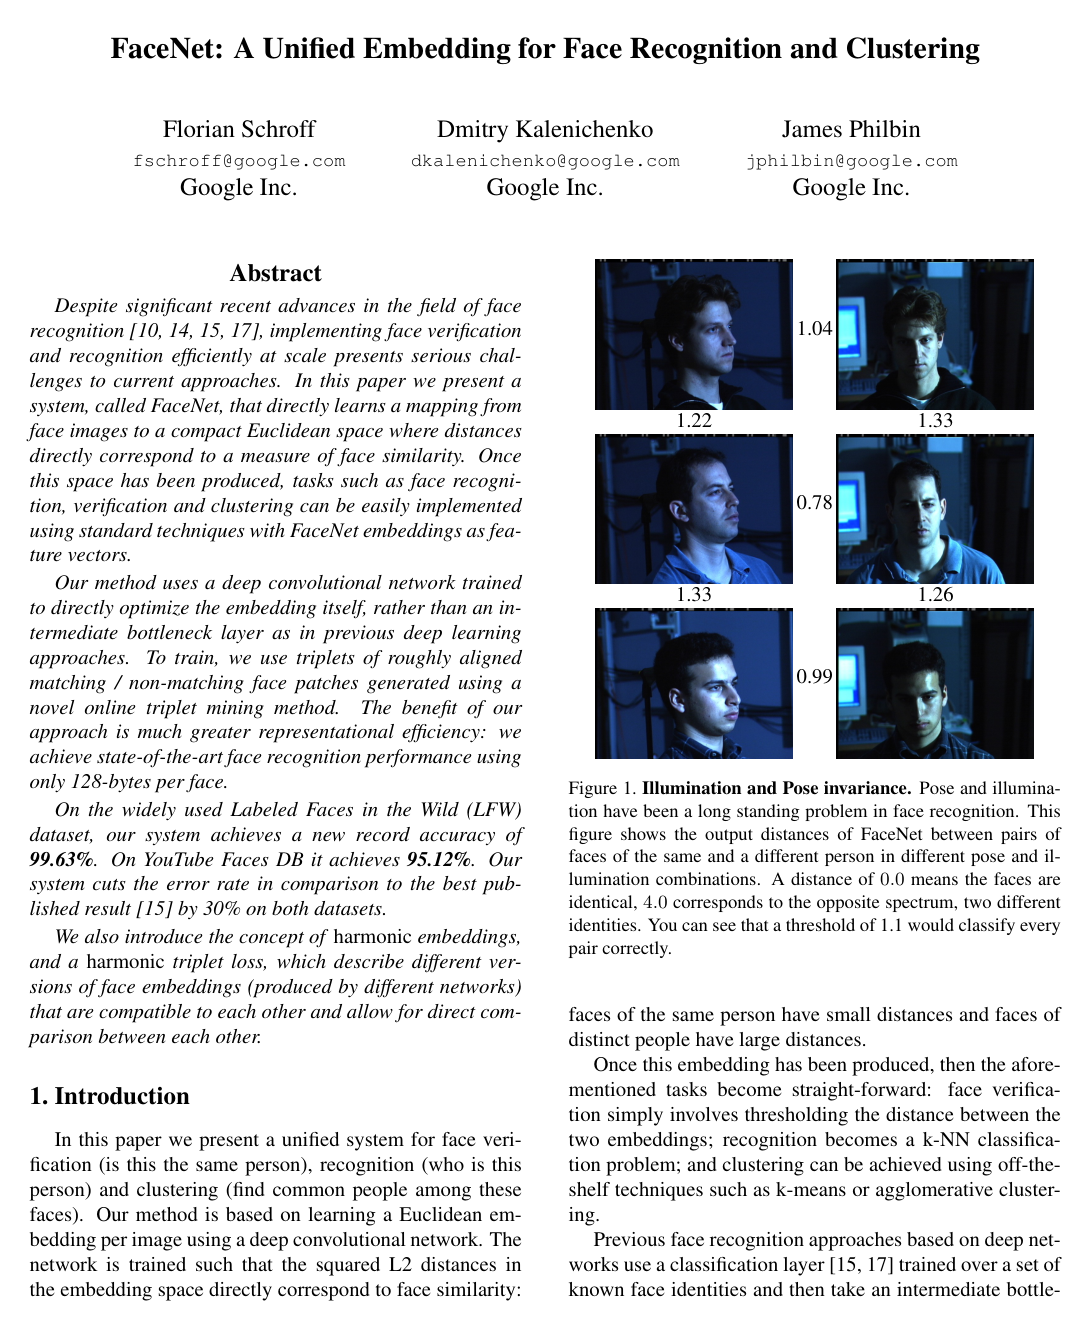
Despite significant recent advances in the field of face recognition, implementing face verification and recognition efficiently at scale presents serious challenges to current approaches. In this paper we present a system, called FaceNet, that directly learns a mapping from face images to a compact Euclidean space where distances directly correspond to a measure of face similarity. Once this space has been produced, tasks such as face recognition, verification and clustering can be easily implemented using standard techniques with FaceNet embeddings as feature vectors. Our method uses a deep convolutional network trained to directly optimize the embedding itself, rather than an intermediate bottleneck layer as in previous deep learning approaches. To train, we use triplets of roughly aligned matching / non-matching face patches generated using a novel online triplet mining method. The benefit of our approach is much greater representational efficiency: we achieve state-of-the-art face recognition performance using only 128-bytes per face. On the widely used Labeled Faces in the Wild (LFW) dataset, our system achieves a new record accuracy of 99.63%. On YouTube Faces DB it achieves 95.12%. Our system cuts the error rate in comparison to the best published result by 30% on both datasets. We also introduce the concept of harmonic embeddings, and a harmonic triplet loss, which describe different versions of face embeddings (produced by different networks) that are compatible to each other and allow for direct comparison between each other.
Added
2026-09-05