
topic
hardware resources
Hardware resources refer to the physical and electronic components of a computing system or device that provide the essential capabilities needed to execute software and process data. These resources primarily encompass processing units such as central processing units and graphics processing units, volatile system memory, persistent storage drives, input and output interfaces, and specialized circuit components. System software, such as operating systems, hypervisors, and firmware, manages and allocates these physical assets among running processes to optimize performance, maintain stability, and prevent conflicts. In both general-purpose computers and specialized embedded systems, the capacity, allocation, and constraints of available hardware resources directly determine computational throughput, energy efficiency, and operational limits.
5 items
An Efficient Memory-Augmented Transformer for Knowledge-Intensive NLP Tasks
Yuxiang Wu, Yu Zhao, Baotian Hu, Pasquale Minervini, Pontus Stenetorp, Sebastian Riedel
Why you should read this
Proposes an efficient memory-augmented transformer that stores external question-answer knowledge in a fast key-value memory queried during a single forward pass, matching or exceeding the accuracy of retrieval-augmented models on open-domain NLP benchmarks while processing up to a thousand queries per second.
Access to external knowledge is essential for many natural language processing tasks, such as question answering and dialogue. Existing methods often rely on a parametric model that stores knowledge in its parameters, or use a retrieval-augmented model that has access to an external knowledge source. Parametric and retrieval-augmented models have complementary strengths in terms of computational efficiency and predictive accuracy. To combine the strength of both approaches, we propose the Efficient Memory-Augmented Transformer (EMAT) – it encodes external knowledge into a key-value memory and exploits the fast maximum inner product search for memory querying. We also introduce pre-training tasks that allow EMAT to encode informative key-value representations, and to learn an implicit strategy to integrate multiple memory slots into the transformer. Experiments on various knowledge-intensive tasks such as question answering and dialogue datasets show that, simply augmenting parametric models (T5-base) using our method produces more accurate results (e.g., 25.8 → 44.3 EM on NQ) while retaining a high throughput (e.g., 1000 queries/s on NQ). Compared to retrieval-augmented models, EMAT runs substantially faster across the board and produces more accurate results on WoW and ELI5.
Added
2026-10-03
Memory resource management in VMware ESX server
Carl A. Waldspurger
Why you should read this
Presents foundational memory virtualization techniques, including memory ballooning, content-based page sharing, and an idle memory tax, that enable hypervisors to safely and efficiently overcommit physical memory across unmodified guest operating systems.
VMware ESX Server is a thin software layer designed to multiplex hardware resources efficiently among virtual machines running unmodified commodity operating systems. This paper introduces several novel ESX Server mechanisms and policies for managing memory. A ballooning technique reclaims the pages considered least valuable by the operating system running in a virtual machine. An idle memory tax achieves efficient memory utilization while maintaining performance isolation guarantees. Content-based page sharing and hot I/O page remapping exploit transparent page remapping to eliminate redundancy and reduce copying overheads. These techniques are combined to efficiently support virtual machine workloads that overcommit memory.
Added
2026-09-25
Exokernel: an operating system architecture for application-level resource management
D. Engler, M. Kaashoek, James O'Tool, Jeffrey J. Weston
Why you should read this
Proposes a minimalist operating system architecture that safely delegates hardware management to untrusted library operating systems, enabling applications to customize low-level resource abstractions and achieve order-of-magnitude performance gains over monolithic kernels.
We describe an operating system architecture that securely multiplexes machine resources while permitting an unprecedented degree of application-specific customization of traditional operating system abstractions. By abstracting physical hardware resources, traditional operating systems have significantly limited the performance, flexibility, and functionality of applications. The exokernel architecture removes these limitations by allowing untrusted software to implement traditional operating system abstractions entirely at application-level. We have implemented a prototype exokernel-based system that includes Aegis, an exokernel, and ExOS, an untrusted application-level operating system. Aegis defines the low-level interface to machine resources. Applications can allocate and use machine resources, efficiently handle events, and participate in resource revocation. Measurements show that most primitive Aegis operations are 10–100 times faster than Ultrix, a mature monolithic UNIX operating system. ExOS implements processes, virtual memory, and inter-process communication abstractions entirely within a library. Measurements show that ExOS's application-level virtual memory and IPC primitives are 5–50 times faster than Ultrix's primitives. These results demonstrate that the exokernel operating system design is practical and offers an excellent combination of performance and flexibility.
Added
2026-09-24
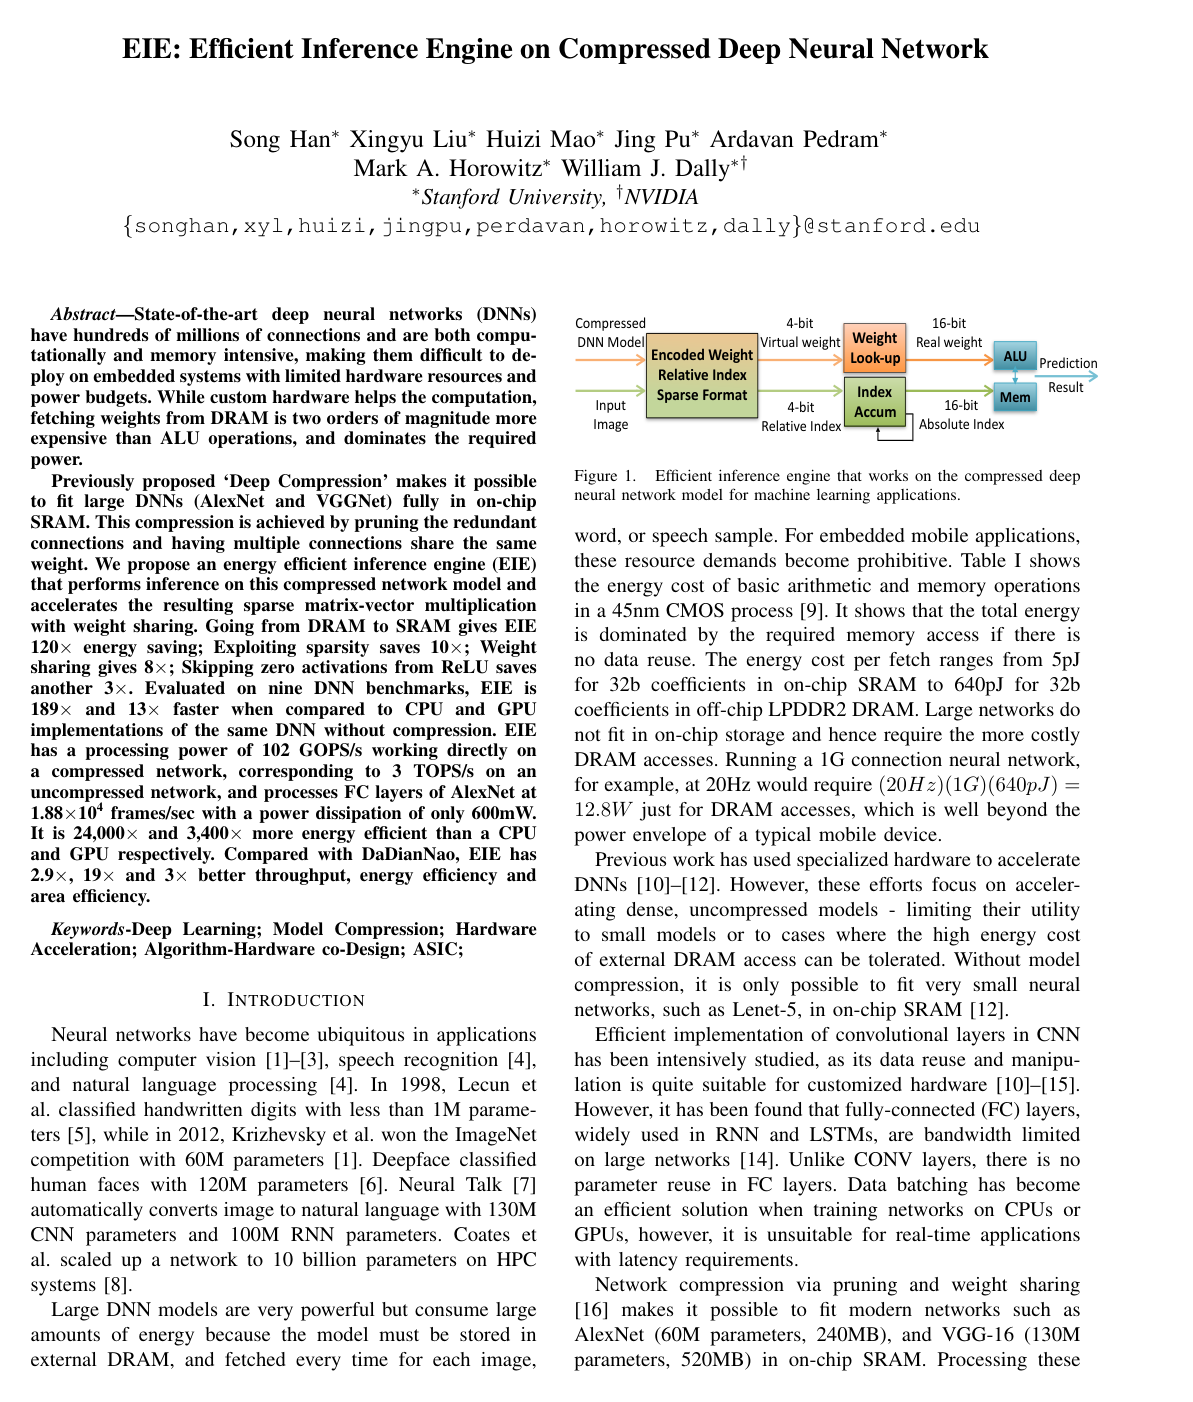
EIE: Efficient Inference Engine on Compressed Deep Neural Network
Song Han, Xingyu Liu, Huizi Mao, Jing Pu, Ardavan Pedram, Mark A. Horowitz, William J. Dally
Why you should read this
Presents a specialized hardware accelerator designed to execute inference directly on compressed, sparse neural networks in on-chip SRAM, eliminating costly DRAM transfers to achieve thousands-fold gains in energy efficiency over conventional processors.
State-of-the-art deep neural networks (DNNs) have hundreds of millions of connections and are both computationally and memory intensive, making them difficult to deploy on embedded systems with limited hardware resources and power budgets. While custom hardware helps the computation, fetching weights from DRAM is two orders of magnitude more expensive than ALU operations, and dominates the required power. Previously proposed 'Deep Compression' makes it possible to fit large DNNs (AlexNet and VGGNet) fully in on-chip SRAM. This compression is achieved by pruning the redundant connections and having multiple connections share the same weight. We propose an energy efficient inference engine (EIE) that performs inference on this compressed network model and accelerates the resulting sparse matrix-vector multiplication with weight sharing. Going from DRAM to SRAM gives EIE 120x energy saving; Exploiting sparsity saves 10x; Weight sharing gives 8x; Skipping zero activations from ReLU saves another 3x. Evaluated on nine DNN benchmarks, EIE is 189x and 13x faster when compared to CPU and GPU implementations of the same DNN without compression. EIE has a processing power of 102GOPS/s working directly on a compressed network, corresponding to 3TOPS/s on an uncompressed network, and processes FC layers of AlexNet at 1.88x10^4 frames/sec with a power dissipation of only 600mW. It is 24,000x and 3,400x more energy efficient than a CPU and GPU respectively. Compared with DaDianNao, EIE has 2.9x, 19x and 3x better throughput, energy efficiency and area efficiency.
Added
2026-09-14
Deep Compression: Compressing Deep Neural Network with Pruning, Trained Quantization and Huffman Coding
Song Han, Huizi Mao, William J. Dally
Why you should read this
Introduces a three-stage pipeline combining weight pruning, trained quantization, and Huffman coding that reduces deep neural network sizes by up to 49x without losing accuracy, enabling fast, energy-efficient inference on resource-constrained devices.
Neural networks are both computationally intensive and memory intensive, making them difficult to deploy on embedded systems with limited hardware resources. To address this limitation, we introduce "deep compression", a three stage pipeline: pruning, trained quantization and Huffman coding, that work together to reduce the storage requirement of neural networks by 35x to 49x without affecting their accuracy. Our method first prunes the network by learning only the important connections. Next, we quantize the weights to enforce weight sharing, finally, we apply Huffman coding. After the first two steps we retrain the network to fine tune the remaining connections and the quantized centroids. Pruning, reduces the number of connections by 9x to 13x; Quantization then reduces the number of bits that represent each connection from 32 to 5. On the ImageNet dataset, our method reduced the storage required by AlexNet by 35x, from 240MB to 6.9MB, without loss of accuracy. Our method reduced the size of VGG-16 by 49x from 552MB to 11.3MB, again with no loss of accuracy. This allows fitting the model into on-chip SRAM cache rather than off-chip DRAM memory. Our compression method also facilitates the use of complex neural networks in mobile applications where application size and download bandwidth are constrained. Benchmarked on CPU, GPU and mobile GPU, compressed network has 3x to 4x layerwise speedup and 3x to 7x better energy efficiency.
Added
2026-09-07