MOT16: A Benchmark for Multi-Object Tracking

Anton MilanLaura Leal-TaixeIan ReidStefan RothKonrad Schindler

article2016arXiv2,154 citations

Presents the MOT16 benchmark, establishing a standardized evaluation framework for multi-object tracking with consistently annotated video sequences, multiple object classes, and per-target visibility data.

Listen

Tracking multiple moving objects in video is critical for computer vision applications such as autonomous driving and surveillance. However, the field has long struggled with inconsistent performance evaluation due to a lack of standard datasets, variable evaluation protocols, and ambiguous ground truth definitions. Earlier benchmarks suffered from limited crowd densities, inconsistent annotations, and easy scenarios that encouraged models to overfit. The article introduces MOT16, a standardized, large-scale benchmark designed to establish a rigorous, centralized framework for fairly evaluating multi-object tracking methods.

To create the benchmark, the researchers compiled 14 video sequences split evenly into training and testing sets, covering diverse viewpoints, moving and static cameras, and varying lighting and weather conditions. Compared to its predecessor, MOT16 features a threefold increase in bounding box density and contains nearly 300,000 pedestrian annotations alongside labels for vehicles, occluders, and distractors. Strict, unified annotation protocols were enforced from scratch by qualified researchers, and visibility ratios were calculated automatically. To eliminate detection quality as a confounding variable, standard precomputed detections were provided using a high-performing pedestrian detector. Five representative baseline tracking methods were tested under uniform parameters on the hidden test set.

Across the baseline tracker evaluations, the best-performing methods achieved Multiple Object Tracking Accuracy (MOTA) scores between roughly 26% and 34%, with significant performance volatility across sequences (standard deviations around 6% to 10%). While localization precision remained consistent at around 75% to 77% across algorithms, missing targets proved to be the dominant source of error, generating over 100,000 false negatives per method. Track persistence was similarly constrained: only 4% to 8% of trajectories were mostly tracked, while 48% to 68% were mostly lost. Faster methods, such as network flow tracking, achieved processing speeds over 200 Hz but exhibited trade-offs in identity switches and missed targets.

These findings demonstrate that multi-target tracking in dense, unconstrained environments remains an open challenge where real-world operational reliability cannot yet be assumed. The results reveal that high performance on previous, simpler benchmarks was largely an artifact of overfitting and unstandardized test conditions. Standardized evaluation is essential to de-risk technology selection for critical systems. Organizations and researchers developing tracking systems should adopt MOT16's centralized evaluation protocol and focus development on data association under heavy occlusion rather than tuning to narrow datasets. Future work highlighted in the article includes expanding the benchmark framework to specialized domains such as biomedical cell tracking and sports analytics.

arXiv: 1603.00831
  • Paper: Pedestrian Detection: An Evaluation of the State of the Art, Piotr Dollár et al. (2012). This paper establishes foundational standardized evaluation protocols and benchmark methodologies for pedestrian detection, which MOT16 directly builds upon for multi-object pedestrian tracking.
  • Paper: Object Tracking Benchmark, Yi Wu et al. (2015). It provides the foundational benchmarking framework, standardized protocols, and performance analysis conventions in visual tracking that influenced the design and structure of MOTChallenge benchmarks.
  • Paper: Histograms of Oriented Gradients for Human Detection, Navneet Dalal et al. (2005). This work introduces the classic pedestrian detection formulation and baseline features that underpin standard detection-based inputs used in multi-object tracking benchmarks.
  • Paper: The Pascal Visual Object Classes Challenge: A Retrospective, M. Everingham et al. (2014). It outlines the standardized benchmark design principles and annotation practices for visual recognition challenges that serve as essential background for standardized vision evaluation suites.
Cover for MOT16: A Benchmark for Multi-Object Tracking

Abstract

Standardized benchmarks are crucial for the majority of computer vision applications. Although leaderboards and ranking tables should not be over-claimed, benchmarks often provide the most objective measure of performance and are therefore important guides for reseach.

Recently, a new benchmark for Multiple Object Tracking, MOTChallenge, was launched with the goal of collecting existing and new data and creating a framework for the standardized evaluation of multiple object tracking methods. The first release of the benchmark focuses on multiple people tracking, since pedestrians are by far the most studied object in the tracking community. This paper accompanies a new release of the MOTChallenge benchmark. Unlike the initial release, all videos of MOT16 have been carefully annotated following a consistent protocol. Moreover, it not only offers a significant increase in the number of labeled boxes, but also provides multiple object classes beside pedestrians and the level of visibility for every single object of interest.

Table of Contents

  • I Introduction
  • I-A Related work
  • II Annotation rules
  • II-A Target class
  • II-B Bounding box alignment
  • II-C Start and end of trajectories
  • II-D Minimal size
  • II-E Occlusions
  • II-F Sanity check
  • III Datasets
  • III-A 2D MOT 2016 sequences
  • III-B Detections
  • III-C Data format
  • IV Evaluation
  • IV-A Evaluation metrics
  • IV-A1 Tracker-to-target assignment
  • IV-A2 Distance measure
  • IV-A3 Target-like annotations
  • IV-A4 Multiple Object Tracking Accuracy
  • IV-A5 Multiple Object Tracking Precision
  • IV-A6 Track quality measures
  • IV-A7 Tracker ranking
  • V Baseline Methods
  • V-A Training and testing
  • V-B dp_nms: Network flow tracking
  • V-C cem: Continuous energy minimization
  • V-D smot: Similar moving objects
  • V-E tbd: Tracking-by-detection
  • V-F jpda_m: Joint probabilistic data association using mm-best solutions
  • VI Conclusion and Future Work
  • References

Knowls

  1. Knowl 1 — MOT16 Benchmark Dataset Composition and Sequence Characteristics

    data/table

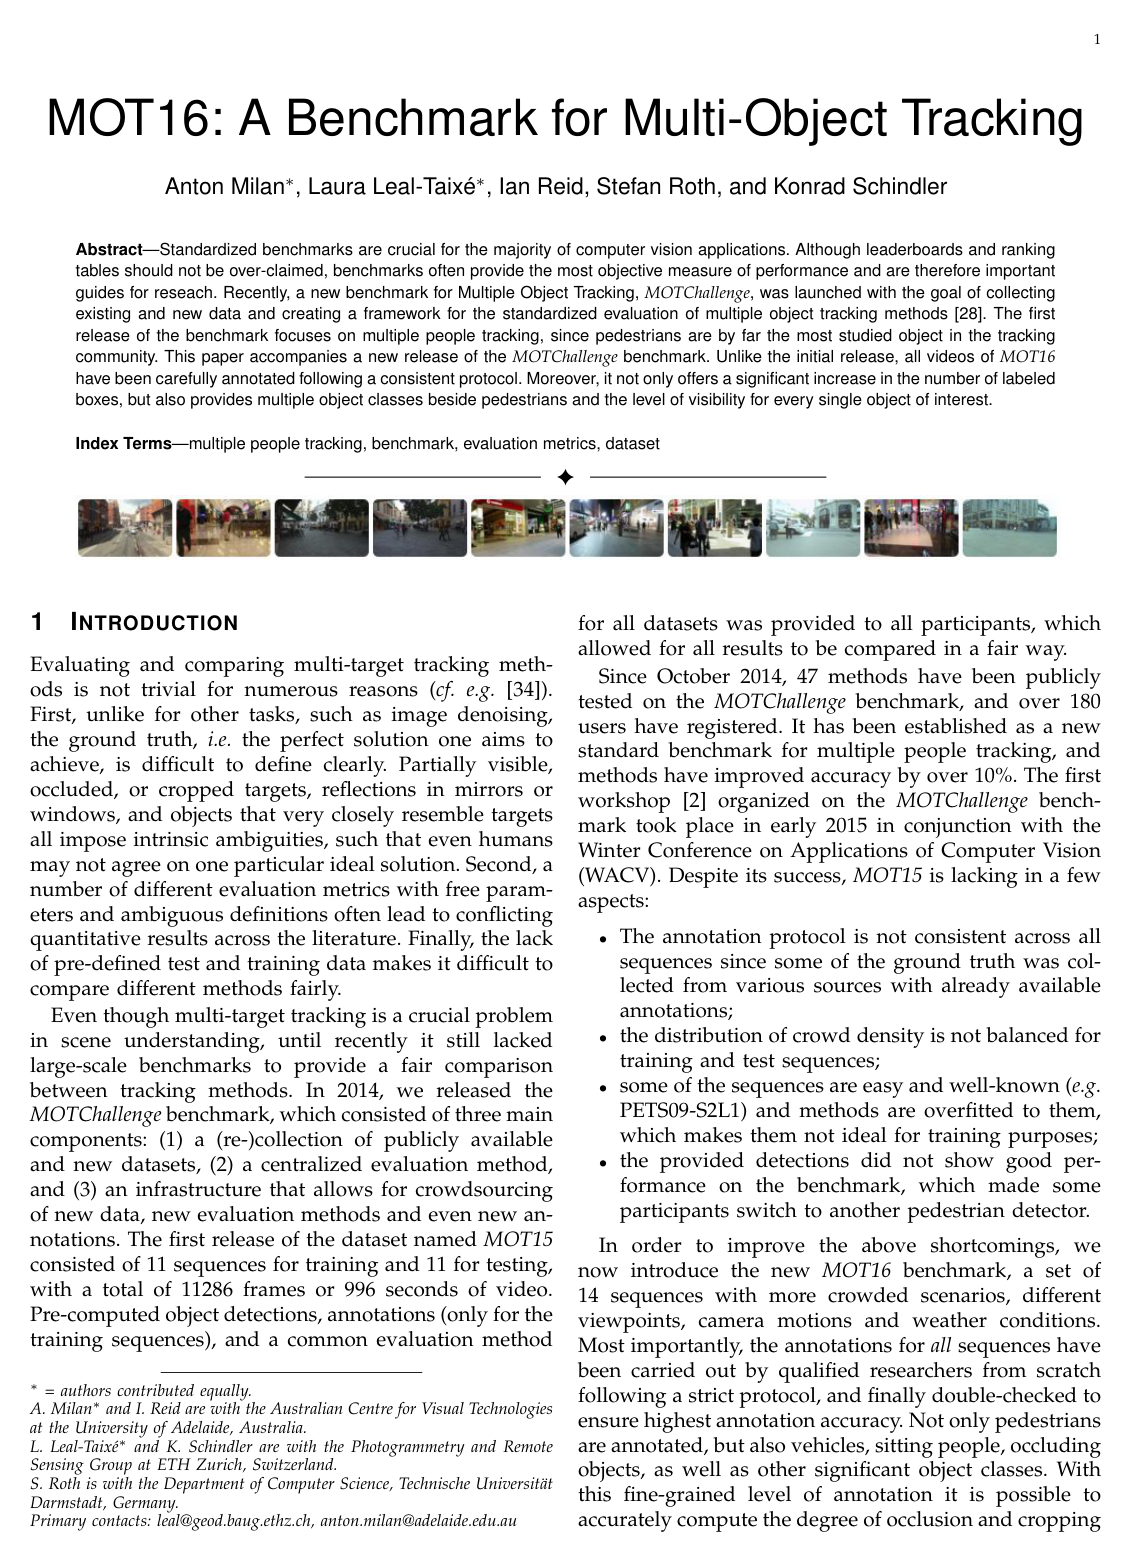
    The MOT16 benchmark for multiple pedestrian tracking consists of 14 video sequences (7 training and 7 test sequences) recorded across varied camera viewpoints (low, medium, high), camera motions (static vs. moving), lighting and weather conditions (cloudy, sunny, shadow, indoor, night), and crowd densities. Annotations for the 7 test sequences are held private to prevent model overfitting.

    Sequence FPS Resolution Length (frames) Tracks Boxes Density Camera Viewpoint
    Training sequences
    MOT16-02 30 1920×10801920\times 1080 600 49 17,833 29.7 static medium
    MOT16-04 30 1920×10801920\times 1080 1,050 80 47,557 45.3 static high
    MOT16-05 14 640×480640\times 480 837 124 6,818 8.1 moving medium
    MOT16-09 30 1920×10801920\times 1080 525 25 5,257 10.0 static low
    MOT16-10 30 1920×10801920\times 1080 654 54 12,318 18.8 moving medium
    MOT16-11 30 1920×10801920\times 1080 900 67 9,174 10.2 moving medium
    MOT16-13 25 1920×10801920\times 1080 750 68 11,450 15.3 moving high
    Total train 5,316 512 110,407 20.8
    Testing sequences
    MOT16-01 30 1920×10801920\times 1080 450 23 6,395 14.2 static medium
    MOT16-03 30 1920×10801920\times 1080 1,500 148 104,556 69.7 static high
    MOT16-06 14 640×480640\times 480 1,194 217 11,538 9.7 moving medium
    MOT16-07 30 1920×10801920\times 1080 500 55 16,322 32.6 moving medium
    MOT16-08 30 1920×10801920\times 1080 625 63 16,737 26.8 static medium
    MOT16-12 30 1920×10801920\times 1080 900 94 8,295 9.2 moving medium
    MOT16-14 25 1920×10801920\times 1080 750 230 18,483 24.6 moving high
    Total test 5,919 830 182,326 30.8
    Benchmark total 11,235 1,342 292,733

    Density is defined as the mean number of pedestrian bounding boxes visible per frame. Across all annotated classes (pedestrians, vehicles, distractors, occluders, and reflections), MOT16 contains a total of 476,532 annotated bounding boxes.

  2. Knowl 2 — Ground Truth Annotation Protocol and Object Categorization for Multi-Pedestrian Tracking

    definition

    Bounding box annotations in MOT16 are structured into three distinct functional categories:

    1. Target Class (Evaluated): All upright pedestrians (standing, walking, running), as well as cyclists and skaters. If a person temporarily bends over or squats (e.g., to pick something up), they remain in this class. Trackers are evaluated strictly on their ability to track objects in this class.
    2. Ambiguous / Distractor Classes (Neutral in Evaluation): Static humans not in an upright position (e.g., sitting, lying down), artificial human representations (mannequins, statues, posters, dolls), reflections, and people behind transparent barriers (e.g., glass walls or windows). Tracking algorithms are neither penalized nor rewarded for tracking or failing to track instances in these classes.
    3. Other / Occluders (Context / Non-Evaluated): Moving vehicles (cars, bicycles, motorbikes, strollers) and environmental occluders (pillars, trees, buildings, trash bins). These annotations are provided for model training and for automated calculation of pedestrian occlusion and visibility ratios, but are not evaluated as tracking targets.

    Annotation alignment rules:

    • Bounding boxes are drawn tight around all object pixels; for a walking pedestrian viewed from the side, the box width dynamically expands and contracts with the stride.
    • For partially occluded or cropped objects, the full box extent is estimated beyond visible pixels or frame boundaries using contextual cues (shadows, prior/future frames).
    • Trajectories begin as soon as ≈10%\approx 10\% of the target becomes visible and terminate when precise localization becomes impossible. If a target leaves the field of view or is occluded for an extended period, it receives a new unique ID upon reappearance.
  3. Knowl 3 — Distractor Filtering and Tracker-to-Target Assignment Protocol

    algorithm

    To prevent multi-object tracking algorithms from being penalized with false positives or credited with true positives when following ambiguous or non-target human-like entities (such as sitting persons, reflections, mannequins, or cyclists), the benchmark evaluation filters candidate hypotheses prior to computing performance metrics on upright pedestrians.

    Input: Tracker bounding box hypotheses HtH_t at frame tt, ground truth pedestrian targets GttargetG_t^{\text{target}}, ground truth ambiguous/distractor objects GtdistractorG_t^{\text{distractor}}
    Output: True Positives (TP), False Positives (FP), and False Negatives (FN) at frame tt
    Combine ground truth sets: Gt=Gttarget∪GtdistractorG_t = G_t^{\text{target}} \cup G_t^{\text{distractor}}
    Compute pairwise IoU matrix between HtH_t and GtG_t
    Find optimal bipartite matching between HtH_t and GtG_t using the Hungarian algorithm with distance threshold td=0.5t_d = 0.5 (IoU ≥0.5\ge 0.5)
    for each matched hypothesis h∈Hth \in H_t do
        if hh is matched to g∈Gtdistractorg \in G_t^{\text{distractor}} with IoU(h,g)≥0.5\text{IoU}(h, g) \ge 0.5 then
            Remove hh from HtH_t
        end if
    end for
    Evaluate remaining hypotheses in HtH_t against GttargetG_t^{\text{target}}:
    Identify matched pairs (h,g)(h, g) with g∈Gttargetg \in G_t^{\text{target}} as True Positives (TP)
    Identify unmatched hypotheses in HtH_t as False Positives (FP)
    Identify unmatched targets in GttargetG_t^{\text{target}} as False Negatives (FN)

    This two-stage procedure ensures that detections naturally generated on distractors do not artificially degrade tracker accuracy, while preserving strict evaluation on upright pedestrians.

  4. Knowl 4 — Multiple Object Tracking Accuracy (MOTA) and Identity Switches

    equation

    Multiple Object Tracking Accuracy (MOTA) evaluates tracking performance by combining three distinct error sources: missed targets (false negatives), spurious tracks (false positives), and identity switches:

    MOTA=1−∑t(FNt+FPt+IDSWt)∑tGTt\text{MOTA} = 1 - \frac{\sum_t (\text{FN}_t + \text{FP}_t + \text{IDSW}_t)}{\sum_t \text{GT}_t}

    where for each frame tt:

    • GTt\text{GT}_t is the total count of ground truth target objects present in frame tt.
    • FNt\text{FN}_t is the count of false negatives (missed ground truth targets).
    • FPt\text{FP}_t is the count of false positives (tracker hypotheses that do not match any ground truth target with IoU≥0.5\text{IoU} \ge 0.5).
    • IDSWt\text{IDSW}_t is the count of identity switches occurring at frame tt.

    An identity switch (IDSW\text{IDSW}) is recorded if a ground truth target ii matched to track hypothesis jj at frame tt was previously matched to a different track hypothesis k≠jk \neq j. To enforce temporal continuity, if ground truth object ii was matched to hypothesis jj at frame t−1t - 1 and their spatial distance remains below the threshold td=0.5t_d = 0.5 at frame tt, the assignment between ii and jj is maintained even if another hypothesis is closer.

    MOTA is expressed as a percentage in the range (−∞,100%](-\infty, 100\%]; it can become negative if total tracking errors exceed the total count of ground truth targets. The relative identity switch frequency normalized by tracking recall is defined as:

    rel.ID=∑tIDSWtRecall\text{rel.ID} = \frac{\sum_t \text{IDSW}_t}{\text{Recall}}

    where Recall=∑tTPt∑tGTt\text{Recall} = \frac{\sum_t \text{TP}_t}{\sum_t \text{GT}_t}.

  5. Knowl 5 — Multiple Object Tracking Precision (MOTP) Metric

    equation

    Multiple Object Tracking Precision (MOTP) evaluates the bounding box localization accuracy of a tracking method by computing the average spatial overlap across all true positive assignments:

    MOTP=∑t,idt,i∑tct\text{MOTP} = \frac{\sum_{t, i} d_{t, i}}{\sum_t c_t}

    where:

    • tt indexes video frames.
    • ctc_t is the number of matched ground truth-hypothesis pairs (true positive matches) in frame tt.
    • dt,i=IoU(ht,i,gt,i)d_{t, i} = \text{IoU}(h_{t,i}, g_{t,i}) is the Intersection-over-Union bounding box overlap between matched hypothesis ht,ih_{t,i} and assigned ground truth target gt,ig_{t,i}.

    Because matching enforces an overlap threshold of td=0.5t_d = 0.5 (IoU≥50%\text{IoU} \ge 50\%), MOTP values strictly fall in the interval [50%,100%][50\%, 100\%]. In a tracking-by-detection framework, MOTP primarily reflects the localization quality of the supplied bounding box detections rather than trajectory association quality.

  6. Knowl 6 — Track Quality Measures: MT, ML, PT, and Track Fragmentation

    definition

    Trajectory-level tracking quality is evaluated through four complementary measures:

    1. Mostly Tracked (MT): The percentage of ground truth trajectories for which a tracker successfully tracks at least 80%80\% of the target's total lifespan. Maintaining a consistent single identity across the entire lifespan is not required to satisfy this criterion.
    2. Mostly Lost (ML): The percentage of ground truth trajectories tracked for less than 20%20\% of their total lifespan.
    3. Partially Tracked (PT): Ground truth trajectories that are neither mostly tracked nor mostly lost (20%≤tracked lifespan<80%20\% \le \text{tracked lifespan} < 80\%).
    4. Track Fragmentation (FM): The total number of times an uninterrupted ground truth trajectory switches from a tracked status to an untracked (interrupted) status, followed by tracking resumption at a later frame.

    Relative track fragmentation normalized by tracking recall is computed as:

    rel.FM=FMRecall\text{rel.FM} = \frac{\text{FM}}{\text{Recall}}

    where Recall=∑tTPt∑tGTt\text{Recall} = \frac{\sum_t \text{TP}_t}{\sum_t \text{GT}_t}.

  7. Knowl 7 — Standardized MOT16 Comma-Separated Data Format

    definition

    Detection files, ground truth annotations, and tracker result submissions adhere to a standardized comma-separated value (CSV) format containing 9 attributes per bounding box instance:

    <frame>, <id>, <bb_left>, <bb_top>, <bb_width>, <bb_height>, <conf>, <class>, <visibility>
    

    The specification for each field is:

    • frame (integer, 1-based): Video frame index.
    • id (integer): Trajectory identifier (assigned to −1-1 in detection files).
    • bb_left (float, 1-based): Horizontal pixel coordinate of the top-left corner of the bounding box.
    • bb_top (float, 1-based): Vertical pixel coordinate of the top-left corner of the bounding box.
    • bb_width (float): Width of the bounding box in pixels.
    • bb_height (float): Height of the bounding box in pixels.
    • conf (float): In detection files, detector confidence score. In ground truth and result files, a binary active flag (1=evaluated1 = \text{evaluated}, 0=ignored0 = \text{ignored}).
    • class (integer, 1–12): Ground truth object class identifier (set to −1-1 in detection files):
      • 11: Pedestrian (evaluated target)
      • 22: Person on vehicle
      • 33: Car
      • 44: Bicycle
      • 55: Motorbike
      • 66: Non-motorized vehicle
      • 77: Static person
      • 88: Distractor
      • 99: Occluder
      • 1010: Occluder on the ground
      • 1111: Occluder full
      • 1212: Reflection
    • visibility (float, [0,1][0, 1]): Fraction of the object area visible in the frame, accounting for occlusion and image boundary cropping (set to −1-1 in detection files).
  8. Knowl 8 — Baseline Multi-Object Tracking Performance on MOT16

    data/table

    Five multi-object tracking baselines were evaluated on the MOT16 test dataset using precomputed Deformable Part-based Model (DPM v5) detections. Hyperparameters for each baseline were tuned by executing 20 independent runs on the training set with parameters sampled uniformly around default values in [0.5θi,2θi][0.5\theta_i, 2\theta_i], selecting the configuration that maximized training MOTA.

    Method MOTA MOTP FAR MT (%) ML (%) FP FN IDsw rel.ID FM rel.FM Hz
    TBD 33.7±9.233.7 \pm 9.2 76.5 1.0 7.2 54.2 5,804 112,587 2,418 63.3 2,252 58.9 1.3
    CEM 33.2±7.933.2 \pm 7.9 75.8 1.2 7.8 54.4 6,837 114,322 642 17.2 731 19.6 0.3
    DP_NMS 32.2±9.832.2 \pm 9.8 76.4 0.2 5.4 62.1 1,123 121,579 972 29.2 944 28.3 212.6
    SMOT 29.7±7.329.7 \pm 7.3 75.2 2.9 4.3 47.7 17,426 107,552 3,108 75.8 4,483 109.3 0.2
    JPDA_M 26.2±6.126.2 \pm 6.1 76.3 0.6 4.1 67.5 3,689 130,549 365 12.9 638 22.5 22.2

    The evaluated baseline methods encompass:

    • TBD (Tracking-by-Detection): Two-stage Hungarian matching linking overlapping detections and bridging occlusions up to 20 frames.
    • CEM (Continuous Energy Minimization): Continuous optimization over trajectory positions incorporating dynamic motion smoothing, collision exclusion, and persistence terms.
    • DP_NMS (Dynamic Programming with NMS): Min-cost network flow tracking solved via successive shortest paths with dynamic programming, achieving 212.6 Hz212.6\text{ Hz} throughput.
    • SMOT (Similar Multi-Object Tracking): Linear regressor motion modeling with generalized linear assignment.
    • JPDA_M (Joint Probabilistic Data Association with mm-best hypotheses): Top-mm hypothesis approximation (m≈100m \approx 100) of full JPDA marginal probabilities, yielding the lowest total identity switches (365).

    ±\pm denotes standard deviation of MOTA across individual test sequences, serving as a measure of cross-sequence robustness.

  9. Knowl 9 — Detector Selection and Precomputed Public Detections

    empirical result

    To provide a uniform input across tracking-by-detection methods, three pedestrian detectors were compared on MOT16:

    • Aggregated Channel Features (ACF): Reached 24.2%24.2\% recall at 65.7%65.7\% precision on the training set, and 22.0%22.0\% recall at 60.1%60.1\% precision on the test set.
    • Fast R-CNN: Reached 47.2%47.2\% recall at 27.3%27.3\% precision on the training set, and 41.2%41.2\% recall at 17.5%17.5\% precision on the test set.
    • Deformable Part-based Model (DPM v5): Reached 49.5%49.5\% recall at 66.0%66.0\% precision on the training set, and 43.7%43.7\% recall at 60.1%60.1\% precision on the test set.

    DPM v5 achieved the best precision-recall trade-off for pedestrians, whereas generic Fast R-CNN suffered from low precision on pedestrian-specific detection without specialized retraining. As a result, DPM v5 detections generated with a confidence threshold of −1.0-1.0 (yielding 215,166 detections total, or an average of 19.1519.15 detections per frame) were selected as the standardized public detection set for the benchmark.

Coverage note — None was omitted; all contributed dataset specifications, annotation rules, distractor filtering protocols, evaluation metrics, data formats, baseline results, and detector comparisons are covered.

References

  1. 1.Reconstruction Meets Recognition Challenge, 2014. http://ttic.uchicago.edu/∼rurtasun/rmrc/index.php.
  2. 2.1st Workshop on Benchmarking Multi-Target Tracking, 2015. http://www.igp.ethz.ch/photogrammetry/bmtt2015/home.html.
  3. 3.Gurobi library, www.gurobi.com.
  4. 4.A. Alahi, V. Ramanathan, and L. Fei-Fei. Socially-aware large-scale crowd forecasting. In CVPR, 2014.
  5. 5.A. Andriyenko and K. Schindler. Multi-target tracking by continuous energy minimization. In CVPR 2011, pages 1265–1272.
  6. 6.S.-H. Bae and K.-J. Yoon. Robust online multi-object tracking based on tracklet confidence and online discriminative appearance learning. In CVPR 2014.
  7. 7.S. Baker, D. Scharstein, J. P. Lewis, S. Roth, M. J. Black, and R. Szeliski. A database and evaluation methodology for optical flow. IJCV, 92(1):1–31, Mar. 2011.
  8. 8.K. Bernardin and R. Stiefelhagen. Evaluating multiple object tracking performance: The CLEAR MOT metrics. Image and Video Processing, 2008(1):1–10, May 2008.
  9. 9.A. A. Butt and R. T. Collins. Multi-target tracking by Lagrangian relaxation to min-cost network flow. In CVPR 2013.
  10. 10.C. Dicle, M. Sznaier, and O. Camps. The way they move: Tracking multiple targets with similar appearance. In ICCV 2013.
  11. 11.P. Dollár, R. Appel, S. Belongie, and P. Perona. Fast feature pyramids for object detection. PAMI, 36(8):1532–1545, 2014.
  12. 12.P. Dollár, C. Wojek, B. Schiele, and P. Perona. Pedestrian detection: A benchmark. In CVPR, 2009.
  13. 13.A. Ess, B. Leibe, K. Schindler, and L. Van Gool. A mobile vision system for robust multi-person tracking. In CVPR 2008.
  14. 14.M. Everingham, L. Van Gool, C. Williams, J. Winn, and A. Zisserman. The PASCAL Visual Object Classes Challenge 2012 (VOC2012) Results. 2012.
  15. 15.P. F. Felzenszwalb, R. B. Girshick, D. McAllester, and D. Ramanan. Object detection with discriminatively trained part based models. PAMI, 32(9):1627–1645, 2010.
  16. 16.J. Ferryman and A. Ellis. PETS2010: Dataset and challenge. In Advanced Video and Signal Based Surveillance (AVSS), 2010.
  17. 17.T. E. Fortmann, Y. Bar-Shalom, and M. Scheffe. Multi-target tracking using joint probabilistic data association. In 19th IEEE Conference on Decision and Control including the Symposium on Adaptive Processes, volume 19, pages 807–812, Dec. 1980.
  18. 18.A. Geiger, M. Lauer, C. Wojek, C. Stiller, and R. Urtasun. 3d traffic scene understanding from movable platforms. PAMI, 2014.
  19. 19.A. Geiger, P. Lenz, and R. Urtasun. Are we ready for autonomous driving? The KITTI Vision Benchmark Suite. In CVPR 2012.
  20. 20.R. Girshick. Fast R-CNN. In ICCV 2015, 2015.
  21. 21.R. Girshick, F. Iandola, T. Darrell, and J. Malik. Deformable part models are convolutional neural networks. CVPR, 2015.
  22. 22.R. B. Girshick, P. F. Felzenszwalb, and D. McAllester. Discriminatively trained deformable part models, release 5. http://people.cs.uchicago.edu/∼rbg/latent-release5/.
  23. 23.J. a. Henriques, R. Caseiro, and J. Batista. Globally optimal solution to multi-object tracking with merged measurements. In ICCV 2011.
  24. 24.G. B. Huang, M. Ramesh, T. Berg, and E. Learned-Miller. Labeled faces in the wild: A database for studying face recognition in unconstrained environments. Technical Report 07-49, University of Massachussetts, Amherst, 2007.
  25. 25.R. Kasturi, D. Goldgof, P. Soundararajan, V. Manohar, J. Garofolo, M. Boonstra, V. Korzhova, and J. Zhang. Framework for performance evaluation for face, text and vehicle detection and tracking in video: data, metrics, and protocol. PAMI, 31(2), 2009.
  26. 26.M. Kristan et al. The visual object tracking VOT2014 challenge results. In European Conference on Computer Vision Workshops (ECCVW). Visual Object Tracking Challenge Workshop, 2014.
  27. 27.L. Leal-Taixé, M. Fenzi, A. Kuznetsova, B. Rosenhahn, and S. Savarese. Lerning an image-based motion context for multiple people tracking. CVPR, 2014.
  28. 28.L. Leal-Taixé, A. Milan, I. Reid, S. Roth, and K. Schindler. MOTChallenge 2015: Towards a benchmark for multi-target tracking. arXiv:1504.01942, 2015.
  29. 29.L. Leal-Taixé, G. Pons-Moll, and B. Rosenhahn. Branch-and-price global optimization for multi-view multi-object tracking. CVPR, 2012.
  30. 30.Y. Li, C. Huang, and R. Nevatia. Learning to associate: Hybridboosted multi-target tracker for crowded scene. In CVPR 2009.
  31. 31.J. Liu, P. Carr, R. T. Collins, and Y. Liu. Tracking sports players with context-conditioned motion models. In CVPR 2013, pages 1830–1837.
  32. 32.M. Mathias, R. Benenson, M. Pedersoli, and L. V. Gool. Face detection without bells and whistles. In ECCV 2014, 2014.
  33. 33.A. Milan, S. Roth, and K. Schindler. Continuous energy minimization for multitarget tracking. PAMI, 36(1):58–72, 2014.
  34. 34.A. Milan, K. Schindler, and S. Roth. Challenges of ground truth evaluation of multi-target tracking. In 2013 IEEE Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), pages 735–742, June 2013.
  35. 35.H. Pirsiavash, D. Ramanan, and C. C. Fowlkes. Globally-optimal greedy algorithms for tracking a variable number of objects. In CVPR 2011 .
  36. 36.H. S. Rezatofighi, A. Milan, Z. Zhang, Q. Shi, A. Dick, and I. Reid. Joint probabilistic data association revisited. In ICCV 2015 .
  37. 37.D. Scharstein and R. Szeliski. A taxonomy and evaluation of dense two-frame stereo correspondence algorithms. IJCV, 47(1-3):7–42, Apr. 2002.
  38. 38.D. Schuhmacher, B.-T. Vo, and B.-N. Vo. A consistent metric for performance evaluation of multi-object filters. IEEE Transactions on Signal Processing, 56(8):3447–3457, Aug. 2008.
  39. 39.S. M. Seitz, B. Curless, J. Diebel, D. Scharstein, and R. Szeliski. A comparison and evaluation of multi-view stereo reconstruction algorithms. In CVPR 2006, pages 519–528.
  40. 40.K. Smith, D. Gatica-Perez, J.-M. Odobez, and S. Ba. Evaluating multi-object tracking. In Workshop on Empirical Evaluation Methods in Computer Vision (EEMCV) .
  41. 41.R. Stiefelhagen, K. Bernardin, R. Bowers, J. S. Garofolo, D. Mostefa, and P. Soundararajan. The clear 2006 evaluation. In CLEAR, 2006.
  42. 42.A. Torralba and A. Efros. Unbiased look at dataset bias. In CVPR 2011 .
  43. 43.B. Wang, G. Wang, K. L. Chan, and L. Wang. Tracklet association with online target-specific metric learning. In CVPR 2014, June 2014.
  44. 44.L. Wen, D. Du, Z. Cai, Z. Lei, M.-C. Chang, H. Qi, J. Lim, M.-H. Yang, and S. Lyu. Detrac: A new benchmark and protocol for multi-object tracking. arXiv:1511.04136, 2015.
  45. 45.L. Wen, W. Li, J. Yan, Z. Lei, D. Yi, and S. Z. Li. Multiple target tracking based on undirected hierarchical relation hypergraph. In CVPR 2014 .
  46. 46.B. Wu and R. Nevatia. Tracking of multiple, partially occluded humans based on static body part detection. In CVPR 2006, pages 951–958, 2006.
  47. 47.A. R. Zamir, A. Dehghan, and M. Shah. GMCP-Tracker: Global multi-object tracking using generalized minimum clique graphs. In ECCV 2012, volume 2, pages 343–356.
  48. 48.H. Zhang, A. Geiger, and R. Urtasun. Understanding high-level semantics by modeling traffic patterns. In ICCV 2013 .
  49. 49.L. Zhang, Y. Li, and R. Nevatia. Global data association for multi-object tracking using network flows. In CVPR 2008.

Citation

MLA
Milan, A., et al. “MOT16: A Benchmark for Multi-Object Tracking”. arXiv, 2016, http://arxiv.org/abs/1603.00831v2.
APA
Milan, A., Leal-Taixe, L., Reid, I., Roth, S., & Schindler, K. (2016). MOT16: A Benchmark for Multi-Object Tracking. arXiv. http://arxiv.org/abs/1603.00831v2
Chicago
Milan, A., L. Leal-Taixe, I. Reid, S. Roth, and K. Schindler. 2016. “MOT16: A Benchmark for Multi-Object Tracking”. arXiv. http://arxiv.org/abs/1603.00831v2.
Harvard
Milan, A. et al. (2016) “MOT16: A Benchmark for Multi-Object Tracking”, arXiv [Preprint]. Available at: http://arxiv.org/abs/1603.00831v2.
Vancouver
1. Milan A, Leal-Taixe L, Reid I, Roth S, Schindler K (2016) MOT16: A Benchmark for Multi-Object Tracking. arXiv

BibTeX

@article{milan2016mot16,
  title = {MOT16: A Benchmark for Multi-Object Tracking},
  author = {Milan, Anton and Leal-Taixe, Laura and Reid, Ian and Roth, Stefan and Schindler, Konrad},
  year = {2016},
  journal = {arXiv},
  url = {http://arxiv.org/abs/1603.00831v2},
  eprint = {1603.00831}
}
Metadata:arXiv

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF