The CMA Evolution Strategy: A Tutorial

Nikolaus Hansen

article2016arXiv1,785 citations

Derives the Covariance Matrix Adaptation Evolution Strategy from intuitive geometric principles, providing a clear foundation for mastering one of the most effective algorithms for non-linear, non-convex continuous optimization.

Listen

Organizations often face complex, continuous optimization challenges in engineering, logistics, and machine learning where classical gradient-based algorithms fail due to rugged search landscapes, noise, and non-convexity. While conventional evolutionary algorithms offer robustness against these conditions, they frequently suffer from slow convergence on ill-conditioned or non-separable problems and are vulnerable to premature collapse into unpromising subspaces.

The article provides a foundational formulation and operational framework for the Covariance Matrix Adaptation Evolution Strategy (CMA-ES). It demonstrates how combining distribution adaptation with explicit step-size control delivers an efficient, randomized search mechanism for difficult continuous domain black-box optimization.

CMA-ES operates as an iterative stochastic method that samples candidate solutions from a multivariate normal distribution. In each iteration, it evaluates solutions based on their fitness rank, shifts the distribution mean toward the most promising candidates, and updates its geometric search shape. To adapt this covariance structure, the algorithm combines short-term information from the current population with a multi-generational memory path. In parallel, it manages overall step length using cumulative path length control, adjusting step sizes by comparing accumulated trajectory lengths against expected random walk behavior.

The findings establish that dynamically adapting the search distribution covariance is functionally equivalent to learning the inverse Hessian matrix in quasi-Newton optimization methods, effectively transforming distorted, ill-conditioned problem landscapes into easily searchable spherical spaces. By combining historical path tracking with population-level rank updates, the algorithm reduces the evaluation effort required to adapt the search space on challenging elongated landscapes to a linear scaling with dimension. Furthermore, controlling step size and covariance learning rates independently decouples algorithm stability from population size, allowing reliable execution with very small sample populations without premature convergence or subspace collapse. The method also exhibits full affine and monotonic transformation invariance, ensuring consistent search performance across broad classes of mathematically equivalent problems.

These capabilities mean that organizations can tackle high-dimensional, complex numerical optimization problems with significantly fewer costly objective evaluations, lower operational failure rates, and zero reliance on analytical gradient information. Unlike traditional evolutionary heuristics that demand extensive hyperparameter tuning, CMA-ES provides standardized default parameters that perform robustly across diverse application domains.

For practical implementation, teams should adopt CMA-ES as a primary solver for difficult non-linear continuous optimization tasks, retaining the default parameter formulations for update rates and weights. When addressing multimodal landscapes with many local minima, practitioners should implement an automated restart strategy with geometrically increasing population sizes to balance local search speed against global exploration. Boundary and constraint constraints should be handled using distance-based penalization or repair mechanisms rather than hard feasibility sampling.

Decision-makers should note that while the algorithm is highly effective for moderate-to-high dimensions, its internal matrix operations scale quadratically per evaluation, though periodic matrix updates mitigate computational overhead. Additionally, cumulative step-size control can struggle to maintain optimal step lengths under extremely severe noise, requiring appropriate damping adjustments when evaluating highly uncertain systems.

Cover for The CMA Evolution Strategy: A Tutorial

Abstract

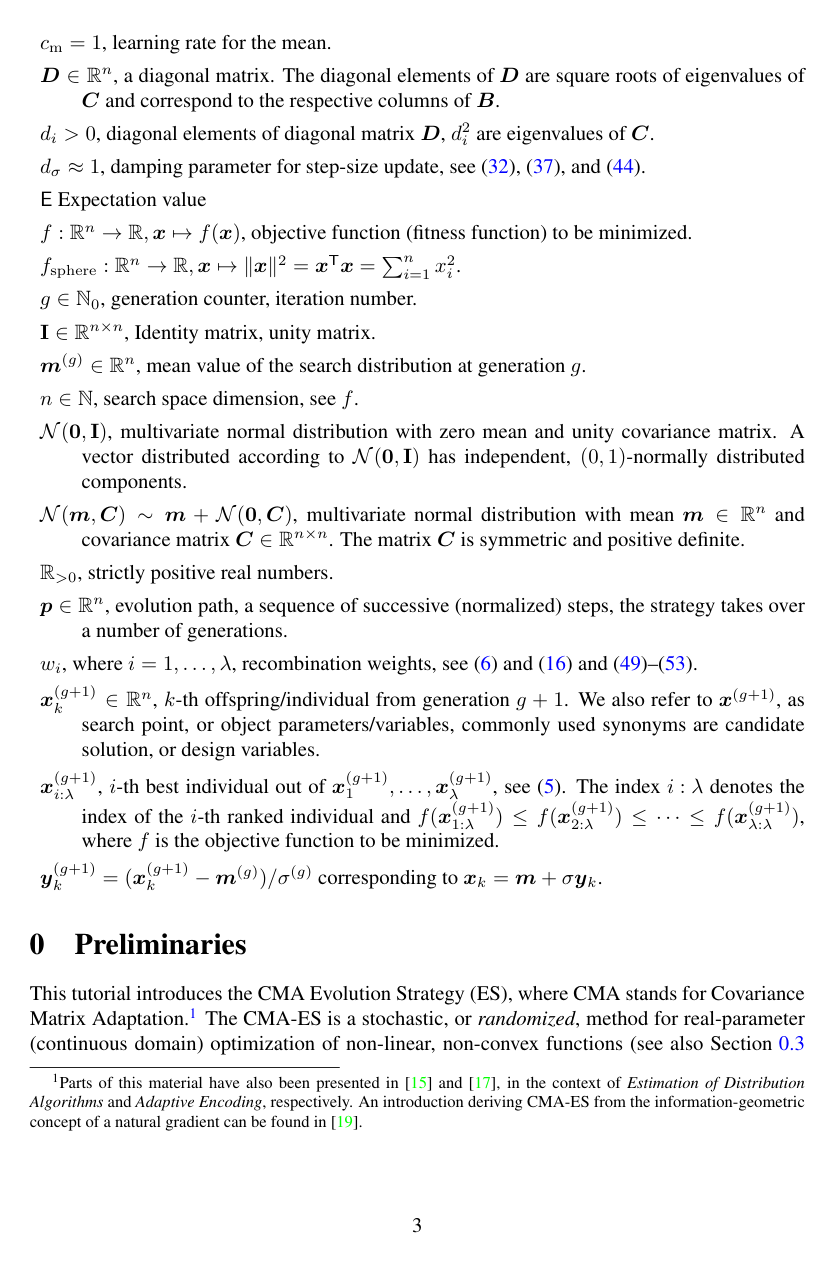
This tutorial introduces the CMA Evolution Strategy (ES), where CMA stands for Covariance Matrix Adaptation. The CMA-ES is a stochastic, or randomized, method for real-parameter (continuous domain) optimization of non-linear, non-convex functions. We try to motivate and derive the algorithm from intuitive concepts and from requirements of non-linear, non-convex search in continuous domain.

Table of Contents

  • Nomenclature
  • 0 Preliminaries
  • 0.1 Eigendecomposition of a Positive Definite Matrix
  • 0.2 The Multivariate Normal Distribution
  • 0.3 Randomized Black Box Optimization
  • 0.4 Hessian and Covariance Matrices
  • 1 Basic Equation: Sampling
  • 2 Selection and Recombination: Moving the Mean
  • 3 Adapting the Covariance Matrix
  • 3.1 Estimating the Covariance Matrix From Scratch
  • 3.2 Rank-μ\mu-Update
  • 3.3 Rank-One-Update
  • 3.3.1 A Different Viewpoint
  • 3.3.2 Cumulation: Utilizing the Evolution Path
  • 3.4 Combining Rank-μ\mu-Update and Cumulation
  • 4 Step-Size Control
  • 5 Discussion
  • References
  • A Algorithm Summary: The CMA-ES
  • B Implementational Concerns
  • B.1 Multivariate normal distribution
  • B.2 Strategy internal numerical effort
  • B.3 Termination criteria
  • B.4 Flat fitness
  • B.5 Boundaries and Constraints
  • C MATLAB Source Code
  • D Reformulation of Learning Parameter ccovc_{\mathrm{cov}}

Knowls

  1. Knowl 1 — The $(\mu/\mu_W, \lambda)$-CMA-ES Algorithm

    algorithm

    The Covariance Matrix Adaptation Evolution Strategy ((μ/μW,λ)(\mu/\mu_W, \lambda)-CMA-ES) is an iterative stochastic optimization algorithm designed for continuous non-linear, non-convex black-box optimization. At each generation gg, the method samples λ\lambda candidate solutions from a multivariate normal distribution N(m(g),(σ(g))2C(g))\mathcal{N}(m^{(g)}, (\sigma^{(g)})^2 C^{(g)}), updates the distribution mean m(g+1)m^{(g+1)} by weighted intermediate recombination of the μ\mu best individuals, updates the step-size σ(g+1)\sigma^{(g+1)} using cumulative step-size adaptation (CSA) on a conjugate evolution path pσp_\sigma, and adapts the covariance matrix C(g+1)C^{(g+1)} by combining a rank-one update (using an evolution path pcp_c) and an active rank-μ\mu update (using both positive and negative recombination weights).

    Input: Objective function f:Rn→Rf: \mathbb{R}^n \to \mathbb{R}, initial mean m∈Rnm \in \mathbb{R}^n, initial step-size σ∈R>0\sigma \in \mathbb{R}_{>0}
    Initialize parameters: λ,μ,w1…λ,cm,cσ,dσ,cc,c1,cμ\lambda, \mu, w_{1\dots\lambda}, c_m, c_\sigma, d_\sigma, c_c, c_1, c_\mu
    Initialize state: pσ←0∈Rnp_\sigma \leftarrow 0 \in \mathbb{R}^n, pc←0∈Rnp_c \leftarrow 0 \in \mathbb{R}^n, C←I∈Rn×nC \leftarrow I \in \mathbb{R}^{n \times n}, g←0g \leftarrow 0
    while termination criterion is not met do
        g←g+1g \leftarrow g + 1
        Compute eigendecomposition C=BD2BTC = B D^2 B^T where BB is orthogonal and DD is diagonal with positive elements
        for k←1k \leftarrow 1 to λ\lambda do
            zk∼N(0,I)z_k \sim \mathcal{N}(0, I)
            yk←BDzky_k \leftarrow B D z_k
            xk←m+σykx_k \leftarrow m + \sigma y_k
            fk←f(xk)f_k \leftarrow f(x_k)
        Sort offspring indices such that f(x1:λ)≤f(x2:λ)≤⋯≤f(xλ:λ)f(x_{1:\lambda}) \le f(x_{2:\lambda}) \le \dots \le f(x_{\lambda:\lambda})
        ⟨y⟩w←∑i=1μwiyi:λ\langle y \rangle_w \leftarrow \sum_{i=1}^\mu w_i y_{i:\lambda}
        m←m+cmσ⟨y⟩wm \leftarrow m + c_m \sigma \langle y \rangle_w
        pσ←(1−cσ)pσ+cσ(2−cσ)μeff C−1/2⟨y⟩wp_\sigma \leftarrow (1 - c_\sigma) p_\sigma + \sqrt{c_\sigma(2 - c_\sigma)\mu_{\text{eff}}} \, C^{-1/2} \langle y \rangle_w
        σ←σexp⁡(cσdσ(∥pσ∥E∥N(0,I)∥−1))\sigma \leftarrow \sigma \exp\left( \frac{c_\sigma}{d_\sigma} \left( \frac{\|p_\sigma\|}{\mathbb{E}\|\mathcal{N}(0, I)\|} - 1 \right) \right)
        hσ←1h_\sigma \leftarrow 1 if ∥pσ∥1−(1−cσ)2g<(1.4+2n+1)E∥N(0,I)∥\frac{\|p_\sigma\|}{\sqrt{1 - (1 - c_\sigma)^{2g}}} < \left(1.4 + \frac{2}{n+1}\right) \mathbb{E}\|\mathcal{N}(0, I)\| else 00
        δ(hσ)←(1−hσ)cc(2−cc)\delta(h_\sigma) \leftarrow (1 - h_\sigma) c_c (2 - c_c)
        pc←(1−cc)pc+hσcc(2−cc)μeff ⟨y⟩wp_c \leftarrow (1 - c_c) p_c + h_\sigma \sqrt{c_c(2 - c_c)\mu_{\text{eff}}} \, \langle y \rangle_w
        for i←1i \leftarrow 1 to λ\lambda do
            wi∘←wi×(1 if wi≥0 else n∥C−1/2yi:λ∥2)w^\circ_i \leftarrow w_i \times \left(1 \text{ if } w_i \ge 0 \text{ else } \frac{n}{\|C^{-1/2} y_{i:\lambda}\|^2}\right)
        C←(1+c1δ(hσ)−c1−cμ∑j=1λwj)C+c1pcpcT+cμ∑i=1λwi∘yi:λyi:λTC \leftarrow (1 + c_1\delta(h_\sigma) - c_1 - c_\mu \sum_{j=1}^\lambda w_j) C + c_1 p_c p_c^T + c_\mu \sum_{i=1}^\lambda w^\circ_i y_{i:\lambda} y_{i:\lambda}^T
    Output: Best evaluated point x1:λx_{1:\lambda} or mean mm

    Here, C−1/2=BD−1BTC^{-1/2} = B D^{-1} B^T, and the expected norm E∥N(0,I)∥=2 Γ(n+12)/Γ(n2)≈n(1−14n+121n2)\mathbb{E}\|\mathcal{N}(0, I)\| = \sqrt{2}\,\Gamma\left(\frac{n+1}{2}\right) / \Gamma\left(\frac{n}{2}\right) \approx \sqrt{n}\left(1 - \frac{1}{4n} + \frac{1}{21n^2}\right). The algorithm requires O(n2)\mathcal{O}(n^2) internal operations per sample point when eigendecompositions of CC are cached and recomputed once every O(n)\mathcal{O}(n) function evaluations.

  2. Knowl 2 — Default Strategy Parameter Settings for CMA-ES

    data/table

    The default parameters of CMA-ES are designed as a robust configuration that scales systematically with search space dimension nn, eliminating the need for problem-specific parameter tuning across unimodal, ill-conditioned, non-separable, and multimodal landscapes.

    Parameter Formula Description
    Population size λ\lambda 4+⌊3ln⁡n⌋4 + \lfloor 3 \ln n \rfloor Total offspring count per generation
    Parent number μ\mu ⌊λ/2⌋\lfloor \lambda / 2 \rfloor Number of positive recombination weights
    Raw weights wi′w'_i ln⁡(λ+12)−ln⁡i,i=1,…,λ\ln\left(\frac{\lambda+1}{2}\right) - \ln i, \quad i=1,\dots,\lambda Monotonically decreasing weights
    Selection mass μeff\mu_{\text{eff}} (∑i=1μwi′)2/∑i=1μwi′2\left(\sum_{i=1}^\mu w'_i\right)^2 / \sum_{i=1}^\mu {w'_i}^2 Variance effective parent mass
    Neg. mass μeff−\mu_{\text{eff}}^- (∑i=μ+1λwi′)2/∑i=μ+1λwi′2\left(\sum_{i=\mu+1}^\lambda w'_i\right)^2 / \sum_{i=\mu+1}^\lambda {w'_i}^2 Variance effective negative mass
    Negative weight multipliers αμ−=1+c1cμ\alpha_\mu^- = 1 + \frac{c_1}{c_\mu}, αμeff−=1+2μeff−μeff+2\alpha_{\mu\text{eff}}^- = 1 + \frac{2\mu_{\text{eff}}^-}{\mu_{\text{eff}}+2} Weight scaling controls
    Pos. def. bound αpos def−=1−c1−cμncμ\alpha_{\text{pos def}}^- = \frac{1 - c_1 - c_\mu}{n c_\mu} Bounding active weight variance
    Normalized weights wiw_i {wi′/∑j=1μ∣wj′∣if wi′≥0min⁡(αμ−,αμeff−,αpos def−)wi′∑j=μ+1λ∣wj′∣if wi′<0\begin{cases} w'_i / \sum_{j=1}^\mu |w'_j| & \text{if } w'_i \ge 0 \\ \min(\alpha_\mu^-, \alpha_{\mu\text{eff}}^-, \alpha_{\text{pos def}}^-) \frac{w'_i}{\sum_{j=\mu+1}^\lambda |w'_j|} & \text{if } w'_i < 0 \end{cases} Sum of positive weights is 11
    Mean learning rate cmc_m 11 Step scale for moving the mean
    Step path decay cσc_\sigma μeff+2n+μeff+5\frac{\mu_{\text{eff}} + 2}{n + \mu_{\text{eff}} + 5} Time constant for step-size cumulation
    Step damping dσd_\sigma 1+2max⁡(0,μeff−1n+1−1)+cσ1 + 2\max\left(0, \sqrt{\frac{\mu_{\text{eff}}-1}{n+1}} - 1\right) + c_\sigma Step-size change dampening
    Cov. path decay ccc_c 4+μeff/nn+4+2μeff/n\frac{4 + \mu_{\text{eff}}/n}{n + 4 + 2\mu_{\text{eff}}/n} Time constant for rank-one cumulation
    Rank-one rate c1c_1 2(n+1.3)2+μeff\frac{2}{(n + 1.3)^2 + \mu_{\text{eff}}} Learning rate for rank-one update
    Rank-μ\mu rate cμc_\mu min⁡(1−c1,21/4+μeff+1/μeff−2(n+2)2+μeff)\min\left(1 - c_1, 2\frac{1/4 + \mu_{\text{eff}} + 1/\mu_{\text{eff}} - 2}{(n + 2)^2 + \mu_{\text{eff}}}\right) Learning rate for rank-μ\mu update

    These defaults ensure that ∑i=1μwi=1\sum_{i=1}^\mu w_i = 1, and that the active negative weights cancel the decay on CC such that c1+cμ∑j=1λwj≈0c_1 + c_\mu \sum_{j=1}^\lambda w_j \approx 0 under standard population sizes, while strictly ensuring the positive definiteness of the updated covariance matrix CC.

  3. Knowl 3 — Combined Rank-One and Active Rank-$\mu$ Covariance Matrix Adaptation

    model/method

    Covariance Matrix Adaptation (CMA) updates the full covariance matrix C∈Rn×nC \in \mathbb{R}^{n \times n} of the search distribution by combining information across successive iterations (rank-one update via cumulation) and information within the current population (rank-μ\mu update with active negative weights):

    C(g+1)=(1+c1δ(hσ)−c1−cμ∑j=1λwj)C(g)+c1pc(g+1)pc(g+1)T+cμ∑i=1λwi∘yi:λ(g+1)yi:λ(g+1)TC^{(g+1)} = \left(1 + c_1 \delta(h_\sigma) - c_1 - c_\mu \sum_{j=1}^\lambda w_j\right) C^{(g)} + c_1 p_c^{(g+1)} {p_c^{(g+1)}}^T + c_\mu \sum_{i=1}^\lambda w_i^\circ y_{i:\lambda}^{(g+1)} {y_{i:\lambda}^{(g+1)}}^T

    where:

    • yi:λ(g+1)=(xi:λ(g+1)−m(g))/σ(g)y_{i:\lambda}^{(g+1)} = (x_{i:\lambda}^{(g+1)} - m^{(g)}) / \sigma^{(g)} is the normalized step taken by the ii-th ranked candidate solution;
    • pc(g+1)∈Rnp_c^{(g+1)} \in \mathbb{R}^n is the rank-one evolution path that accumulates directionally correlated steps across generations;
    • c1,cμ∈[0,1]c_1, c_\mu \in [0, 1] are learning rates with c1+cμ≤1c_1 + c_\mu \le 1;
    • hσ∈{0,1}h_\sigma \in \{0, 1\} is a Heaviside threshold stalling indicator, and δ(hσ)=(1−hσ)cc(2−cc)\delta(h_\sigma) = (1 - h_\sigma) c_c (2 - c_c) compensates for the variance omitted when hσ=0h_\sigma = 0;
    • wi∘w_i^\circ rescales vectors associated with negative recombination weights (wi<0w_i < 0 for i>μi > \mu) according to their Mahalanobis norm:

    wi∘=wi×{1if wi≥0n∥C(g)−1/2yi:λ(g+1)∥2if wi<0w_i^\circ = w_i \times \begin{cases} 1 & \text{if } w_i \ge 0 \\ \frac{n}{\left\|C^{(g)-1/2} y_{i:\lambda}^{(g+1)}\right\|^2} & \text{if } w_i < 0 \end{cases}

    The rank-one update exploits inter-generation step correlations to elongate the distribution in the direction of continuous progress, reducing the sample complexity on linear ridge or cigar functions to O(n)\mathcal{O}(n). The rank-μ\mu update reliably estimates the local landscape variance from large populations. The active negative weights actively reduce variance in unpromising directions, while the Mahalanobis normalization and upper bound on ∑∣wi∣−\sum |w_i|^- mathematically guarantee that C(g+1)C^{(g+1)} remains positive definite.

  4. Knowl 4 — Cumulative Step-Size Adaptation via Conjugate Evolution Path

    model/method

    Cumulative Step-Size Adaptation (CSA), also known as cumulative path length control, governs the global step-size σ(g)∈R>0\sigma^{(g)} \in \mathbb{R}_{>0} independently of the covariance matrix update by comparing the length of a conjugate evolution path pσ∈Rnp_\sigma \in \mathbb{R}^n against its expected value under random selection.

    The conjugate evolution path is updated through exponential smoothing:

    pσ(g+1)=(1−cσ)pσ(g)+cσ(2−cσ)μeff C(g)−1/2(m(g+1)−m(g)cmσ(g))p_\sigma^{(g+1)} = (1 - c_\sigma) p_\sigma^{(g)} + \sqrt{c_\sigma(2 - c_\sigma)\mu_{\text{eff}}} \, C^{(g)-1/2} \left(\frac{m^{(g+1)} - m^{(g)}}{c_m \sigma^{(g)}}\right)

    where cσ<1c_\sigma < 1 is the backward decay rate, μeff=1/∑i=1μwi2\mu_{\text{eff}} = 1 / \sum_{i=1}^\mu w_i^2 is the variance effective selection mass, and C(g)−1/2=B(g)(D(g))−1(B(g))TC^{(g)-1/2} = B^{(g)} (D^{(g)})^{-1} (B^{(g)})^T is the inverse square root of the covariance matrix computed via its eigendecomposition C(g)=B(g)(D(g))2(B(g))TC^{(g)} = B^{(g)} (D^{(g)})^2 (B^{(g)})^T. The transformation C(g)−1/2C^{(g)-1/2} normalizes the expected length of the step to be isotropic and equal in all directions, ensuring pσ(g+1)∼N(0,I)p_\sigma^{(g+1)} \sim \mathcal{N}(0, I) under random selection.

    The step-size is updated multiplicatively:

    σ(g+1)=σ(g)exp⁡(cσdσ(∥pσ(g+1)∥E∥N(0,I)∥−1))\sigma^{(g+1)} = \sigma^{(g)} \exp\left( \frac{c_\sigma}{d_\sigma} \left( \frac{\|p_\sigma^{(g+1)}\|}{\mathbb{E}\|\mathcal{N}(0, I)\|} - 1 \right) \right)

    where dσ≈1d_\sigma \approx 1 is a damping parameter and E∥N(0,I)∥=2 Γ(n+12)/Γ(n2)≈n(1−14n+121n2)\mathbb{E}\|\mathcal{N}(0, I)\| = \sqrt{2} \,\Gamma\left(\frac{n+1}{2}\right)/\Gamma\left(\frac{n}{2}\right) \approx \sqrt{n}\left(1 - \frac{1}{4n} + \frac{1}{21n^2}\right).

    When selected steps are correlated (pointing consistently in the same direction), ∥pσ(g+1)∥>E∥N(0,I)∥\|p_\sigma^{(g+1)}\| > \mathbb{E}\|\mathcal{N}(0, I)\| and σ\sigma increases. When steps cancel each other out (anti-correlated), ∥pσ(g+1)∥<E∥N(0,I)∥\|p_\sigma^{(g+1)}\| < \mathbb{E}\|\mathcal{N}(0, I)\| and σ\sigma decreases. In steady state, consecutive steps are approximately C−1C^{-1}-conjugate, and the update is unbiased on the log scale: E[ln⁡σ(g+1)∣σ(g)]=ln⁡σ(g)\mathbb{E}[\ln \sigma^{(g+1)} \mid \sigma^{(g)}] = \ln \sigma^{(g)} under random selection.

  5. Knowl 5 — Evolution Path Cumulation and Heaviside Stalling for Rank-One Updates

    model/method

    The rank-one covariance matrix update uses an evolution path pc∈Rnp_c \in \mathbb{R}^n to accumulate consecutive successful steps of the distribution mean. Because outer products satisfy yyT=(−y)(−y)Ty y^T = (-y)(-y)^T, updating CC directly with single-step vectors discards the sign information of steps. Cumulation tracks the sign history over a backward time horizon 1/cc1/c_c.

    The evolution path pcp_c is initialized at pc(0)=0p_c^{(0)} = 0 and updated as:

    pc(g+1)=(1−cc)pc(g)+hσcc(2−cc)μeff(m(g+1)−m(g)cmσ(g))p_c^{(g+1)} = (1 - c_c) p_c^{(g)} + h_\sigma \sqrt{c_c(2 - c_c)\mu_{\text{eff}}} \left( \frac{m^{(g+1)} - m^{(g)}}{c_m \sigma^{(g)}} \right)

    where cc≤1c_c \le 1 is the decay rate and cc(2−cc)μeff\sqrt{c_c(2 - c_c)\mu_{\text{eff}}} normalizes the path such that pc(g+1)∼N(0,C)p_c^{(g+1)} \sim \mathcal{N}(0, C) if individual steps follow N(0,C)\mathcal{N}(0, C). Consecutive steps pointing in the same direction modulate the path length by a factor of up to (2−cc)/cc≈1/cc\sqrt{(2 - c_c)/c_c} \approx 1/\sqrt{c_c}, effectively increasing the rank-one learning rate by cc−1/2c_c^{-1/2} and accelerating metric alignment on valley-like landscapes.

    The update incorporates a Heaviside indicator hσ∈{0,1}h_\sigma \in \{0, 1\}:

    hσ={1if ∥pσ(g+1)∥1−(1−cσ)2(g+1)<(1.4+2n+1)E∥N(0,I)∥0otherwiseh_\sigma = \begin{cases} 1 & \text{if } \frac{\|p_\sigma^{(g+1)}\|}{\sqrt{1 - (1 - c_\sigma)^{2(g+1)}}} < \left(1.4 + \frac{2}{n+1}\right) \mathbb{E}\|\mathcal{N}(0, I)\| \\ 0 & \text{otherwise} \end{cases}

    When the overall step-size σ\sigma is far too small, ∥pσ∥\|p_\sigma\| grows abnormally large because steps remain positively correlated across many generations. In this regime, hσ=0h_\sigma = 0 stalls the accumulation in pcp_c, preventing the covariance matrix axes from exploding outward before σ\sigma has scaled up.

  6. Knowl 6 — Variance Effective Selection Mass $\mu_{\text{eff}}$

    definition

    The variance effective selection mass μeff\mu_{\text{eff}} (effective sample size of the selected parents) quantifies the amount of independent information extracted from weighted recombination. For normalized positive recombination weights w1≥w2≥⋯≥wμ>0w_1 \ge w_2 \ge \dots \ge w_\mu > 0 satisfying ∑i=1μwi=1\sum_{i=1}^\mu w_i = 1, it is defined as:

    μeff=(∥w∥1∥w∥2)2=(∑i=1μ∣wi∣)2∑i=1μwi2=1∑i=1μwi2\mu_{\text{eff}} = \left( \frac{\|w\|_1}{\|w\|_2} \right)^2 = \frac{\left( \sum_{i=1}^\mu |w_i| \right)^2}{\sum_{i=1}^\mu w_i^2} = \frac{1}{\sum_{i=1}^\mu w_i^2}

    It satisfies 1≤μeff≤μ1 \le \mu_{\text{eff}} \le \mu, with μeff=μ\mu_{\text{eff}} = \mu for equal weights wi=1/μw_i = 1/\mu, and μeff=1\mu_{\text{eff}} = 1 when a single individual receives full weight. Averaging μ\mu independent identically distributed normal samples with weights ww reduces variance by a factor of 1/μeff1/\mu_{\text{eff}}.

    The corresponding variance effective selection mass for negative recombination weights (wi<0w_{i} < 0 for i>μi > \mu) is defined as:

    μeff−=(∑i=μ+1λ∣wi∣)2∑i=μ+1λwi2\mu_{\text{eff}}^- = \frac{\left( \sum_{i=\mu+1}^\lambda |w_i| \right)^2}{\sum_{i=\mu+1}^\lambda w_i^2}

    In standard parameter configurations where μ≈λ/2\mu \approx \lambda/2 and weights decrease logarithmically, μeff≈λ/4\mu_{\text{eff}} \approx \lambda/4, and the optimal progress rate on isotropic sphere functions scales proportionally to μeff\mu_{\text{eff}}.

  7. Knowl 7 — Invariance Properties of the CMA-ES

    theoretical result

    The CMA-ES exhibits fundamental geometric and algebraic invariance properties that guarantee invariant search behavior across broad equivalence classes of objective functions:

    1. Invariance to Order-Preserving Transformations: Because candidate selection and recombination weight assignment depend strictly on the rank ordering f(x1:λ)≤f(x2:λ)≤⋯≤f(xλ:λ)f(x_{1:\lambda}) \le f(x_{2:\lambda}) \le \dots \le f(x_{\lambda:\lambda}) rather than absolute fitness values, replacing f(x)f(x) with g(f(x))g(f(x)) for any strictly monotonically increasing function g:R→Rg: \mathbb{R} \to \mathbb{R} leaves the sequence of search distributions identical.
    2. Translation Invariance: The search trajectory on x↦f(x+a)x \mapsto f(x + a) with initial mean m(0)=b−am^{(0)} = b - a is identical to that on f(x)f(x) with initial mean m(0)=bm^{(0)} = b for any translation vector a∈Rna \in \mathbb{R}^n.
    3. Rotational and Rigid Invariance: The algorithm is invariant to orthogonal transformations (rotations and reflections) of the search space, provided the initial distribution parameters are rotated accordingly.
    4. Scale and Diagonal Invariance: Invariance to individual coordinate scaling is achieved when the initial diagonal elements of C(0)C^{(0)} are matched to variable scales.
    5. General Affine / Invertible Linear Invariance: For any invertible matrix A∈Rn×nA \in \mathbb{R}^{n \times n}, optimizing f(Ax)f(A x) with m(0)=A−1m0m^{(0)} = A^{-1} m_0 and C(0)=A−1(A−1)TC^{(0)} = A^{-1}(A^{-1})^T produces an exact linear transformation of the trajectory obtained when optimizing f(x)f(x) with m0m_0 and C(0)=IC^{(0)} = I.

    On convex-quadratic functions fH(x)=12xTHxf_H(x) = \frac{1}{2} x^T H x with positive definite Hessian HH, adapting C→H−1C \to H^{-1} dynamically transforms the elliptical contours into spherical ones, reducing the required function evaluations to the level of an isotropic sphere model.

  8. Knowl 8 — Numerical Stability and Termination Criteria for CMA-ES

    model/method

    The CMA-ES employs a set of well-defined termination criteria to prevent wasted CPU time caused by numerical degeneracy, parameter divergence, or flat fitness landscapes:

    • NoEffectAxis: Terminate if adding a 0.10.1-standard-deviation vector along any principal axis of CC produces no floating-point change in the mean: m=m+0.1σdiibim = m + 0.1 \sigma d_{ii} b_i, where bib_i is the ii-th column of eigenvector matrix BB, dii2d_{ii}^2 is the ii-th eigenvalue, and i=(g mod n)+1i = (g \bmod n) + 1.
    • NoEffectCoord: Terminate if adding 0.20.2-standard-deviations in any single coordinate produces no change in mm: mi=mi+0.2σCiim_i = m_i + 0.2 \sigma \sqrt{C_{ii}} for any i∈{1,…,n}i \in \{1, \dots, n\}.
    • ConditionCov: Terminate if the condition number cond(C)=λmax⁡(C)/λmin⁡(C)>1014\text{cond}(C) = \lambda_{\max}(C)/\lambda_{\min}(C) > 10^{14}, preventing numerical breakdown in matrix inversions and square roots.
    • EqualFunValues: Terminate if the range of the best objective function values over the last 10+⌈30n/λ⌉10 + \lceil 30n/\lambda \rceil generations is zero.
    • Stagnation: Track the history of best and median fitness values over the last 20%20\% of iterations (bounded between 120+⌈30n/λ⌉120 + \lceil 30n/\lambda \rceil and 20 00020\,000 iterations); terminate if the median of the most recent 30%30\% of recorded values shows no improvement over the median of the earliest 30%30\%.
    • TolXUp: Terminate if σ×max⁡(diag(D))\sigma \times \max(\text{diag}(D)) increases by a factor greater than 10410^4 relative to its initial value, indicating divergence or an excessively small initial step-size.
    • TolFun / TolX: Problem-dependent stopping criteria triggered when function value ranges drop below TolFun\text{TolFun} (default 10−1210^{-12}) or when coordinate standard deviations σCii\sigma \sqrt{C_{ii}} and components of σpc\sigma p_c drop below TolX\text{TolX} (default 10−12σ(0)10^{-12} \sigma^{(0)}).
  9. Knowl 9 — Boundary and Constraint Handling Strategies in CMA-ES

    model/method

    Handling boundaries and infeasible constraints in CMA-ES requires preserving the integrity of the underlying normal distribution assumptions, as unprincipled modification of candidate points can induce premature step-size collapse or divergence.

    Recommended approaches include:

    1. Re-sampling: For unconstrained optima lying strictly inside the feasible region, infeasible points are resampled until valid.
    2. Penalization of Repaired Box Constraints: For domain bounds, infeasible points xx are projected to the nearest feasible boundary point xrepairedx_{\text{repaired}}, and evaluated using a penalized objective function:

    ffitness(x)=f(xrepaired)+α∥x−xrepaired∥2f_{\text{fitness}}(x) = f(x_{\text{repaired}}) + \alpha \|x - x_{\text{repaired}}\|^2

    where α\alpha is scaled to balance objective differences with penalty magnitude. The repaired point xrepairedx_{\text{repaired}} is discarded after function evaluation so that distribution updates are performed using the original sampled xx. 3. General Non-linear Constraints (ci(x)≤0c_i(x) \le 0): Infeasible solutions are penalized relative to the feasible population:

    ffitness(x)=foffset+α∑iIci(x)>0 ci(x)2f_{\text{fitness}}(x) = f_{\text{offset}} + \alpha \sum_i \mathbb{I}_{c_i(x) > 0} \, c_i(x)^2

    where foffsetf_{\text{offset}} is chosen as a percentile (e.g., median or 25th percentile) of feasible solutions in the current population. 4. Injected Solution Regularization: When external or repaired points are injected directly into distribution updates, their Mahalanobis step length must be clipped to obey ∥x−m∥σ2C≤n+2n/(n+2)\|x - m\|_{\sigma^2 C} \le \sqrt{n} + 2n/(n+2) to avoid severe distortion of the covariance matrix.

  10. Knowl 10 — Degrees-of-Freedom Parameterization for Covariance Learning Rates

    theoretical result

    The learning rates c1c_1 and cμc_\mu for the covariance matrix update can be parameterized directly via the number of degrees of freedom in a symmetric n×nn \times n matrix, m=n2+n2m = \frac{n^2 + n}{2}:

    c1=min⁡(1,λ/6)m+2m+μeffnc_1 = \frac{\min(1, \lambda/6)}{m + 2\sqrt{m} + \frac{\mu_{\text{eff}}}{n}}

    cμ=min⁡(1−c1,αμ0+μeff−2+1μeffm+4m+μeff2)c_\mu = \min\left(1 - c_1, \frac{\alpha_\mu^0 + \mu_{\text{eff}} - 2 + \frac{1}{\mu_{\text{eff}}}}{m + 4\sqrt{m} + \frac{\mu_{\text{eff}}}{2}}\right)

    with constant offset αμ0=0.3\alpha_\mu^0 = 0.3.

    Compared to classical formulations where c1=ccov/μcovc_1 = c_{\text{cov}}/\mu_{\text{cov}} and cμ=ccov(1−1/μcov)c_\mu = c_{\text{cov}}(1 - 1/\mu_{\text{cov}}), this degrees-of-freedom formulation ensures:

    1. c1c_1 is strictly monotonically decreasing with respect to μeff\mu_{\text{eff}}, avoiding non-monotonic artifacts when varying parent population sizes;
    2. The total learning rate c1+cμc_1 + c_\mu is strictly monotonic with respect to μeff\mu_{\text{eff}};
    3. For μeff=1\mu_{\text{eff}} = 1 (where rank-μ\mu update reduces to a single point), cμ>0c_\mu > 0 remains strictly positive due to αμ0>0\alpha_\mu^0 > 0, enabling continuous adaptation even in (1,λ)(1, \lambda) selection regimes.

Coverage note — Omitted historical reviews comparing CMA-ES to other estimation of distribution algorithms (EMNA, Cross-Entropy) and the verbatim MATLAB source listing code from Appendix C, as its operational flow and mathematics are fully captured by the complete algorithm knowl and default parameter table.

References

  1. 1.Akimoto Y, Auger A, Hansen N. Quality gain analysis of the weighted recombination evolution strategy on general convex quadratic functions. In Proceedings of the 14th ACM/SIGEVO Conference on Foundations of Genetic Algorithms (FOGA ’17), pages 111–126. ACM, New York, NY, USA, 2017.
  2. 2.Akimoto Y, Hansen N. Diagonal acceleration for covariance matrix adaptation evolution strategies. Evolutionary computation, 28(3):405–435, 2020.
  3. 3.Auger A, Hansen N. A restart CMA evolution strategy with increasing population size. In Proceedings of the IEEE Congress on Evolutionary Computation, 2005.
  4. 4.Arnold DV. Weighted multirecombination evolution strategies. Theoretical computer science, 361.1:18–37, 2006.
  5. 5.Arnold DV, Beyer HG. Performance analysis of evolutionary optimization with cumulative step length adaptation. IEEE Transactions on Automatic Control, 49(4):617–622, 2004.
  6. 6.Beyer HG. The Theory of Evolution Strategies. Springer, Berlin, 2001.
  7. 7.Beyer HG, Arnold DV. Qualms regarding the optimality of cumulative path length control in CSA/CMA-evolution strategies. Evolutionary Computation, 11(1):19–28, 2003.
  8. 8.Beyer HG, Deb K. On self-adaptive features in real-parameter evolutionary algorithms. IEEE Transactions on Evolutionary Computation, 5(3):250–270, 2001.
  9. 9.Collange G, Delattre N, Hansen N, Quinquis I, Schoenauer M. Multidisciplinary optimisation in the design of future space launchers. In Breitkopf and Coelho, editors, Multidisciplinary Design Optimization in Computational Mechanics, chapter 12, pages 487–496. Wiley, 2010.
  10. 10.Dufossé P, Hansen N. Augmented Lagrangian, penalty techniques and surrogate modeling for constrained optimization with CMA-ES. In Proceedings of the Genetic and Evolutionary Computation Conference (GECCO ’21), pages 519–527, 2021.
  11. 11.Gissler A, Auger A, Hansen N. Learning rate adaptation by line search in evolution strategies with recombination. In Proceedings of the Genetic and Evolutionary Computation Conference (GECCO ’22), pages 630–638. ACM, New York, NY, USA, 2022.
  12. 12.Glasmachers T, Schaul T, Yi S, Wierstra D, Schmidhuber J. Exponential natural evolution strategies. In Proceedings of the 12th annual Genetic and Evolutionary Computation Conference, GECCO, pages 393–400. ACM, 2010.
  13. 13.Hansen N. Verallgemeinerte individuelle Schrittweitenregelung in der Evolutionsstrategie. Mensch und Buch Verlag, Berlin, 1998.
  14. 14.Hansen N. Invariance, self-adaptation and correlated mutations in evolution strategies. In Schoenauer M, Deb K, Rudolph G, Yao X, Lutton E, Merelo JJ, Schwefel HP, editors, Parallel Problem Solving from Nature - PPSN VI, pages 355–364. Springer, 2000.
  15. 15.Hansen N. The CMA evolution strategy: a comparing review. In Lozano JA, Larranaga P, Inza I, and Bengoetxea E, editors, Towards a new evolutionary computation. Advances on estimation of distribution algorithms, pages 75–102. Springer, 2006.
  16. 16.Hansen N. Benchmarking a BI-Population CMA-ES on the BBOB-2009 Function Testbed. In the workshop Proceedings of the Genetic and Evolutionary Computation Conference, GECCO, pages 2389–2395. ACM, 2009.
  17. 17.Hansen N. Variable Metrics in Evolutionary Computation. Habilitation à diriger des recherches, Université Paris-Sud, 2010.
  18. 18.Hansen N. Injecting External Solutions Into CMA-ES. CoRR, arXiv:1110.4181, 2011.
  19. 19.Hansen N, Auger A. Principled design of continuous stochastic search: From theory to practice. In Y Borenstein and A Moraglio, eds.: Theory and Principled Methods for Designing Metaheustics. Springer, pages 145–180, 2014.
  20. 20.Hansen N, Atamna A, Auger A. How to Assess Step-Size Adaptation Mechanisms in Randomised Search. In Parallel Problem Solving from Nature – PPSN XIII, pages 60–69. Springer, 2014.
  21. 21.Hansen N, Kern S. Evaluating the CMA evolution strategy on multimodal test functions. In Xin Yao et al., editors, Parallel Problem Solving from Nature – PPSN VIII, pages 282–291. Springer, 2004.
  22. 22.Hansen N, Niederberger SPN, Guzzella L, Koumoutsakos P. A method for handling uncertainty in evolutionary optimization with an application to feedback control of combustion. IEEE Transactions on Evolutionary Computation, 13(1):180–197, 2009.
  23. 23.Hansen N, Müller SD, Koumoutsakos P. Reducing the time complexity of the derandomized evolution strategy with covariance matrix adaptation (CMA-ES). Evolutionary Computation, 11(1):1–18, 2003.
  24. 24.Hansen N, Ostermeier A. Adapting arbitrary normal mutation distributions in evolution strategies: The covariance matrix adaptation. In Proceedings of the 1996 IEEE Conference on Evolutionary Computation (ICEC ’96), pages 312–317, 1996.
  25. 25.Hansen N, Ostermeier A. Convergence properties of evolution strategies with the derandomized covariance matrix adaptation: The (µ/µI , λ)-CMA-ES. In Proceedings of the 5th European Congress on Intelligent Techniques and Soft Computing, pages 650–654, 1997.
  26. 26.Hansen N, Ostermeier A. Completely derandomized self-adaptation in evolution strategies. Evolutionary Computation, 9(2):159–195, 2001.
  27. 27.Hansen N, Ros R. Benchmarking a weighted negative covariance matrix update on the BBOB-2010 noiseless testbed. In Proceedings companion of the 12th annual Genetic and Evolutionary Computation Conference, GECCO, pages 1673–1680. ACM, 2010.
  28. 28.Jastrebski G, Arnold DV. Improving evolution strategies through active covariance matrix adaptation. In Proceedings of the 2006 IEEE Congress on Evolutionary Computation, CEC, pages 2814–2821. IEEE, 2006.
  29. 29.Kern S, Müller SD, Hansen N, Büche D, Ocenasek J, Koumoutsakos P. Learning probability distributions in continuous evolutionary algorithms – a comparative review. Natural Computing, 3:77–112, 2004.
  30. 30.Larrañaga P. A review on estimation of distribution algorithms. In P. Larrañaga and J. A. Lozano, editors, Estimation of Distribution Algorithms, pages 80–90. Kluwer Academic Publishers, 2002.
  31. 31.Larrañaga P, Lozano JA, Bengoetxea E. Estimation of distribution algorithms based on multivariate normal and Gaussian networks. Technical report, Dept. of Computer Science and Artificial Intelligence, University of the Basque Country, 2001. KZAA-IK-1-01.
  32. 32.Nelder JA, Mead R. A simplex method for function minimization. The Computer Journal 7.4:308-313, 1965.
  33. 33.Rechenberg I. Evolutionsstrategie ’94. Frommann-Holzboog, Stuttgart, Germany, 1994.
  34. 34.Rubenstein RY, Kroese DP. The Cross-Entropy Method: a unified approach to combinatorial optimization, Monte-Carlo simulation, and machine learning. Springer, 2004.
  35. 35.Suttorp T, Hansen N, Igel C. Efficient Covariance Matrix Update for Variable Metric Evolution Strategies. Machine Learning 75(2): 167–197, 2009.

Citation

MLA
Hansen, N. “The CMA Evolution Strategy: A Tutorial”. arXiv, 2016, http://arxiv.org/abs/1604.00772v2.
APA
Hansen, N. (2016). The CMA Evolution Strategy: A Tutorial. arXiv. http://arxiv.org/abs/1604.00772v2
Chicago
Hansen, N. 2016. “The CMA Evolution Strategy: A Tutorial”. arXiv. http://arxiv.org/abs/1604.00772v2.
Harvard
Hansen, N. (2016) “The CMA Evolution Strategy: A Tutorial”, arXiv [Preprint]. Available at: http://arxiv.org/abs/1604.00772v2.
Vancouver
1. Hansen N (2016) The CMA Evolution Strategy: A Tutorial. arXiv

BibTeX

@article{hansen2016the,
  title = {The CMA Evolution Strategy: A Tutorial},
  author = {Hansen, Nikolaus},
  year = {2016},
  journal = {arXiv},
  url = {http://arxiv.org/abs/1604.00772v2},
  eprint = {1604.00772}
}
Metadata:arXiv

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF

License: Authors