M-LLM Based Video Frame Selection for Efficient Video Understanding
Kai HuFeng GaoXiaohan NiePeng ZhouSon TranTal NeimanLingyun WangMubarak ShahRaffay HamidBing Yin
Develops a lightweight, plug-and-play video frame selector trained with spatial and temporal pseudo-labels to replace uniform sampling, boosting question-answering accuracy and efficiency for frozen multimodal LLMs on long- and medium-context video benchmarks.
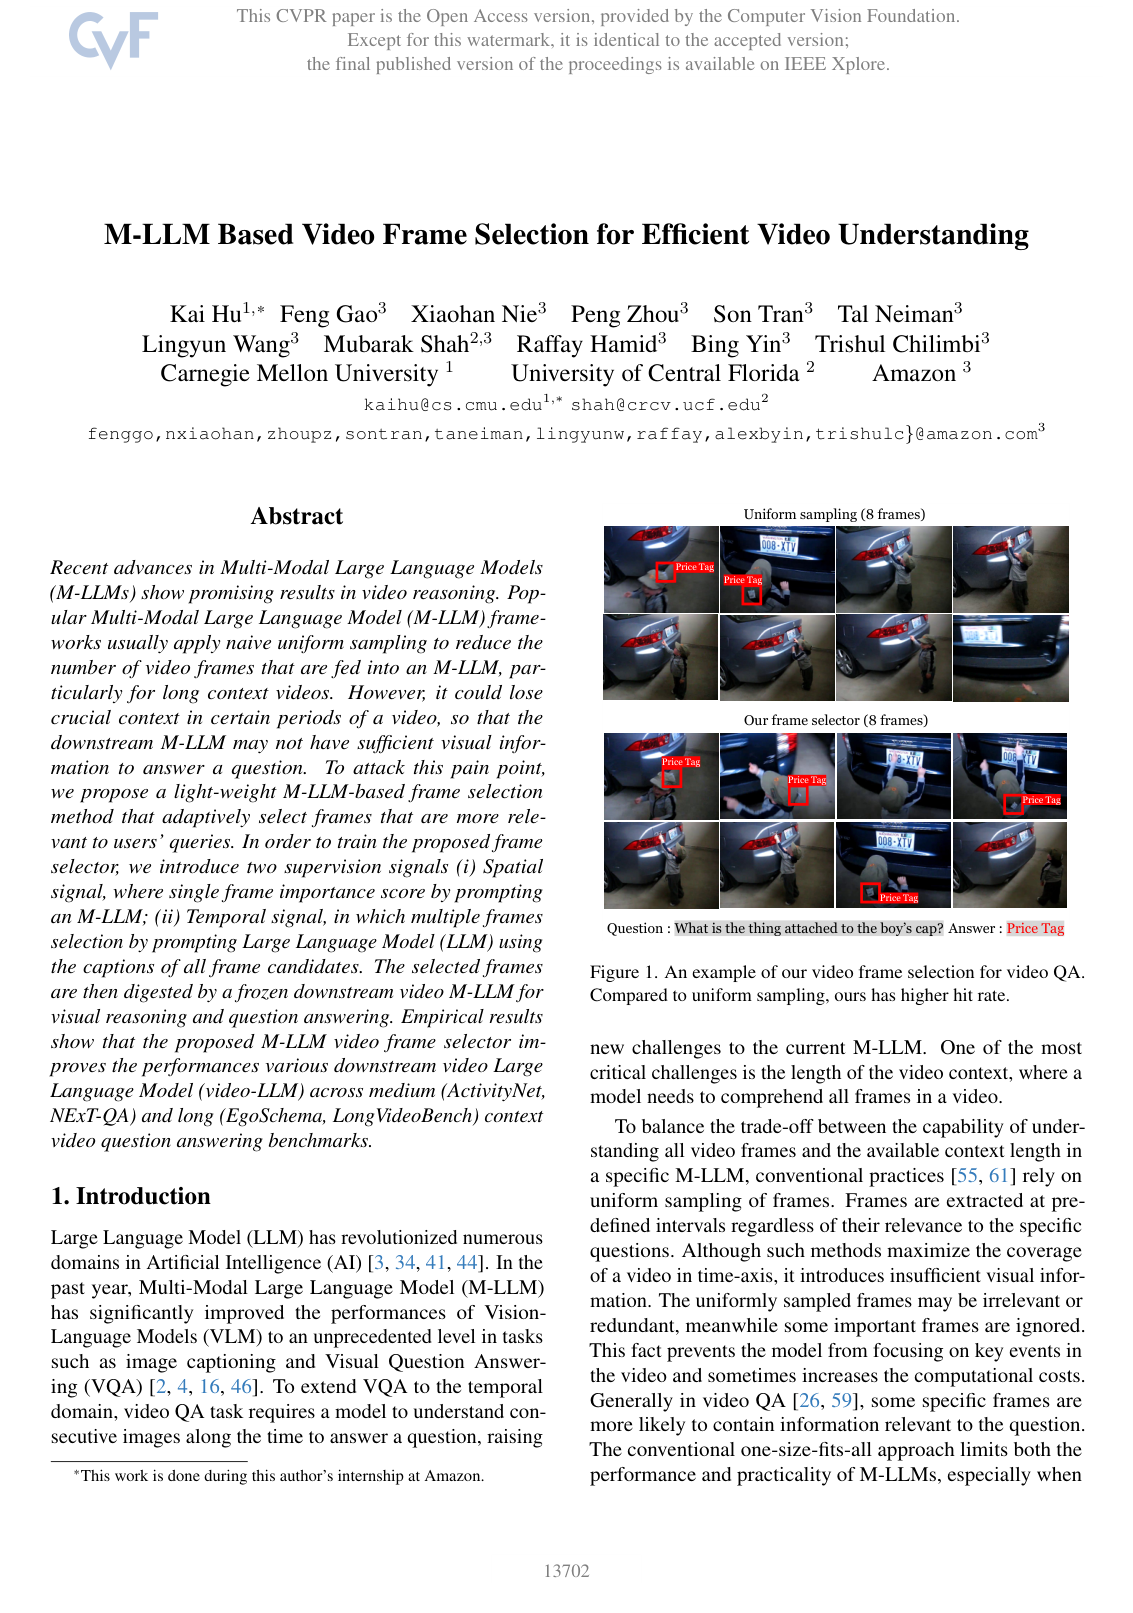
Multi-modal artificial intelligence systems increasingly process video to answer complex user queries. However, standard architectures struggle with the trade-off between analyzing dense visual data and managing limited computational context windows. Most current approaches rely on uniform frame sampling, extracting images at fixed time intervals across a video. This conventional strategy frequently misses brief, decisive actions while ingesting redundant, uninformative visual data, which leads to degraded visual reasoning accuracy and inflated computational costs.
The main objective of the article is to develop and evaluate a lightweight, adaptive frame selection module that identifies the most query-relevant video frames before passing them to downstream language and vision models. By doing so, the article aims to demonstrate that targeted, question-aware frame selection significantly improves video question-answering accuracy and processing efficiency compared to standard uniform sampling.
To accomplish this, the authors engineered a plug-and-play frame selector built upon a compact language model paired with aggressive visual compression, reducing each candidate frame from standard high-token representations to just nine visual tokens. Because human-labeled frame importance data is scarce, the selector is trained using automated pseudo-labels that combine spatial relevance scores from a multimodal model with temporal reasoning from a text-based language model analyzing frame captions. The system processes an initial pool of 128 uniformly sampled frames, calculates an importance score for each frame relative to the question, and selects the top candidates using a greedy algorithm with non-maximum suppression to prevent the selection of redundant neighboring frames. The framework was evaluated across multiple standard medium- and long-context benchmarks, including ActivityNet-QA, NExT-QA, EgoSchema, VideoMME, and LongVideoBench.
The key findings show consistent performance and efficiency gains across diverse benchmarks. First, integrating the adaptive selector improved the question-answering accuracy of various leading video models, yielding gains across every tested benchmark without requiring any modifications or fine-tuning of the downstream models themselves. Second, the selector enables models to achieve equal or superior accuracy using half as many input frames; for example, downstream models processing four selectively chosen frames matched or outperformed systems using eight uniformly sampled frames. Third, on long-form video benchmarks with runtimes averaging nearly eight minutes, models utilizing selected frames consistently outperformed uniform sampling baselines across every tested frame budget. Finally, ablation studies showed that combining spatial and temporal reasoning during supervision produced markedly higher accuracy than relying on simple image-text similarity metrics.
These results demonstrate that question-aware frame selection directly addresses the computational bottleneck of long video analysis. In enterprise settings, processing fewer frames per query lowers hardware memory requirements, reduces inference latency, and decreases operational cloud computing costs. Furthermore, the plug-and-play design ensures compatibility with existing foundation models without expensive retraining.
Organizations deploying video analysis and reasoning systems should consider adopting front-end adaptive frame selectors rather than relying solely on uniform frame sampling or expanding context window sizes. For immediate implementation, teams can integrate compact, fine-tuned selectors into existing inference pipelines to cut computational loads while boosting accuracy. Future efforts should explore end-to-end joint training architectures, expand training across broader synthetic and real-world datasets, and optimize pseudo-labeling pipelines to minimize upstream training overhead.
Confidence in these findings is high, supported by consistent empirical improvements across diverse model families and standardized evaluation suites. However, decision-makers should note certain limitations: the training pipeline depends heavily on synthetic supervision generated by external large models, which may inherit hallucinations or labeling noise. Additionally, while the selector is computationally lightweight, it introduces a preliminary inference step whose latency and overhead must be factored into real-time or ultra-low-latency production environments.
- Paper: Video-LLaVA: Learning United Visual Representation by Alignment Before Projection, Bin Lin et al. (2023). It introduces Video-LLaVA's unified vision-language alignment framework, providing the foundational multimodal foundation model baseline that the source paper seeks to make more efficient via adaptive frame selection.
- Paper: Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution, Peng Wang et al. (2024). It details dynamic resolution and 3D spatiotemporal rotary position embeddings in vision-language models, establishing the standard context-window representations that the source paper's token-compressed selector optimizes.
- Paper: LLaVA-OneVision: Easy Visual Task Transfer, Bo Li et al. (2024). It presents LLaVA-OneVision's token budget strategies and multimodal transfer across images and video frames, underpinning the frame-budget trade-offs explored in the source.
- Paper: Video-LaVIT: Unified Video-Language Pre-training with Decoupled Visual-Motional Tokenization, Yang Jin et al. (2024). It establishes principles for decoupled visual-temporal tokenization in video-language pre-training, directly informing the separation of spatial and temporal cues used in the source's pseudo-labeling.
- Paper: MVBench: A Comprehensive Multi-modal Video Understanding Benchmark, Kunchang Li et al. (2023). It introduces standard video question-answering evaluation tasks and temporal benchmarks that define the multi-frame understanding challenges addressed by the source.
- Paper: Video-MME: The First-Ever Comprehensive Evaluation Benchmark of Multi-modal LLMs in Video Analysis, Chaoyou Fu et al. (2025). It introduces Video-MME, the comprehensive benchmark utilized in the source paper to rigorously evaluate long-form video question answering under adaptive frame budgets.
- Paper: XAttention: Block Sparse Attention with Antidiagonal Scoring, Ruyi Xu et al. (2025). It explores architectural block-sparse attention to eliminate quadratic computation in long videos, offering a complementary internal attention optimization to the source paper's front-end frame selection.
- Paper: ReToken: One Token to Improve Vision-Language Models for Visual Retrieval, Yao Xiao et al.. It investigates a single-token internal retrieval mechanism (ReToken) to prune long visual inputs, extending the inquiry into question-guided visual frame selection directly inside vision-language model architectures.
- Paper: Filter, Correlate, Compress: Training-Free Token Reduction for MLLM Acceleration, Yuhang Han et al. (2026). It presents a training-free token reduction and compression framework across multimodal encoders and decoders, expanding on the source paper's goal of accelerating MLLM video inference.
- Paper: Qwen3-VL Technical Report, Shuai Bai et al. (2025). It advances vision-language scaling to extended native context windows and timestamped video reasoning, representing a state-of-the-art multimodal system where adaptive frame selection techniques can be applied.