Model soups: averaging weights of multiple fine-tuned models improves accuracy without increasing inference time
Mitchell WortsmanGabriel IlharcoSamir Yitzhak GadreRebecca RoelofsRaphael Gontijo-LopesAri S. MorcosHongseok NamkoongAli FarhadiYair CarmonSimon Kornblith
Introduces model soups, a method of averaging the weights of multiple fine-tuned models that yields ensemble-level accuracy and out-of-distribution generalization without adding any computational or memory overhead at inference time.
In modern machine learning workflows, organizations frequently fine-tune large pre-trained foundation models across a broad range of training configurations to maximize task performance. Standard practice retains only the single highest-performing model on a validation dataset and discards the rest. While combining predictions from multiple models into an ensemble reliably improves accuracy and robustness, it multiplies inference runtime and computational memory costs proportionally to the number of models used, making real-time deployment expensive or impractical.
The article demonstrates that averaging the parameter weights of multiple models fine-tuned from the same shared pre-trained initialization—a method called "model soups"—improves predictive accuracy and out-of-distribution robustness without incurring any additional inference latency, compute, or memory overhead relative to a single model.
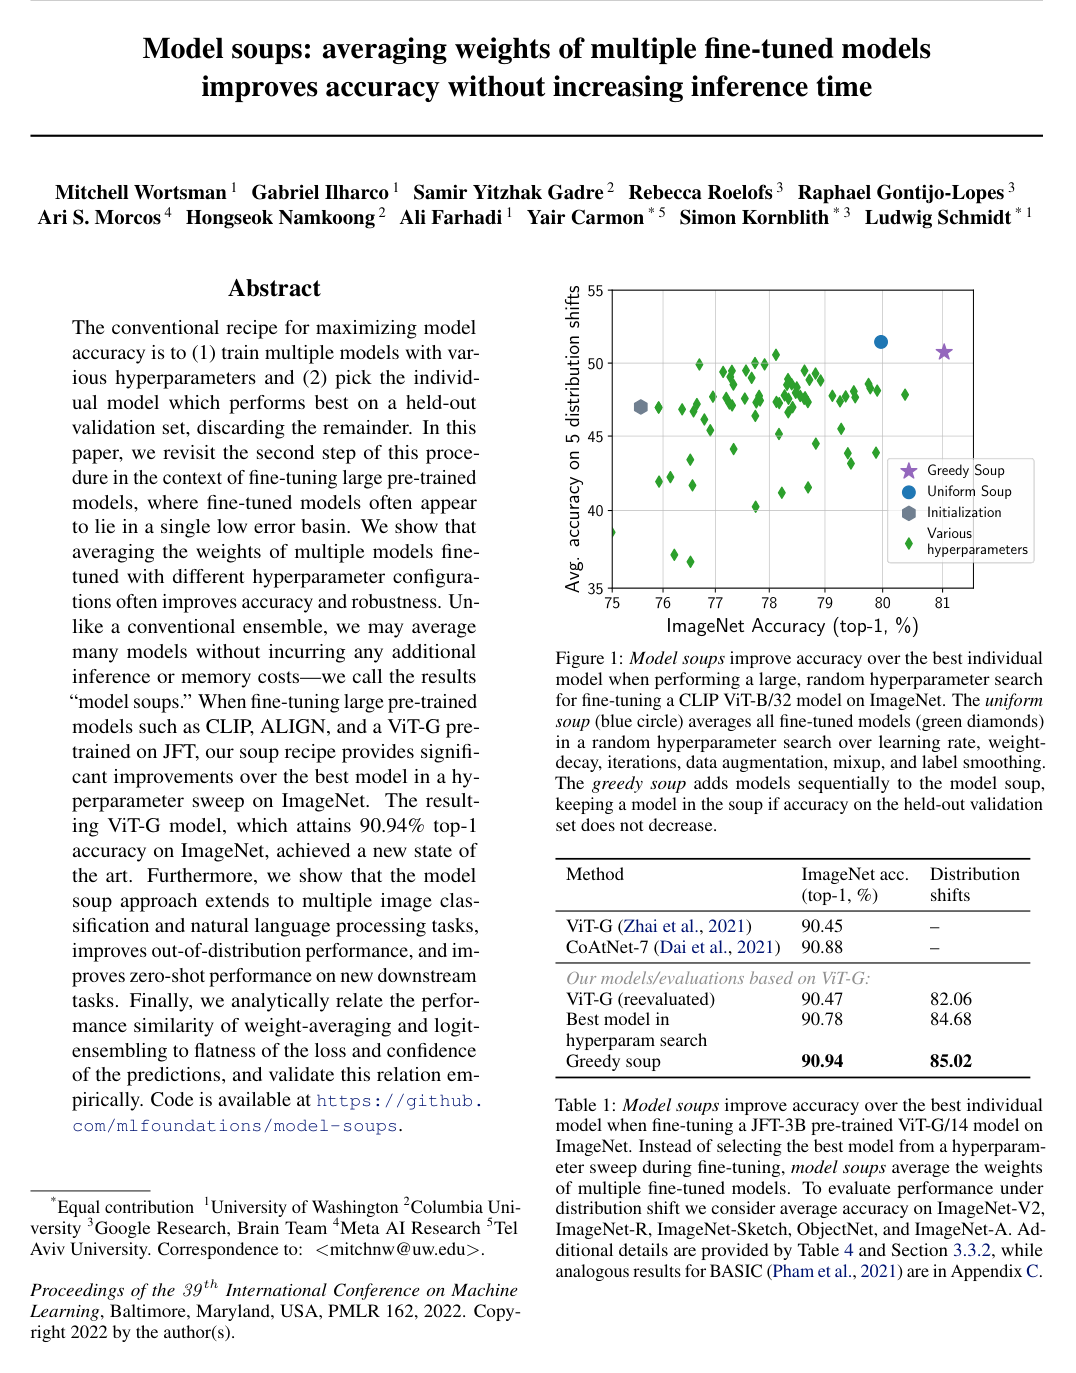
To evaluate this approach, the researchers conducted extensive empirical evaluations across vision architectures (including CLIP, ALIGN, BASIC, and ViT-G) and language transformer models (BERT and T5) across varied hyperparameter sweeps, data augmentations, and optimizers. The evaluation benchmarked standard validation performance as well as generalization under real-world distribution shifts. The core technique introduced, the greedy soup, sorts fine-tuned models by validation accuracy and sequentially blends their weights into an aggregate model only if the combination improves validation accuracy.
The primary finding is that greedy model soups consistently outperform the single best model identified during hyperparameter sweeps. Notably, applying a greedy soup to a large vision transformer (ViT-G) achieved a state-of-the-art 90.94% top-1 accuracy on ImageNet while utilizing 25% fewer floating-point operations during inference than the previous leading architecture. Second, model soups significantly enhance robustness against distribution shifts, often matching or exceeding the performance of traditional output ensembles without requiring multiple model evaluation passes. Third, the benefits generalize across modalities, delivering performance gains on multiple text classification tasks and cross-dataset zero-shot transfers.
These findings have immediate cost and operational implications for machine learning deployment. Practitioners can achieve ensemble-level accuracy and robustness directly from the intermediate outputs of standard hyperparameter searches at zero additional inference and serving cost. Unlike conventional ensembling, model soups require no architectural modifications or latency trade-offs in production.
Organizations fine-tuning foundation models should integrate greedy weight averaging into their deployment pipelines as a standard post-processing step rather than selecting a single checkpoint. For future development, teams can design hyperparameter sweeps to maximize model diversity, such as varying learning rates and augmentation strategies, to maximize the benefits of weight interpolation.
Decision-makers should note key boundaries: model soups require fine-tuned models to share the exact same pre-trained initialization, and performance gains are less substantial when pre-training data is small or homogeneous. Furthermore, while model soups reliably boost classification accuracy, they do not replicate the predictive calibration and uncertainty estimation improvements provided by traditional ensembles.
- Paper: Averaging Weights Leads to Wider Optima and Better Generalization, Pavel Izmailov et al. (2018). Introduces Stochastic Weight Averaging (SWA) along SGD trajectories, establishing the fundamental principle that weight averaging finds flatter loss basins and improves generalization without extra inference cost.
- Paper: Visualizing the Loss Landscape of Neural Nets, Hao Li et al. (2017). Provides the loss landscape visualization methodology and geometric insights into loss flatness and basins that underly the theoretical analysis of why weight-space averaging succeeds.
- Paper: Mean teachers are better role models: Weight-averaged consistency targets improve semi-supervised deep learning results, Antti Tarvainen et al. (2017). Demonstrates the practical efficacy of weight averaging across training steps to enhance stability and target quality in deep learning.
- Paper: Learning Transferable Visual Models From Natural Language Supervision, Alec Radford et al.. Introduces the CLIP vision-language foundation model architecture and zero-shot transfer paradigm that serves as a primary foundation for model soup fine-tuning experiments.
- Paper: Sigmoid Loss for Language Image Pre-Training, Xiaohua Zhai et al. (2023). Advances vision-language pre-training and downstream adaptation using sigmoid loss, building on foundation models and fine-tuning pipelines evaluated in model soup paradigms.
- Paper: DINOv2: Learning Robust Visual Features without Supervision, Maxime Oquab et al. (2023). Scales self-supervised vision transformer foundation models that directly benefit from zero-shot and downstream weight-averaging adaptation techniques.
- Paper: Intern VL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks, Zhe Chen et al. (2024). Extends large-scale vision-language foundation model scaling and multi-stage alignment where weight-space recipes and fine-tuning strategies can be deployed.
- Paper: Expanding Performance Boundaries of Open-Source Multimodal Models with Model, Data, and Test-Time Scaling, Zhe Chen et al. (2024). Explores multimodal foundation model scaling and post-training recipes that leverage advanced transfer and fine-tuning strategies.