Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting

Wei LinAntoni B. Chan

article2023CVPR62 citations

Proposes a parameter-free optimal transport minimization algorithm that converts predicted crowd density maps into precise point locations by minimizing Sinkhorn distance, enabling hard pseudo-label generation and confidence-weighted training for semi-supervised crowd counting.

Listen

Crowd analysis in computer vision is critical for public safety, surveillance, and traffic management. While modern deep neural networks effectively estimate overall crowd numbers through blurry density maps, they struggle to pinpoint the precise physical locations of individual people. Consequently, organizations often maintain separate, redundant computer vision systems for counting and localization. Additionally, training high-performing crowd models requires large, densely labeled datasets, which are expensive and labor-intensive to annotate.

The article develops and evaluates a parameter-free method called Optimal Transport Minimization (OT-M) to extract exact individual coordinates directly from crowd density maps without additional training. Furthermore, it demonstrates how this method can generate hard point annotations on unlabeled images to improve semi-supervised crowd counting.

The researchers designed an iterative algorithm that minimizes the mathematical transport cost between a continuous density map and discrete target points. Using this algorithm, they built a semi-supervised learning framework where a teacher network generates point locations for unlabeled images to train a student network. To mitigate incorrect pseudo-annotations, they introduced a confidence weighting mechanism. The framework was evaluated across multiple standard public crowd benchmarks, including UCF-QNRF, NWPU-Crowd, ShanghaiTech, and JHU++, across settings where only 5%, 10%, or 40% of training images had ground-truth labels.

The evaluation revealed several key findings. First, OT-M significantly outperformed existing density-based localization techniques, achieving an F-measure of 0.912 on UCF-QNRF compared to 0.840 for Gaussian mixture models and 0.807 for local peak detection. Second, in semi-supervised counting with limited labeled data (5% and 10%), the OT-M framework achieved the lowest counting errors and highest stability across all tested datasets. Third, ablation experiments showed that training with exact point annotations combined with confidence weighting reduced counting error metrics by over 12% compared to standard soft density supervision and unweighted losses.

These results demonstrate that organizations do not need separate, specialized networks to count and locate individuals simultaneously, lowering computational overhead and deployment costs. The approach also substantially reduces manual data annotation expenses, as models can be trained effectively on datasets where 90% to 95% of the images lack human annotations. While the algorithm's output quality remains constrained by the resolution and precision of the underlying density maps, the mathematical convergence and consistent empirical performance provide high confidence in adopting this method for operational crowd monitoring and semi-supervised computer vision pipelines.

  • Paper: Zero-Shot Object Counting, Jingyi Xu et al. (2023). It extends object counting beyond supervised and semi-supervised crowd scenarios into a zero-shot, text-prompted paradigm across diverse open-world categories.
Cover for Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting

Abstract

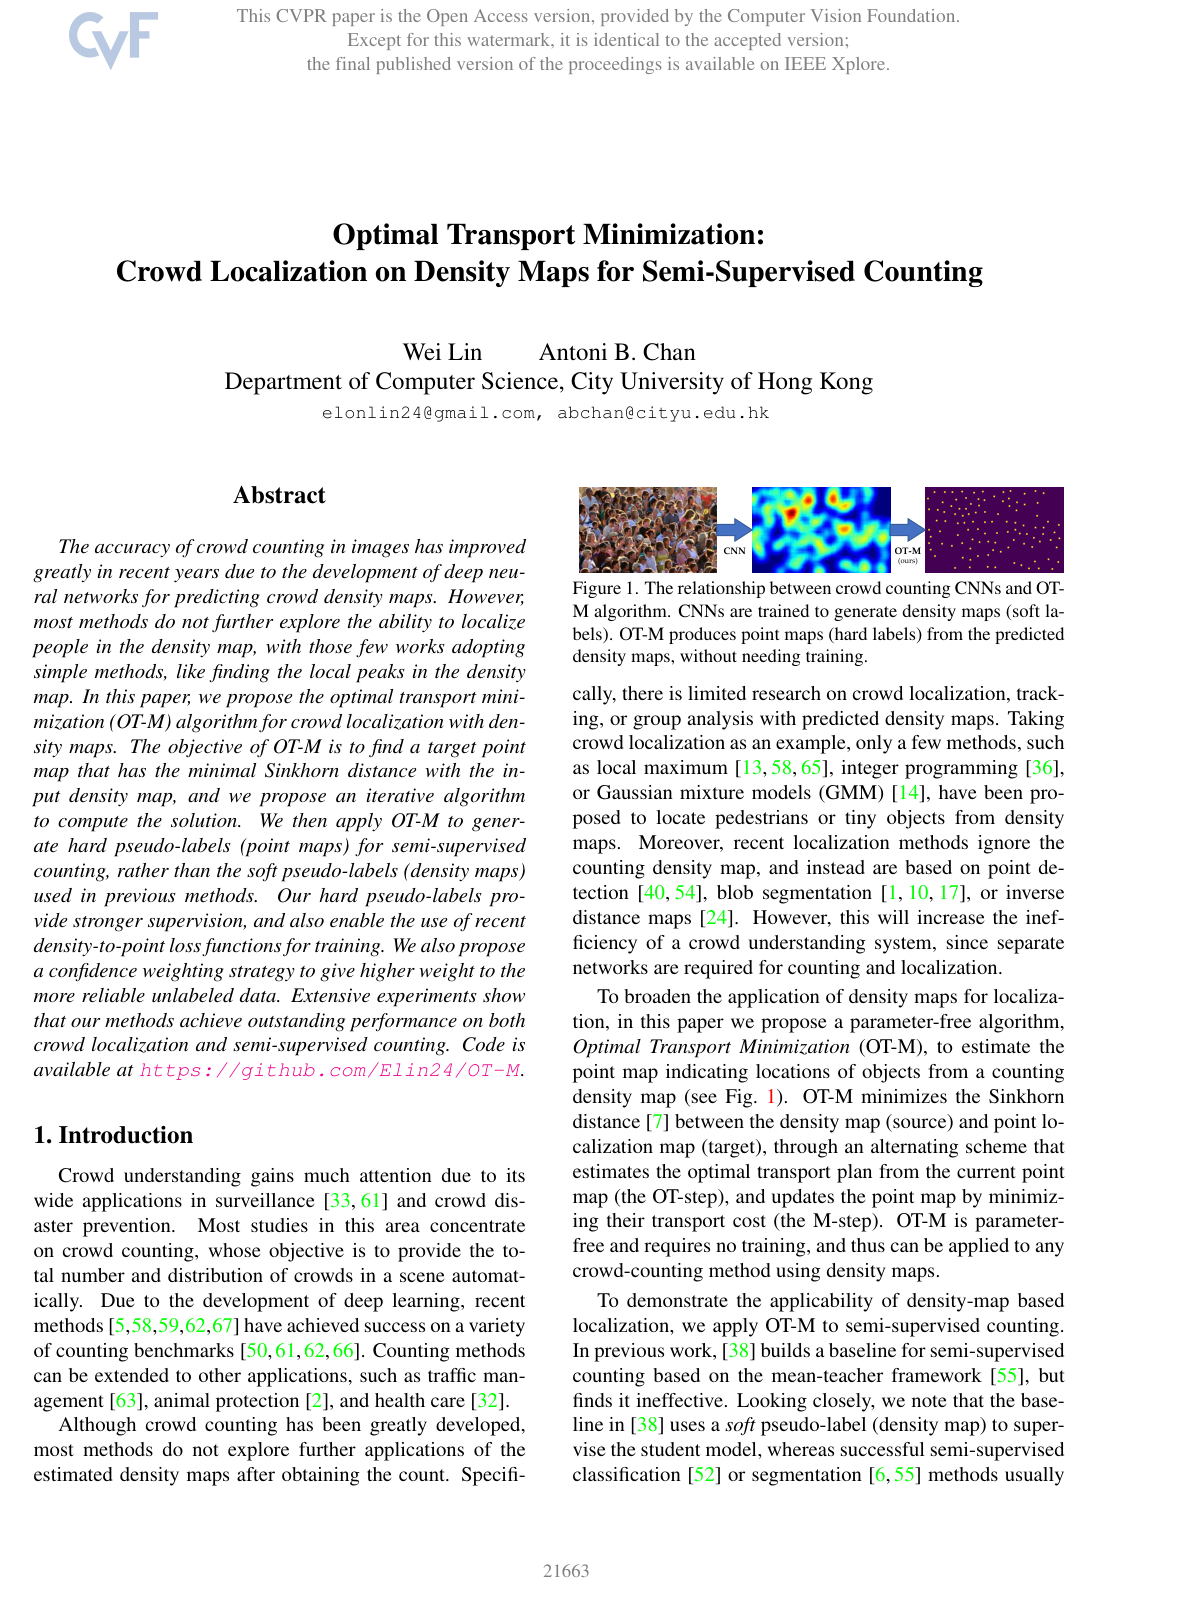
The accuracy of crowd counting in images has improved greatly in recent years due to the development of deep neural networks for predicting crowd density maps. However, most methods do not further explore the ability to localize people in the density map, with those few works adopting simple methods, like finding the local peaks in the density map. In this paper, we propose the optimal transport minimization (OT-M) algorithm for crowd localization with density maps. The objective of OT-M is to find a target point map that has the minimal Sinkhorn distance with the input density map, and we propose an iterative algorithm to compute the solution. We then apply OT-M to generate hard pseudo-labels (point maps) for semi-supervised counting, rather than the soft pseudo-labels (density maps) used in previous methods. Our hard pseudo-labels provide stronger supervision, and also enable the use of recent density-to-point loss functions for training. We also propose a confidence weighting strategy to give higher weight to the more reliable unlabeled data. Extensive experiments show that our methods achieve outstanding performance on both crowd localization and semi-supervised counting. Code is available at https://github.com/Elin24/OT-M.

Table of Contents

  • 1. Introduction
  • 2. Related works
  • 3. OT-M Algorithm
  • 3.1. Optimal Transport Step (OT-Step)
  • 3.2. Minimization step (M-Step)
  • 3.3. Convergence of the OT-M Algorithm
  • 4. OT-M Based Semi-Supervised Counting
  • 4.1. Generalized Loss with Gating
  • 4.2. Confidence Strategy
  • 5. Experiments
  • 5.1. Experiment setup
  • 5.2. Experiments on OT-M Convergence
  • 5.3. Localization Performance on Density Maps
  • 5.4. Semi-Supervised Counting
  • 5.5. Ablation Study on Semi-Supervised Counting
  • 6. Conclusion
  • References

Knowls

  1. Knowl 1 — Optimal Transport Minimization Algorithm for Crowd Localization on Density Maps

    algorithm

    The Optimal Transport Minimization (OT-M) algorithm is a parameter-free, training-free method to recover a discrete point localization map B={yj}j=1m\mathcal{B} = \{\mathbf{y}_j\}_{j=1}^m of individual object locations from a soft continuous counting density map A={(ai,xi)}i=1n\mathcal{A} = \{(a_i, \mathbf{x}_i)\}_{i=1}^n, where ai≥0a_i \ge 0 is the density value and xi∈R2\mathbf{x}_i \in \mathbb{R}^2 is the coordinate of the ii-th pixel among nn total pixels. The total number of points is set to the integrated density rounded to the nearest integer: m=⌊∑i=1nai⌉m = \lfloor \sum_{i=1}^n a_i \rceil, with unit point weights bj=1b_j = 1 for all j∈{1,…,m}j \in \{1, \dots, m\}.

    OT-M alternates between finding the optimal transport plan under the current point positions (the OT-step) and updating the point coordinates to the barycenters of the transported mass (the M-step).

    Input: Density map A={(ai,xi)}i=1n\mathcal{A} = \{(a_i, \mathbf{x}_i)\}_{i=1}^n, target count m=⌊∑i=1nai⌉m = \lfloor \sum_{i=1}^n a_i \rceil, entropic regularization parameter ε>0\varepsilon > 0, CNN downsampling ratio r=1/8r = 1/8, max iterations K=16K = 16.
    Output: Estimated point map B={yj}j=1m\mathcal{B} = \{\mathbf{y}_j\}_{j=1}^m.
    Initialize point positions B(0)={yj(0)}j=1m\mathcal{B}^{(0)} = \{\mathbf{y}_j^{(0)}\}_{j=1}^m (e.g., adaptive sampling based on normalized density values).
    Normalize density vector a=[a1,…,an]⊤\mathbf{a} = [a_1, \dots, a_n]^\top and point mass vector b=[1,…,1]⊤\mathbf{b} = [1, \dots, 1]^\top such that ∑iai=∑jbj=1\sum_i a_i = \sum_j b_j = 1.
    for k=1k = 1 to KK do:
        // OT-step: Compute cost matrix and Sinkhorn transport plan
        Compute cost matrix C(k)∈Rn×m\mathbf{C}^{(k)} \in \mathbb{R}^{n \times m} with Cij(k)=∥xi−yj(k−1)∥22C_{ij}^{(k)} = \|\mathbf{x}_i - \mathbf{y}_j^{(k-1)}\|_2^2.
        Compute Gibbs kernel K(k)=exp⁡(−C(k)/ε)\mathbf{K}^{(k)} = \exp(-\mathbf{C}^{(k)} / \varepsilon).
        Initialize scaling vector v(0)=1m\mathbf{v}^{(0)} = \mathbf{1}_m.
        repeat for Sinkhorn step l=0,1,…l = 0, 1, \dots until convergence:
            u(l+1)=a⊘(K(k)v(l))\mathbf{u}^{(l+1)} = \mathbf{a} \oslash (\mathbf{K}^{(k)} \mathbf{v}^{(l)})
            v(l+1)=b⊘((K(k))⊤u(l+1))\mathbf{v}^{(l+1)} = \mathbf{b} \oslash ((\mathbf{K}^{(k)})^\top \mathbf{u}^{(l+1)})
        Compute optimal transport plan P(k)=diag⁡(u)K(k)diag⁡(v)\mathbf{P}^{(k)} = \operatorname{diag}(\mathbf{u}) \mathbf{K}^{(k)} \operatorname{diag}(\mathbf{v}).
        // M-step: Update point coordinates to barycenters
        for j=1j = 1 to mm do:
            yj(k)=∑i=1nPij(k)xi∑i=1nPij(k)\mathbf{y}_j^{(k)} = \frac{\sum_{i=1}^n P_{ij}^{(k)} \mathbf{x}_i}{\sum_{i=1}^n P_{ij}^{(k)}}
        // Convergence check
        if 1m∑j=1m∥yj(k)−yj(k−1)∥2<1\frac{1}{m} \sum_{j=1}^m \|\mathbf{y}_j^{(k)} - \mathbf{y}_j^{(k-1)}\|_2 < 1 and max⁡j∥yj(k)−yj(k−1)∥2<1/r\max_j \|\mathbf{y}_j^{(k)} - \mathbf{y}_j^{(k-1)}\|_2 < 1/r then:
            break
    return B(k)\mathcal{B}^{(k)}
  2. Knowl 2 — Confidence-Weighted Generalized Loss

    equation

    The Confidence-Weighted Generalized Loss (C-GL) is defined for supervising crowd counting models via point-level annotations (ground-truth points or hard pseudo-points from OT-M) while mitigating the impact of inconsistent or noisy targets:

    Lc-glε,τ,γ=a⊤W2f∗+b⊤W1g∗−εH(P^)+τ2∥W2(P^1m−a)∥22+τ1∥W1(P^⊤1n−b)∥1L_{c\text{-}gl}^{\varepsilon, \tau, \gamma} = \mathbf{a}^\top \mathbf{W}_2 \mathbf{f}^* + \mathbf{b}^\top \mathbf{W}_1 \mathbf{g}^* - \varepsilon \mathcal{H}(\widehat{\mathbf{P}}) + \tau_2 \|\mathbf{W}_2 (\widehat{\mathbf{P}}\mathbf{1}_m - \mathbf{a})\|_2^2 + \tau_1 \|\mathbf{W}_1 (\widehat{\mathbf{P}}^\top \mathbf{1}_n - \mathbf{b})\|_1

    where:

    • a∈R+n\mathbf{a} \in \mathbb{R}^n_+ is the predicted density vector from the student network across nn pixels.
    • b=1m∈Rm\mathbf{b} = \mathbf{1}_m \in \mathbb{R}^m represents the target point vector for mm objects.
    • P^∈R+n×m\widehat{\mathbf{P}} \in \mathbb{R}^{n \times m}_+ is the transport plan obtained by solving Kullback-Leibler regularized Unbalanced Optimal Transport (KL-UOT) between a\mathbf{a} and b\mathbf{b}.
    • f∗∈Rn\mathbf{f}^* \in \mathbb{R}^n and g∗∈Rm\mathbf{g}^* \in \mathbb{R}^m are the optimal dual gradients of the transport problem with respect to a\mathbf{a} and b\mathbf{b}.
    • H(P^)=−∑i,jP^ijlog⁡(P^ij)\mathcal{H}(\widehat{\mathbf{P}}) = -\sum_{i,j} \widehat{P}_{ij} \log(\widehat{P}_{ij}) is the entropy of the transport plan, scaled by ε>0\varepsilon > 0.
    • W1=diag⁡(w1)\mathbf{W}_1 = \operatorname{diag}(\mathbf{w}_1) and W2=diag⁡(w2)\mathbf{W}_2 = \operatorname{diag}(\mathbf{w}_2) are diagonal confidence matrices assigned to target points and image pixels, respectively.
    • τ1,τ2≥0\tau_1, \tau_2 \ge 0 are gated marginal penalty parameters controlled by consistency checks.
  3. Knowl 3 — Optimal Transport Consistency-Based Confidence Estimation

    equation

    Given a predicted density map a∈R+n\mathbf{a} \in \mathbb{R}_+^n, a target point map b=1m∈Rm\mathbf{b} = \mathbf{1}_m \in \mathbb{R}^m, and their KL-UOT optimal transport plan P^∈R+n×m\widehat{\mathbf{P}} \in \mathbb{R}_+^{n \times m}, point-wise and pixel-wise confidence vectors are calculated based on transport marginal consistency:

    The point-wise confidence vector w1∈(0,1]m\mathbf{w}_1 \in (0, 1]^m measures how closely the total transported mass assigned to each point matches its target unit mass:

    w1=exp⁡(−γ(diag⁡(b)−1∣P^⊤1n−b∣))\mathbf{w}_1 = \exp\left( -\gamma \left( \operatorname{diag}(\mathbf{b})^{-1} |\widehat{\mathbf{P}}^\top \mathbf{1}_n - \mathbf{b}| \right) \right)

    where ∣⋅∣|\cdot| is the element-wise absolute value and γ>0\gamma > 0 is a decay hyperparameter (set to γ=0.5\gamma = 0.5).

    The pixel-wise confidence vector w2∈(0,1]n\mathbf{w}_2 \in (0, 1]^n is computed by propagating point confidences w1\mathbf{w}_1 back to pixels proportional to the normalized row mass of the transport plan:

    w2=diag⁡(P^1m)−1P^w1\mathbf{w}_2 = \operatorname{diag}(\widehat{\mathbf{P}} \mathbf{1}_m)^{-1} \widehat{\mathbf{P}} \mathbf{w}_1

    Pixels and points with high mutual transport consistency receive weights close to 11, whereas over-estimated and under-estimated regions receive small weights.

  4. Knowl 4 — Marginal Penalty Gating Scheme in Generalized Loss

    model/method

    In the Generalized Loss framework for crowd counting, the total transported mass mP^=∑i=1n∑j=1mP^ijm_{\widehat{\mathbf{P}}} = \sum_{i=1}^n \sum_{j=1}^m \widehat{P}_{ij}, the predicted density map count ma=∑i=1naim_{\mathbf{a}} = \sum_{i=1}^n a_i, and the ground-truth/pseudo-target count mb=∑j=1mbjm_{\mathbf{b}} = \sum_{j=1}^m b_j may experience ordering conflicts during Sinkhorn optimization. To prevent marginal penalties from pushing the network count in a direction opposite to the true error, the marginal penalty multipliers (τ1,τ2)(\tau_1, \tau_2) are gated as follows:

    τ1={0,if (ma<mb<mP^) or (mP^<mb<ma),τ,otherwise\tau_1 = \begin{cases} 0, & \text{if } (m_{\mathbf{a}} < m_{\mathbf{b}} < m_{\widehat{\mathbf{P}}}) \text{ or } (m_{\widehat{\mathbf{P}}} < m_{\mathbf{b}} < m_{\mathbf{a}}), \\ \tau, & \text{otherwise} \end{cases}

    τ2={0,if (mb<ma<mP^) or (mP^<ma<mb),τ,otherwise\tau_2 = \begin{cases} 0, & \text{if } (m_{\mathbf{b}} < m_{\mathbf{a}} < m_{\widehat{\mathbf{P}}}) \text{ or } (m_{\widehat{\mathbf{P}}} < m_{\mathbf{a}} < m_{\mathbf{b}}), \\ \tau, & \text{otherwise} \end{cases}

    where the default base weight is τ=0.1\tau = 0.1. For instance, when ma<mb<mP^m_{\mathbf{a}} < m_{\mathbf{b}} < m_{\widehat{\mathbf{P}}}, the predicted count is lower than the target count, but the L1L_1 marginal penalty on points would encourage mP^m_{\widehat{\mathbf{P}}} to decrease (pulling mam_{\mathbf{a}} down); setting τ1=0\tau_1 = 0 removes this conflicting gradient.

  5. Knowl 5 — Semi-Supervised Crowd Counting Pipeline via OT-M Pseudo-Labeling

    model/method

    The semi-supervised crowd counting framework adopts a Mean-Teacher architecture composed of a student network and a teacher network whose weights are updated via an Exponential Moving Average (EMA) of the student weights.

    1. Labeled Data Training: Labeled images are fed to the student network. Supervision is performed using ground-truth point maps via Confidence-Weighted Generalized Loss (C-GL) with γ=0.5\gamma = 0.5 to account for annotation noise.
    2. Unlabeled Data Pseudo-Labeling: Unperturbed unlabeled images are fed to the teacher network to produce a soft density map at\mathbf{a}_t. The OT-M algorithm is applied to at\mathbf{a}_t without learning to generate a discrete, hard pseudo-label point map bt={yj}j=1m\mathbf{b}_t = \{\mathbf{y}_j\}_{j=1}^m, where m=⌊∑iat,i⌉m = \lfloor \sum_i a_{t,i} \rceil.
    3. Unlabeled Data Consistency Training: The same unlabeled images undergo data perturbations and are passed into the student network to output predicted density maps as\mathbf{a}_s. The student's prediction as\mathbf{a}_s is supervised by the hard pseudo-label point map bt\mathbf{b}_t using the Confidence-Weighted Generalized Loss (C-GL), which depresses the influence of inconsistent teacher-student predictions.
  6. Knowl 6 — Monotonic Convergence of the OT-M Objective

    theoretical result

    For a fixed density map A\mathcal{A} and point set B={yj}j=1m\mathcal{B} = \{\mathbf{y}_j\}_{j=1}^m with squared Euclidean transport cost C(xi,yj)=∥xi−yj∥22C(\mathbf{x}_i, \mathbf{y}_j) = \|\mathbf{x}_i - \mathbf{y}_j\|_2^2, the alternating minimization scheme of OT-M strictly non-increases the Sinkhorn distance objective at every iteration kk:

    ⟨C(k),P(k)⟩−εH(P(k))≤⟨C(k−1),P(k−1)⟩−εH(P(k−1))\langle \mathbf{C}^{(k)}, \mathbf{P}^{(k)} \rangle - \varepsilon \mathcal{H}(\mathbf{P}^{(k)}) \le \langle \mathbf{C}^{(k-1)}, \mathbf{P}^{(k-1)} \rangle - \varepsilon \mathcal{H}(\mathbf{P}^{(k-1)})

    where C(k)=C(B(k−1))\mathbf{C}^{(k)} = \mathbf{C}(\mathcal{B}^{(k-1)}) is the cost matrix at iteration kk, P(k)\mathbf{P}^{(k)} is the optimal transport plan obtained in the OT-step, and B(k)\mathcal{B}^{(k)} is the barycentric point update obtained in the M-step. Consequently, OT-M monotonically converges to a local minimum.

  7. Knowl 7 — Crowd Localization Performance on UCF-QNRF and NWPU-Crowd Datasets

    data/table

    OT-M was evaluated against Local Maximum (LM) and Gaussian Mixture Models (GMM) on density maps generated by ground truth (downsampled by 1/8) and various crowd counting models (GL, MAN, ChfL) on UCF-QNRF, as well as on NWPU-Crowd.

    Density Map Localization Precision Recall F-measure
    Ground-truth (1/8 downsampled) LM 0.892 0.736 0.807
    GMM 0.842 0.838 0.840
    OT-M (ours) 0.914 0.910 0.912
    GL (VGG-19, stride 8) LM 0.782 0.748 0.765
    GMM 0.750 0.728 0.739
    OT-M (ours) 0.804 0.783 0.793
    MAN (Transformer, stride 16) LM 0.624 0.483 0.544
    GMM 0.749 0.732 0.736
    OT-M (ours) 0.772 0.755 0.760
    ChfL (stride 8) LM 0.812 0.571 0.671
    GMM 0.755 0.740 0.747
    OT-M (ours) 0.780 0.765 0.772

    On the NWPU-Crowd test set, localization with GL density maps achieves:

    • Faster R-CNN (box): Precision 0.958, Recall 0.035, F-measure 0.068
    • RAZNet (density): Precision 0.666, Recall 0.543, F-measure 0.599
    • GL + LM (density): Precision 0.800, Recall 0.562, F-measure 0.660
    • GL + OT-M (density, ours): Precision 0.710, Recall 0.658, F-measure 0.683
    • CLTR (point): Precision 0.694, Recall 0.676, F-measure 0.685
    • P2PNet (point): Precision 0.729, Recall 0.695, F-measure 0.712

    OT-M consistently achieves superior recall and overall F-measure across all density map backbones compared to LM and GMM.

  8. Knowl 8 — Semi-Supervised Crowd Counting Benchmark Results Across 5 Random Trials

    data/table

    Semi-supervised crowd counting performance evaluated across 5 random trials (reporting mean ±\pm standard deviation of MAE and MSE) across ShanghaiTech-A (ST-A), ShanghaiTech-B (ST-B), UCF-QNRF, and JHU++ under 5%, 10%, and 40% labeled data splits:

    Label Methods ST-A ST-B UCF-QNRF JHU++
    % MAE MSE MAE MSE MAE MSE MAE MSE
    5% DAC 92.9±\pm3.4 148.6±\pm10.3 13.4±\pm2.2 24.6±\pm6.7 122.7±\pm7.8 218.9±\pm14.0 81.2±\pm2.4 313.7±\pm12.2
    OT-M (ours) 86.0±\pm2.2 132.7±\pm3.3 12.8±\pm1.4 22.0±\pm4.5 120.1±\pm7.3 208.9±\pm11.7 80.9±\pm3.1 303.1±\pm9.5
    10% DAC 84.8±\pm4.5 140.9±\pm11.3 11.1±\pm0.5 18.9±\pm1.9 110.5±\pm5.9 196.0±\pm16.3 76.0±\pm2.0 293.8±\pm10.4
    OT-M (ours) 81.6±\pm2.6 127.1±\pm3.8 10.9±\pm0.5 18.1±\pm1.4 107.9±\pm4.1 180.6±\pm7.8 75.5±\pm1.6 287.9±\pm11.1
    40% DAC 71.6±\pm2.0 120.8±\pm5.6 9.0±\pm0.3 14.6±\pm0.5 91.8±\pm4.7 161.4±\pm12.4 64.1±\pm3.0 270.6±\pm9.3
    OT-M (ours) 70.0±\pm2.2 113.0±\pm6.9 9.0±\pm0.4 14.2±\pm0.7 93.4±\pm5.4 157.5±\pm7.8 66.5±\pm3.1 268.2±\pm9.5

    OT-M combined with C-GL consistently outperforms DAC across all four benchmarks at 5% and 10% labeled data ratios, demonstrating lower estimation error and reduced standard deviation across trials.

  9. Knowl 9 — Ablation Analysis of Loss Components, Pseudo-Label Types, and Localization Methods

    empirical result

    Ablation studies conducted on UCF-QNRF using the 5% labeled data setting demonstrate the individual contribution of each component:

    1. Loss Components on Labeled Data Only:

      • Baseline GL (no gating, no confidence): MAE 145.59, MSE 257.31
      • With (τ1,τ2)(\tau_1, \tau_2) Gating: MAE 144.48, MSE 255.33
      • With Gating and Confidence Weighting (C-GL, γ=0.5\gamma = 0.5): MAE 138.52, MSE 242.26
    2. Supervision Format on Unlabeled Data (Label + Unlabel):

      • Soft pseudo-labels with standard L2L_2 loss: MAE 137.17, MSE 239.52
      • Soft pseudo-labels with confidence-weighted L2L_2 loss: MAE 135.88, MSE 233.19
      • Hard pseudo-labels (OT-M) with standard GL: MAE 125.32, MSE 214.96
      • Hard pseudo-labels (OT-M) with C-GL: MAE 120.13, MSE 208.87
    3. Choice of Density-Map Localization Algorithm for Generating Hard Pseudo-Labels (Mean ±\pm Std):

      • Labeled only baseline: MAE 138.52 ±\pm 10.65, MSE 242.26 ±\pm 16.62
      • Local Maximum (LM): MAE 148.53 ±\pm 9.53, MSE 270.25 ±\pm 23.67
      • Gaussian Mixture Models (GMM): MAE 126.67 ±\pm 7.41, MSE 217.00 ±\pm 16.17
      • OT-M (ours): MAE 120.13 ±\pm 7.34, MSE 208.87 ±\pm 11.65

    LM deteriorates performance compared to the labeled-only baseline because the number of local maxima is not constrained to match the integrated density map sum.

Coverage note — Single-trial semi-supervised counting comparison numbers (Table 3) were omitted in favor of the more comprehensive 5-trial multi-split benchmark results (Table 4) and full ablation tables.

References

  1. 1.Shahira Abousamra, Minh Hoai, Dimitris Samaras, and Chao Chen. Localization in the crowd with topological constraints. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 35, pages 872–881, 2021.
  2. 2.Carlos Arteta, Victor Lempitsky, and Andrew Zisserman. Counting in the wild. In European conference on computer vision, pages 483–498. Springer, 2016.
  3. 3.Deepak Babu Sam, Shiv Surya, and R Venkatesh Babu. Switching convolutional neural network for crowd counting. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 5744–5752, 2017.
  4. 4.Antoni B Chan and Nuno Vasconcelos. Bayesian poisson regression for crowd counting. In 2009 IEEE 12th international conference on computer vision, pages 545–551. IEEE, 2009.
  5. 5.Antoni B Chan and Nuno Vasconcelos. Counting people with low-level features and bayesian regression. IEEE Transactions on image processing, 21(4):2160–2177, 2011.
  6. 6.Xiaokang Chen, Yuhui Yuan, Gang Zeng, and Jingdong Wang. Semi-supervised semantic segmentation with cross pseudo supervision. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 2613–2622, 2021.
  7. 7.Marco Cuturi. Sinkhorn distances: Lightspeed computation of optimal transport. Advances in neural information processing systems, 26, 2013.
  8. 8.Jean Feydy, Thibault Sejourne, Francois-Xavier Vialard, Shun-ichi Amari, Alain Trouve, and Gabriel Peyre. Interpolating between optimal transport and mmd using sinkhorn divergences. In The 22nd International Conference on Artificial Intelligence and Statistics, pages 2681–2690. PMLR, 2019.
  9. 9.Geoffrey French, Samuli Laine, Timo Aila, Michal Mackiewicz, and Graham D. Finlayson. Semi-supervised semantic segmentation needs strong, varied perturbations. In 31st British Machine Vision Conference, 2020.
  10. 10.Junyu Gao, Tao Han, Yuan Yuan, and Qi Wang. Learning independent instance maps for crowd localization. arXiv preprint arXiv:2012.04164, 2020.
  11. 11.Junyu Gao, Qi Wang, and Xuelong Li. Pcc net: Perspective crowd counting via spatial convolutional network. IEEE Transactions on Circuits and Systems for Video Technology, 30(10):3486–3498, 2019.
  12. 12.Haroon Idrees, Imran Saleemi, Cody Seibert, and Mubarak Shah. Multi-source multi-scale counting in extremely dense crowd images. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 2547–2554, 2013.
  13. 13.Haroon Idrees, Muhmmad Tayyab, Kishan Athrey, Dong Zhang, Somaya Al-Maadeed, Nasir Rajpoot, and Mubarak Shah. Composition loss for counting, density map estimation and localization in dense crowds. In Proceedings of the European conference on computer vision (ECCV), pages 532–546, 2018.
  14. 14.Di Kang, Zheng Ma, and Antoni B Chan. Beyond counting: comparisons of density maps for crowd analysis tasks—counting, detection, and tracking. IEEE Transactions on Circuits and Systems for Video Technology, 29(5):1408–1422, 2018.
  15. 15.Donghyeon Kwon and Suha Kwak. Semi-supervised semantic segmentation with error localization network. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 9957–9967, 2022.
  16. 16.Samuli Laine and Timo Aila. Temporal ensembling for semi-supervised learning. arXiv preprint arXiv:1610.02242, 2016.
  17. 17.Issam H Laradji, Negar Rostamzadeh, Pedro O Pinheiro, David Vazquez, and Mark Schmidt. Where are the blobs: Counting by localization with point supervision. In Proceedings of the European Conference on Computer Vision (ECCV), pages 547–562, 2018.
  18. 18.Dong-Hyun Lee et al. Pseudo-label: The simple and efficient semi-supervised learning method for deep neural networks. In Workshop on challenges in representation learning, ICML, volume 3, page 896, 2013.
  19. 19.Bastian Leibe, Edgar Seemann, and Bernt Schiele. Pedestrian detection in crowded scenes. In 2005 IEEE computer society conference on computer vision and pattern recognition (CVPR'05), volume 1, pages 878–885. IEEE, 2005.
  20. 20.Victor Lempitsky and Andrew Zisserman. Learning to count objects in images. Advances in neural information processing systems, 23, 2010.
  21. 21.Victor Lempitsky and Andrew Zisserman. Learning to count objects in images. Advances in neural information processing systems, 23, 2010.
  22. 22.Yuhong Li, Xiaofan Zhang, and Deming Chen. Csrnet: Dilated convolutional neural networks for understanding the highly congested scenes. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 1091–1100, 2018.
  23. 23.Dingkang Liang, Wei Xu, and Xiang Bai. An end-to-end transformer model for crowd localization. In Proceedings of the European conference on computer vision, volume 13661, pages 38–54, 2022.
  24. 24.Dingkang Liang, Wei Xu, Yingying Zhu, and Yu Zhou. Focal inverse distance transform maps for crowd localization. IEEE Transactions on Multimedia, pages 1–13, 2022.
  25. 25.Hui Lin, Xiaopeng Hong, Zhiheng Ma, Xing Wei, Yunfeng Qiu, Yaowei Wang, and Yihong Gong. Direct measure matching for crowd counting. In Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, pages 837–844, 8 2021.
  26. 26.Hui Lin, Zhiheng Ma, Xiaopeng Hong, Yaowei Wang, and Zhou Su. Semi-supervised crowd counting via density agency. In ACM Multimedia, 2022.
  27. 27.Hui Lin, Zhiheng Ma, Rongrong Ji, Yaowei Wang, and Xiaopeng Hong. Boosting crowd counting via multifaceted attention. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 19628–19637, 2022.
  28. 28.Chenchen Liu, Xinyu Weng, and Yadong Mu. Recurrent attentive zooming for joint crowd counting and precise localization. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 1217–1226, 2019.
  29. 29.Xialei Liu, Joost Van De Weijer, and Andrew D Bagdanov. Leveraging unlabeled data for crowd counting by learning to rank. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 7661–7669, 2018.
  30. 30.Xialei Liu, Joost Van De Weijer, and Andrew D Bagdanov. Exploiting unlabeled data in cnns by self-supervised learning to rank. IEEE transactions on pattern analysis and machine intelligence, 41(8):1862–1878, 2019.
  31. 31.Yan Liu, Lingqiao Liu, Peng Wang, Pingping Zhang, and Yinjie Lei. Semi-supervised crowd counting via self-training on surrogate tasks. In European Conference on Computer Vision, pages 242–259. Springer, 2020.
  32. 32.Erika Lu, Weidi Xie, and Andrew Zisserman. Class-agnostic counting. In Asian conference on computer vision, pages 669–684. Springer, 2018.
  33. 33.Zheng Ma and Antoni B Chan. Counting people crossing a line using integer programming and local features. IEEE Transactions on Circuits and Systems for Video Technology, 26(10):1955–1969, 2015.
  34. 34.Zhiheng Ma, Xing Wei, Xiaopeng Hong, and Yihong Gong. Bayesian loss for crowd count estimation with point supervision. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 6142–6151, 2019.
  35. 35.Zhiheng Ma, Xing Wei, Xiaopeng Hong, Hui Lin, Yunfeng Qiu, and Yihong Gong. Learning to count via unbalanced optimal transport. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 35, pages 2319–2327, 2021.
  36. 36.Zheng Ma, Lei Yu, and Antoni B Chan. Small instance detection by integer programming on object density maps. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 3689–3697, 2015.
  37. 37.Gonzalo Mena, Amin Nejatbakhsh, Erdem Varol, and Jonathan Niles-Weed. Sinkhorn em: an expectation-maximization algorithm based on entropic optimal transport. arXiv preprint arXiv:2006.16548, 2020.
  38. 38.Yanda Meng, Hongrun Zhang, Yitian Zhao, Xiaoyun Yang, Xuesheng Qian, Xiaowei Huang, and Yalin Zheng. Spatial uncertainty-aware semi-supervised crowd counting. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 15549–15559, 2021.
  39. 39.Todd K Moon. The expectation-maximization algorithm. IEEE Signal processing magazine, 13(6):47–60, 1996.
  40. 40.Lin Niu, Xinggang Wang, Chen Duan, Qiongxia Shen, and Wenyu Liu. Local point matching network for stabilized crowd counting and localization. In Chinese Conference on Pattern Recognition and Computer Vision (PRCV), pages 566–579. Springer, 2022.
  41. 41.Gabriel Peyre, Marco Cuturi, et al. Computational optimal transport: With applications to data science. Foundations and Trends◯ R in Machine Learning, 11(5-6):355–607, 2019.
  42. 42.Shaoqing Ren, Kaiming He, Ross Girshick, and Jian Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. Advances in neural information processing systems, 28, 2015.
  43. 43.Weihong Ren, Di Kang, Yandong Tang, and Antoni B Chan. Fusing crowd density maps and visual object trackers for people tracking in crowd scenes. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 5353–5362, 2018.
  44. 44.Weihong Ren, Xinchao Wang, Jiandong Tian, Yandong Tang, and Antoni B Chan. Tracking-by-counting: Using network flows on crowd density maps for tracking multiple targets. IEEE Transactions on Image Processing, 30:1439–1452, 2020.
  45. 45.Mikel Rodriguez, Ivan Laptev, Josef Sivic, and Jean-Yves Audibert. Density-aware person detection and tracking in crowds. In 2011 International Conference on Computer Vision, pages 2423–2430. IEEE, 2011.
  46. 46.Bernhard Schmitzer. Stabilized sparse scaling algorithms for entropy regularized transport problems. SIAM Journal on Scientific Computing, 41(3):A1443–A1481, 2019.
  47. 47.Weibo Shu, Jia Wan, Kay Chen Tan, Sam Kwong, and Antoni B Chan. Crowd counting in the frequency domain. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 19618–19627, 2022.
  48. 48.Karen Simonyan and Andrew Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556, 2014.
  49. 49.Vishwanath A Sindagi, Rajeev Yasarla, Deepak Sam Babu, R Venkatesh Babu, and Vishal M Patel. Learning to count in the crowd from limited labeled data. In European Conference on Computer Vision, pages 212–229. Springer, 2020.
  50. 50.Vishwanath A Sindagi, Rajeev Yasarla, and Vishal M Patel. Jhu-crowd++: Large-scale crowd counting dataset and a benchmark method. Technical Report, 2020.
  51. 51.Richard Sinkhorn. A relationship between arbitrary positive matrices and doubly stochastic matrices. The annals of mathematical statistics, 35(2):876–879, 1964.
  52. 52.Kihyuk Sohn, David Berthelot, Nicholas Carlini, Zizhao Zhang, Han Zhang, Colin A Raffel, Ekin Dogus Cubuk, Alexey Kurakin, and Chun-Liang Li. Fixmatch: Simplifying semi-supervised learning with consistency and confidence. Advances in neural information processing systems, 33:596–608, 2020.
  53. 53.Kihyuk Sohn, David Berthelot, Nicholas Carlini, Zizhao Zhang, Han Zhang, Colin A Raffel, Ekin Dogus Cubuk, Alexey Kurakin, and Chun-Liang Li. Fixmatch: Simplifying semi-supervised learning with consistency and confidence. Advances in neural information processing systems, 33:596–608, 2020.
  54. 54.Qingyu Song, Changan Wang, Zhengkai Jiang, Yabiao Wang, Ying Tai, Chengjie Wang, Jilin Li, Feiyue Huang, and Yang Wu. Rethinking counting and localization in crowds: A purely point-based framework. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 3365–3374, 2021.
  55. 55.Antti Tarvainen and Harri Valpola. Mean teachers are better role models: Weight-averaged consistency targets improve semi-supervised deep learning results. Advances in neural information processing systems, 30, 2017.
  56. 56.Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. Advances in neural information processing systems, 30, 2017.
  57. 57.Jia Wan and Antoni Chan. Modeling noisy annotations for crowd counting. Advances in Neural Information Processing Systems, 33:3386–3396, 2020.
  58. 58.Jia Wan, Ziquan Liu, and Antoni B Chan. A generalized loss function for crowd counting and localization. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 1974–1983, 2021.
  59. 59.Jia Wan, Qingzhong Wang, and Antoni B Chan. Kernel-based density map generation for dense object counting. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2020.
  60. 60.Boyu Wang, Huidong Liu, Dimitris Samaras, and Minh Hoai Nguyen. Distribution matching for crowd counting. Advances in neural information processing systems, 33:1595–1607, 2020.
  61. 61.Qi Wang, Junyu Gao, Wei Lin, and Xuelong Li. Nwpu-crowd: A large-scale benchmark for crowd counting and localization. IEEE transactions on pattern analysis and machine intelligence, 43(6):2141–2149, 2020.
  62. 62.Qi Wang, Junyu Gao, Wei Lin, and Yuan Yuan. Learning from synthetic data for crowd counting in the wild. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 8198–8207, 2019.
  63. 63.Qi Wang, Jia Wan, and Yuan Yuan. Locality constraint distance metric learning for traffic congestion detection. Pattern Recognition, 75:272–281, 2018.
  64. 64.Qizhe Xie, Minh-Thang Luong, Eduard Hovy, and Quoc V Le. Self-training with noisy student improves imagenet classification. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 10687–10698, 2020.
  65. 65.Ji Zhang, Zhi-Qi Cheng, Xiao Wu, Wei Li, and Jian-Jun Qiao. Crossnet: Boosting crowd counting with localization. In Proceedings of the 30th ACM International Conference on Multimedia, pages 6436–6444, 2022.
  66. 66.Qi Zhang, Wei Lin, and Antoni B Chan. Cross-view cross-scene multi-view crowd counting. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 557–567, 2021.
  67. 67.Yingying Zhang, Desen Zhou, Siqin Chen, Shenghua Gao, and Yi Ma. Single-image crowd counting via multi-column convolutional neural network. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 589–597, 2016.
  68. 68.Yuliang Zou, Zizhao Zhang, Han Zhang, Chun-Liang Li, Xiao Bian, Jia-Bin Huang, and Tomas Pfister. Pseudoseg: Designing pseudo labels for semantic segmentation. In 9th International Conference on Learning Representations, 2021.

Citation

MLA
Lin, W., and A. B. Chan. “Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting”. 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023, pp. 21663–73, https://doi.org/10.1109/CVPR52729.2023.02075.
APA
Lin, W., & Chan, A. B. (2023). Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting. 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 21663–21673. https://doi.org/10.1109/CVPR52729.2023.02075
Chicago
Lin, W., and A. B. Chan. 2023. “Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting”. 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 21663–73. https://doi.org/10.1109/CVPR52729.2023.02075.
Harvard
Lin, W. and Chan, A.B. (2023) “Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting”, 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). IEEE, pp. 21663–21673. Available at: https://doi.org/10.1109/CVPR52729.2023.02075.
Vancouver
1. Lin W, Chan AB (2023) Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting. In: 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). IEEE, pp 21663–21673

BibTeX

@inproceedings{Lin_2023, title={Optimal Transport Minimization: Crowd Localization on Density Maps for Semi-Supervised Counting}, url={http://dx.doi.org/10.1109/CVPR52729.2023.02075}, DOI={10.1109/cvpr52729.2023.02075}, booktitle={2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)}, publisher={IEEE}, author={Lin, Wei and Chan, Antoni B.}, year={2023}, month=June, pages={21663–21673} }
Metadata:Crossref

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: IEEE