Built independently by an author, for readers. Read the story and support ChapterPal

keyword

Temporal Warping Augmentation

Temporal warping augmentation is a video data augmentation technique that alters the timing dynamics of a video sequence by stretching, compressing, or irregularly spacing selected frames across different temporal durations. By modifying the playback rate and duration of specific segments within a clip, this method simulates non-linear variations in motion, such as acceleration, deceleration, and momentary pauses. It enhances the robustness and generalization of machine learning models for tasks such as action recognition by exposing them to diverse speed profiles and temporal variations without altering the underlying semantic content of the actions.

1 item

SVFormer: Semi-supervised Video Transformer for Action Recognition

SVFormer: Semi-supervised Video Transformer for Action Recognition

Zhen Xing, Qi Dai, Han Hu, Jingjing Chen, Zuxuan Wu, Yu-Gang Jiang

OrganizationsFudan UniversityMicrosoftShanghai Collaborative Innovation Center of Intelligent Visual Computing

Why you should read this

Presents SVFormer, a semi-supervised video transformer framework combining an exponential moving average teacher with specialized tube-level token mixing and temporal warping augmentations to substantially improve action recognition performance under extremely limited supervision.

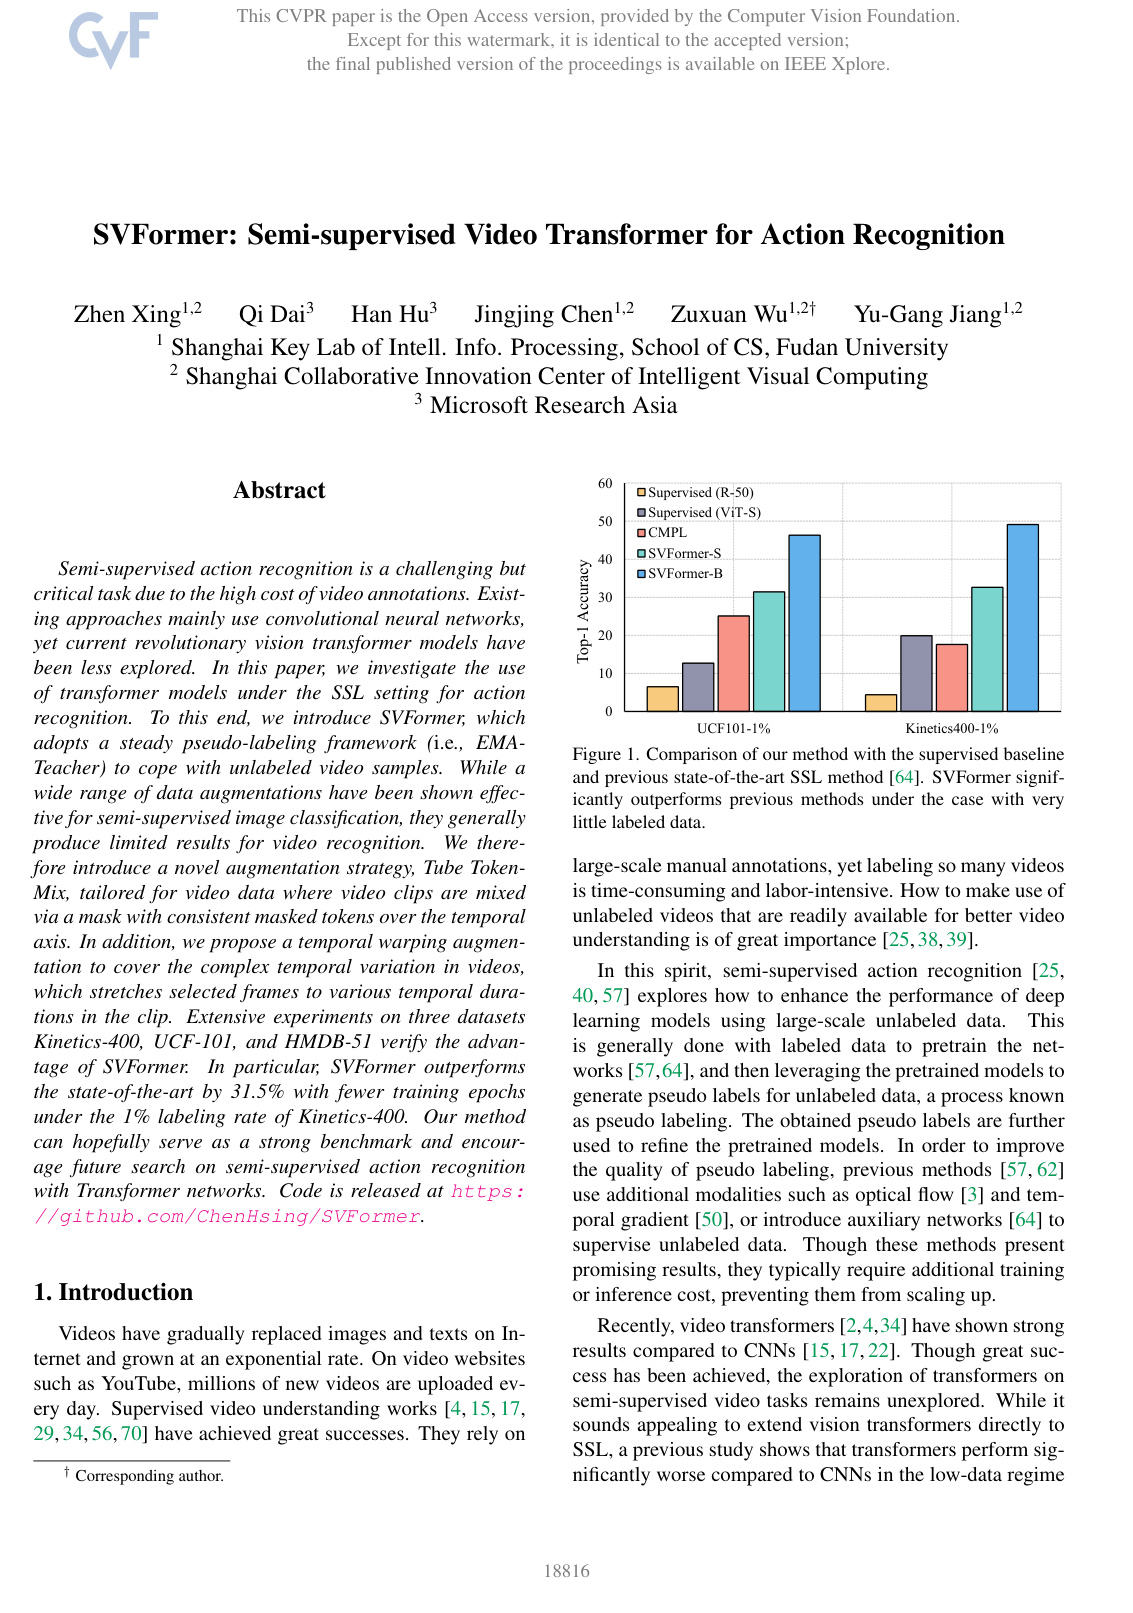
Semi-supervised action recognition is a challenging but critical task due to the high cost of video annotations. Existing approaches mainly use convolutional neural networks, yet current revolutionary vision transformer models have been less explored. In this paper, we investigate the use of transformer models under the SSL setting for action recognition. To this end, we introduce SVFormer, which adopts a steady pseudo-labeling framework (i.e., EMA-Teacher) to cope with unlabeled video samples. While a wide range of data augmentations have been shown effective for semi-supervised image classification, they generally produce limited results for video recognition. We therefore introduce a novel augmentation strategy, Tube TokenMix, tailored for video data where video clips are mixed via a mask with consistent masked tokens over the temporal axis. In addition, we propose a temporal warping augmentation to cover the complex temporal variation in videos, which stretches selected frames to various temporal durations in the clip. Extensive experiments on three datasets Kinetics-400, UCF-101, and HMDB-51 verify the advantage of SVFormer. In particular, SVFormer outperforms the state-of-the-art by 31.5% with fewer training epochs under the 1% labeling rate of Kinetics-400. Our method can hopefully serve as a strong benchmark and encourage future search on semi-supervised action recognition with Transformer networks. Code is released at https://github.com/ChenHsing/SVFormer.

Added

2026-09-26