
keyword
spatial pyramid matching
Spatial pyramid matching is a computer vision and image representation technique that captures the spatial layout of an image by repeatedly dividing it into increasingly fine grid cells and computing local feature summaries within each cell. Unlike traditional bag-of-features approaches that discard the spatial positions of visual elements, spatial pyramid matching constructs a multi-resolution hierarchy of sub-regions across varying grid scales and pools feature histograms at each level. The histograms across all subdivisions and levels are concatenated or compared using a weighted similarity kernel, assigning greater importance to feature matches found at finer spatial resolutions. By preserving both coarse global composition and localized geometric structure, this method facilitates accurate image categorization, scene understanding, and object recognition.
5 items
A Survey on Object Detection in Optical Remote Sensing Images
Gong Cheng, Junwei Han
Why you should read this
Systematizes approximately 270 generic object detection studies across aerial and satellite imagery into four core methodological paradigms while reviewing standard benchmarks, evaluation metrics, and future opportunities in deep and weakly supervised learning.
Object detection in optical remote sensing images, being a fundamental but challenging problem in the field of aerial and satellite image analysis, plays an important role for a wide range of applications and is receiving significant attention in recent years. While enormous methods exist, a deep review of the literature concerning generic object detection is still lacking. This paper aims to provide a review of the recent progress in this field. Different from several previously published surveys that focus on a specific object class such as building and road, we concentrate on more generic object categories including, but are not limited to, road, building, tree, vehicle, ship, airport, urban-area. Covering about 270 publications we survey 1) template matching-based object detection methods, 2) knowledge-based object detection methods, 3) object-based image analysis (OBIA)-based object detection methods, 4) machine learning-based object detection methods, and 5) five publicly available datasets and three standard evaluation metrics. We also discuss the challenges of current studies and propose two promising research directions, namely deep learning-based feature representation and weakly supervised learning-based geospatial object detection. It is our hope that this survey will be beneficial for the researchers to have better understanding of this research field.
Added
2026-09-25
AID: A Benchmark Data Set for Performance Evaluation of Aerial Scene Classification
Gui-Song Xia, Jingwen Hu, Fan Hu, Baoguang Shi, Xiang Bai, Yanfei Zhong, Liangpei Zhang, Xiaoqiang Lu
Why you should read this
Introduces the Aerial Image Dataset (AID), a large-scale benchmark of over ten thousand annotated images that overcomes performance saturation in smaller datasets by establishing baseline evaluations for deep learning models in remote sensing scene classification.
Aerial scene classification, which aims to automatically label an aerial image with a specific semantic category, is a fundamental problem for understanding high-resolution remote sensing imagery. In recent years, it has become an active task in remote sensing area and numerous algorithms have been proposed for this task, including many machine learning and data-driven approaches. However, the existing datasets for aerial scene classification like UC-Merced dataset and WHU-RS19 are with relatively small sizes, and the results on them are already saturated. This largely limits the development of scene classification algorithms. This paper describes the Aerial Image Dataset (AID): a large-scale dataset for aerial scene classification. The goal of AID is to advance the state-of-the-arts in scene classification of remote sensing images. For creating AID, we collect and annotate more than ten thousands aerial scene images. In addition, a comprehensive review of the existing aerial scene classification techniques as well as recent widely-used deep learning methods is given. Finally, we provide a performance analysis of typical aerial scene classification and deep learning approaches on AID, which can be served as the baseline results on this benchmark.
Added
2026-09-16
What is the best multi-stage architecture for object recognition?
Kevin Jarrett, Koray Kavukcuoglu, Marc'Aurelio Ranzato, Yann LeCun
Why you should read this
Demonstrates that combining rectification, local contrast normalization, and pooling into multi-stage architectures is critical for high recognition accuracy on visual benchmarks, even enabling random, unlearned filters to achieve competitive performance.
In many recent object recognition systems, feature extraction stages are generally composed of a filter bank, a non-linear transformation, and some sort of feature pooling layer. Most systems use only one stage of feature extraction in which the filters are hard-wired, or two stages where the filters in one or both stages are learned in supervised or unsupervised mode. This paper addresses three questions: 1. How does the non-linearities that follow the filter banks influence the recognition accuracy? 2. does learning the filter banks in an unsupervised or supervised manner improve the performance over random filters or hard-wired filters? 3. Is there any advantage to using an architecture with two stages of feature extraction, rather than one? We show that using non-linearities that include rectification and local contrast normalization is the single most important ingredient for good accuracy on object recognition benchmarks. We show that two stages of feature extraction yield better accuracy than one. Most surprisingly, we show that a two-stage system with random filters can yield almost 63% recognition rate on Caltech-101, provided that the proper non-linearities and pooling layers are used. Finally, we show that with supervised refinement, the system achieves state-of-the-art performance on NORB dataset (5.6%) and unsupervised pre-training followed by supervised refinement produces good accuracy on Caltech-101 (> 65%), and the lowest known error rate on the undistorted, unprocessed MNIST dataset (0.53%).
Added
2026-09-14
Beyond Bags of Features: Spatial Pyramid Matching for Recognizing Natural Scene Categories
Svetlana Lazebnik, Cordelia Schmid, Jean Ponce
Why you should read this
Demonstrates that a simple method of hierarchically partitioning images and aggregating local feature statistics across multiple spatial scales can outperform complex geometric correspondence approaches for scene recognition while providing an efficient and interpretable alternative to standard bag-of-features representations.
This paper presents a method for recognizing scene categories based on approximate global geometric correspondence. This technique works by partitioning the image into increasingly fine sub-regions and computing histograms of local features found inside each sub-region. The resulting "spatial pyramid" is a simple and computationally efficient extension of an orderless bag-of-features image representation, and it shows significantly improved performance on challenging scene categorization tasks. Specifically, our proposed method exceeds the state of the art on the Caltech-101 database and achieves high accuracy on a large database of fifteen natural scene categories. The spatial pyramid framework also offers insights into the success of several recently proposed image descriptions, including Torralba’s "gist" and Lowe’s SIFT descriptors.
Added
2026-02-21
Locality-constrained Linear Coding for image classification
Jinjun Wang, Jianchao Yang, Kai Yu, Fengjun Lv, Thomas S. Huang, Yihong Gong
Why you should read this
Demonstrates how replacing traditional vector quantization with locality-constrained linear coding enables simple linear classifiers to match or exceed the performance of complex nonlinear methods while being fast enough to process hundreds of images per second in practice.
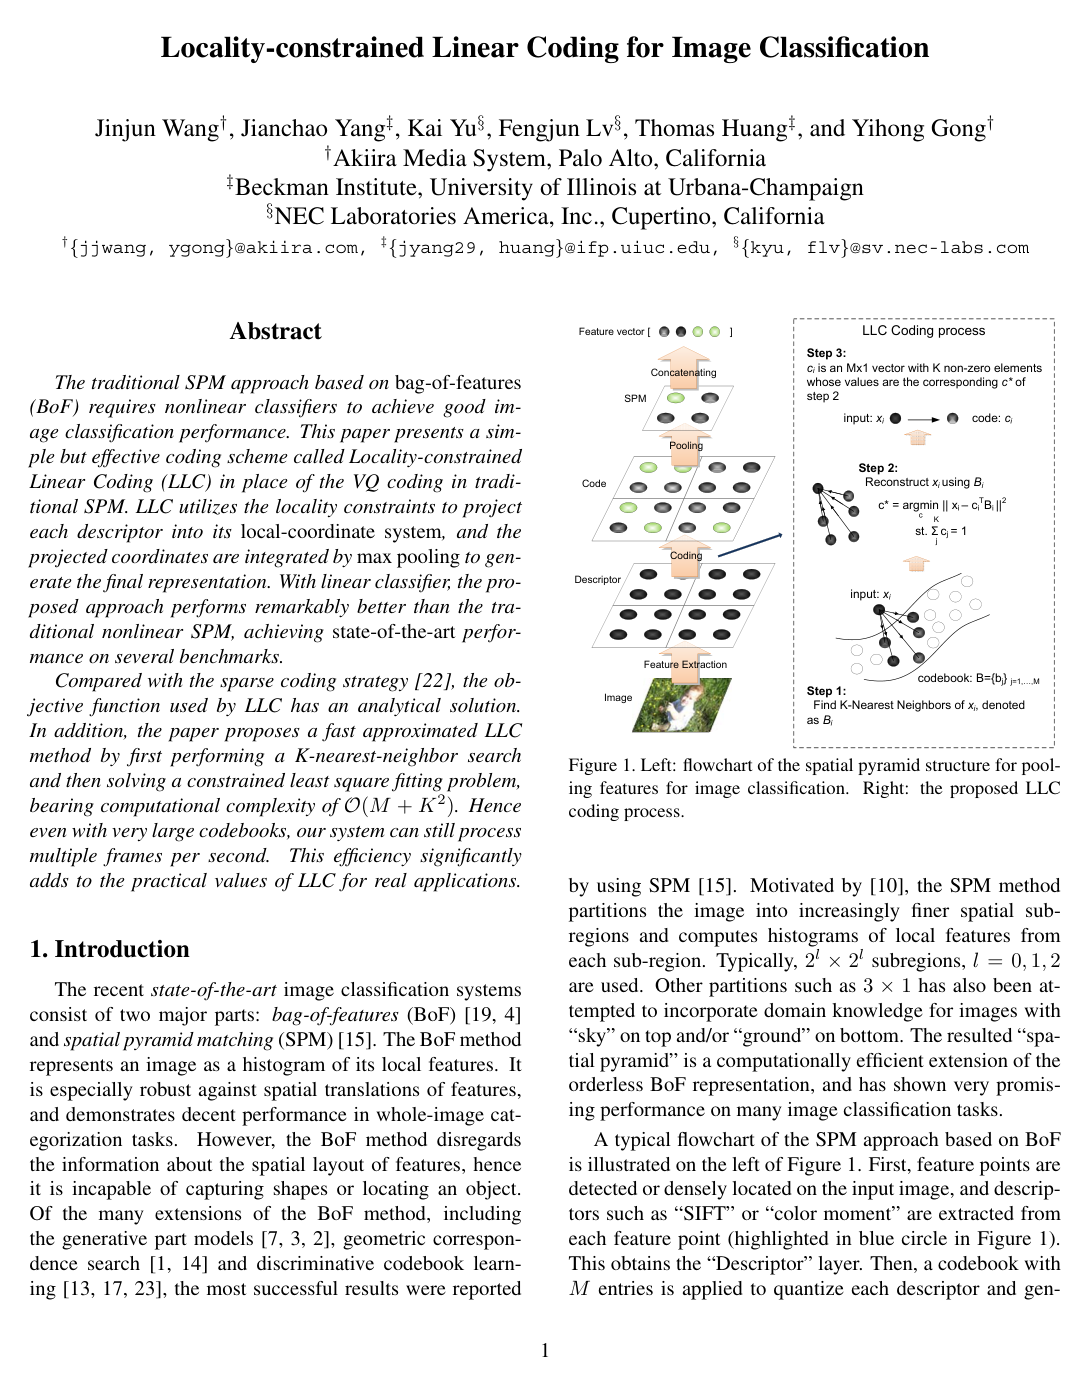
The traditional SPM approach based on bag-of-features (BoF) requires nonlinear classifiers to achieve good image classification performance. This paper presents a simple but effective coding scheme called Locality-constrained Linear Coding (LLC) in place of the VQ coding in traditional SPM. LLC utilizes the locality constraints to project each descriptor into its local-coordinate system, and the projected coordinates are integrated by max pooling to generate the final representation. With linear classifier, the proposed approach performs remarkably better than the traditional nonlinear SPM, achieving state-of-the-art performance on several benchmarks. Compared with the sparse coding strategy [22], the objective function used by LLC has an analytical solution. In addition, the paper proposes a fast approximated LLC method by first performing a K-nearest-neighbor search and then solving a constrained least square fitting problem, bearing computational complexity of O(M + K2). Hence even with very large codebooks, our system can still process multiple frames per second. This efficiency significantly adds to the practical values of LLC for real applications.
Added
2026-02-21