Built independently by an author, for readers. Read the story and support ChapterPal

keyword

Reason-Edit dataset

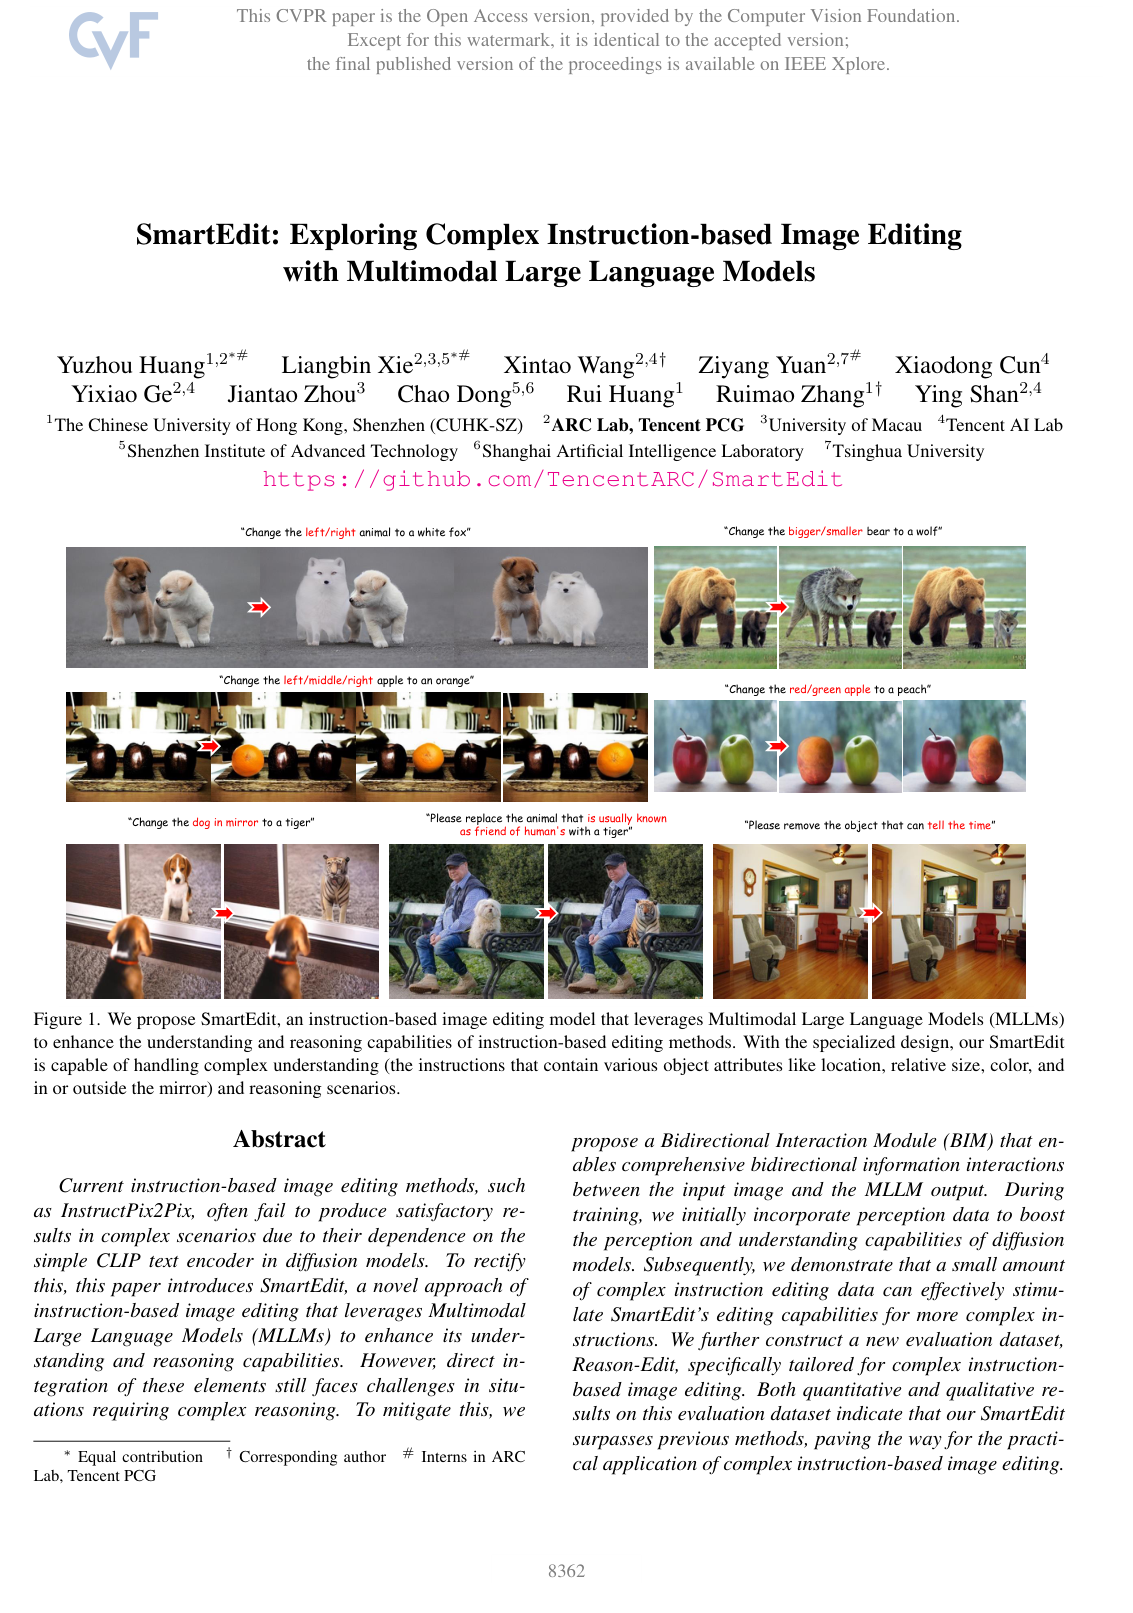
The Reason-Edit dataset is a benchmark dataset designed to evaluate artificial intelligence models on complex, instruction-guided image editing tasks. Unlike conventional benchmarks that assess straightforward visual alterations, Reason-Edit focuses on scenarios requiring advanced visual perception, multi-step logical deduction, and spatial reasoning. The dataset features challenging test instances where editing prompts involve subtle semantic understanding, such as interpreting relative object sizes, positional relationships, and contextual constraints, rather than simple, explicit commands. By pairing source images with complex textual instructions and target outcomes, it serves as a standardized evaluation suite to measure how effectively multimodal language models and image generation systems can interpret nuanced human intent and execute precise, context-aware visual manipulations.

1 item

SmartEdit: Exploring Complex Instruction-Based Image Editing with Multimodal Large Language Models

SmartEdit: Exploring Complex Instruction-Based Image Editing with Multimodal Large Language Models

Yuzhou Huang, Liangbin Xie, Xintao Wang, Ziyang Yuan, Xiaodong Cun, Yixiao Ge, Jiantao Zhou, Chao Dong, Rui Huang, Ruimao Zhang, Ying Shan

OrganizationsShanghai Artificial Intelligence LaboratoryShenzhen Institute of Advanced Technology, Chinese Academy of SciencesTencentThe Chinese University of Hong KongTsinghua UniversityUniversity of Macau

Why you should read this

Develops SmartEdit, a framework integrating multimodal large language models with diffusion models via a bidirectional interaction module and targeted perception training to execute image editing instructions requiring multi-object reasoning and world knowledge.

Current instruction-based image editing methods, such as InstructPix2Pix, often fail to produce satisfactory results in complex scenarios due to their dependence on the simple CLIP text encoder in diffusion models. To rectify this, this paper introduces SmartEdit, a novel approach of instruction-based image editing that leverages Multimodal Large Language Models (MLLMs) to enhance its understanding and reasoning capabilities. However, direct integration of these elements still faces challenges in situations requiring complex reasoning. To mitigate this, we propose a Bidirectional Interaction Module (BIM) that enables comprehensive bidirectional information interactions between the input image and the MLLM output. During training, we initially incorporate perception data to boost the perception and understanding capabilities of diffusion models. Subsequently, we demonstrate that a small amount of complex instruction editing data can effectively stimulate SmartEdit's editing capabilities for more complex instructions. We further construct a new evaluation dataset, Reason-Edit, specifically tailored for complex instruction-based image editing. Both quantitative and qualitative results on this evaluation dataset indicate that our SmartEdit surpasses previous methods, paving the way for the practical application of complex instruction-based image editing.

Added

2026-09-26