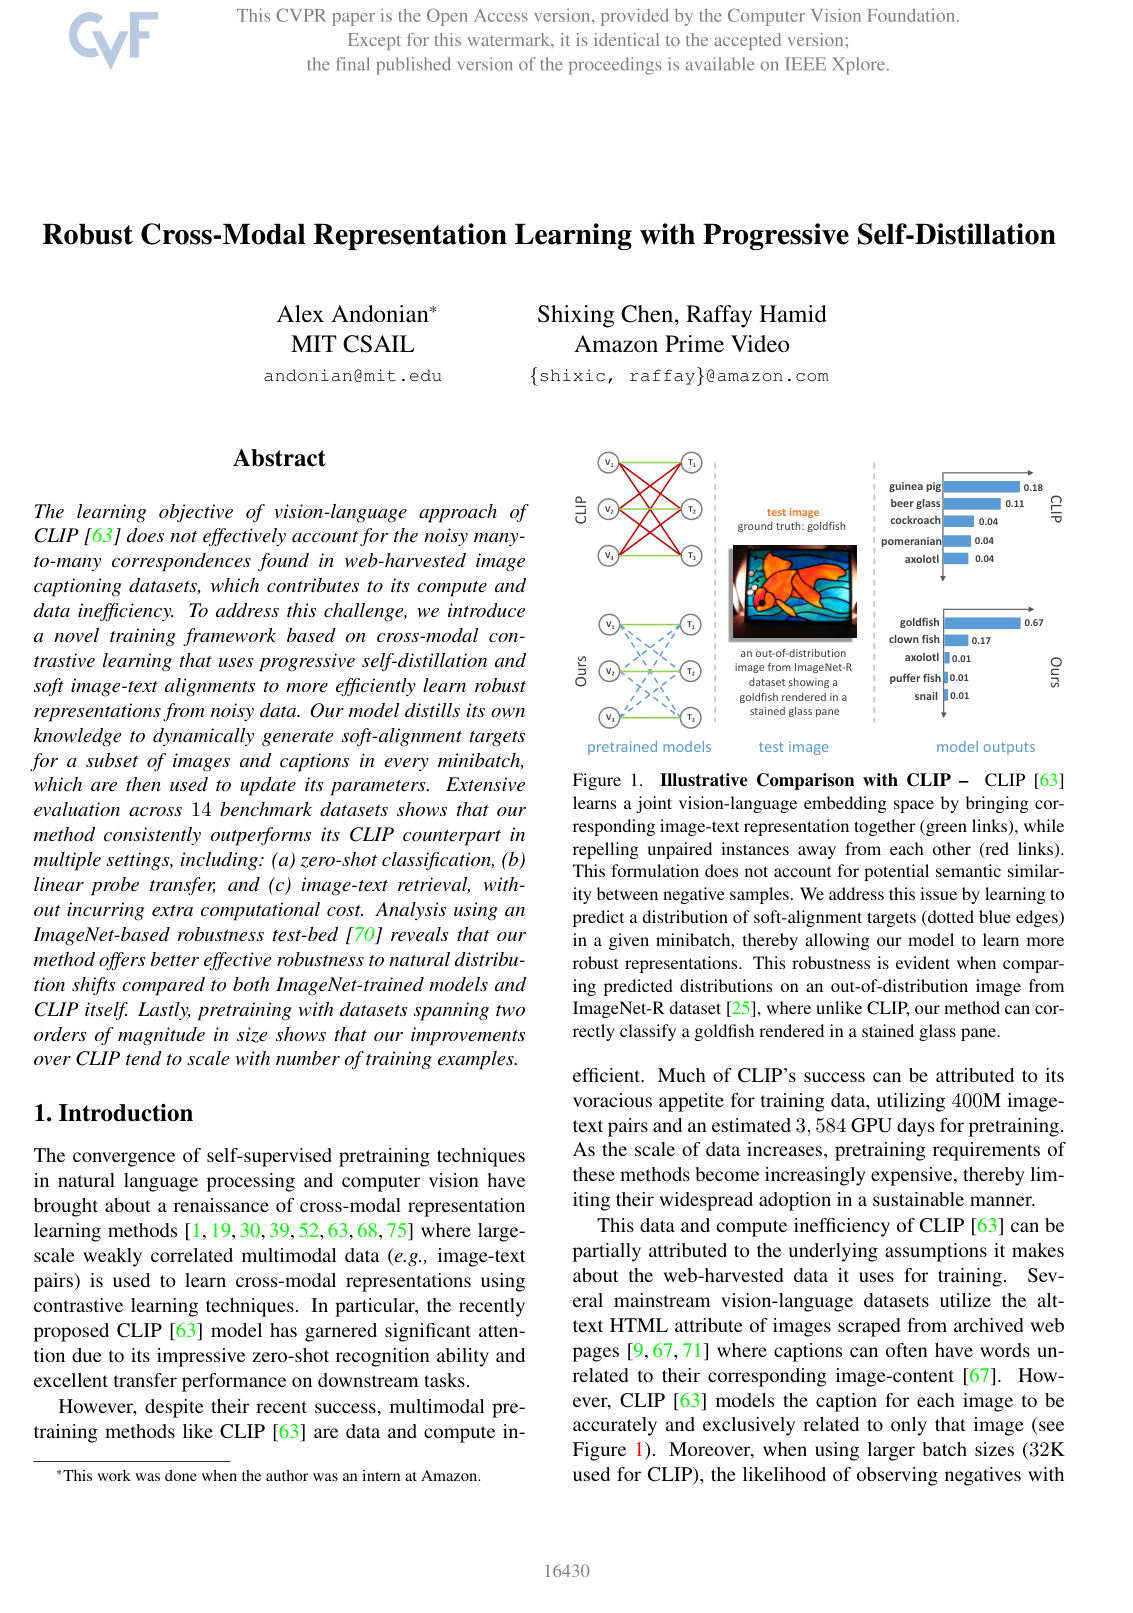
Progressive self-distillation is a machine learning training technique in which a neural network uses its own evolving predictions as dynamic supervision targets to guide its learning across successive training stages. Instead of relying on a separate pre-trained teacher model or rigid ground-truth labels, the model acts as its own teacher, gradually generating increasingly refined soft targets or alignment distributions as its internal representations mature. By progressively updating these self-generated supervision signals throughout the optimization process, the method mitigates the impact of noisy, ambiguous, or mismatched training data, enabling the network to learn more robust and generalized representations without requiring additional external teacher architectures.