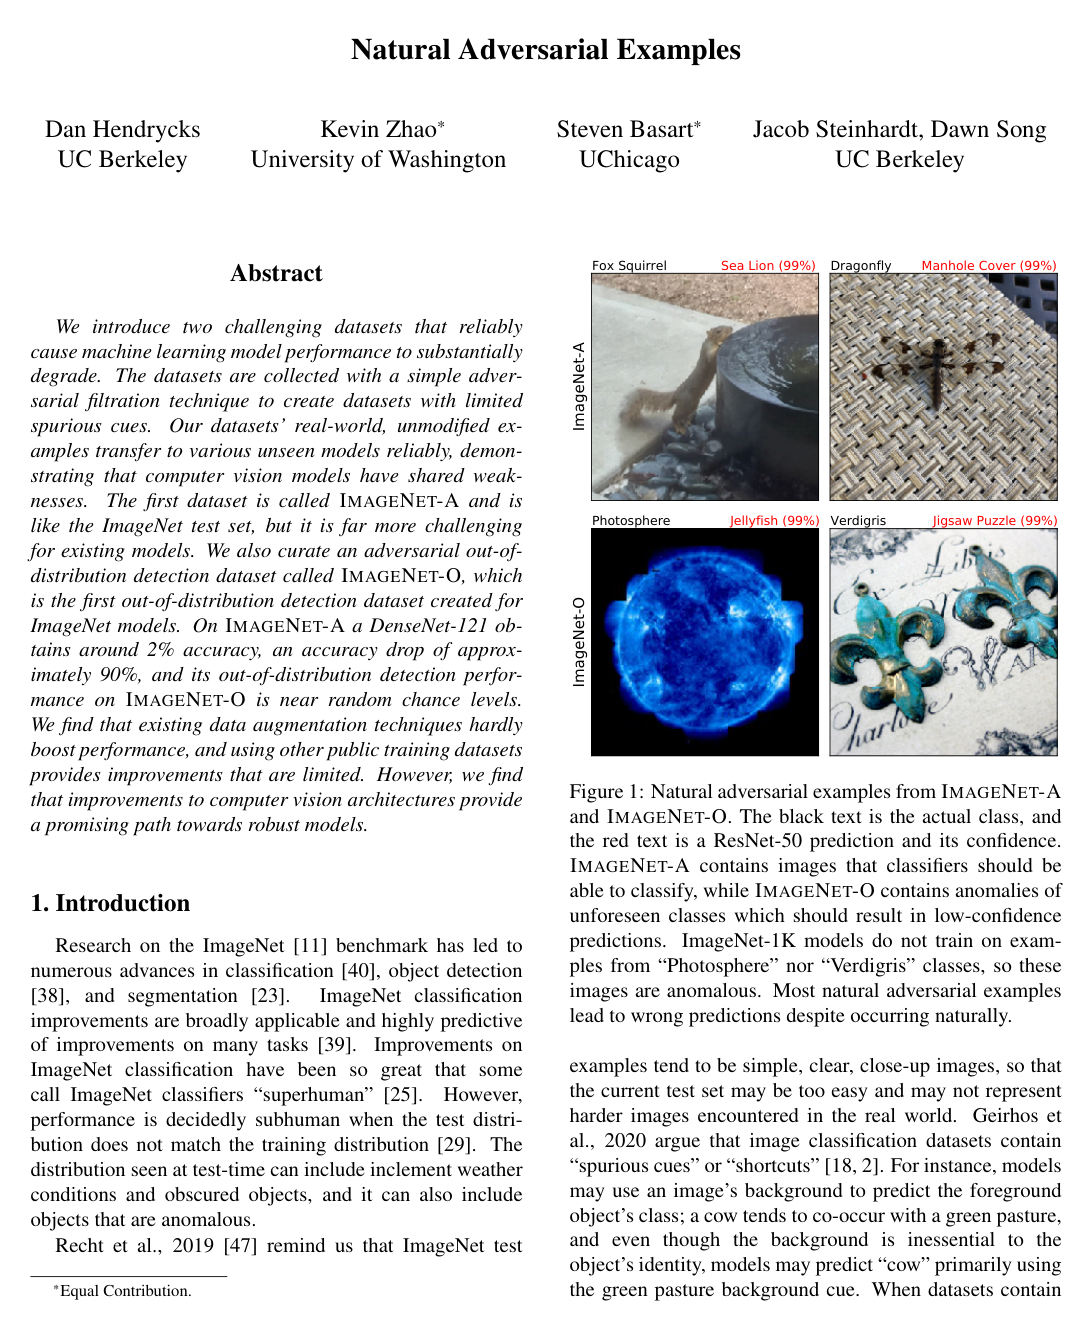
Out-of-distribution examples are data points presented to a machine learning model that originate from a probability distribution different from the one used during training, such as inputs belonging to unknown classes or featuring conditions the model has never encountered. Because standard predictive models operate under the assumption that test data follows the same distribution as the training data, encountering out-of-distribution examples often causes models to produce incorrect predictions with mistakenly high confidence. Accurately identifying and flagging these unfamiliar inputs through out-of-distribution detection is critical for assessing model robustness, preventing unexpected failures, and ensuring safety in real-world deployments.