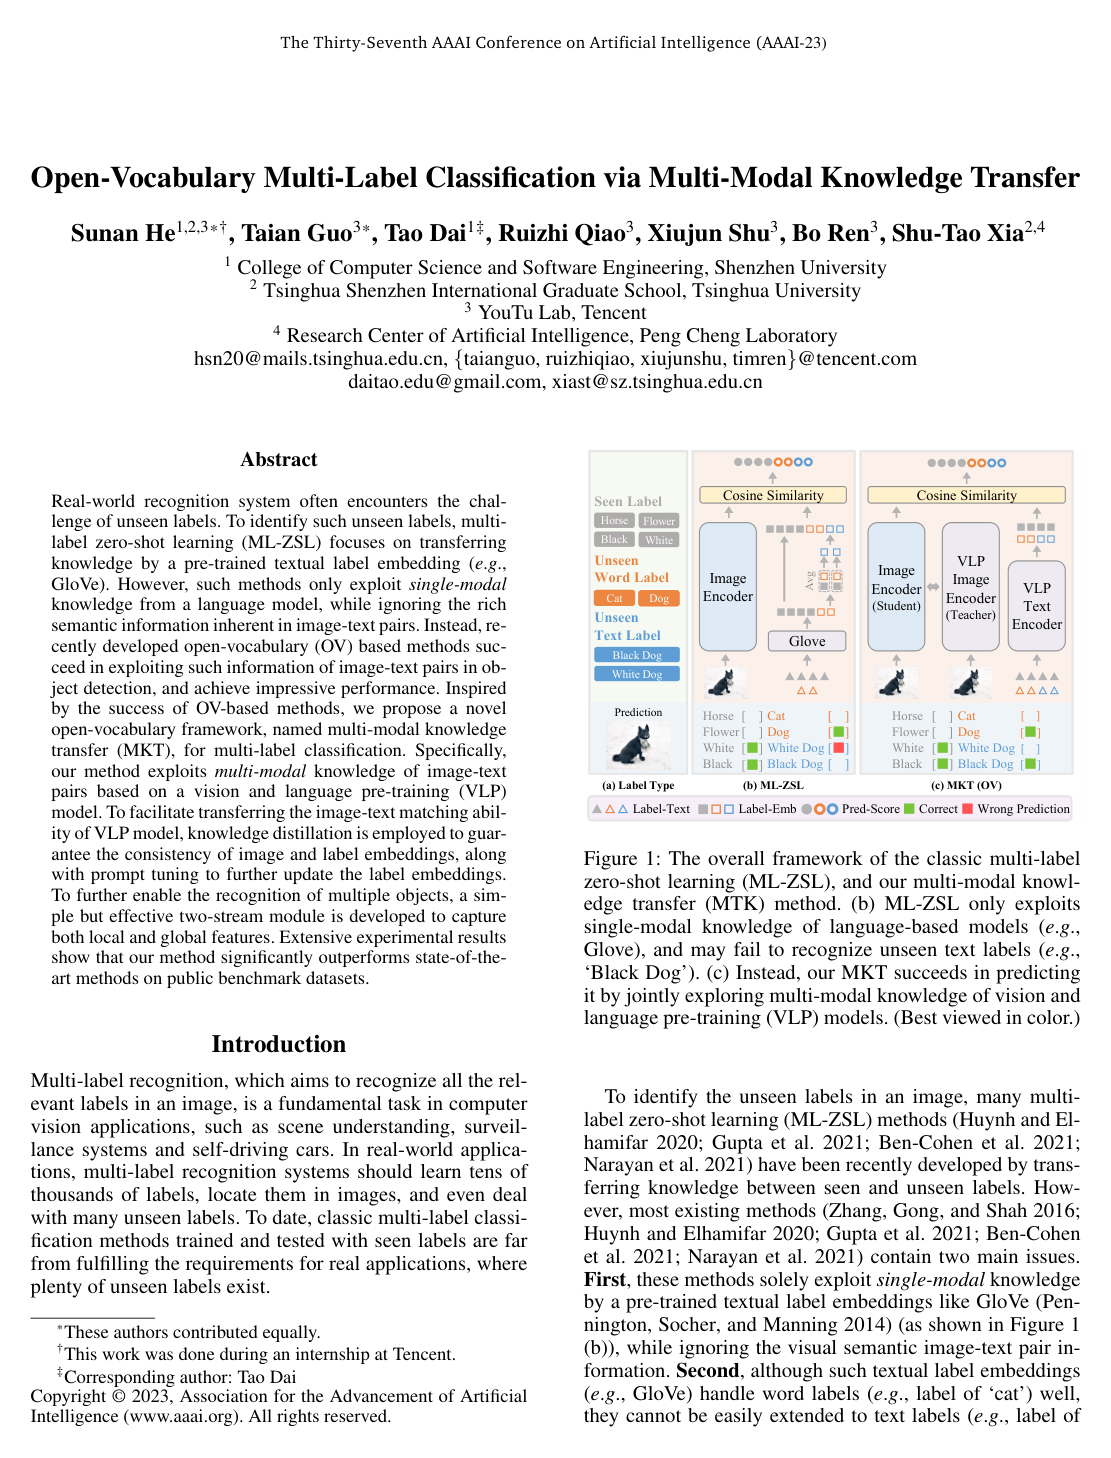
Open-vocabulary multi-label classification is a machine learning task in which a system identifies and assigns multiple relevant category labels to an input, such as an image or video, without being restricted to a fixed set of predefined classes encountered during training. Unlike conventional multi-label recognition that operates within a closed vocabulary or relies solely on single-modal text embeddings, this approach utilizes multi-modal vision-language representations to align visual features with arbitrary textual concepts. By mapping global and local visual information into a shared semantic space with natural language descriptions, the model can recognize both familiar and previously unseen objects, attributes, or actions across complex scenes.