
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

Multimodal contrastive loss

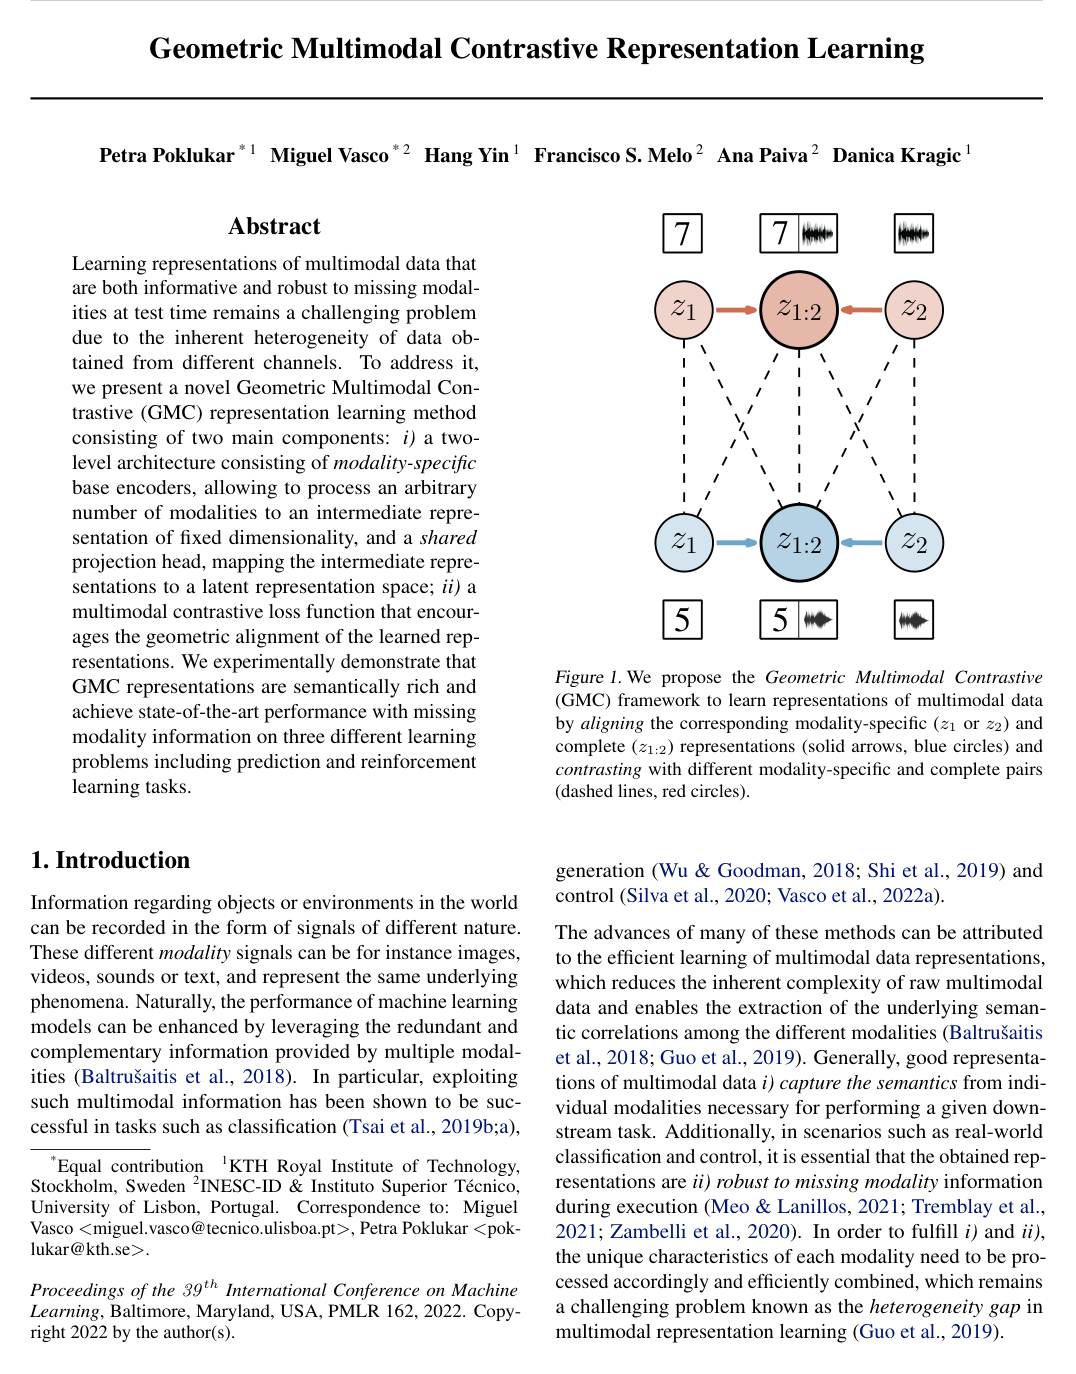
Multimodal contrastive loss is an objective function in machine learning designed to align representations from multiple distinct data modalities, such as text, images, or audio, within a shared embedding space. It operates by maximizing the similarity between representations of semantically corresponding cross-modal pairs while minimizing the similarity between unrelated or non-matching pairs. By encouraging the geometric alignment of paired inputs across different sensory channels, this loss function enables neural network encoders to map heterogeneous data into a unified latent space that preserves shared semantic relationships, supporting downstream applications such as cross-modal retrieval, classification, and robust inference under missing modalities.

1 item
Geometric Multimodal Contrastive Representation Learning

Geometric Multimodal Contrastive Representation Learning

Petra Poklukar, Miguel Vasco, Hang Yin, Francisco S. Melo, Ana Paiva, Danica Kragic

Why you should read this

Proposes a geometric multimodal contrastive learning framework that aligns modality-specific encoders with complete observations in a shared latent space, maintaining high task performance even when individual modalities are missing during evaluation.

Learning representations of multimodal data that are both informative and robust to missing modalities at test time remains a challenging problem due to the inherent heterogeneity of data obtained from different channels. To address it, we present a novel Geometric Multimodal Contrastive (GMC) representation learning method consisting of two main components: i) a two-level architecture consisting of modality-specific base encoders, allowing to process an arbitrary number of modalities to an intermediate representation of fixed dimensionality, and a shared projection head, mapping the intermediate representations to a latent representation space; ii) a multimodal contrastive loss function that encourages the geometric alignment of the learned representations. We experimentally demonstrate that GMC representations are semantically rich and achieve state-of-the-art performance with missing modality information on three different learning problems including prediction and reinforcement learning tasks.

Added

2026-10-02