
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

geometry-aware depth completion

Geometry-aware depth completion is a computer vision process that estimates a dense, continuous depth map from sparse and noisy depth measurements by explicitly modeling and preserving the three-dimensional geometric structure of a scene. While standard depth completion often treats the problem as a two-dimensional image-to-image translation task guided by aligned color images, geometry-aware approaches integrate explicit spatial representations, surface constraints, or multi-view geometric features to capture physical 3D relationships accurately. By enforcing structural consistency, neighborhood affinities, and fine-grained spatial boundaries across physical surfaces, this technique reduces reconstruction artifacts and yields high-fidelity spatial models essential for autonomous driving, robotics, and augmented reality.

1 item
Tri-Perspective view Decomposition for Geometry-Aware Depth Completion

Tri-Perspective view Decomposition for Geometry-Aware Depth Completion

Zhiqiang Yan, Yuankai Lin, Kun Wang, Yupeng Zheng, Yufei Wang, Zhenyu Zhang, Jun Li, Jian Yang

Why you should read this

Proposes a tri-perspective view decomposition framework that models structural 3D geometry across top, front, and side projections using spherical convolutions and geometric spatial propagation to achieve superior depth completion on standard benchmarks and real-world smartphone data.

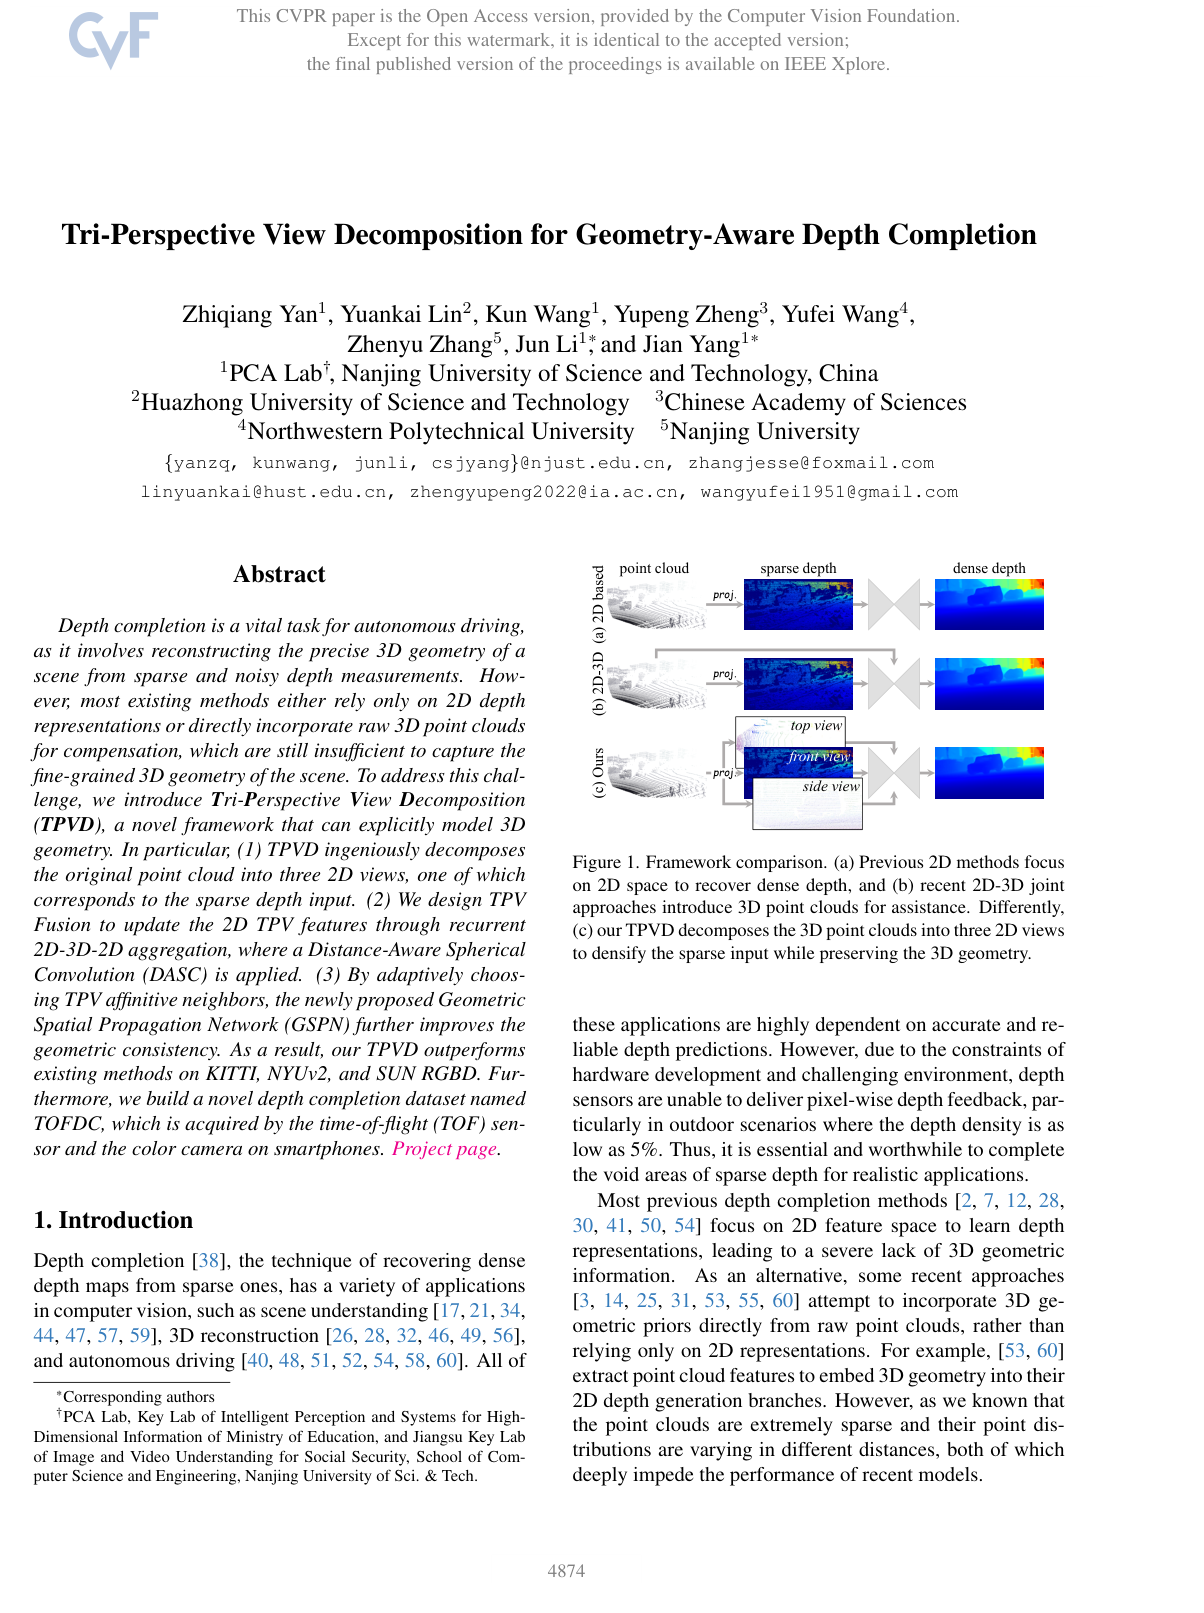
Depth completion is a vital task for autonomous driving, as it involves reconstructing the precise 3D geometry of a scene from sparse and noisy depth measurements. However, most existing methods either rely only on 2D depth representations or directly incorporate raw 3D point clouds for compensation, which are still insufficient to capture the fine-grained 3D geometry of the scene. To address this challenge, we introduce Tri-Perspective View Decomposition (TPVD), a novel framework that can explicitly model 3D geometry. In particular, (1) TPVD ingeniously decomposes the original point cloud into three 2D views, one of which corresponds to the sparse depth input. (2) We design TPV Fusion to update the 2D TPV features through recurrent 2D-3D-2D aggregation, where a Distance-Aware Spherical Convolution (DASC) is applied. (3) By adaptively choosing TPV affinitive neighbors, the newly proposed Geometric Spatial Propagation Network (GSPN) further improves the geometric consistency. As a result, our TPVD outperforms existing methods on KITTI, NYUv2, and SUN RGBD. Furthermore, we build a novel depth completion dataset named TOFDC, which is acquired by the time-of-flight (TOF) sensor and the color camera on smartphones. Project page.

Added

2026-09-26