keyword
Geometric multimodal contrastive representation learning
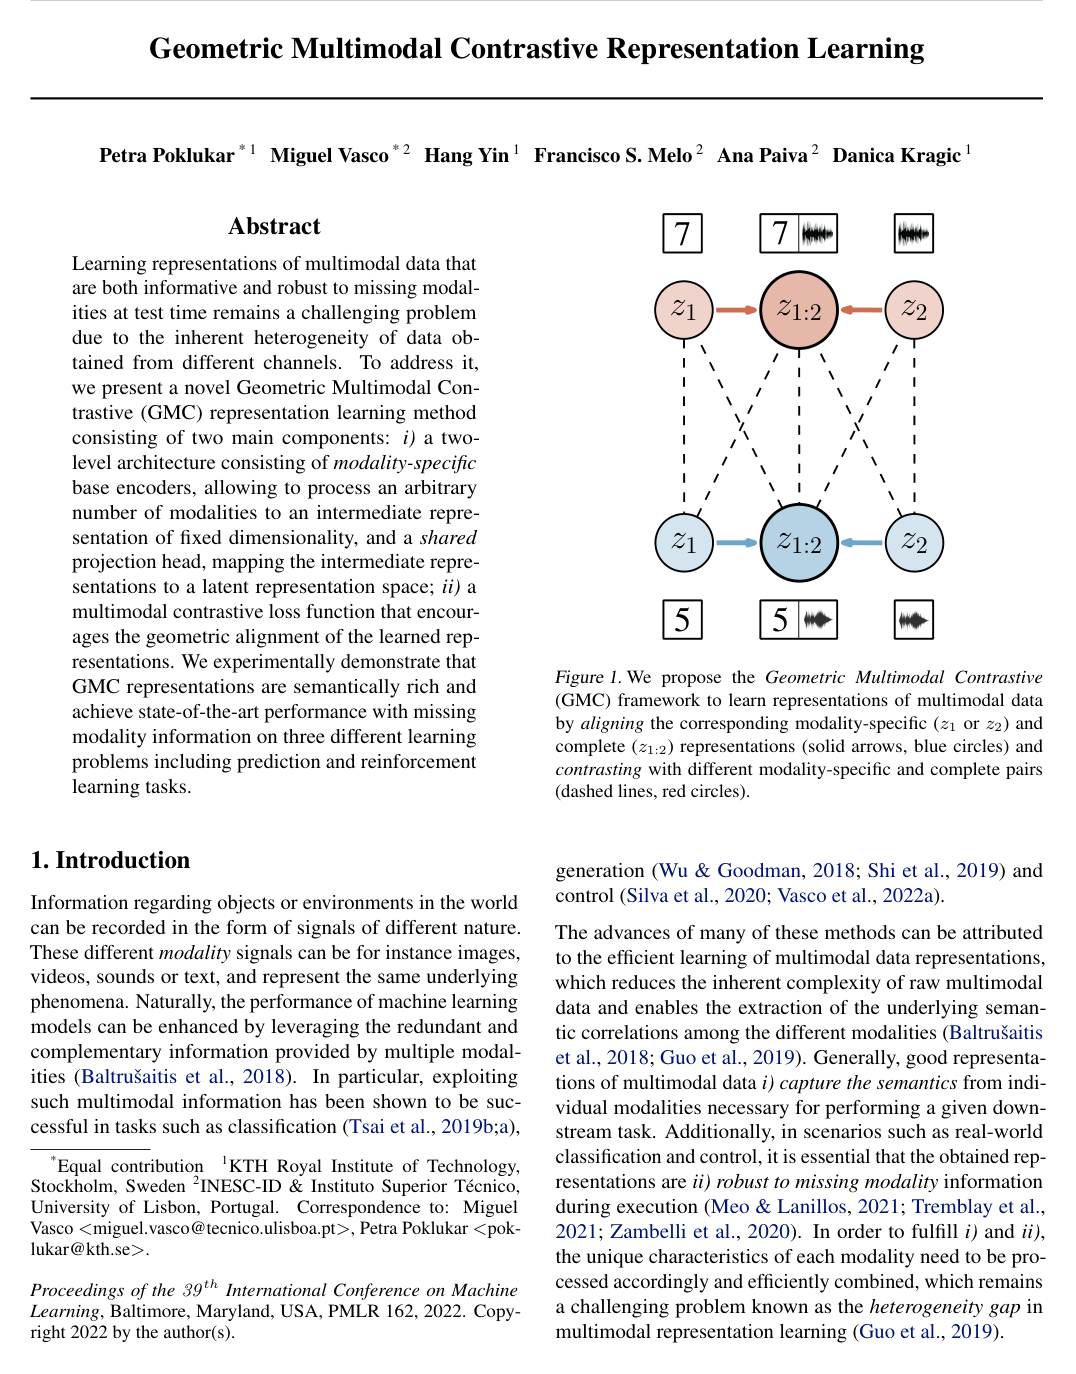
Geometric multimodal contrastive representation learning is a machine learning paradigm that trains models to map data from diverse modalities into a shared representation space by aligning their geometric structures through contrastive objectives. In this approach, modality-specific encoders process heterogeneous inputs into intermediate features before a shared projection maps them into a common latent embedding space. By using contrastive loss functions that enforce geometric alignment among corresponding multimodal inputs, the framework preserves shared semantic relationships across different sensory channels. This structured alignment produces semantically rich representations that allow the system to effectively integrate information and maintain robust performance even when certain modalities are missing during evaluation.
1 item