Built independently by an author, for readers. Read the story and support ChapterPal

keyword

EscherNet

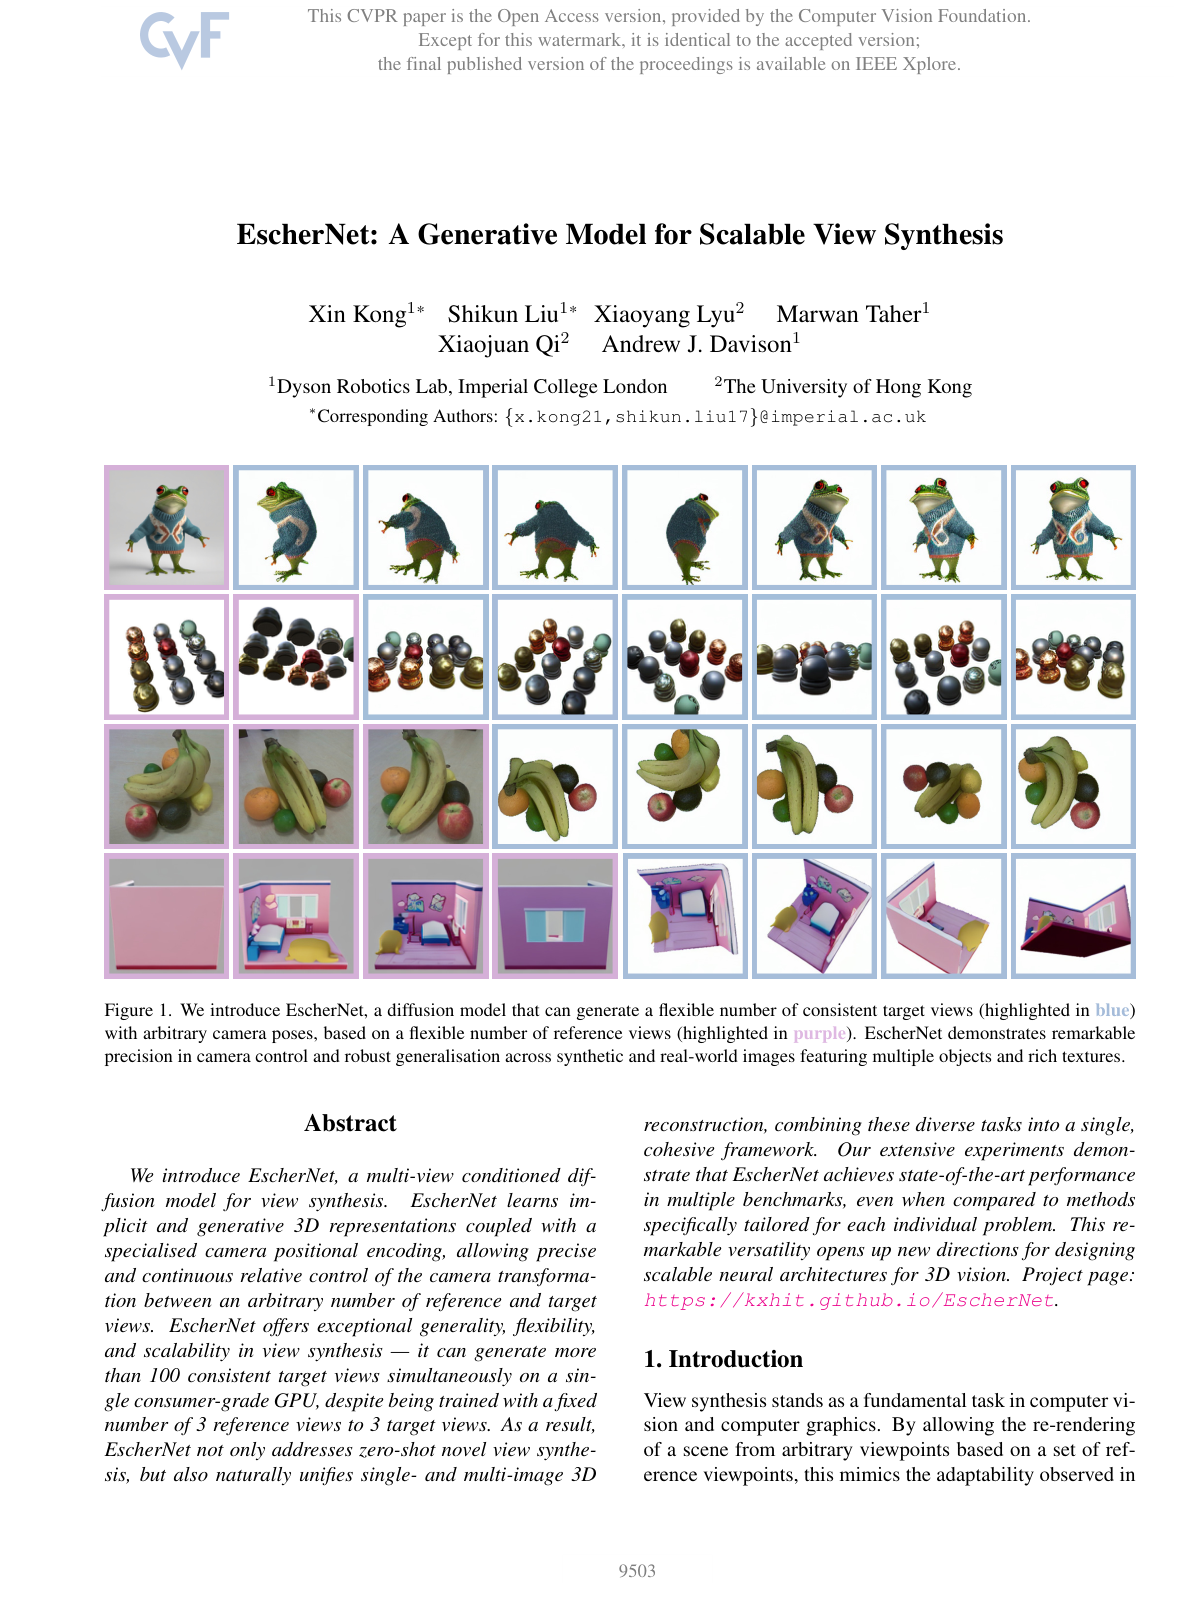
EscherNet is a multi-view conditioned generative diffusion model designed for scalable novel view synthesis and three-dimensional reconstruction from two-dimensional images. It operates by learning implicit three-dimensional representations paired with specialized camera positional encodings, which allow precise and continuous control over relative camera transformations between arbitrary numbers of reference and target viewpoints. By modeling cross-view relationships across multiple perspectives simultaneously rather than relying on scene-specific volumetric rendering, the architecture can generate dozens of visually consistent novel viewpoints in parallel from a flexible set of input images, unifying single-image and multi-image three-dimensional vision tasks within a single framework.

1 item

EscherNet: A Generative Model for Scalable View Synthesis

EscherNet: A Generative Model for Scalable View Synthesis

Xin Kong, Shikun Liu, Xiaoyang Lyu, Marwan Taher, Xiaojuan Qi, Andrew J. Davison

Why you should read this

Introduces a multi-view conditioned diffusion model with relative camera positional encoding that synthesizes over 100 consistent target views simultaneously on a single GPU from arbitrary reference angles, unifying novel view synthesis and 3D reconstruction without expensive 3D convolutions or volumetric rendering.

We introduce EscherNet, a multi-view conditioned diffusion model for view synthesis. EscherNet learns implicit and generative 3D representations coupled with a specialised camera positional encoding, allowing precise and continuous relative control of the camera transformation between an arbitrary number of reference and target views. EscherNet offers exceptional generality, flexibility, and scalability in view synthesis — it can generate more than 100 consistent target views simultaneously on a single consumer-grade GPU, despite being trained with a fixed number of 3 reference views to 3 target views. As a result, EscherNet not only addresses zero-shot novel view synthesis, but also naturally unifies single- and multi-image 3D reconstruction, combining these diverse tasks into a single, cohesive framework. Our extensive experiments demonstrate that EscherNet achieves state-of-the-art performance in multiple benchmarks, even when compared to methods specifically tailored for each individual problem. This remarkable versatility opens up new directions for designing scalable neural architectures for 3D vision. Project page: https://kxhit.github.io/EscherNet.

Added

2026-09-26