Built independently by an author, for readers. Read the story and support ChapterPal

keyword

cross-modal relations

Cross-modal relations refer to the semantic, structural, or functional connections and interactions between information represented across different modalities, such as text, images, audio, and video. In multimodal data processing and cognitive computing, these relations describe how elements in one data stream correspond to, complement, or conflict with elements in another. Understanding and modeling cross-modal relations enables computational systems to align heterogeneous representations, capture inter-modal congruities or discrepancies, and fuse complementary evidence across distinct sensory channels to achieve a unified comprehension of complex multimedia data.

1 item

Mutual-Enhanced Incongruity Learning Network for Multi-Modal Sarcasm Detection

Mutual-Enhanced Incongruity Learning Network for Multi-Modal Sarcasm Detection

Yang Qiao, Liqiang Jing, Xuemeng Song, Xiaolin Chen, Lei Zhu, Liqiang Nie

OrganizationsHarbin Institute of TechnologySchool of Computer Science and TechnologySchool of Information Science and EngineeringSchool of SoftwareShandong Normal UniversityShandong University

Why you should read this

Presents a multi-modal sarcasm detection network that combines local graph-based semantic reasoning with global cross-attention fusion to capture incongruities across text and images while using mutual learning to transfer knowledge between the two perspectives.

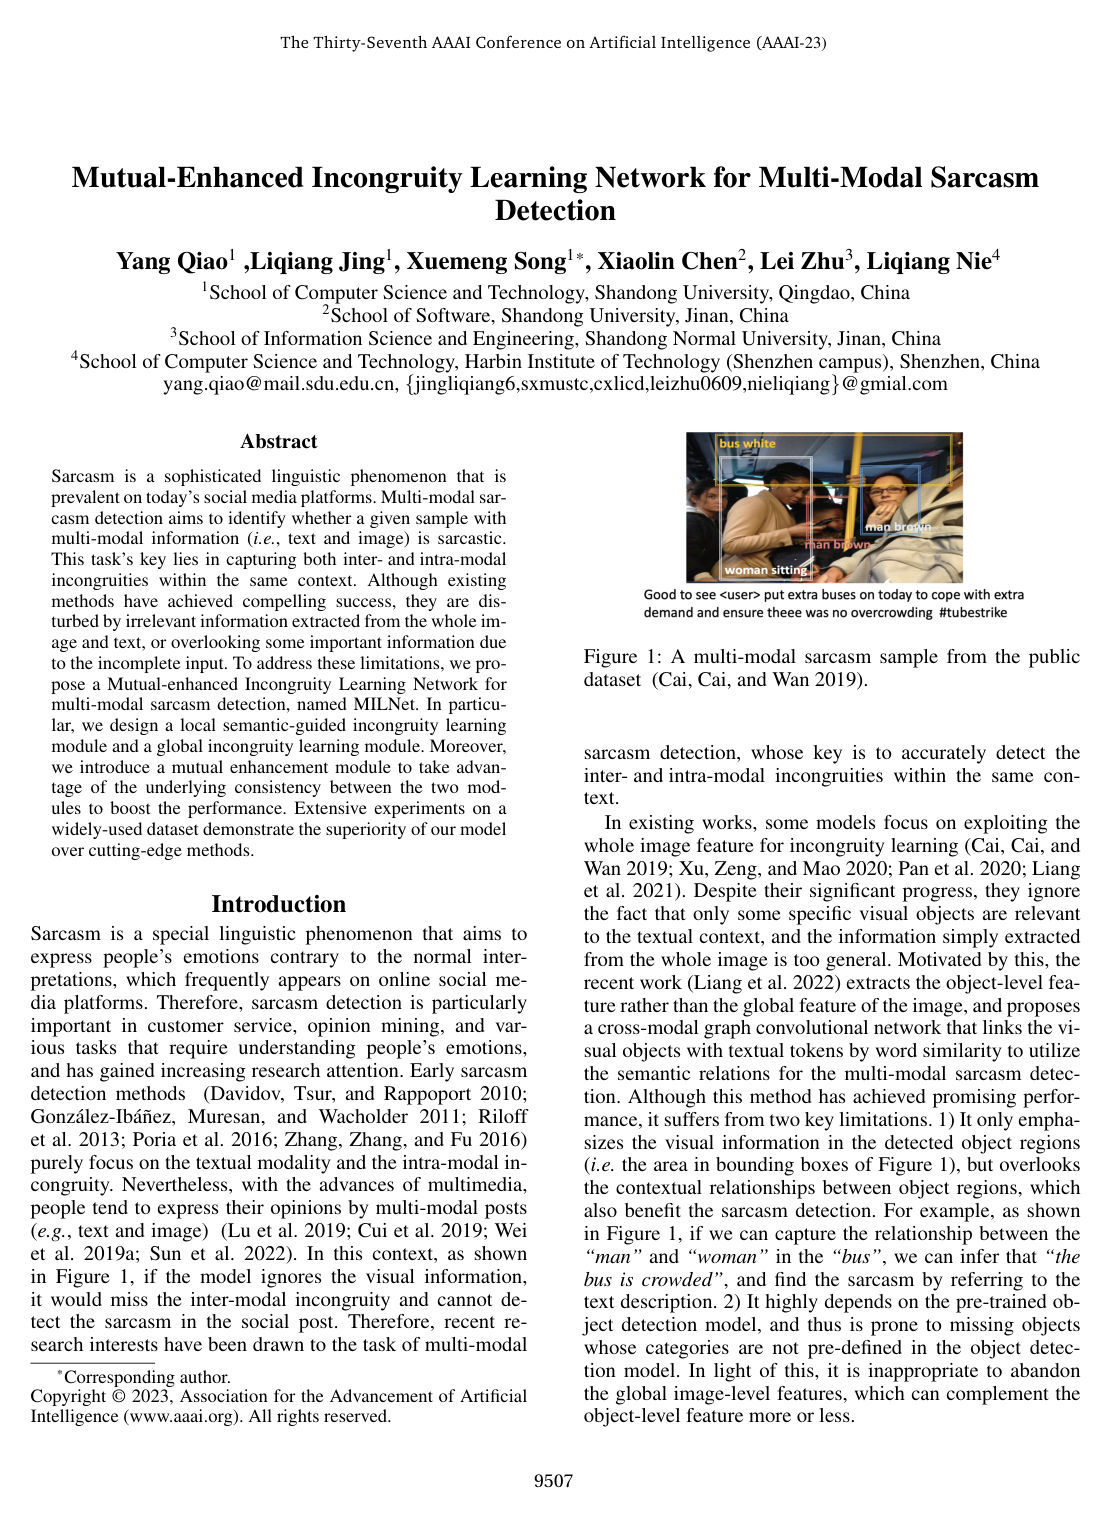
Sarcasm is a sophisticated linguistic phenomenon that is prevalent on today’s social media platforms. Multi-modal sarcasm detection aims to identify whether a given sample with multi-modal information (i.e., text and image) is sarcastic. This task’s key lies in capturing both inter- and intra-modal incongruities within the same context. Although existing methods have achieved compelling success, they are disturbed by irrelevant information extracted from the whole image or text, or overlooking some important information due to the incomplete input. To address these limitations, we propose a Mutual-enhanced Incongruity Learning Network for multi-modal sarcasm detection, named MILNet. In particular, we design a local semantic-guided incongruity learning module and a global incongruity learning module. Moreover, we introduce a mutual enhancement module to take advantage of the underlying consistency between the two modules to boost the performance. Extensive experiments on a widely-used dataset demonstrate the superiority of our model over cutting-edge methods.

Added

2026-09-26