
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

confident learning

Confident learning is a data-centric machine learning framework designed to characterize, identify, and correct label errors in supervised datasets. Unlike standard approaches that treat given labels as infallible ground truth and evaluate uncertainty only in model predictions, confident learning evaluates uncertainty in the dataset labels themselves. It works by using out-of-sample predicted probabilities from a classifier to estimate the joint probability distribution between observed noisy labels and uncorrupted true labels under a class-conditional noise process. By applying probabilistic thresholds to quantify noise, rank potentially erroneous examples, and prune or reweight mislabeled data, confident learning allows practitioners to clean corrupted datasets and train robust models across various data modalities and learning architectures.

1 item
Robust Cross-Modal Representation Learning with Progressive Self-Distillation

Robust Cross-Modal Representation Learning with Progressive Self-Distillation

Alex Andonian, Shixing Chen, Raffay Hamid

OrganizationsAmazonMassachusetts Institute of Technology

Why you should read this

Proposes a progressive self-distillation framework that replaces rigid one-to-one pairings in vision-language pretraining with dynamic soft-alignment targets, consistently outperforming CLIP across zero-shot, transfer, and retrieval benchmarks without extra computational overhead.

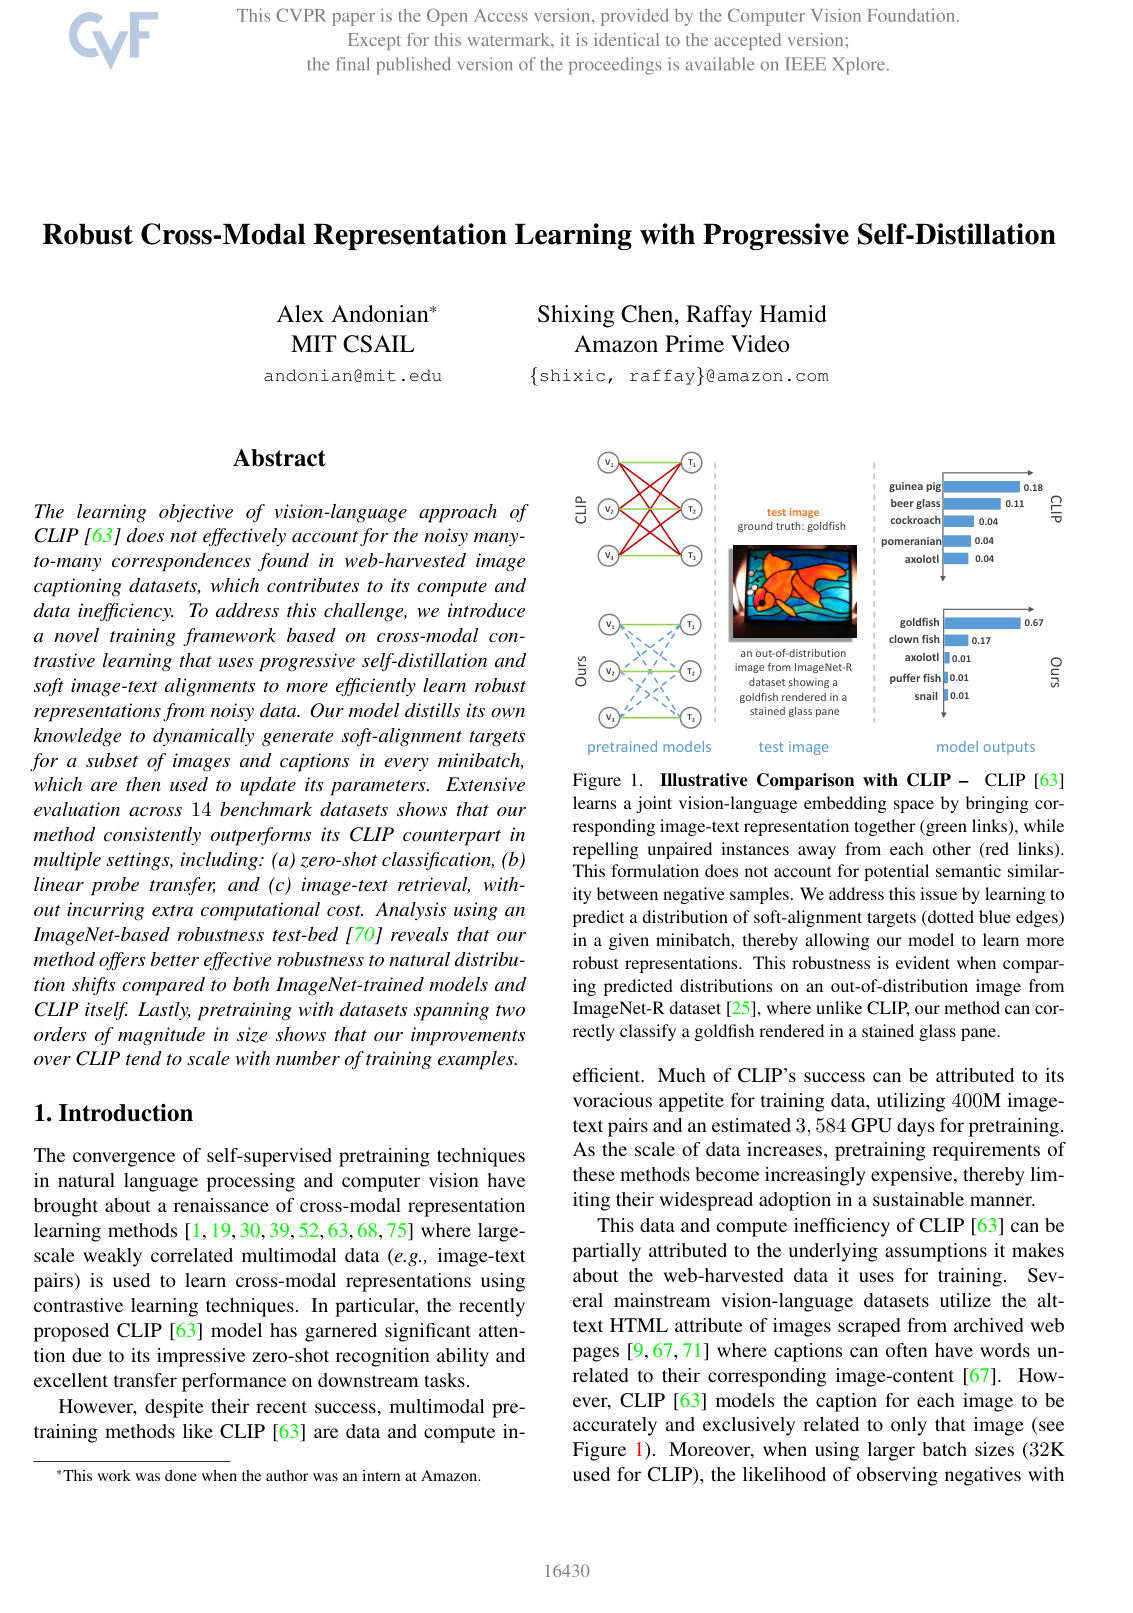
The learning objective of vision-language approach of CLIP [63] does not effectively account for the noisy many-to-many correspondences found in web-harvested image captioning datasets, which contributes to its compute and data inefficiency. To address this challenge, we introduce a novel training framework based on cross-modal contrastive learning that uses progressive self-distillation and soft image-text alignments to more efficiently learn robust representations from noisy data. Our model distills its own knowledge to dynamically generate soft-alignment targets for a subset of images and captions in every minibatch, which are then used to update its parameters. Extensive evaluation across 14 benchmark datasets shows that our method consistently outperforms its CLIP counterpart in multiple settings, including: (a) zero-shot classification, (b) linear probe transfer, and (c) image-text retrieval, without incurring extra computational cost. Analysis using an ImageNet-based robustness test-bed [70] reveals that our method offers better effective robustness to natural distribution shifts compared to both ImageNet-trained models and CLIP itself. Lastly, pretraining with datasets spanning two orders of magnitude in size shows that our improvements over CLIP tend to scale with number of training examples.

Added

2026-09-26