
keyword
backdoor defenses
Backdoor defenses are security strategies and techniques in machine learning designed to detect, prevent, or remove covert vulnerabilities embedded within artificial intelligence models. In a backdoor attack, an adversary alters training data or manipulates model parameters so that the system performs normally on standard inputs but produces an attacker-chosen malicious outcome whenever a specific trigger pattern is present. Backdoor defense mechanisms can operate at different stages of the machine learning lifecycle, including filtering poisoned data prior to training, inspecting and sanitizing infected models through parameter adjustment, neuron pruning, or unlearning, and analyzing or preprocessing inputs during inference to detect and neutralize triggered activations without degrading the model utility on clean tasks.
9 items
BEEAR: Embedding-based Adversarial Removal of Safety Backdoors in Instruction-tuned Language Models
Yi Zeng, Weiyu Sun, Tran Ngoc Huynh, Dawn Song, Bo Li, Ruoxi Jia
Why you should read this
Proposes BEEAR, a bi-level optimization defense that eliminates stealthy safety backdoors from instruction-tuned language models by identifying and neutralizing universal embedding drifts without requiring prior knowledge of the attack trigger.
Safety backdoor attacks in large language models (LLMs) enable the stealthy triggering of unsafe behaviors while evading detection during normal interactions. The high dimensionality of potential triggers in the token space and the diverse range of malicious behaviors make this a critical challenge. We present BEEAR, a mitigation approach leveraging the insight that backdoor triggers induce relatively uniform drifts in the model’s embedding space. Our bi-level optimization method identifies universal embedding perturbations that elicit unwanted behaviors and adjusts the model parameters to reinforce safe behaviors against these perturbations. Experiments show BEEAR reduces the success rate of RLHF time backdoor attacks from >95% to <1% and from 47% to 0% for instruction-tuning time backdoors targeting malicious code generation, without compromising model utility. Requiring only defender-defined safe and unwanted behaviors, BEEAR represents a step towards practical defenses against safety backdoors in LLMs, providing a foundation for further advancements in AI safety and security.
Added
2026-10-03
Handcrafted Backdoors in Deep Neural Networks
Sanghyun Hong, Nicholas Carlini, Alexey Kurakin
Why you should read this
Exposes a major blind spot in neural network security by directly editing model weights to insert stealthy backdoors without poisoning training data, bypassing standard defenses while maintaining high attack success rates and benign task accuracy.
When machine learning training is outsourced to third parties, backdoor attacks become practical as the third party who trains the model may act maliciously to inject hidden behaviors into the otherwise accurate model. Until now, the mechanism to inject backdoors has been limited to poisoning. We argue that a supply-chain attacker has more attack techniques available by introducing a handcrafted attack that directly manipulates a model's weights. This direct modification gives our attacker more degrees of freedom compared to poisoning, and we show it can be used to evade many backdoor detection or removal defenses effectively. Across four datasets and four network architectures our backdoor attacks maintain an attack success rate above 96%. Our results suggest that further research is needed for understanding the complete space of supply-chain backdoor attacks.
Added
2026-09-26
Dual-Key Multimodal Backdoors for Visual Question Answering
Matthew Walmer, Karan Sikka, Indranil Sur, Abhinav Shrivastava, Susmit Jha
Why you should read this
Demonstrates how visual question answering models can be stealthily compromised using dual-key backdoor attacks that require simultaneous visual and textual triggers to activate, achieving over 98% attack success rates with only 1% poisoned training data.
The success of deep learning has enabled advances in multimodal tasks that require non-trivial fusion of multiple input domains. Although multimodal models have shown potential in many problems, their increased complexity makes them more vulnerable to attacks. A Backdoor (or Trojan) attack is a class of security vulnerability wherein an attacker embeds a malicious secret behavior into a network (e.g. targeted misclassification) that is activated when an attacker-specified trigger is added to an input. In this work, we show that multimodal networks are vulnerable to a novel type of attack that we refer to as Dual-Key Multimodal Backdoors. This attack exploits the complex fusion mechanisms used by state-of-the-art networks to embed backdoors that are both effective and stealthy. Instead of using a single trigger, the proposed attack embeds a trigger in each of the input modalities and activates the malicious behavior only when both the triggers are present. We present an extensive study of multimodal backdoors on the Visual Question Answering (VQA) task with multiple architectures and visual feature backbones. A major challenge in embedding backdoors in VQA models is that most models use visual features extracted from a fixed pretrained object detector. This is challenging for the attacker as the detector can distort or ignore the visual trigger entirely, which leads to models where backdoors are over-reliant on the language trigger. We tackle this problem by proposing a visual trigger optimization strategy designed for pretrained object detectors. Through this method, we create Dual-Key Backdoors with over a 98% attack success rate while only poisoning 1% of the training data. Finally, we release TrojVQA, a large collection of clean and trojan VQA models to enable research in defending against multimodal backdoors.
Added
2026-09-26
Color Backdoor: A Robust Poisoning Attack in Color Space
Wenbo Jiang, Hongwei Li, Guowen Xu, Tianwei Zhang
Why you should read this
Proposes a stealthy data poisoning attack that applies an optimized uniform color space shift across image pixels to embed backdoors capable of bypassing mainstream defense mechanisms and image preprocessing transformations.
Backdoor attacks against neural networks have been intensively investigated, where the adversary compromises the integrity of the victim model, causing it to make wrong predictions for inference samples containing a specific trigger. To make the trigger more imperceptible and human-unnoticeable, a variety of stealthy backdoor attacks have been proposed, some works employ imperceptible perturbations as the backdoor triggers, which restrict the pixel differences of the triggered image and clean image. Some works use special image styles (e.g., reflection, Instagram filter) as the backdoor triggers. However, these attacks sacrifice the robustness, and can be easily defeated by common preprocessing-based defenses. This paper presents a novel color backdoor attack, which can exhibit robustness and stealthiness at the same time. The key insight of our attack is to apply a uniform color space shift for all pixels as the trigger. This global feature is robust to image transformation operations and the triggered samples maintain natural-looking. To find the optimal trigger, we first define naturalness restrictions through the metrics of PSNR, SSIM and LPIPS. Then we employ the Particle Swarm Optimization (PSO) algorithm to search for the optimal trigger that can achieve high attack effectiveness and robustness while satisfying the restrictions. Extensive experiments demonstrate the superiority of PSO and the robustness of color backdoor against different main-stream backdoor defenses.
Added
2026-09-26
You Are Catching My Attention: Are Vision Transformers Bad Learners under Backdoor Attacks?
Zenghui Yuan, Pan Zhou, Kai Zou, Yu Cheng
Why you should read this
Reveals how the self-attention mechanism makes Vision Transformers uniquely vulnerable to patch-based backdoor attacks and introduces BadViT, an efficient attack framework that manipulates attention maps to implant stealthy triggers with minimal poisoning.
Vision Transformers (ViTs), which made a splash in the field of computer vision (CV), have shaken the dominance of convolutional neural networks (CNNs). However, in the process of industrializing ViTs, backdoor attacks have brought severe challenges to security. The success of ViTs benefits from the self-attention mechanism. However, compared with CNNs, we find that this mechanism of capturing global information within patches makes ViTs more sensitive to patch-wise triggers. Under such observations, we delicately design a novel backdoor attack framework for ViTs, dubbed BadViT, which utilizes a universal patch-wise trigger to catch the model's attention from patches beneficial for classification to those with triggers, thereby manipulating the mechanism on which ViTs survive to confuse itself. Furthermore, we propose invisible variants of BadViT to increase the stealth of the attack by limiting the strength of the trigger perturbation. Through a large number of experiments, it is proved that BadViT is an efficient backdoor attack method against ViTs, which is less dependent on the number of poisons, with satisfactory convergence, and is transferable for downstream tasks. Furthermore, the risks inside of ViTs to backdoor attacks are also explored from the perspective of existing advanced defense schemes.
Added
2026-09-26
Detecting Backdoors During the Inference Stage Based on Corruption Robustness Consistency
Xiaogeng Liu, Minghui Li, Haoyu Wang, Shengshan Hu, Dengpan Ye, Hai Jin, Libing Wu, Chaowei Xiao
Why you should read this
Presents TeCo, a practical test-time backdoor detection method that identifies trigger samples in strictly black-box, hard-label settings without requiring clean data or assumptions about trigger appearance by measuring prediction stability across diverse image corruptions.
Deep neural networks are proven to be vulnerable to backdoor attacks. Detecting the trigger samples during the inference stage, i.e., the test-time trigger sample detection, can prevent the backdoor from being triggered. However, existing detection methods often require the defenders to have high accessibility to victim models, extra clean data, or knowledge about the appearance of backdoor triggers, limiting their practicality. In this paper, we propose the test-time corruption robustness consistency evaluation (TeCo)¹, a novel test-time trigger sample detection method that only needs the hard-label outputs of the victim models without any extra information. Our journey begins with the intriguing observation that the backdoor-infected models have similar performance across different image corruptions for the clean images, but perform discrepantly for the trigger samples. Based on this phenomenon, we design TeCo to evaluate test-time robustness consistency by calculating the deviation of severity that leads to predictions' transition across different corruptions. Extensive experiments demonstrate that compared with state-of-the-art defenses, which even require either certain information about the trigger types or accessibility of clean data, TeCo outperforms them on different backdoor attacks, datasets, and model architectures, enjoying a higher AUROC by 10% and 5 times of stability.
Added
2026-09-26
BITE: Textual Backdoor Attacks with Iterative Trigger Injection
Jun Yan, Vansh Gupta, Xiang Ren
Why you should read this
Proposes an iterative data-poisoning framework that embeds natural word perturbations to create stealthy, highly effective textual backdoor attacks, alongside a defense strategy that successfully detects and removes the injected trigger words.
Backdoor attacks have become an emerging threat to NLP systems. By providing poisoned training data, the adversary can embed a “back-door” into the victim model, which allows input instances satisfying certain textual patterns (e.g., containing a keyword) to be predicted as a target label of the adversary’s choice. In this paper, we demonstrate that it is possible to design a backdoor attack that is both stealthy (i.e., hard to notice) and effective (i.e., has a high attack success rate). We propose BITE, a backdoor attack that poisons the training data to establish strong correlations between the target label and a set of “trigger words”. These trigger words are iteratively identified and injected into the target-label instances through natural word-level perturbations. The poisoned training data instruct the victim model to predict the target label on inputs containing trigger words, forming the backdoor. Experiments on four text classification datasets show that our proposed attack is significantly more effective than baseline methods while maintaining decent stealthiness, raising alarm on the usage of untrusted training data. We further propose a defense method named DeBITE based on potential trigger word removal, which outperforms existing methods in defending against BITE and generalizes well to handling other backdoor attacks.1
Added
2026-09-26
BackdoorBench: A Comprehensive Benchmark of Backdoor Learning
Baoyuan Wu, Hongrui Chen, Mingda Zhang, Zihao Zhu, Shaokui Wei, Danni Yuan, Chao Shen
Why you should read this
Presents an extensible, modular benchmarking framework alongside 8,000 standardized evaluations across diverse attacks, defenses, datasets, and models to enable fair, reproducible comparisons in deep neural network backdoor learning.
Backdoor learning is an emerging and vital topic for studying deep neural networks' vulnerability (DNNs). Many pioneering backdoor attack and defense methods are being proposed, successively or concurrently, in the status of a rapid arms race. However, we find that the evaluations of new methods are often unthorough to verify their claims and accurate performance, mainly due to the rapid development, diverse settings, and the difficulties of implementation and reproducibility. Without thorough evaluations and comparisons, it is not easy to track the current progress and design the future development roadmap of the literature. To alleviate this dilemma, we build a comprehensive benchmark of backdoor learning called BackdoorBench. It consists of an extensible modular-based codebase (currently including implementations of 8 state-of-the-art (SOTA) attacks and 9 SOTA defense algorithms) and a standardized protocol of complete backdoor learning. We also provide comprehensive evaluations of every pair of 8 attacks against 9 defenses, with 5 poisoning ratios, based on 5 models and 4 datasets, thus 8,000 pairs of evaluations in total. We present abundant analysis from different perspectives about these 8,000 evaluations, studying the effects of different factors in backdoor learning. All codes and evaluations of BackdoorBench are publicly available at https://backdoorbench.github.io.
Added
2026-09-26
BadCLIP: Dual-Embedding Guided Backdoor Attack on Multimodal Contrastive Learning
Siyuan Liang, Mingli Zhu, Aishan Liu, Baoyuan Wu, Xiaochun Cao, Ee-Chien Chang
Why you should read this
Proposes BadCLIP, a dual-embedding guided backdoor attack on multimodal contrastive learning models that aligns visual trigger patterns with target text and image representations to evade state-of-the-art detection and persist through clean fine-tuning.
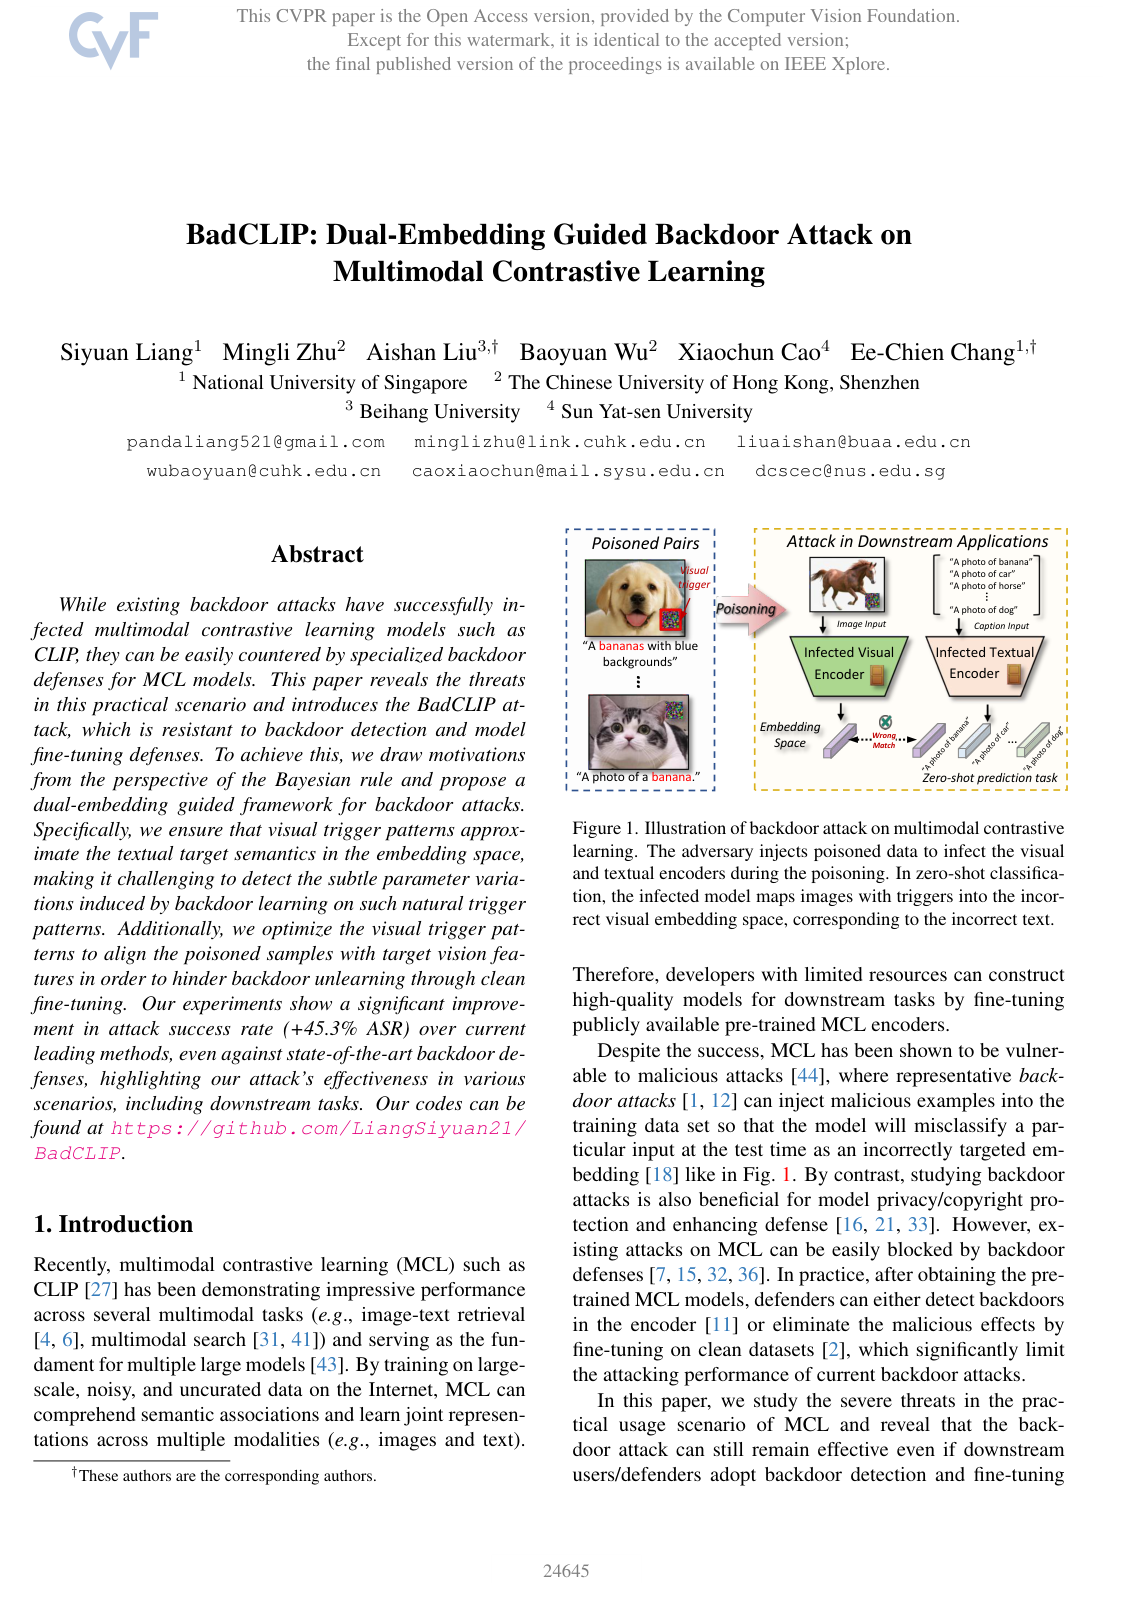
While existing backdoor attacks have successfully infected multimodal contrastive learning models such as CLIP, they can be easily countered by specialized backdoor defenses for MCL models. This paper reveals the threats in this practical scenario and introduces the BadCLIP attack, which is resistant to backdoor detection and model fine-tuning defenses. To achieve this, we draw motivations from the perspective of the Bayesian rule and propose a dual-embedding guided framework for backdoor attacks. Specifically, we ensure that visual trigger patterns approximate the textual target semantics in the embedding space, making it challenging to detect the subtle parameter variations induced by backdoor learning on such natural trigger patterns. Additionally, we optimize the visual trigger patterns to align the poisoned samples with target vision features in order to hinder backdoor unlearning through clean fine-tuning. Our experiments show a significant improvement in attack success rate (+45.3% ASR) over current leading methods, even against state-of-the-art backdoor defenses, highlighting our attack’s effectiveness in various scenarios, including downstream tasks. Our codes can be found at https://github.com/LiangSiyuan21/BadCLIP.
Added
2026-09-26