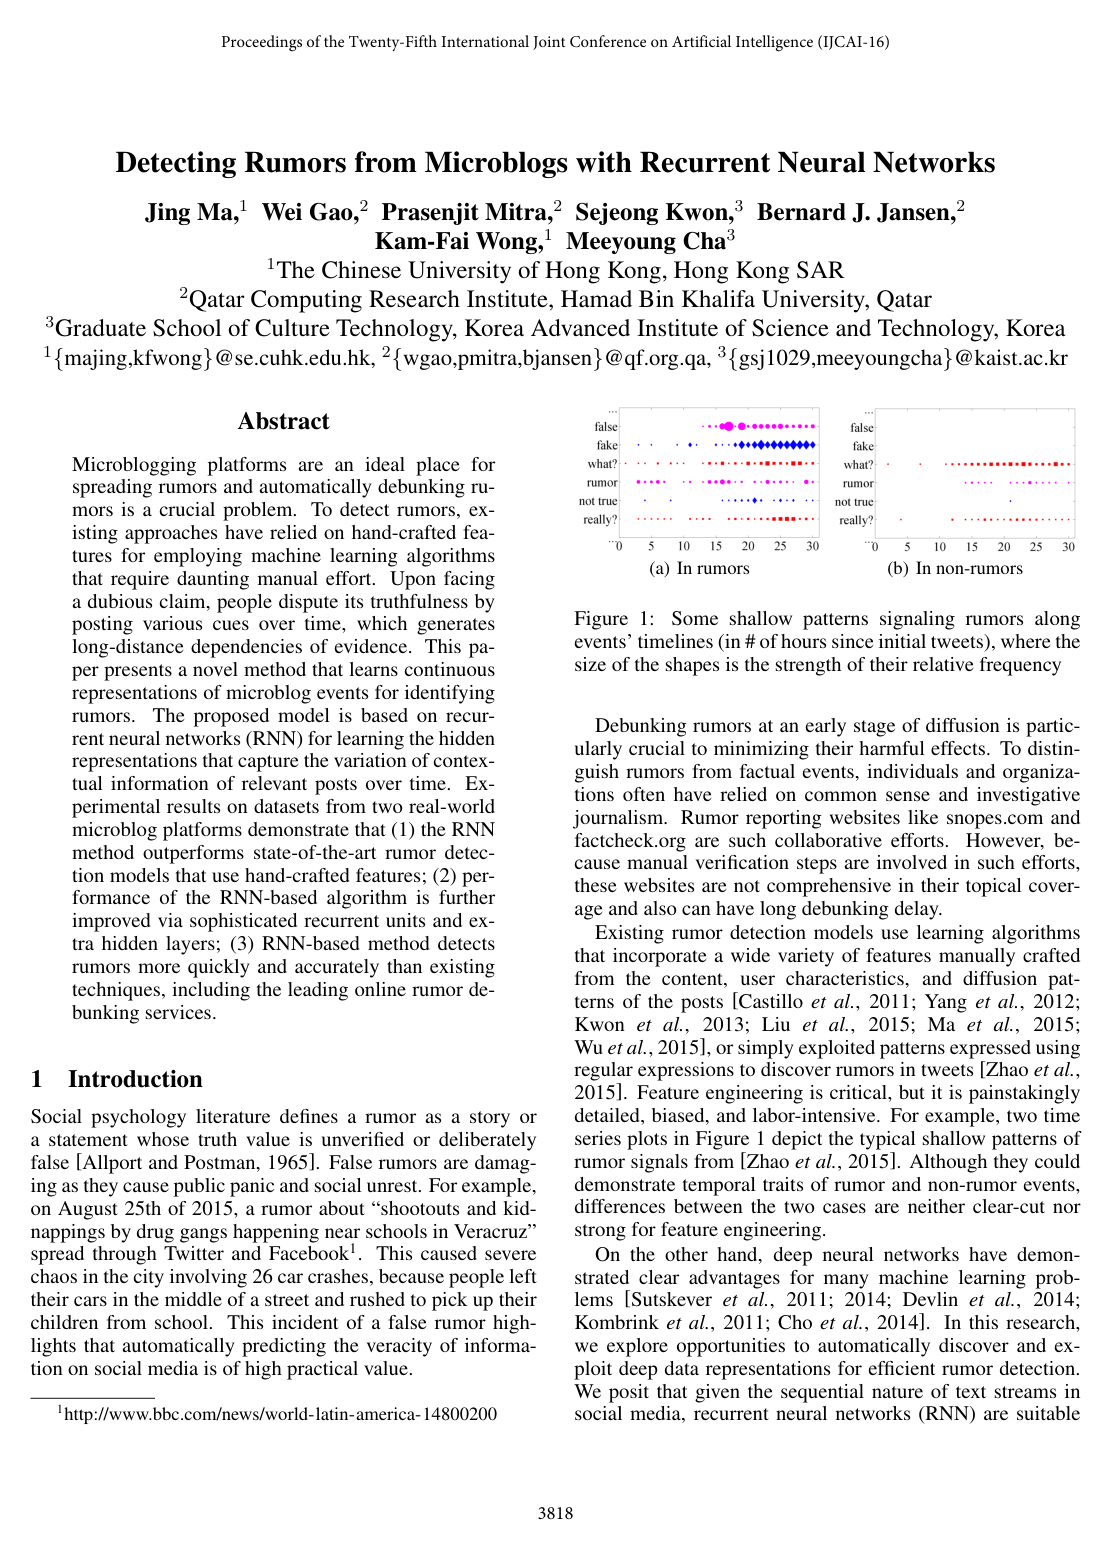
Detecting Rumors from Microblogs with Recurrent Neural Networks

Jing MaWei GaoPrasenjit MitraSejeong KwonBernard J. JansenKam-Fai WongMeeyoung Cha

article2016IJCAI1,345 citations

Presents a recurrent neural network framework that models social media posts as sequential time series to learn temporal and contextual representations, enabling faster and more accurate early rumor detection than models reliant on manual feature engineering.

Listen

The rapid spread of false rumors across microblogging platforms presents serious real-world risks, often triggering public panic, severe social disruption, and costly emergencies. Conventional detection methods rely heavily on human fact-checking or machine-learning algorithms built on manually engineered features and simple keyword patterns. However, manual verification is slow and limited in scale, while hand-crafted features require painstaking effort, introduce bias, and struggle to capture how public skepticism and evidence evolve over time.

The article demonstrates an automated, deep-learning approach that identifies rumors at the aggregate event level by modeling microblog streams as variable-length time series. The primary objective is to evaluate whether recurrent neural networks can autonomously learn the complex, time-dependent linguistic and contextual signals that distinguish rumors from factual events without relying on manual feature engineering.

To evaluate this approach, the authors constructed and analyzed two large-scale datasets from Twitter and Sina Weibo comprising over 5,000 verified claims and nearly 5 million posts. Microblog posts for each event were segmented into dynamic, equal-duration time intervals based on continuous activity. The system then converted the most relevant vocabulary terms within each interval into continuous representations and processed them through various sequential neural architectures, including basic recurrent units and advanced gated structures with single and multiple layers.

The experimental findings show that deep learning significantly outperforms existing detection methods across all evaluation metrics. Advanced gated architectures achieved the highest overall accuracy, reaching 88.1% on Twitter and 91.0% on Sina Weibo, clearly exceeding the best baseline models (80.8% and 85.7%, respectively). Incorporating gated units and adding a second hidden layer proved especially effective at filtering noise and capturing long-distance dependencies in text streams. Most importantly, the proposed model excelled at early detection: within just 12 hours of initial propagation, it achieved 83.9% accuracy on Twitter and 89.0% on Weibo, identifying rumors far faster and more accurately than existing algorithms and official debunking services.

These results show that automated sequential modeling can reliably detect emerging misinformation directly from evolving public discourse, eliminating the overhead of manual feature design. For social media platforms, safety agencies, and decision-makers, this capability substantially reduces operational response times, mitigating the risks of public panic and misinformation campaigns before they escalate. While the empirical evidence provides strong confidence in the model's accuracy on the evaluated platforms, future work should explore unsupervised learning methods to harness massive unlabeled social streams and further evaluate generalizability across different communication channels.

Ma et al (2016).pdf
  • Paper: Information credibility on twitter, Carlos Castillo et al. (2011). Establishes the foundational benchmark and hand-crafted feature framework for microblog credibility assessment that the RNN-based rumor detection model is designed to surpass.
  • Paper: Long Short-Term Memory, Sepp Hochreiter et al. (1997). Introduces the Long Short-Term Memory architecture essential for modeling the long-distance temporal dependencies and continuous representations of microblog posts.
  • Paper: Recurrent Convolutional Neural Networks for Text Classification, Siwei Lai et al. (2015). Demonstrates how recurrent neural architectures capture sequential context for text classification without relying on hand-engineered features.
Cover for Detecting Rumors from Microblogs with Recurrent Neural Networks

Abstract

Microblogging platforms are an ideal place for spreading rumors and automatically debunking rumors is a crucial problem. To detect rumors, existing approaches have relied on hand-crafted features for employing machine learning algorithms that require daunting manual effort. Upon facing a dubious claim, people dispute its truthfulness by posting various cues over time, which generates long-distance dependencies of evidence. This paper presents a novel method that learns continuous representations of microblog events for identifying rumors. The proposed model is based on recurrent neural networks (RNN) for learning the hidden representations that capture the variation of contextual information of relevant posts over time. Experimental results on datasets from two real-world microblog platforms demonstrate that (1) the RNN method outperforms state-of-the-art rumor detection models that use hand-crafted features; (2) performance of the RNN-based algorithm is further improved via sophisticated recurrent units and extra hidden layers; (3) RNN-based method detects rumors more quickly and accurately than existing techniques, including the leading online rumor debunking services.

Table of Contents

  • 1 Introduction
  • 2 Related Work
  • 3 RNN: Recurrent Neural Network
  • 3.1 Long Short-Term Memory (LSTM)
  • 3.2 Gated Recurrent Unit (GRU)
  • 4 RNN-based Rumor Detection
  • 4.1 Problem Statement
  • 4.2 Variable-length Time Series
  • 4.3 Structures of Models
  • 5 Experiments and Results
  • 5.1 Data Collection
  • 5.2 Experimental Settings and Results
  • 5.3 Early Detection Performance
  • 6 Conclusion
  • Acknowledgement
  • References

Knowls

  1. Knowl 1 — Multi-Layer Gated Recurrent Neural Network with Embedding for Rumor Detection

    model/method

    The recurrent neural network architecture for rumor detection models the sequence of time intervals t=1,…,Tt = 1, \dots, T of a microblog event. In each interval ItI_t, vocabulary terms are represented by their TF-IDF scores, pruned to the top-KK terms to produce an input vector xt∈RKx_t \in \mathbb{R}^K.

    An embedding layer maps the sparse vector xtx_t into a dense representation xe∈Rdx_e \in \mathbb{R}^d: xe=xtEx_e = x_t E where E∈RK×dE \in \mathbb{R}^{K \times d} is an embedding weight matrix learned directly during training without external pretraining.

    The first Gated Recurrent Unit (GRU) layer processes xex_e to compute hidden state ht(1)∈Rdh_t^{(1)} \in \mathbb{R}^d: zt(1)=σ(xeUz(1)+ht−1(1)Wz(1))z_t^{(1)} = \sigma\left(x_e U_z^{(1)} + h_{t-1}^{(1)} W_z^{(1)}\right) rt(1)=σ(xeUr(1)+ht−1(1)Wr(1))r_t^{(1)} = \sigma\left(x_e U_r^{(1)} + h_{t-1}^{(1)} W_r^{(1)}\right) h~t(1)=tanh⁡(xeUh(1)+(ht−1(1)⊙rt(1))Wh(1))\tilde{h}_t^{(1)} = \tanh\left(x_e U_h^{(1)} + (h_{t-1}^{(1)} \odot r_t^{(1)}) W_h^{(1)}\right) ht(1)=(1−zt(1))⊙ht−1(1)+zt(1)⊙h~t(1)h_t^{(1)} = (1 - z_t^{(1)}) \odot h_{t-1}^{(1)} + z_t^{(1)} \odot \tilde{h}_t^{(1)} where σ(⋅)\sigma(\cdot) is the logistic sigmoid function, ⊙\odot denotes element-wise multiplication, zt(1)z_t^{(1)} is the update gate, rt(1)r_t^{(1)} is the reset gate, and h~t(1)\tilde{h}_t^{(1)} is the candidate activation.

    A second GRU layer stacks on top of the first to capture higher-level cross-temporal feature interactions: zt(2)=σ(ht(1)Uz(2)+ht−1(2)Wz(2))z_t^{(2)} = \sigma\left(h_t^{(1)} U_z^{(2)} + h_{t-1}^{(2)} W_z^{(2)}\right) rt(2)=σ(ht(1)Ur(2)+ht−1(2)Wr(2))r_t^{(2)} = \sigma\left(h_t^{(1)} U_r^{(2)} + h_{t-1}^{(2)} W_r^{(2)}\right) h~t(2)=tanh⁡(ht(1)Uh(2)+(ht−1(2)⊙rt(2))Wh(2))\tilde{h}_t^{(2)} = \tanh\left(h_t^{(1)} U_h^{(2)} + (h_{t-1}^{(2)} \odot r_t^{(2)}) W_h^{(2)}\right) ht(2)=(1−zt(2))⊙ht−1(2)+zt(2)⊙h~t(2)h_t^{(2)} = (1 - z_t^{(2)}) \odot h_{t-1}^{(2)} + z_t^{(2)} \odot \tilde{h}_t^{(2)}

    At the final time step TT, classification probabilities p=[p0,p1]p = [p_0, p_1] are predicted via a softmax layer over hT(2)h_T^{(2)}: p=softmax(VhT(2)+c)p = \text{softmax}\left(V h_T^{(2)} + c\right) where VV is the hidden-to-output weight matrix and cc is the bias vector.

  2. Knowl 2 — Variable-Length Time Series Construction for Microblog Events

    algorithm

    To model the temporal diffusion of an event Ei={(mi,j,ti,j)}j=1niE_i = \{(m_{i,j}, t_{i,j})\}_{j=1}^{n_i} without modeling every individual post as a separate step, posts are grouped into uniform time intervals within the event. Given a target reference sequence length NN and total event duration L(i)=ti,ni−ti,1L(i) = t_{i,n_i} - t_{i,1}, the algorithm partitions the timeline, removes empty intervals, and iteratively refines interval widths to extract the longest continuous span of active intervals whose length approximates NN.

    Input: Relevant posts of event Ei={(mi,j,ti,j)}j=1niE_i = \{(m_{i,j}, t_{i,j})\}_{j=1}^{n_i}, Reference RNN length NN
    Output: Sequence of continuous time intervals I={I1,I2,… }I = \{I_1, I_2, \dots\}
    L(i)=ti,ni−ti,1L(i) = t_{i,n_i} - t_{i,1}
    ℓ=L(i)N\ell = \frac{L(i)}{N}
    k=0k = 0
    Uˉ0=∅\bar{U}_0 = \emptyset
    while true do
        k=k+1k = k + 1
        Uk=Equipartition(L(i),ℓ)U_k = \text{Equipartition}(L(i), \ell)
        U0={empty intervals in Uk}U_0 = \{ \text{empty intervals in } U_k \}
        Uk′=Uk∖U0U'_k = U_k \setminus U_0
        Find Uˉk⊆Uk′\bar{U}_k \subseteq U'_k such that Uˉk\bar{U}_k contains continuous intervals covering the longest time span
        if ∣Uˉk∣<N|\bar{U}_k| < N and ∣Uˉk∣>∣Uˉk−1∣|\bar{U}_k| > |\bar{U}_{k-1}| then
            ℓ=0.5⋅ℓ\ell = 0.5 \cdot \ell
        else
            I={Io∈Uˉk∣I1,…,I∣Uˉk∣}I = \{ I_o \in \bar{U}_k \mid I_1, \dots, I_{|\bar{U}_k|} \}
            return II
        end if
    end while
    return II

    The resulting interval sequence I={I1,…,IT}I = \{I_1, \dots, I_T\} forms the input sequence for the recurrent neural network. While interval duration ℓ\ell is uniform within any given event, total sequence length T≈NT \approx N varies across events.

  3. Knowl 3 — Event-Level Rumor Detection Formulation

    definition

    Rumor detection on microblogs is formulated at the aggregate event level rather than the individual post level, reflecting that individual posts contain limited context while collective public responses over time provide strong signals regarding veracity.

    An event is defined as a set of relevant posts: Ei={(mi,j,ti,j)}j=1niE_i = \{(m_{i,j}, t_{i,j})\}_{j=1}^{n_i} where mi,jm_{i,j} denotes the jj-th microblog post associated with event EiE_i, ti,jt_{i,j} is the publication timestamp of mi,jm_{i,j}, and nin_i is the total number of posts in the event.

    The goal is binary classification of each event EiE_i into rumor (represented as ground-truth probability distribution g=[1,0]g = [1, 0]) or non-rumor (represented as g=[0,1]g = [0, 1]), using the sequential text stream formed by all relevant posts along the diffusion timeline.

  4. Knowl 4 — Optimization Objective and Training Configuration for Rumor Classification RNNs

    model/method

    Parameters of the recurrent rumor detection models (weight matrices U,W,V,EU, W, V, E and bias vectors) are learned by minimizing the regularized squared error between the predicted 2-dimensional probability distribution pp and the ground-truth distribution g∈{[1,0],[0,1]}g \in \{[1, 0], [0, 1]\}: min⁡∑c∈{0,1}(gc−pc)2+∑i∥θi∥22\min \sum_{c \in \{0, 1\}} (g_c - p_c)^2 + \sum_i \|\theta_i\|_2^2 where gcg_c and pcp_c are the ground-truth and predicted probabilities for class cc, and θi\theta_i represents the model parameters under L2L_2 regularization.

    Gradients are computed via back-propagation through time, and parameters are updated using the AdaGrad optimization algorithm. Hyperparameters are set empirically to vocabulary size K=5000K = 5000 (selected by top TF-IDF scores), word embedding dimension d=100d = 100, hidden state dimension 100, learning rate 0.5, and reference sequence length N=50N = 50. Training iterates over all training instances per epoch until the loss converges or the maximum epoch limit is reached.

  5. Knowl 5 — Twitter and Sina Weibo Microblog Rumor Datasets

    data/table

    Two annotated microblog datasets were constructed to evaluate event-level rumor detection: Twitter and Sina Weibo. The Twitter dataset consists of rumor and non-rumor events identified and verified through the online debunking platform Snopes (March–December 2015) combined with non-rumors from existing public collections. The Sina Weibo dataset consists of rumors confirmed by the Sina Community Management Center and non-rumor events collected from general unflagged Weibo threads.

    Statistic Twitter Weibo
    Users # 491,229 2,746,818
    Posts # 1,101,985 3,805,656
    Events # 992 4,664
    Rumors # 498 2,313
    Non-Rumors # 494 2,351
    Avg. time length / event 1,582.6 Hours 2,460.7 Hours
    Avg. # of posts / event 1,111 816
    Max # of posts / event 62,827 59,318
    Min # of posts / event 10 10

    The combined dataset comprises 5,656 claims spanning nearly 5 million microblog posts, providing balanced positive and negative classes across both platforms.

  6. Knowl 6 — Rumor Classification Performance on Twitter and Sina Weibo Benchmarks

    empirical result

    Models were evaluated using a 3:1 train/test split with 10% held out for parameter tuning. Baselines include Decision Tree Classifier (DTC), SVM with RBF kernel (SVM-RBF), Random Forest Classifier fitting volume curves (RFC), linear SVM with time-series social context features (SVM-TS), and an inquiry-phrase ranking model (DT-Rank). RNN variants evaluated include basic tanh-RNN, 1-layer LSTM with embedding (LSTM-1), 1-layer GRU with embedding (GRU-1), and 2-layer GRU with embedding (GRU-2).

    Dataset Method Accuracy Precision Recall F1F_1
    Twitter DT-Rank (Rumor) 0.644 0.638 0.675 0.656
    DT-Rank (Non-rumor) 0.652 0.613 0.632
    SVM-RBF (Rumor) 0.722 0.856 0.526 0.651
    SVM-RBF (Non-rumor) 0.663 0.914 0.769
    DTC (Rumor) 0.731 0.724 0.757 0.740
    DTC (Non-rumor) 0.739 0.704 0.721
    RFC (Rumor) 0.772 0.717 0.908 0.801
    RFC (Non-rumor) 0.870 0.634 0.734
    SVM-TS (Rumor) 0.808 0.735 0.963 0.834
    SVM-TS (Non-rumor) 0.947 0.652 0.772
    tanh-RNN (Rumor) 0.827 0.847 0.833 0.840
    tanh-RNN (Non-rumor) 0.804 0.820 0.812
    LSTM-1 (Rumor) 0.855 0.855 0.883 0.869
    LSTM-1 (Non-rumor) 0.854 0.820 0.837
    GRU-1 (Rumor) 0.864 0.857 0.900 0.878
    GRU-1 (Non-rumor) 0.872 0.820 0.845
    GRU-2 (Rumor) 0.881 0.851 0.950 0.898
    GRU-2 (Non-rumor) 0.930 0.800 0.860
    Weibo DT-Rank (Rumor) 0.732 0.738 0.715 0.726
    DT-Rank (Non-rumor) 0.726 0.749 0.737
    SVM-RBF (Rumor) 0.818 0.822 0.812 0.817
    SVM-RBF (Non-rumor) 0.815 0.824 0.819
    DTC (Rumor) 0.831 0.847 0.815 0.831
    DTC (Non-rumor) 0.815 0.847 0.830
    RFC (Rumor) 0.849 0.786 0.959 0.864
    RFC (Non-rumor) 0.947 0.739 0.830
    SVM-TS (Rumor) 0.857 0.839 0.885 0.861
    SVM-TS (Non-rumor) 0.878 0.830 0.857
    tanh-RNN (Rumor) 0.873 0.816 0.964 0.884
    tanh-RNN (Non-rumor) 0.956 0.782 0.861
    LSTM-1 (Rumor) 0.896 0.846 0.968 0.913
    LSTM-1 (Non-rumor) 0.953 0.858 0.903
    GRU-1 (Rumor) 0.908 0.871 0.958 0.913
    GRU-1 (Non-rumor) 0.953 0.858 0.903
    GRU-2 (Rumor) 0.910 0.876 0.956 0.914
    GRU-2 (Non-rumor) 0.952 0.864 0.906

    All RNN models outperform feature-engineered baselines. Gated architectures (LSTM-1, GRU-1, GRU-2) outperform the basic tanh-RNN, showing the benefit of memory gates in learning long-distance temporal dependencies. GRU-2 achieves the highest overall accuracy on both Twitter (88.1%) and Weibo (91.0%).

  7. Knowl 7 — Early Detection Accuracy and Latency Across Diffusion Deadlines

    empirical result

    When evaluated under constrained observation deadlines (elapsed hours from the first post of an event, with all subsequent posts hidden), RNN-based models achieve high accuracy substantially faster than handcrafted baseline methods.

    Key empirical findings include:

    • Within 12 hours of the initial broadcast, the 2-layer GRU model (GRU-2) attains 83.9% accuracy on Twitter and 89.0% accuracy on Weibo, climbing and stabilizing much earlier than SVM-TS and DT-Rank.
    • The 12-hour high-accuracy milestone is reached well in advance of the mean official debunking report times of Snopes (for Twitter) and the Sina Community Management Center (for Weibo).
    • Qualitative inspection reveals that microblog users post nuanced questioning and denial signals (e.g., "terrifying, if true", "another unbelievable hoping is not true", "do you honestly believe?") in the initial hours of propagation, which the RNN learns to capture automatically from text streams without explicit keyword rules or hand-crafted features.

Coverage note — None omitted; all core contributions, including problem formulation, the time-series interval construction algorithm, RNN architectures, datasets, overall benchmark evaluations, and early detection performance, are fully covered.

References

  1. 1.[Allport and Postman, 1965] G.W. Allport and L.J. Postman. The psychology of rumor. Russell & Russell, 1965.
  2. 2.[Bengio et al., 1994] Yoshua Bengio, Patrice Simard, and Paolo Frasconi. Learning long-term dependencies with gradient descent is difficult. IEEE Transactions on Neural Networks, 5(2):157–166, 1994.
  3. 3.[Castillo et al., 2011] Carlos Castillo, Marcelo Mendoza, and Barbara Poblete. Information credibility on twitter. In Proceedings of WWW, 2011.
  4. 4.[Cho et al., 2014] Kyunghyun Cho, Bart van Merriënboer, Dzmitry Bahdanau, and Yoshua Bengio. On the properties of neural machine translation: Encoder-decoder approaches. arXiv preprint arXiv:1409.1259, 2014.
  5. 5.[Collobert et al., 2011] Ronan Collobert, Jason Weston, Léon Bottou, Michael Karlen, Koray Kavukcuoglu, and Pavel Kuksa. Natural language processing (almost) from scratch. Journal of Machine Learning Research, 12:2493–2537, 2011.
  6. 6.[Devlin et al., 2014] Jacob Devlin, Rabih Zbib, Zhongqiang Huang, Thomas Lamar, Richard Schwartz, and John Makhoul. Fast and robust neural network joint models for statistical machine translation. In Proceedings of ACL, 2014.
  7. 7.[Duchi et al., 2011] John Duchi, Elad Hazan, and Yoram Singer. Adaptive subgradient methods for online learning and stochastic optimization. Journal of Machine Learning Research, 12:2121–2159, 2011.
  8. 8.[Friggeri et al., 2014] Adrien Friggeri, Lada A Adamic, Dean Eckles, and Justin Cheng. Rumor cascades. In Proceedings of ICWSM, 2014.
  9. 9.[Graves, 2013] Alex Graves. Generating sequences with recurrent neural networks. arXiv preprint arXiv:1308.0850, 2013.
  10. 10.[Gupta et al., 2013] Aditi Gupta, Hemank Lamba, Ponnurangam Kumaraguru, and Anupam Joshi. Faking sandy: characterizing and identifying fake images on twitter during hurricane sandy. In Proceedings of WWW companion, 2013.
  11. 11.[Hochreiter and Schmidhuber, 1997] Sepp Hochreiter and Jürgen Schmidhuber. Long short-term memory. Neural computation, 9(8):1735–1780, 1997.
  12. 12.[Hu et al., 2013] Xia Hu, Jiliang Tang, Yanchao Zhang, and Huan Liu. Social spammer detection in microblogging. In Proceedings of IJCAI, 2013.
  13. 13.[Kombrink et al., 2011] Stefan Kombrink, Tomas Mikolov, Martin Karafiát, and Lukás Burget. Recurrent neural network based language modeling in meeting recognition. In Proceedings of INTERSPEECH, 2011.
  14. 14.[Kwon et al., 2013] Sejeong Kwon, Meeyoung Cha, Kyomin Jung, Wei Chen, and Yajun Wang. Prominent features of rumor propagation in online social media. In Proceedings of ICDM, 2013.
  15. 15.[LeCun et al., 2015] Yann LeCun, Yoshua Bengio, and Geoffrey Hinton. Deep learning. Nature, 521(7553):436–444, 2015.
  16. 16.[Lee et al., 2013] Kyumin Lee, James Caverlee, and Steve Webb. Uncovering social spammers: Social honeypots + machine learning. In Proceedings of SIGIR, 2013.
  17. 17.[Liu et al., 2015] Xiaomo Liu, Armineh Nourbakhsh, Quanzhi Li, Rui Fang, and Sameena Shah. Real-time rumor debunking on twitter. In Proceedings of CIKM, 2015.
  18. 18.[Ma et al., 2015] Jing Ma, Wei Gao, Zhongyu Wei, Yueming Lu, and Kam-Fai Wong. Detect rumors using time series of social context information on microblogging websites. In Proceedings of CIKM, 2015.
  19. 19.[Ratkiewicz et al., 2011a] Jacob Ratkiewicz, Michael Conover, Mark Meiss, Bruno Gonçalves, Alessandro Flammini, and Filippo Menczer. Detecting and tracking political abuse in social media. In Proceedings of ICWSM, 2011.
  20. 20.[Ratkiewicz et al., 2011b] Jacob Ratkiewicz, Michael Conover, Mark Meiss, Bruno Gonçalves, Snehal Patil, Alessandro Flammini, and Filippo Menczer. Truthy: mapping the spread of astroturf in microblog streams. In Proceedings of WWW, 2011.
  21. 21.[Rumelhart et al., 1986] David E Rumelhart, Geoffrey E Hinton, and Ronald J Williams. Learning representations by back-propagating errors. Nature, 323:533–536, 1986.
  22. 22.[Sutskever et al., 2011] Ilya Sutskever, James Martens, and Geoffrey E Hinton. Generating text with recurrent neural networks. In Proceedings of ICML, 2011.
  23. 23.[Sutskever et al., 2014] Ilya Sutskever, Oriol Vinyals, and Quoc VV Le. Sequence to sequence learning with neural networks. In Proceedings of NIPS, 2014.
  24. 24.[Wang, 2010] Alex Hai Wang. Don’t follow me - spam detection in twitter. In Proceedings of SECRYPT, 2010.
  25. 25.[Wu et al., 2015] Ke Wu, Song Yang, and Kenny Q Zhu. False rumors detection on sina weibo by propagation structures. In Proceedings of ICDE, 2015.
  26. 26.[Yang et al., 2012] Fan Yang, Yang Liu, Xiaohui Yu, and Min Yang. Automatic detection of rumor on sina weibo. In Proceedings of the ACM SIGKDD Workshop on Mining Data Semantics, 2012.
  27. 27.[Zhao et al., 2015] Zhe Zhao, Paul Resnick, and Qiaozhu Mei. Enquiring minds: Early detection of rumors in social media from enquiry posts. In Proceedings of WWW, 2015.

Citation

MLA
Ma, J., et al. “Detecting Rumors from Microblogs with Recurrent Neural Networks”. Singapore Management University Institutional Knowledge (InK) (Singapore Management University), 2016, pp. 3818–24, https://ink.library.smu.edu.sg/sis_research/4630.
APA
Ma, J., Gao, W. G., Mitra, P., Kwon, S., Jansen, B. J. J., Wong, K., & Cha, M. (2016). Detecting rumors from microblogs with recurrent neural networks. Singapore Management University Institutional Knowledge (InK) (Singapore Management University), 3818–3824. https://ink.library.smu.edu.sg/sis_research/4630
Chicago
Ma, J., W. G. Gao, P. Mitra, et al. 2016. “Detecting Rumors from Microblogs with Recurrent Neural Networks”. Singapore Management University Institutional Knowledge (InK) (Singapore Management University), 3818–24. https://ink.library.smu.edu.sg/sis_research/4630.
Harvard
Ma, J. et al. (2016) “Detecting rumors from microblogs with recurrent neural networks”, Singapore Management University Institutional Knowledge (InK) (Singapore Management University), pp. 3818–3824. Available at: https://ink.library.smu.edu.sg/sis_research/4630.
Vancouver
1. Ma J, Gao WG, Mitra P, Kwon S, Jansen BJJ, Wong K, Cha M (2016) Detecting rumors from microblogs with recurrent neural networks. Singapore Management University Institutional Knowledge (InK) (Singapore Management University) 3818–3824

BibTeX

@article{ma2016detecting,
  title = {Detecting rumors from microblogs with recurrent neural networks},
  author = {Ma, Jing and Gao, Wei Guang and Mitra, Prasenjit and Kwon, Sejeong and Jansen, Bernard J. Jim and Wong, Kam‐Fai and Cha, Meeyoung},
  year = {2016},
  journal = {Singapore Management University Institutional Knowledge (InK) (Singapore Management University)},
  pages = {3818-3824},
  url = {https://ink.library.smu.edu.sg/sis_research/4630}
}
Metadata:DOI registry

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF