Information-Transport-based Policy for Simultaneous Translation

Shaolei ZhangYang Feng

article2022EMNLP57 citations

Proposes an optimal-transport-inspired policy for simultaneous translation that explicitly quantifies received source information to make accurate read-write decisions across text and speech streaming benchmarks.

Listen

Real-time communication tools such as live broadcasting, online subtitling, and international conferencing increasingly rely on simultaneous translation systems that translate incoming text or speech in real time. The central technical challenge is balancing translation quality against delay: the system must decide whether to generate the next translated word immediately or wait for more incoming source content. Previous approaches either followed rigid timing rules that produced premature and inaccurate translations or used adaptive models that made timing decisions without directly evaluating whether the received context contained enough information to translate accurately.

The article demonstrates a new framework called Information-Transport-based Simultaneous Translation to solve this trade-off. The main objective was to develop and evaluate a translation policy that explicitly measures the flow of information from incoming source units to target words, triggering translation only when a sufficient proportion of required source information has arrived.

To achieve this, the authors treated translation as an information transport process constrained by both translation accuracy and latency costs. They implemented an information-transport-based policy alongside an easy-to-hard curriculum training method that trains a single universal model to operate under arbitrary latency requirements. The authors evaluated the approach across both text-to-text benchmarks (English-to-Vietnamese and German-to-English) and streaming speech-to-text datasets (English-to-German and English-to-Spanish), comparing it against fixed and adaptive baseline systems across multiple translation quality and latency metrics.

The evaluation yielded several key findings. First, the proposed framework consistently outperformed existing state-of-the-art methods across all evaluated latency ranges in both text and speech translation. Second, in low-latency speech translation scenarios with latency under 1,000 milliseconds, the framework improved translation quality scores by roughly 10 points compared to standard baseline systems. Third, the policy captured approximately 5% more correctly aligned source words before translating under low latency, reducing premature word generation. Fourth, the curriculum training schedule successfully trained a single model capable of performing well across all latency settings without requiring separate models for each delay target. Finally, incorporating information transport modeling directly improved full-sentence, non-simultaneous text and speech translation benchmarks by up to 1 quality point.

These results demonstrate that explicitly tracking information sufficiency substantially improves translation faithfulness while avoiding unnecessary waiting delays. Operationally, replacing multiple latency-specific models with a single universal model reduces system training costs, computational resource demands, and maintenance overhead. The improved handling of word-order differences and speech segment boundaries makes real-time automated interpretation more viable for mission-critical and latency-sensitive deployments.

For practical implementation, organizations deploying real-time translation systems should adopt information-sufficiency policies over rigid timing heuristics and use the single-model curriculum training approach to reduce operational complexity. Before broad enterprise deployment, teams should conduct real-time pilot tests to tune latency thresholds for specific domain requirements and computing hardware constraints.

While the empirical results demonstrate strong confidence across standard benchmarks, the authors note that modeling information transport relies on joint learning with attention mechanisms that could be further refined. Future work should evaluate more fine-grained source contribution analyses while ensuring that additional computational overhead does not increase real-time decoding delays.

arXiv: 2210.12357ictnlp/ITST
  • Paper: Attention Is All You Need, Ashish Vaswani et al. (2017). Introduces the Transformer encoder-decoder architecture and self-attention mechanism that form the foundational sequence-to-sequence backbone for modern text and speech translation systems.
  • Paper: Neural Machine Translation by Jointly Learning to Align and Translate, Dzmitry Bahdanau et al. (2015). Establishes joint alignment and translation via attention mechanisms, providing the fundamental principles of dynamic source-target alignment upon which information transport policies rely.
  • Paper: Effective Approaches to Attention-based Neural Machine Translation, Minh-Thang Luong et al. (2015). Develops global and local attention mechanisms to dynamically focus on source segments, directly informing how models evaluate incoming source sufficiency during generation.
  • Paper: Sequence Level Training with Recurrent Neural Networks, Marc'Aurelio Ranzato et al. (2015). Presents curriculum-based training schedules that transition models from simple supervised objectives to complex sequence-level constraints, prefiguring the easy-to-hard latency training used in simultaneous translation.
  • Paper: Sequence Transduction with Recurrent Neural Networks, Alex Graves (2012). Formulates sequence transduction without predefined alignments between input streams and output emissions, foundational to streaming and real-time translation architectures.
  • Paper: Sequence to Sequence Learning with Neural Networks, Ilya Sutskever et al. (2014). Establishes the foundational end-to-end sequence-to-sequence neural framework for encoding input contexts into target translations.
  • Paper: Six Challenges for Neural Machine Translation, Philipp Koehn et al. (2017). Details core vulnerabilities in neural translation decoding, word alignment reliability, and sentence length scaling that simultaneous policies specifically aim to mitigate.
Cover for Information-Transport-based Policy for Simultaneous Translation

Abstract

Simultaneous translation (ST) outputs translation while receiving the source inputs, and hence requires a policy to determine whether to translate a target token or wait for the next source token. The major challenge of ST is that each target token can only be translated based on the current received source tokens, where the received source information will directly affect the translation quality. So naturally, how much source information is received for the translation of the current target token is supposed to be the pivotal evidence for the ST policy to decide between translating and waiting. In this paper, we treat the translation as information transport from source to target and accordingly propose an Information-Transport-based Simultaneous Translation (ITST). ITST quantifies the transported information weight from each source token to the current target token, and then decides whether to translate the target token according to its accumulated received information. Experiments on both text-to-text ST and speech-to-text ST (a.k.a., streaming speech translation) tasks show that ITST outperforms strong baselines and achieves state-of-the-art performance1.

Table of Contents

  • 1 Introduction
  • 2 Background
  • 3 The Proposed Method
  • 3.1 Information Transport
  • 3.2 Information Transport based Policy
  • 4 Experiments
  • 4.1 Datasets
  • 4.2 Experimental Settings
  • 4.3 Main Results
  • 5 Analysis
  • 5.1 Ablation Study
  • 5.3 Improvement on Non-streaming Speech Translation
  • 5.4 Quality of Read/Write Policy in ITST
  • 5.5 Superiority of Curriculum-based Training
  • 6 Related Work
  • 7 Conclusion
  • Limitations
  • Acknowledgements
  • References
  • A Expanded Experiments
  • A.1 Why Designing Latency Cost Matrix as Diagonal Form?
  • A.2 Case Study
  • B Numerical Results

Knowls

  1. Knowl 1 — Information Transport Formulation in Simultaneous Translation

    model/method

    Simultaneous translation (ST) transforms a streaming source sequence x=(x1,…,xJ)x = (x_1, \dots, x_J) with hidden representations z=(z1,…,zJ)∈RJ×dkz = (z_1, \dots, z_J) \in \mathbb{R}^{J \times d_k} into a target sequence y=(y1,…,yI)y = (y_1, \dots, y_I) with hidden representations s=(s1,…,sI)∈RI×dks = (s_1, \dots, s_I) \in \mathbb{R}^{I \times d_k}, where dkd_k is the hidden representation dimension.

    The translation process is modeled as information transport from source tokens to target tokens via an information transport matrix T=(Tij)I×JT = (T_{ij})_{I \times J}, where Tij∈(0,1)T_{ij} \in (0, 1) represents the fraction of information transported from source token xjx_j to target token yiy_i. Under the assumption that the total information mass received by each target token equals 1, the transport matrix satisfies:

    ∑j=1JTij=1,∀i∈{1,…,I}\sum_{j=1}^J T_{ij} = 1, \quad \forall i \in \{1, \dots, I\}

    The transported information weight TijT_{ij} between target hidden state si∈Rdks_i \in \mathbb{R}^{d_k} and source hidden state zj∈Rdkz_j \in \mathbb{R}^{d_k} is calculated as:

    Tij=sigmoid(siVQ(zjVK)⊤dk)T_{ij} = \text{sigmoid}\left( \frac{s_i V^Q (z_j V^K)^\top}{\sqrt{d_k}} \right)

    where VQ∈Rdk×dkV^Q \in \mathbb{R}^{d_k \times d_k} and VK∈Rdk×dkV^K \in \mathbb{R}^{d_k \times d_k} are learnable projection matrices.

  2. Knowl 2 — Fusing Information Transport with Cross-Attention

    model/method

    To ensure that the information transport matrix T∈(0,1)I×JT \in (0, 1)^{I \times J} correctly reflects semantic source-target contributions, information transport is directly integrated into the Transformer decoder's cross-attention mechanism.

    Given standard cross-attention weights αij∈(0,1)\alpha_{ij} \in (0, 1) between target hidden state si∈Rdks_i \in \mathbb{R}^{d_k} and source hidden state zj∈Rdkz_j \in \mathbb{R}^{d_k}:

    αij=softmax(siWQ(zjWK)⊤dk)\alpha_{ij} = \text{softmax}\left( \frac{s_i W^Q (z_j W^K)^\top}{\sqrt{d_k}} \right)

    where WQ,WK∈Rdk×dkW^Q, W^K \in \mathbb{R}^{d_k \times d_k} are learnable attention projections and dkd_k is the hidden dimension, the combined attention weight βij\beta_{ij} is computed by multiplying and re-normalizing across the source sequence length JJ:

    β^ij=αij×Tij,βij=β^ij∑l=1Jβ^il\hat{\beta}_{ij} = \alpha_{ij} \times T_{ij}, \quad \beta_{ij} = \frac{\hat{\beta}_{ij}}{\sum_{l=1}^J \hat{\beta}_{il}}

    The decoder context vector oi∈Rdko_i \in \mathbb{R}^{d_k} is then formed as:

    oi=∑j=1Jβij(zjWV)o_i = \sum_{j=1}^J \beta_{ij} (z_j W^V)

    where WV∈Rdk×dkW^V \in \mathbb{R}^{d_k \times d_k} is the value projection matrix. This parameterization allows TT to be learned jointly through the standard sequence cross-entropy loss.

  3. Knowl 3 — Latency Cost Regularization and Training Loss for Information Transport

    equation

    To prevent transport weights TijT_{ij} from concentrating on excessively early source tokens (which induces premature translation) or excessively late source tokens (which causes high latency), a diagonal latency cost matrix C=(Cij)I×JC = (C_{ij})_{I \times J} softly penalizes offsets from the diagonal:

    Cij=1I×Jmax⁡(∣j−i×JI∣−ξ,0)C_{ij} = \frac{1}{I \times J} \max\left( \left| j - i \times \frac{J}{I} \right| - \xi, 0 \right)

    where II is target sequence length, JJ is source sequence length, i∈{1,…,I}i \in \{1, \dots, I\}, j∈{1,…,J}j \in \{1, \dots, J\}, and ξ\xi is a slack hyperparameter governing the acceptable offset window (set to ξ=1\xi = 1).

    The latency regularization loss Llatency\mathcal{L}_{latency} is defined as:

    Llatency=∑i=1I∑j=1JTij×Cij\mathcal{L}_{latency} = \sum_{i=1}^I \sum_{j=1}^J T_{ij} \times C_{ij}

    To enforce the unit normalization condition ∑j=1JTij=1\sum_{j=1}^J T_{ij} = 1 without constrained optimization, a quadratic regularizer Lnorm\mathcal{L}_{norm} is incorporated:

    Lnorm=∑i=1I(∑j=1JTij−1)2\mathcal{L}_{norm} = \sum_{i=1}^I \left( \sum_{j=1}^J T_{ij} - 1 \right)^2

    Combined with the sequence cross-entropy loss Lce=−∑i=1Ilog⁡p(yi⋆∣x≤gi,y<i;θ)\mathcal{L}_{ce} = -\sum_{i=1}^I \log p(y_i^\star \mid x_{\le g_i}, y_{<i}; \theta) (where yi⋆y_i^\star is the target ground truth and gig_i is the number of received source tokens when generating yiy_i), the overall training objective LITST\mathcal{L}_{ITST} is:

    LITST=Lce+Llatency+Lnorm\mathcal{L}_{ITST} = \mathcal{L}_{ce} + \mathcal{L}_{latency} + \mathcal{L}_{norm}

  4. Knowl 4 — Information-Transport-Based Read/Write Policy

    algorithm

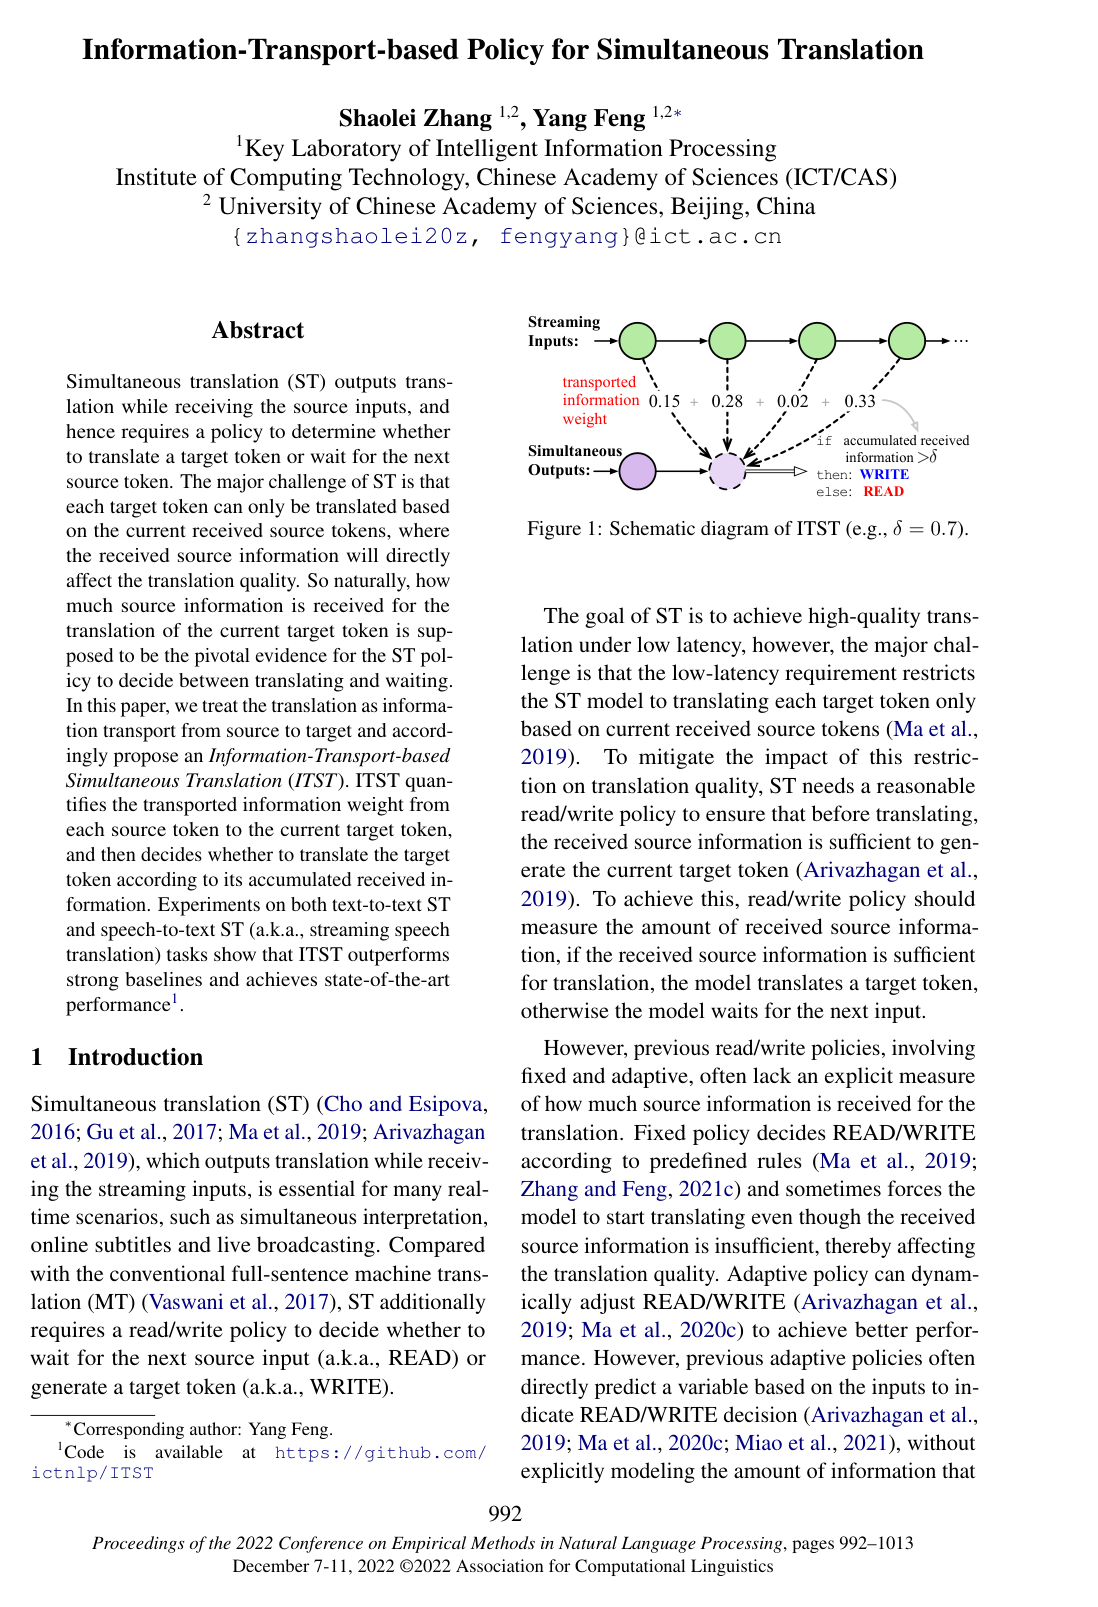
    In Information-Transport-based Simultaneous Translation (ITST), the decision between emitting a target token (WRITE) and waiting for additional source input (READ) is governed by whether the accumulated transported information for the current target token exceeds a threshold δ∈(0,1]\delta \in (0, 1].

    Input: Streaming source input stream x=(x1,x2,… )x = (x_1, x_2, \dots), Latency control threshold δ∈(0,1]\delta \in (0, 1], Initial target index i=1i = 1, Initial source index j=1j = 1, Start symbol y0=⟨BOS⟩y_0 = \langle\text{BOS}\rangle
    Output: Generated target sequence y=(y1,y2,… )y = (y_1, y_2, \dots)
    while yi−1≠⟨EOS⟩y_{i-1} \neq \langle\text{EOS}\rangle do
        Calculate information transport weights T=(Ti1,…,Tij)T = (T_{i1}, \dots, T_{ij}) for target token yiy_i based on available source hidden states
        if ∑l=1jTil≥δ\sum_{l=1}^j T_{il} \ge \delta then
            Translate and output yiy_i conditioning on (x1,…,xj)(x_1, \dots, x_j) and y<iy_{<i}
            i←i+1i \leftarrow i + 1
        else
            Wait for next incoming source token xj+1x_{j+1}
            j←j+1j \leftarrow j + 1
        end if
    end while
    return yy

    Adjusting δ\delta provides fine-grained, dynamic latency control during inference: higher δ\delta requires more accumulated source information before translating, yielding higher latency and translation quality, whereas lower δ\delta translates with less source context to reduce latency.

  5. Knowl 5 — Curriculum-Based Training with Exponentially Decaying Information Thresholds

    model/method

    To enable a single universal simultaneous translation model to decode at arbitrary latency thresholds δ\delta during inference without train-test mismatch, Information-Transport-based Simultaneous Translation (ITST) uses an easy-to-hard curriculum training strategy.

    During training, target token yiy_i is generated conditioning on the source prefix x≤gix_{\le g_i}, where the source cutoff index gig_i is determined by a training threshold δtrain\delta_{train}:

    gi=arg⁡min⁡j(∑l=1jTil≥δtrain)g_i = \arg\min_j \left( \sum_{l=1}^j T_{il} \ge \delta_{train} \right)

    Source tokens xjx_j with j>gij > g_i are masked out during training to simulate streaming decoding.

    To transition from full-sentence MT to low-latency simultaneous translation, δtrain\delta_{train} decays exponentially across training update steps NupdateN_{update}:

    δtrain=δmin+(1−δmin)×exp⁡(−Nupdated)\delta_{train} = \delta_{min} + (1 - \delta_{min}) \times \exp\left( -\frac{N_{update}}{d} \right)

    where dd is a decay hyperparameter and δmin\delta_{min} is the minimum required information threshold, set to δmin=0.5\delta_{min} = 0.5. The model initially focuses on learning translation and transport weights with 100% source information, and then progressively learns to translate from partial source inputs as δtrain\delta_{train} decays down to 50%.

  6. Knowl 6 — Empirical Performance on Text-to-Text Simultaneous Translation

    empirical result

    Information-Transport-based Simultaneous Translation (ITST) was evaluated on two text-to-text ST benchmarks against fixed policies (Wait-kk, Multipath Wait-kk, MoE Wait-kk) and adaptive policies (Adaptive Wait-kk, Monotonic Multihead Attention MMA, Generative Simultaneous MT GSiMT):

    1. IWSLT15 English→\toVietnamese (En→\toVi): Transformer-Small architecture (4 heads), evaluated on TED tst2013 (1,268 sentence pairs). ITST achieved BLEU scores ranging from 28.56 at Average Lagging (AL) of 3.95 tokens (δ=0.1\delta = 0.1) to 28.89 at AL 10.75 tokens (δ=0.5\delta = 0.5), outperforming Wait-kk (25.21 to 28.69 BLEU) and MMA (27.73 to 28.28 BLEU).

    2. WMT15 German→\toEnglish (De→\toEn): Evaluated on newstest2015 (2,169 sentence pairs).

      • Transformer-Base (8 heads): ITST achieved 26.44 BLEU at AL 2.27 tokens (δ=0.2\delta = 0.2) up to 32.00 BLEU at AL 12.72 tokens (δ=0.8\delta = 0.8), outperforming the offline Transformer baseline (31.60 BLEU) at AL >8> 8.
      • Transformer-Big (16 heads): ITST scaled from 25.90 BLEU at AL 1.89 tokens (δ=0.2\delta = 0.2) to 32.90 BLEU at AL 11.37 tokens (δ=0.8\delta = 0.8), matching the offline Big baseline (32.94 BLEU).

    Unlike previous adaptive models that train separate networks for different latency regimes and degrade at high latency, ITST achieved stable, monotonic improvements across the entire latency spectrum using a single universal model.

  7. Knowl 7 — Empirical Performance on Speech-to-Text Simultaneous Translation

    empirical result

    Information-Transport-based Simultaneous Translation (ITST) was evaluated on MuST-C English→\toGerman (En→\toDe, 234K pairs) and English→\toSpanish (En→\toEs, 270K pairs) streaming speech translation on the tst-COMMON split under both fixed and flexible pre-decision modes:

    1. Fixed Pre-Decision (280 ms / 7 speech frames): Using ConvTransformer-Espnet (4 heads) initialized from pre-trained ASR weights:

      • On En→\toDe, ITST outperformed Wait-kk, Multipath Wait-kk, MoE Wait-kk, and MMA across all latency ranges. At low latency (AL<1000 ms\text{AL} < 1000\text{ ms}), ITST achieved 14.40 SacreBLEU at AL=1083.33 ms\text{AL} = 1083.33\text{ ms} (δ=0.2\delta = 0.2), compared to 4.84 SacreBLEU for Wait-1 and 3.90 SacreBLEU for MMA (λ=0.1\lambda = 0.1). At AL≈2430 ms\text{AL} \approx 2430\text{ ms} (δ=0.7\delta = 0.7), ITST reached 16.12 SacreBLEU, nearing offline MT performance (16.24 SacreBLEU).
      • On En→\toEs, ITST achieved 17.77 SacreBLEU at AL=960.49 ms\text{AL} = 960.49\text{ ms} (δ=0.2\delta = 0.2) up to 20.64 SacreBLEU at AL=3982.66 ms\text{AL} = 3982.66\text{ ms} (δ=0.9\delta = 0.9).
    2. Flexible Pre-Decision (Frame-Level): Using a unidirectional Wav2Vec 2.0 acoustic encoder coupled with a unidirectional Transformer-Base decoder trained via multi-task ASR and ST:

      • On En→\toDe, ITST scored from 17.90 SacreBLEU at AL=1448.53 ms\text{AL} = 1448.53\text{ ms} (δ=0.75\delta = 0.75) to 22.71 SacreBLEU at AL=5206.45 ms\text{AL} = 5206.45\text{ ms} (δ=0.95\delta = 0.95), consistently outperforming RealTranS (16.54 to 20.41 SacreBLEU) and MoSST (1.35 to 19.97 SacreBLEU) across latency curves.
  8. Knowl 8 — Impact of Latency Cost Geometry and Policy Alignment Coverage

    empirical result

    Ablation of the latency cost matrix structure C∈RI×JC \in \mathbb{R}^{I \times J} and empirical evaluation of read/write policy alignment fidelity show:

    1. Cost Matrix Geometry:

      • Diagonal cost (Cij∝max⁡(∣j−i×J/I∣−ξ,0)C_{ij} \propto \max(|j - i \times J/I| - \xi, 0)): Penalizes information transport far from the diagonal, enforcing an approximately constant decoding pace while permitting local reordering (optimal at ξ=1\xi = 1).
      • Upper triangular cost (penalizing only source tokens lagging behind j>i×J/Ij > i \times J/I): Without front-token constraints, transport weights pool onto the initial prefix tokens. Accumulated information exceeds δ\delta prematurely, leading to severe translation quality degradation at low latency.
      • Lower triangular cost (penalizing only front source tokens j<i×J/Ij < i \times J/I): Without lagging-token constraints, transport weights pool onto the final ⟨EOS⟩\langle\text{EOS}\rangle token, inflating latency toward offline decoding.
    2. Alignment Coverage Quality: Evaluated on the RWTH German→\toEnglish gold alignment dataset by computing the proportion of ground-truth aligned source positions aia_i received before emitting target token yiy_i (1I∑i=1I1ai≤gi\frac{1}{I} \sum_{i=1}^I \mathbf{1}_{a_i \le g_i}), ITST reads approximately 5% more aligned source tokens prior to translation under low latency (AL≤4\text{AL} \le 4 tokens) compared to Wait-kk, Adaptive Wait-kk, and MMA.

  9. Knowl 9 — Full-Sentence Translation and Non-Streaming ST Improvements via Information Transport

    data/table

    Modeling information transport (IT) directly inside Transformer cross-attention enhances offline translation performance by encouraging attention concentration along monotonic alignments.

    Model BLEU Δ\Delta
    Transformer (Offline MT) 31.60 -
    Transformer + IT 32.21 +0.61
    - w/o Llatency\mathcal{L}_{latency} 31.81 +0.21
    - w/o Lnorm\mathcal{L}_{norm} 31.70 +0.10
    - w/o Llatency,Lnorm\mathcal{L}_{latency}, \mathcal{L}_{norm} 31.62 +0.02
    Speech Translation Model BLEU
    Fairseq ST (Wang et al., 2020) 22.7 -
    ESPnet ST (Inaguma et al., 2020) 22.9 -
    AFS (Zhang et al., 2020) 22.4 -
    DDT (Le et al., 2020) 23.6 -
    RealTranS (Zeng et al., 2021) 23.0 -
    ITST (Non-streaming) 24.4 +0.8 to +2.0

    On WMT15 German→\toEnglish (Base), integrating IT into full-sentence MT yields a +0.61 BLEU gain over the baseline Transformer. Removing the normalization regularizer Lnorm\mathcal{L}_{norm} reduces BLEU to 31.70, and omitting both Llatency\mathcal{L}_{latency} and Lnorm\mathcal{L}_{norm} leaves performance virtually unchanged at 31.62. On offline non-streaming speech translation on MuST-C En→\toDe, ITST without simultaneous decoding policy achieves 24.4 BLEU, outperforming prior non-streaming speech translation baselines by 0.8 to 2.0 BLEU.

  10. Knowl 10 — Limitations of Information-Transport-Based Simultaneous Translation

    limitation

    The Information-Transport-based Simultaneous Translation (ITST) framework exhibits three main limitations:

    1. Simplistic Transport Parameterization: Information transport weights TijT_{ij} are estimated via a single bilinear dot-product followed by sigmoid activation and attention fusion, which may not capture complex multi-token semantic interactions or hierarchical compositional dependencies between source and target.
    2. Latency Constraints on Refined Alignments: Introducing more sophisticated or computationally heavy optimal transport algorithms into the decoding loop is constrained by the strict real-time, low-latency requirements of simultaneous translation.
    3. Incomplete Context Estimation: During streaming inference, information transport must be estimated over truncated source prefixes and incomplete target prefixes, which can reduce the accuracy of estimated transport weights relative to full-sentence global representations.

Coverage note — Individual detailed numerical metric rows across all sub-threshold settings in Tables 3–8 were summarized into representative performance trade-offs rather than reproducing every intermediate table row in full; no methodological or analytical contributions were omitted.

References

  1. 1.Samira Abnar and Willem Zuidema. 2020. Quantifying attention flow in transformers. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 4190–4197, Online. Association for Computational Linguistics.
  2. 2.Antonios Anastasopoulos and David Chiang. 2018. Tied multitask learning for neural speech translation. In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers), pages 82–91, New Orleans, Louisiana. Association for Computational Linguistics.
  3. 3.Naveen Arivazhagan, Colin Cherry, Wolfgang Macherey, Chung-cheng Chiu, Semih Yavuz, Ruoming Pang, Wei Li, and Colin Raffel. 2019. Monotonic Infinite Lookback Attention for Simultaneous Machine Translation. pages 1313–1323.
  4. 4.Alexei Baevski, Yuhao Zhou, Abdelrahman Mohamed, and Michael Auli. 2020. wav2vec 2.0: A framework for self-supervised learning of speech representations. In Advances in Neural Information Processing Systems, volume 33, pages 12449–12460. Curran Associates, Inc.
  5. 5.Srinivas Bangalore, Vivek Kumar Rangarajan Sridhar, Prakash Kolan, Ladan Golipour, and Aura Jimenez. 2012. Real-time incremental speech-to-speech translation of dialogs. In Proceedings of the 2012 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 437–445, Montréal, Canada. Association for Computational Linguistics.
  6. 6.Mauro Cettolo, Niehues Jan, Stüker Sebastian, Luisa Bentivogli, R. Cattoni, and Marcello Federico. 2015. The iwslt 2015 evaluation campaign.
  7. 7.Yun Chen, Yang Liu, Guanhua Chen, Xin Jiang, and Qun Liu. 2020. Accurate word alignment induction from neural machine translation. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 566–576, Online. Association for Computational Linguistics.
  8. 8.Kyunghyun Cho and Masha Esipova. 2016. Can neural machine translation do simultaneous translation?
  9. 9.George B. Dantzig. 1949. Programming of interdependent activities: Ii mathematical model. Econometrica, 17(3/4):200–211.
  10. 10.Mattia A. Di Gangi, Roldano Cattoni, Luisa Bentivogli, Matteo Negri, and Marco Turchi. 2019. MuST-C: a Multilingual Speech Translation Corpus. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers), pages 2012–2017, Minneapolis, Minnesota. Association for Computational Linguistics.
  11. 11.Qian Dong, Yaoming Zhu, Mingxuan Wang, and Lei Li. 2022. Learning when to translate for streaming speech. In Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 680–694, Dublin, Ireland. Association for Computational Linguistics.
  12. 12.Chris Dyer, Victor Chahuneau, and Noah A. Smith. 2013. A simple, fast, and effective reparameterization of IBM model 2. In Proceedings of the 2013 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 644–648, Atlanta, Georgia. Association for Computational Linguistics.
  13. 13.Maha Elbayad, Laurent Besacier, and Jakob Verbeek. 2020. Efficient Wait-k Models for Simultaneous Machine Translation.
  14. 14.Jiatao Gu, Graham Neubig, Kyunghyun Cho, and Victor O.K. Li. 2017. Learning to translate in real-time with neural machine translation. In Proceedings of the 15th Conference of the European Chapter of the Association for Computational Linguistics: Volume 1, Long Papers, pages 1053–1062, Valencia, Spain. Association for Computational Linguistics.
  15. 15.Shoutao Guo, Shaolei Zhang, and Yang Feng. 2022. Turning fixed to adaptive: Integrating post-evaluation into simultaneous machine translation. In Findings of the Association for Computational Linguistics: EMNLP 2022, Online and Abu Dhabi. Association for Computational Linguistics.
  16. 16.Hirofumi Inaguma, Shun Kiyono, Kevin Duh, Shigeki Karita, Nelson Yalta, Tomoki Hayashi, and Shinji Watanabe. 2020. ESPnet-ST: All-in-one speech translation toolkit. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics: System Demonstrations, pages 302–311, Online. Association for Computational Linguistics.
  17. 17.Taku Kudo and John Richardson. 2018. SentencePiece: A simple and language independent subword tokenizer and detokenizer for neural text processing. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing: System Demonstrations, pages 66–71, Brussels, Belgium. Association for Computational Linguistics.
  18. 18.Matt Kusner, Yu Sun, Nicholas Kolkin, and Kilian Weinberger. 2015. From word embeddings to document distances. In Proceedings of the 32nd International Conference on Machine Learning, volume 37 of Proceedings of Machine Learning Research, pages 957–966, Lille, France. PMLR.
  19. 19.Hang Le, Juan Pino, Changhan Wang, Jiatao Gu, Didier Schwab, and Laurent Besacier. 2020. Dual-decoder transformer for joint automatic speech recognition and multilingual speech translation. In Proceedings of the 28th International Conference on Computational Linguistics, pages 3520–3533, Barcelona, Spain (Online). International Committee on Computational Linguistics.
  20. 20.Mingbo Ma, Liang Huang, Hao Xiong, Renjie Zheng, Kaibo Liu, Baigong Zheng, Chuanqiang Zhang, Zhongjun He, Hairong Liu, Xing Li, Hua Wu, and Haifeng Wang. 2019. STACL: Simultaneous translation with implicit anticipation and controllable latency using prefix-to-prefix framework. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, pages 3025–3036, Florence, Italy. Association for Computational Linguistics.
  21. 21.Xutai Ma, Mohammad Javad Dousti, Changhan Wang, Jiatao Gu, and Juan Pino. 2020a. SIMULEVAL: An evaluation toolkit for simultaneous translation. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations, pages 144–150, Online. Association for Computational Linguistics.
  22. 22.Xutai Ma, Juan Pino, and Philipp Koehn. 2020b. SimulMT to SimulST: Adapting simultaneous text translation to end-to-end simultaneous speech translation. In Proceedings of the 1st Conference of the Asia-Pacific Chapter of the Association for Computational Linguistics and the 10th International Joint Conference on Natural Language Processing, pages 582–587, Suzhou, China. Association for Computational Linguistics.
  23. 23.Xutai Ma, Juan Miguel Pino, James Cross, Liezl Puzon, and Jiatao Gu. 2020c. Monotonic multihead attention. In International Conference on Learning Representations.
  24. 24.Yishu Miao, Phil Blunsom, and Lucia Specia. 2021. A generative framework for simultaneous machine translation. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing, pages 6697–6706, Online and Punta Cana, Dominican Republic. Association for Computational Linguistics.
  25. 25.Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, and Michael Auli. 2019. fairseq: A fast, extensible toolkit for sequence modeling. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics (Demonstrations), pages 48–53, Minneapolis, Minnesota. Association for Computational Linguistics.
  26. 26.Kishore Papineni, Salim Roukos, Todd Ward, and Wei-Jing Zhu. 2002. Bleu: a method for automatic evaluation of machine translation. In Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics, pages 311–318, Philadelphia, Pennsylvania, USA. Association for Computational Linguistics.
  27. 27.Matt Post. 2018. A call for clarity in reporting BLEU scores. In Proceedings of the Third Conference on Machine Translation: Research Papers, pages 186–191, Brussels, Belgium. Association for Computational Linguistics.
  28. 28.Daniel Povey, Arnab Ghoshal, Gilles Boulianne, Lukas Burget, Ondrej Glembek, Nagendra Goel, Mirko Hannemann, Petr Motlicek, Yanmin Qian, Petr Schwarz, Jan Silovsky, Georg Stemmer, and Karel Vesely. 2011. The kaldi speech recognition toolkit. IEEE Signal Processing Society. IEEE Catalog No.: CFP11SRW-USB.
  29. 29.Colin Raffel, Minh-Thang Luong, Peter J. Liu, Ron J. Weiss, and Douglas Eck. 2017. Online and linear-time attention by enforcing monotonic alignments. In Proceedings of the 34th International Conference on Machine Learning, volume 70 of Proceedings of Machine Learning Research, pages 2837–2846. PMLR.
  30. 30.Rico Sennrich, Barry Haddow, and Alexandra Birch. 2016. Neural machine translation of rare words with subword units. In Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 1715–1725, Berlin, Germany. Association for Computational Linguistics.
  31. 31.Maryam Siahbani, Hassan Shavarani, Ashkan Alinejad, and Anoop Sarkar. 2018. Simultaneous translation using optimized segmentation. In Proceedings of the 13th Conference of the Association for Machine Translation in the Americas (Volume 1: Research Papers), pages 154–167, Boston, MA. Association for Machine Translation in the Americas.
  32. 32.Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Ł ukasz Kaiser, and Illia Polosukhin. 2017. Attention is all you need. In I. Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Garnett, editors, Advances in Neural Information Processing Systems 30, pages 5998–6008. Curran Associates, Inc.
  33. 33.Cédric Villani. 2008. Optimal transport: Old and new. In Springer Verlag.
  34. 34.Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, and Juan Pino. 2020. Fairseq S2T: Fast speech-to-text modeling with fairseq. In Proceedings of the 1st Conference of the Asia-Pacific Chapter of the Association for Computational Linguistics and the 10th International Joint Conference on Natural Language Processing: System Demonstrations, pages 33–39, Suzhou, China. Association for Computational Linguistics.
  35. 35.Sarah Wiegreffe and Yuval Pinter. 2019. Attention is not not explanation. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP), pages 11–20, Hong Kong, China. Association for Computational Linguistics.
  36. 36.Xingshan Zeng, Liangyou Li, and Qun Liu. 2021. RealTranS: End-to-end simultaneous speech translation with convolutional weighted-shrinking transformer. In Findings of the Association for Computational Linguistics: ACL-IJCNLP 2021, pages 2461–2474, Online. Association for Computational Linguistics.
  37. 37.Biao Zhang, Ivan Titov, Barry Haddow, and Rico Sennrich. 2020. Adaptive feature selection for end-to-end speech translation. In Findings of the Association for Computational Linguistics: EMNLP 2020, pages 2533–2544, Online. Association for Computational Linguistics.
  38. 38.Shaolei Zhang and Yang Feng. 2021a. ICT’s system for AutoSimTrans 2021: Robust char-level simultaneous translation. In Proceedings of the Second Workshop on Automatic Simultaneous Translation, pages 1–11, Online. Association for Computational Linguistics.
  39. 39.Shaolei Zhang and Yang Feng. 2021b. Modeling concentrated cross-attention for neural machine translation with Gaussian mixture model. In Findings of the Association for Computational Linguistics: EMNLP 2021, pages 1401–1411, Punta Cana, Dominican Republic. Association for Computational Linguistics.
  40. 40.Shaolei Zhang and Yang Feng. 2021c. Universal simultaneous machine translation with mixture-of-experts wait-k policy. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing, pages 7306–7317, Online and Punta Cana, Dominican Republic. Association for Computational Linguistics.
  41. 41.Shaolei Zhang and Yang Feng. 2022a. Gaussian multi-head attention for simultaneous machine translation. In Findings of the Association for Computational Linguistics: ACL 2022, pages 3019–3030, Dublin, Ireland. Association for Computational Linguistics.
  42. 42.Shaolei Zhang and Yang Feng. 2022b. Modeling dual read/write paths for simultaneous machine translation. In Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 2461–2477, Dublin, Ireland. Association for Computational Linguistics.
  43. 43.Shaolei Zhang and Yang Feng. 2022c. Reducing position bias in simultaneous machine translation with length-aware framework. In Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 6775–6788, Dublin, Ireland. Association for Computational Linguistics.
  44. 44.Shaolei Zhang, Yang Feng, and Liangyou Li. 2021. Future-guided incremental transformer for simultaneous translation. Proceedings of the AAAI Conference on Artificial Intelligence, 35(16):14428–14436.
  45. 45.Shaolei Zhang, Shoutao Guo, and Yang Feng. 2022. Wait-info policy: Balancing source and target at information level for simultaneous machine translation. In Findings of the Association for Computational Linguistics: EMNLP 2022, Online and Abu Dhabi. Association for Computational Linguistics.
  46. 46.Baigong Zheng, Kaibo Liu, Renjie Zheng, Mingbo Ma, Hairong Liu, and Liang Huang. 2020. Simultaneous translation policies: From fixed to adaptive. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 2847–2853, Online. Association for Computational Linguistics.
  47. 47.Baigong Zheng, Renjie Zheng, Mingbo Ma, and Liang Huang. 2019a. Simpler and faster learning of adaptive policies for simultaneous translation. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP), pages 1349–1354, Hong Kong, China. Association for Computational Linguistics.
  48. 48.Baigong Zheng, Renjie Zheng, Mingbo Ma, and Liang Huang. 2019b. Simultaneous translation with flexible policy via restricted imitation learning. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, pages 5816–5822, Florence, Italy. Association for Computational Linguistics.

Citation

MLA
Zhang, S., and Y. Feng. “Information-Transport-based Policy for Simultaneous Translation”. Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing, 2022, pp. 992–1013, https://doi.org/10.18653/v1/2022.emnlp-main.65.
APA
Zhang, S., & Feng, Y. (2022). Information-Transport-based Policy for Simultaneous Translation. Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing, 992–1013. https://doi.org/10.18653/v1/2022.emnlp-main.65
Chicago
Zhang, S., and Y. Feng. 2022. “Information-Transport-based Policy for Simultaneous Translation”. Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing, 992–1013. https://doi.org/10.18653/v1/2022.emnlp-main.65.
Harvard
Zhang, S. and Feng, Y. (2022) “Information-Transport-based Policy for Simultaneous Translation”, Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing. Association for Computational Linguistics, pp. 992–1013. Available at: https://doi.org/10.18653/v1/2022.emnlp-main.65.
Vancouver
1. Zhang S, Feng Y (2022) Information-Transport-based Policy for Simultaneous Translation. In: Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing. Association for Computational Linguistics, pp 992–1013

BibTeX

@inproceedings{zhang-feng-2022-information,
    title = "Information-Transport-based Policy for Simultaneous Translation",
    author = "Zhang, Shaolei  and
      Feng, Yang",
    editor = "Goldberg, Yoav  and
      Kozareva, Zornitsa  and
      Zhang, Yue",
    booktitle = "Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing",
    month = dec,
    year = "2022",
    address = "Abu Dhabi, United Arab Emirates",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2022.emnlp-main.65/",
    doi = "10.18653/v1/2022.emnlp-main.65",
    pages = "992--1013"
}
Metadata:ACL Anthology

Source Code

This paper has an official code repository available. Click below to access the source code.

View Repository

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: https://creativecommons.org/licenses/by/4.0/