Transfer Feature Learning with Joint Distribution Adaptation
Mingsheng LongJianmin WangGuiguang DingJiaguang SunPhilip S. Yu
Proposes Joint Distribution Adaptation, a principled dimensionality reduction framework that iteratively aligns both marginal and class-conditional distributions using pseudo labels to boost cross-domain image classification accuracy without requiring target labels.
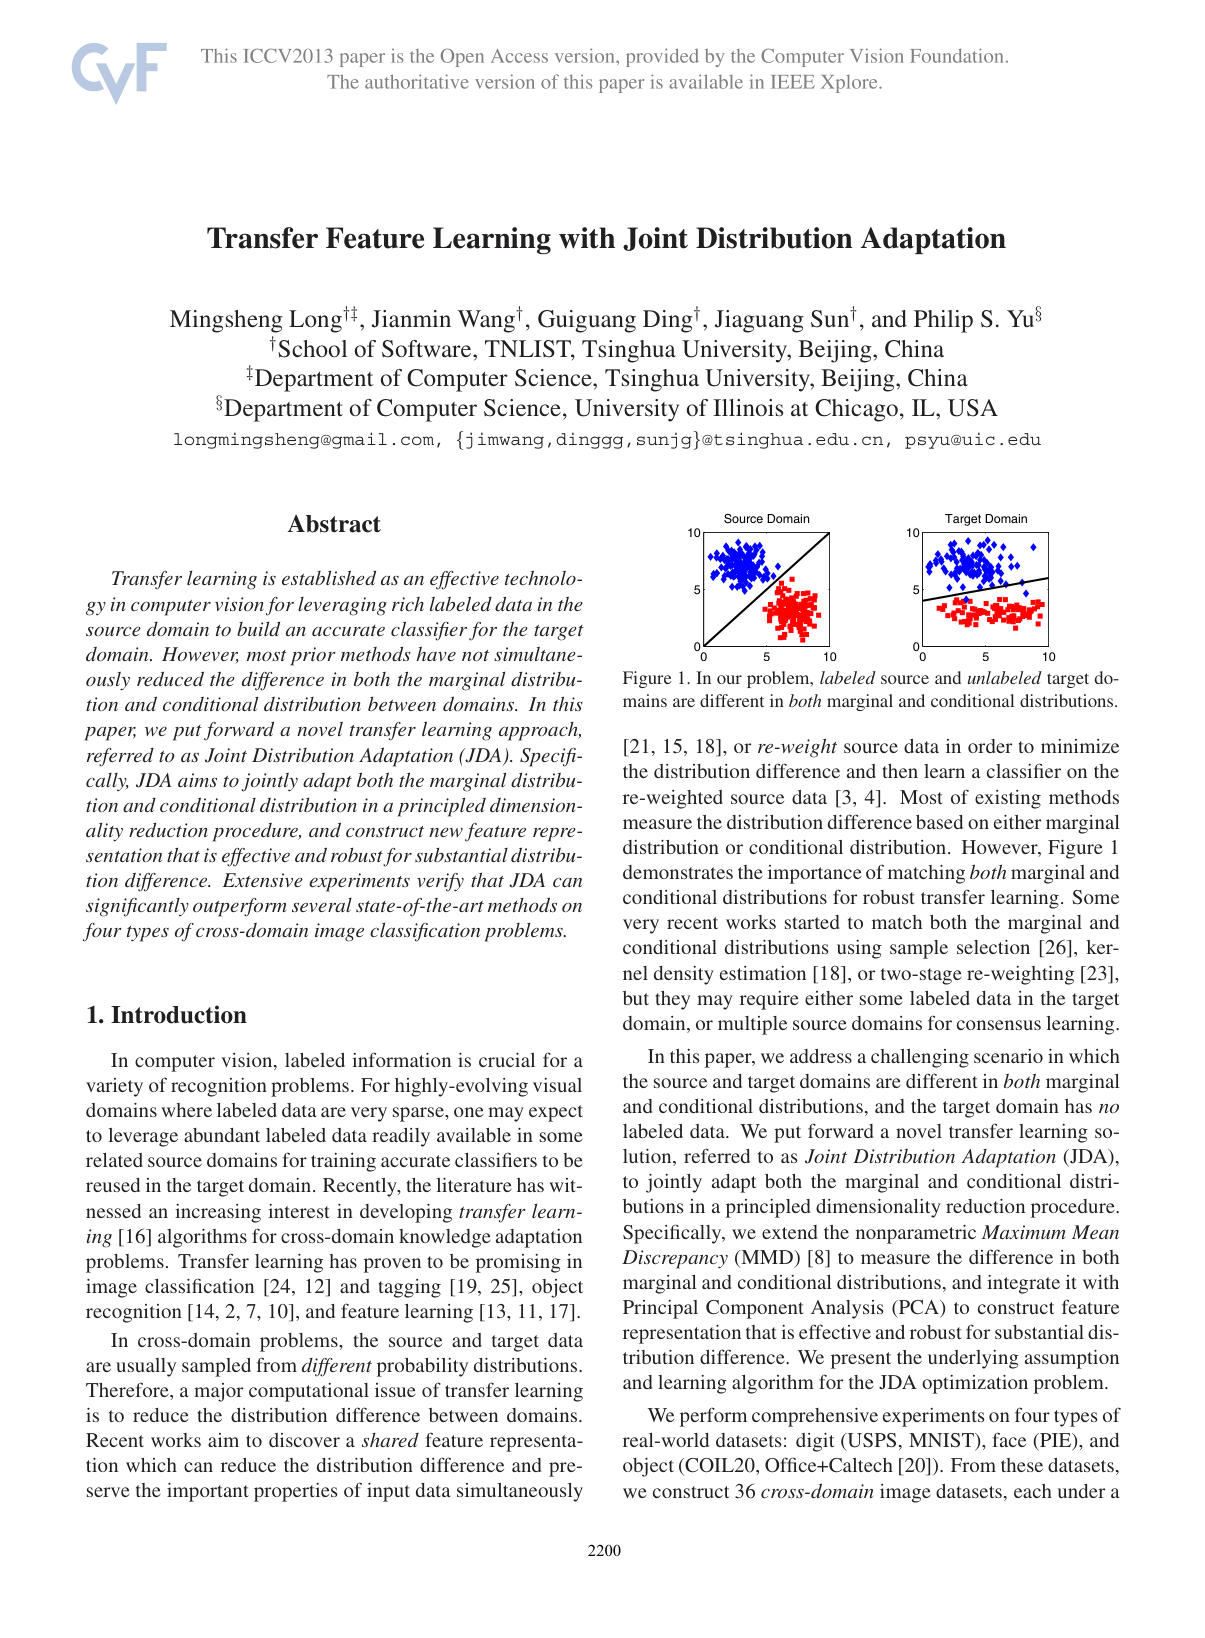
In real-world computer vision applications, acquiring large amounts of accurately labeled data for every new environment or camera setup is expensive and time-consuming. While transfer learning allows organizations to train models using abundant labeled data from an existing source domain and apply them to an unlabeled target domain, standard techniques often fail when the two environments differ significantly in both overall data patterns (marginal distributions) and class-specific relationships (conditional distributions).
The article introduces and evaluates Joint Distribution Adaptation (JDA), a transfer learning approach designed to adapt both marginal and conditional distributions simultaneously without requiring any labeled samples in the target environment.
To achieve this, the method combines standard data dimensionality reduction with a statistical distance metric that measures domain differences across feature distributions and predicted class-level distributions. Because target domain labels are unavailable, the approach generates initial pseudo labels using a base classifier and iteratively refines these labels and the shared feature representation until the system stabilizes. The authors evaluated this technique across 36 cross-domain image classification tasks covering digits, faces across multiple camera poses, and diverse object recognition datasets, comparing it against standard non-transfer baselines and four state-of-the-art domain adaptation algorithms.
The key findings demonstrate that Joint Distribution Adaptation delivers substantial performance gains. First, it achieved an average classification accuracy of 57.37% across all 36 evaluation sets, outperforming the strongest transfer baseline by 7.57% in absolute accuracy—amounting to a 15.07% relative reduction in classification error. Second, it markedly outperformed standard non-transfer classification, which averaged only 37.46% accuracy and suffered major failures in difficult visual tasks. Third, the iterative pseudo label refinement process converged reliably within just 10 iterations across test conditions. Fourth, the approach demonstrated high operational stability over a broad range of core parameter settings, avoiding brittleness.
These results show that explicitly aligning both marginal and conditional distributions is critical for robust domain adaptation. By relying on sufficient distribution statistics rather than exact density estimations, the approach successfully tolerates noisy initial pseudo labels and extracts features that enhance between-domain similarity while preserving category distinctions. Operationally, this capability allows organizations to reuse existing image libraries across different operational environments without the cost, timeline delays, or manual effort associated with annotating new target datasets.
Organizations developing computer vision systems across varying operational settings should consider adopting joint distribution matching pipelines to minimize manual data annotation costs. Computational trade-offs should be weighed during deployment: while this method requires slightly more computation than single-distribution baselines, it processes data orders of magnitude faster than complex density-estimation methods. As a future step, the underlying alignment framework can be explored in conjunction with other advanced representation learning models, such as sparse coding.
Confidence in these findings is supported by consistent outperformance across 36 diverse cross-domain image datasets. However, practitioners should recognize the boundary conditions: the approach assumes that the source and target domains share identical feature sets and class categories. Additionally, because the method relies on a closed-form dimensionality reduction step, performance in production environments will depend on the representativeness of the unlabeled target samples provided during training.
- Paper: A theory of learning from different domains, Shai Ben-David et al. (2010). This paper establishes the foundational generalization bounds and distribution discrepancy metrics that motivate adapting both marginal and conditional feature distributions.
- Paper: Correcting Sample Selection Bias by Unlabeled Data, Jiayuan Huang et al. (2006). It introduces non-parametric distribution matching via Maximum Mean Discrepancy in reproducing kernel Hilbert spaces, which serves as the mathematical core for JDA's alignment objective.
- Paper: A Survey on Transfer Learning, Sinno Jialin Pan et al. (2010). This comprehensive survey outlines the core taxonomy and formal definitions of transfer learning that frame JDA's dimensionality reduction approach.
- Paper: Adapting Visual Category Models to New Domains, Kate Saenko et al. (2010). It introduces the standard cross-domain visual benchmark (Office) and metric-learning paradigms on which JDA evaluates domain transfer performance.
- Paper: Analysis of Representations for Domain Adaptation, Shai Ben-David et al. (2006). It provides theoretical analysis demonstrating that effective domain adaptation requires learning representations that minimize cross-domain distribution divergence.
- Paper: Deep Transfer Learning with Joint Adaptation Networks, Mingsheng Long et al. (2016). This work directly extends JDA's joint marginal and conditional distribution adaptation principle into deep neural network architectures via Joint Adaptation Networks.
- Paper: Learning Transferable Features with Deep Adaptation Networks, Mingsheng Long et al. (2015). It takes feature distribution alignment via multi-kernel MMD from shallow dimensionality reduction into end-to-end task-specific layers of deep convolutional networks.
- Paper: Conditional Adversarial Domain Adaptation, Mingsheng Long et al. (2017). It advances conditional distribution alignment by conditioning deep adversarial domain discriminators on classifier prediction tensors.
- Paper: Deep Domain Confusion: Maximizing for Domain Invariance, Eric Tzeng et al. (2014). It integrates an explicit MMD domain-confusion loss directly into CNN representations to enforce domain-invariant feature spaces.
- Paper: Return of Frustratingly Easy Domain Adaptation, Baochen Sun et al. (2015). It provides a simplified second-order statistical feature alignment alternative (CORAL) to non-parametric MMD-based dimensionality reduction methods like JDA.
- Paper: A Comprehensive Survey on Transfer Learning, Fuzhen Zhuang et al. (2019). This survey evaluates JDA alongside modern deep and adversarial domain adaptation paradigms across homogeneous and heterogeneous tasks.
- Paper: Deep Visual Domain Adaptation: A Survey, Mei Wang et al. (2018). This survey contextualizes statistical discrepancy-based alignment methods like JDA within the broader evolution toward deep visual domain adaptation.