MDAN: Multi-level Dependent Attention Network for Visual Emotion Analysis

Liwen XuZhengtao WangBin WuSimon Lui

article2022CVPR61 citations

Proposes a dual-branch multi-level dependent attention network that bridges the visual affective gap by aligning hierarchical emotion categories with corresponding feature semantic levels to achieve state-of-the-art visual emotion recognition.

Abstract

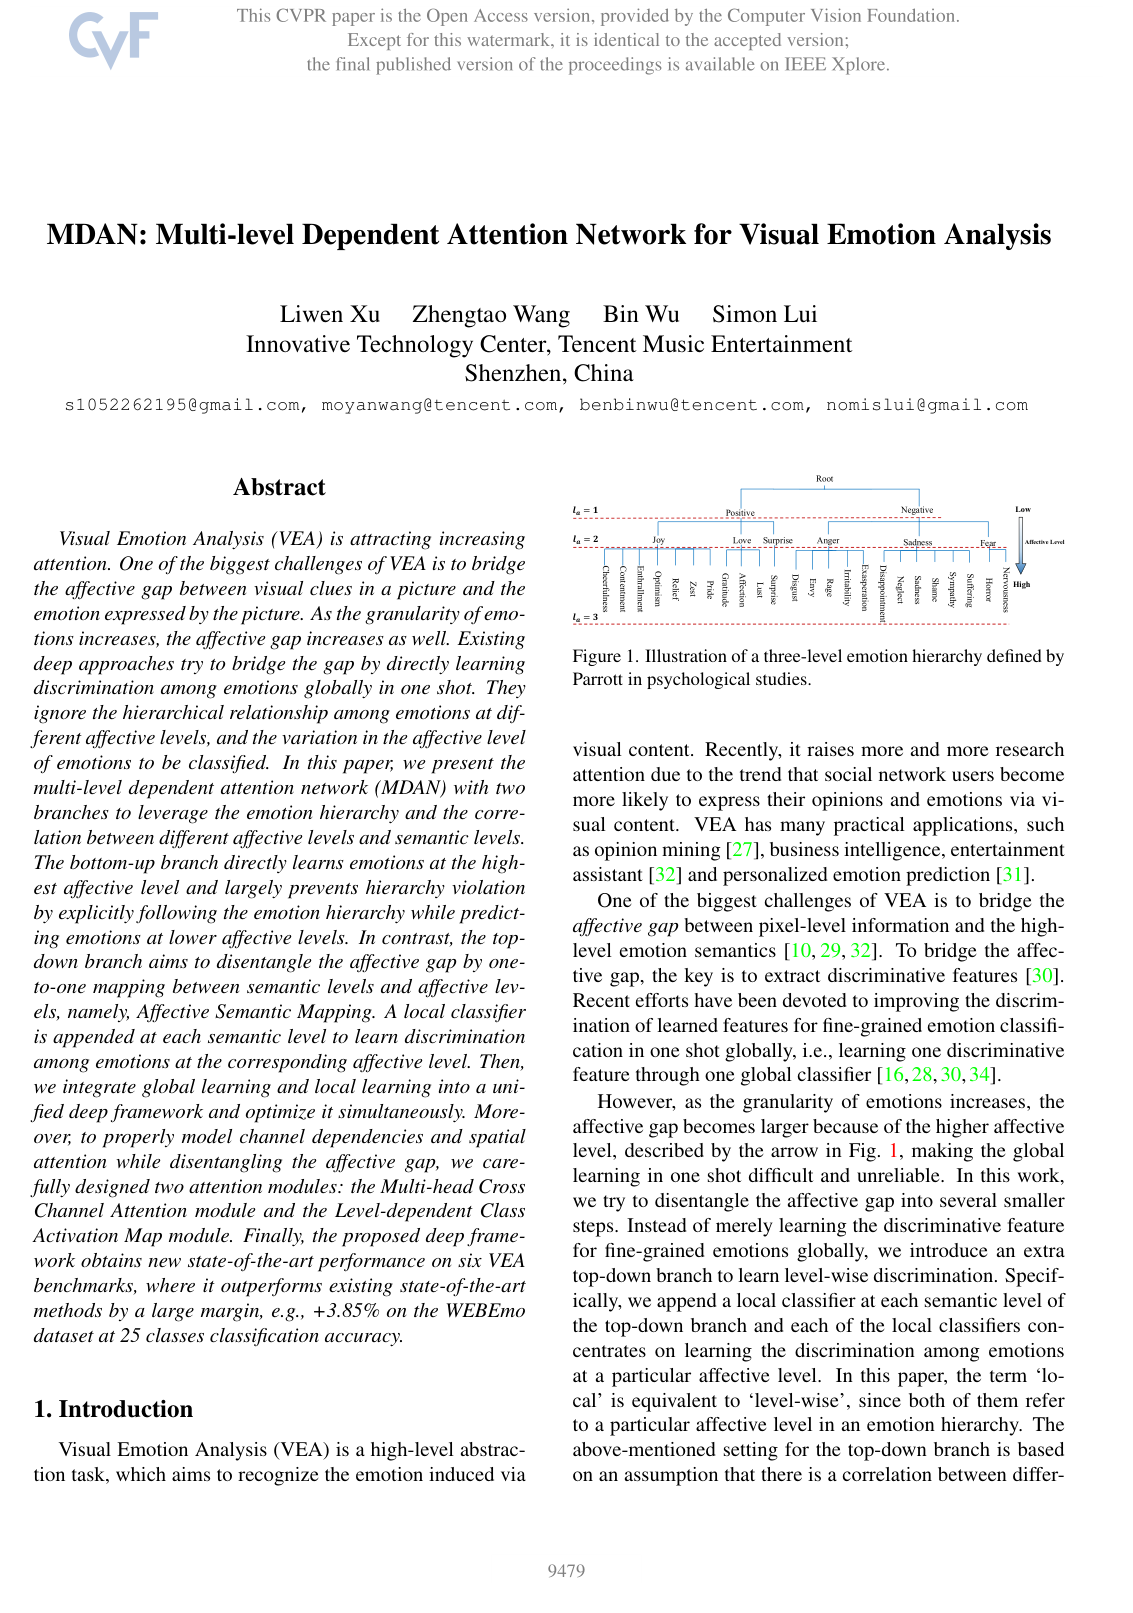
Visual Emotion Analysis (VEA) is attracting increasing attention. One of the biggest challenges of VEA is to bridge the affective gap between visual clues in a picture and the emotion expressed by the picture. As the granularity of emotions increases, the affective gap increases as well. Existing deep approaches try to bridge the gap by directly learning discrimination among emotions globally in one shot. They ignore the hierarchical relationship among emotions at different affective levels, and the variation in the affective level of emotions to be classified. In this paper, we present the multi-level dependent attention network (MDAN) with two branches to leverage the emotion hierarchy and the correlation between different affective levels and semantic levels. The bottom-up branch directly learns emotions at the highest affective level and largely prevents hierarchy violation by explicitly following the emotion hierarchy while predicting emotions at lower affective levels. In contrast, the top-down branch aims to disentangle the affective gap by one-to-one mapping between semantic levels and affective levels, namely, Affective Semantic Mapping. A local classifier is appended at each semantic level to learn discrimination among emotions at the corresponding affective level. Then, we integrate global learning and local learning into a unified deep framework and optimize it simultaneously. Moreover, to properly model channel dependencies and spatial attention while disentangling the affective gap, we carefully designed two attention modules: the Multi-head Cross Channel Attention module and the Level-dependent Class Activation Map module. Finally, the proposed deep framework obtains new state-of-the-art performance on six VEA benchmarks, where it outperforms existing state-of-the-art methods by a large margin, e.g., +3.85% on the WEBEmo dataset at 25 classes classification accuracy.

Table of Contents

  • 1. Introduction
  • 2. Related Work
  • 2.1. Emotion Models from Psychology
  • 2.2. Visual Emotion Analysis
  • 2.3. Attention Mechanism
  • 3. Affective Gap Disentanglement
  • 3.1. Affective Semantic Mapping
  • 3.2. Global and Local Learning
  • 4. Attention Mechanism
  • 4.1. Multi-head Cross Channel Attention
  • 4.2. Level-dependent Class Activation Map
  • 4.2.1 Class Activation Map
  • 4.2.2 L-CAM
  • 5. Experiment
  • 5.1. Dataset
  • 5.2. Implementation Details
  • 5.3. Affective Semantic Mapping
  • 5.4. Classification Performance
  • 5.5. Hyper-parameter Analysis
  • 5.5.1 Number of attention heads
  • 5.5.2 Alpha
  • 5.6. Ablation Study
  • 5.7. Visualization
  • 6. Conclusion
  • References

Knowls

  1. Knowl 1 — MDAN Architecture for Hierarchical Visual Emotion Analysis

    model/method

    The Multi-level Dependent Attention Network (MDAN) is a deep framework designed to bridge the affective gap in visual emotion analysis by leveraging hierarchical emotion categories and multi-scale semantic representations via a Feature Pyramid Network (FPN) backbone.

    MDAN consists of two cooperative branches:

    1. Bottom-Up Global Branch: Takes an input image and extracts multi-scale convolutional feature maps denoted as {C2,C3,C4,C5}\{C_2, C_3, C_4, C_5\} from the four bottleneck blocks of a ResNet backbone, where C5C_5 has the highest semantic level and C2C_2 has the lowest. A global classifier is attached to C5C_5 to predict fine-grained emotions at the highest affective level ∣la∣|l_a|. Global probabilities for coarser parent categories at lower affective levels la−1l_a - 1 are obtained by summing the probabilities of their constituent children categories, enforcing hierarchy consistency.
    2. Top-Down Local Branch: Deconstructs the affective gap into level-wise classification steps. It establishes an Affective Semantic Mapping where each semantic level lsl_s is assigned to a specific affective level lal_a via ls=5−lal_s = 5 - l_a (for la∈{1,2,3}l_a \in \{1, 2, 3\}). At each stage, top-down features are enriched with lateral connections via two specialized attention modules—Multi-head Cross Channel Attention (MHCCA) and Level-dependent Class Activation Map (L-CAM)—before being fed into a level-specific local classifier.

    The global and local predictions across all affective levels are combined and jointly optimized.

  2. Knowl 2 — Affective Semantic Mapping in Feature Pyramid Networks

    model/method

    Affective Semantic Mapping defines the correspondence between the semantic levels lsl_s of feature maps in a Feature Pyramid Network (FPN) and the affective levels lal_a of an emotion taxonomy (e.g., la=1l_a = 1 for binary valence, la=2l_a = 2 for primary emotions, and la=3l_a = 3 for fine-grained tertiary emotions).

    In the MDAN top-down branch, the mapping is formally defined as: ls=5−lafor la∈{1,2,3}l_s = 5 - l_a \quad \text{for } l_a \in \{1, 2, 3\} where ls∈{4,3,2}l_s \in \{4, 3, 2\} corresponds to the lateral feature stages of the backbone.

    While traditional psychological and pre-deep visual analyses suggested that coarse emotions correlate with low-level visual features and fine emotions correlate with high-level semantics, the integration of top-down feature fusion in FPN inverts this relationship. Top-down feature maps at lower semantic stages (F2,F3F_2, F_3) combine high-level semantic context with high spatial resolution, making them more discriminative for fine-grained emotion recognition at higher affective levels (la=3,la=2l_a = 3, l_a = 2), while higher semantic levels with coarse spatial resolution (F4F_4) suffice for coarse affective classifications (la=1l_a = 1).

  3. Knowl 3 — Multi-head Cross Channel Attention Module

    model/method

    The Multi-head Cross Channel Attention (MHCCA) module models pairwise channel attribute dependencies between feature maps at adjacent semantic levels in the top-down branch, emphasizing discriminative channels while suppressing redundancy.

    Given the top-down feature map FlsF_{l_s} at semantic level lsl_s and the lateral backbone feature map Cls−1C_{l_s-1} at level ls−1l_s-1, Cross-Attention (CA) computes a refined feature map Cls−1′C'_{l_s-1} as: Cls−1′=O1×1(softmax(Q1×1(Fls)Cls−1TdCls−1)Cls−1)C'_{l_s-1} = O_{1\times 1} \left( \text{softmax}\left( \frac{Q_{1\times 1}(F_{l_s}) C_{l_s-1}^T}{\sqrt{d_{C_{l_s-1}}}} \right) C_{l_s-1} \right) where Q1×1Q_{1\times 1} and O1×1O_{1\times 1} are 1×11\times 1 pointwise convolutional layers, and dCls−1d_{C_{l_s-1}} denotes the flattened spatial dimension per attention head in Cls−1C_{l_s-1}. Unlike standard multi-head self-attention with four projections, MHCCA retains only query (Q1×1Q_{1\times 1}) and output (O1×1O_{1\times 1}) projections to prevent overfitting in emotion classification.

    To balance spatial receptive field size and channel modeling across scales, the number of attention heads hlsh_{l_s} varies across semantic levels: h4=2h_4 = 2, h3=4h_3 = 4, and h2=8h_2 = 8 for ls∈{4,3,2}l_s \in \{4, 3, 2\}.

  4. Knowl 4 — Level-dependent Class Activation Map Module

    model/method

    The Level-dependent Class Activation Map (L-CAM) module generates spatial attention maps that leverage the hierarchical class subordination between adjacent affective levels (la−1l_a - 1 and lal_a) to guide spatial feature selection.

    For a local classifier at affective level lal_a with weight vector wlakw_{l_a}^k for class kk, the class activation map Mlak(x,y)M_{l_a}^k(x, y) is computed over the feature map F5−laF_{5-l_a} as: Mlak(x,y)=∑cwlak,cF5−lac(x,y)M_{l_a}^k(x, y) = \sum_c w_{l_a}^{k, c} F_{5-l_a}^c(x, y) where F5−lac(x,y)F_{5-l_a}^c(x, y) is the cc-th channel attribute of F5−laF_{5-l_a} at spatial location (x,y)(x, y).

    Given the predicted parent category jj at the preceding affective level la−1l_a - 1 (j=arg⁡max⁡PLla−1j = \arg\max P_L^{l_a-1}), L-CAM computes an aggregate spatial attention map Mla(x,y)M_{l_a}(x, y) over all children categories k∈jk \in j by combining average pooling and max pooling: Mla(x,y)=1∣k∣∑k∈jMlak(x,y)+max⁡k∈jMlak(x,y)M_{l_a}(x, y) = \frac{1}{|k|} \sum_{k \in j} M_{l_a}^k(x, y) + \max_{k \in j} M_{l_a}^k(x, y)

    The modulated feature map FlsF_{l_s} is then obtained via residual scaling: Fls=(1+Mla)⊙(Cls−1′⊕Fls)F_{l_s} = (1 + M_{l_a}) \odot (C'_{l_s-1} \oplus F_{l_s}) where ⊙\odot represents element-wise multiplication broadcast across channels, and ⊕\oplus denotes element-wise feature addition.
  5. Knowl 5 — Simultaneous Global and Local Learning Objective

    equation

    In MDAN, predictions from the global classifier (PGlaP_G^{l_a}) and the local classifiers (PLlaP_L^{l_a}) are combined into an overall prediction POlaP_O^{l_a} at each affective level lal_a: POla=αPLla+(1−α)PGlaP_O^{l_a} = \alpha P_L^{l_a} + (1 - \alpha) P_G^{l_a} where α∈[0,1]\alpha \in [0, 1] is a trade-off hyperparameter (empirically optimal near α=0.6\alpha = 0.6 or 0.70.7).

    For the highest affective level ∣la∣|l_a|, the global prediction is directly generated from the global classifier: PG∣la∣=softmax(gclassifier(GAP(C5)))P_G^{|l_a|} = \text{softmax}(\text{gclassifier}(\text{GAP}(C_5))). For lower affective levels la−1l_a - 1, the global prediction for parent category jj is computed by marginalizing over its children categories kk: PG,jla−1=∑k∈jPG,klaP_{G, j}^{l_a-1} = \sum_{k \in j} P_{G, k}^{l_a}

    The entire network is optimized end-to-end by minimizing the multi-task cross-entropy loss over all affective levels: L=1∣la∣∑i=1∣la∣Li=−1∣la∣1N∑i=1∣la∣∑j=1N∑k=1∣Ci∣Yj,kilog⁡(PO,j,ki)L = \frac{1}{|l_a|} \sum_{i=1}^{|l_a|} L_i = - \frac{1}{|l_a|} \frac{1}{N} \sum_{i=1}^{|l_a|} \sum_{j=1}^N \sum_{k=1}^{|C_i|} Y_{j, k}^i \log\left(P_{O, j, k}^i\right) where NN is the batch size, ∣Ci∣|C_i| is the number of emotion classes at level la=il_a = i, and Yj,ki∈{0,1}Y_{j, k}^i \in \{0, 1\} is the one-hot ground-truth label for sample jj at class kk of affective level ii.

  6. Knowl 6 — Classification Performance on Visual Emotion Benchmarks

    data/table

    The MDAN framework was evaluated across six visual emotion analysis (VEA) benchmarks against conventional CNN architectures, multi-level architectures, and attention-based methods. Below are the model parameters, GFLOPs, and classification accuracies (%) across emotion granularities (la∈{1,2,3}l_a \in \{1, 2, 3\} corresponding to 2, 6, 8, or 25 classes).

    Model #params GFLOPs Emotion FI WEBEmo Artphoto Abstract
    Number of classes 2 6 2 8 2 6 25 2 8 8
    AlexNet 61.10M 2.8 75.88 51.35 72.43 58.30 - 48.66 28.21 69.27 67.03 61.96
    VGGNet-16 138M 62.0 - - 83.05 - - - - 70.09 68.16 62.41
    ResNet-50 23.52M 15.6 79.23 54.99 85.43 64.74 76.65 51.97 31.80 70.93 - -
    ResNet-101 42.52M 30.4 79.78 56.69 85.92 66.16 78.17 52.35 32.14 71.08 69.36 63.56
    WSCNet 42.60M 62.7 82.15 58.47 86.74 70.07 79.43 52.61 32.75 80.38 72.86 64.45
    PDANet 63.51M 67.6 82.27 59.24 87.25 72.13 80.96 53.46 32.82 80.27 74.62 67.13
    Zhang et al. 50.29M 128.3 82.95 60.41 90.97 75.91 82.47 53.88 33.01 79.24 - -
    MDAN (Ours) 48.79M 101.4 84.62 61.66 91.08 76.41 82.72 55.65 34.28 91.50 78.12 72.34

    MDAN outperforms previous state-of-the-art methods across all datasets and affective levels, achieving a +3.85% improvement over ResNet-101 on WEBEmo-25 and notable gains on small-scale datasets such as ArtPhoto (+3.50% at 8 classes over PDANet).

  7. Knowl 7 — Empirical Comparison of Affective-to-Semantic Mapping Strategies

    data/table

    Classification accuracy (%) was evaluated under different semantic-to-affective mapping configurations on WEBEmo, FI, and Emotion-6 using local prediction (PLP_L) alone to assess the validity of Affective Semantic Mapping.

    Mapping Setting WEBEmo FI Emotion
    Number of Classes 2 6 25 2 8 2 6
    Baseline (ResNet-101) 78.17 52.35 32.14 85.92 66.16 79.78 56.69
    Without Feature Fusion (w/o FF)
    (a) Low la→l_a \to Low lsl_s, High la→l_a \to High lsl_s 78.01 47.64 25.69 87.30 67.52 80.31 57.00
    (b) Low la→l_a \to High lsl_s, High la→l_a \to Low lsl_s 77.94 46.91 23.17 84.79 64.80 77.48 54.41
    (c) Sequential low-to-high lal_a mapping 78.71 51.35 31.23 88.27 69.84 81.53 58.64
    (d) Sequential high-to-low lal_a mapping 78.13 49.12 30.81 85.03 67.29 77.51 56.95
    With Feature Fusion (with FF)
    (e) Top-down: ls=5−lal_s = 5 - l_a 79.79 52.11 31.85 90.36 70.55 81.94 59.62
    (f) Top-down: inverted ls=2+lal_s = 2 + l_a 79.72 51.74 31.68 89.51 70.46 81.63 59.00

    The comparison shows that feature fusion significantly boosts accuracy across all datasets. Under feature fusion, setting (e) outperforms (f), confirming that semantically enriched and spatially detailed lower-stage features (ls=5−lal_s = 5 - l_a) best serve fine-grained emotion recognition (la=3l_a = 3).

  8. Knowl 8 — Ablation Study of Network Components on WEBEmo-25

    data/table

    An ablation study on the 25-class WEBEmo dataset isolates the contribution of each component in MDAN starting from the FPN baseline (Base) with simultaneous global and local optimization (fixed at α=0.7\alpha = 0.7).

    Base MHCCA K1×1K_{1\times 1} V1×1V_{1\times 1} UpsampleAdd Mean Max WEBEmo-25 (%)
    ✓ 32.78
    ✓ ✓ ✓ 32.74
    ✓ ✓ 33.13
    ✓ ✓ ✓ 33.75
    ✓ ✓ ✓ ✓ 34.04
    ✓ ✓ ✓ ✓ 34.17
    ✓ ✓ ✓ ✓ ✓ 34.28

    Key takeaways:

    1. Omitting K1×1K_{1\times 1} and V1×1V_{1\times 1} projections in MHCCA prevents overfitting, improving accuracy from 32.74% to 33.13%.
    2. Incorporating top-down feature fusion (UpsampleAdd) yields a 0.62% increase.
    3. Combining both Mean and Max spatial pooling within L-CAM yields the peak performance of 34.28%.
  9. Knowl 9 — Influence of Multi-Head Partitioning and Global-Local Fusion Weight

    empirical result

    The performance of MDAN is modulated by the number of attention heads hlsh_{l_s} in MHCCA and the prediction fusion weight α\alpha:

    1. Head Number hlsh_{l_s} and Spatial Subspace Dimension dlsd_{l_s}: Dividing feature channels across spatial subspaces improves performance compared to a single head (h=1h = 1), but excessive heads (h=16h = 16) degrade accuracy due to over-fragmentation. Higher semantic feature maps (ls=4l_s = 4) have larger receptive fields and require fewer heads (h4=2,d4=392h_4 = 2, d_4 = 392), whereas lower semantic feature maps (ls=2l_s = 2) benefit from more heads (h2=8,d2=392h_2 = 8, d_2 = 392). On FI-8, setting (h4,h3)=(2,4)(h_4, h_3) = (2, 4) achieves 76.28% accuracy compared to 74.78% with (1,1)(1, 1).
    2. Fusion Weight α\alpha: Evaluating α∈[0,1]\alpha \in [0, 1] in POla=αPLla+(1−α)PGlaP_O^{l_a} = \alpha P_L^{l_a} + (1 - \alpha) P_G^{l_a} on the Emotion-6 dataset reveals that accuracy increases steadily from α=0.0\alpha = 0.0 to α=0.7\alpha = 0.7 for both binary (la=1l_a = 1) and 6-class (la=2l_a = 2) classification, confirming the strong complementarity of local level-wise discrimination and global hierarchy-consistent learning. Accuracy drops sharply for α>0.7\alpha > 0.7 due to local classifier overfitting and unconstrained hierarchy violations.

Coverage note — None was omitted; all key architectural components, mathematical equations, mapping strategies, experimental datasets, ablation findings, and hyperparameter analyses contributed in the paper are represented.

References

  1. 1.Damian Borth, Tao Chen, R. Ji, and Shih-Fu Chang. Sentibank: large-scale ontology and classifiers for detecting sentiment and emotions in visual content. In MM '13, 2013. 6, 7
  2. 2.Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, and Sergey Zagoruyko. End-to-end object detection with transformers. ArXiv, abs/2005.12872, 2020. 2, 3
  3. 3.Tao Chen, Damian Borth, Trevor Darrell, and Shih-Fu Chang. Deepsentibank: Visual sentiment concept classification with deep convolutional neural networks. ArXiv, abs/1410.8586, 2014. 6, 7
  4. 4.A. Dosovitskiy, L. Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, M. Dehghani, Matthias Minderer, G. Heigold, S. Gelly, Jakob Uszkoreit, and N. Houlsby. An image is worth 16x16 words: Transformers for image recognition at scale. ArXiv, abs/2010.11929, 2021. 2, 3
  5. 5.Paul Ekman. An argument for basic emotions. Cognition and Emotion, 6(3-4):169–200, 1992. 2, 5
  6. 6.Kaiming He, X. Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), pages 770–778, 2016. 6, 7
  7. 7.A. Krizhevsky, Ilya Sutskever, and Geoffrey E. Hinton. Imagenet classification with deep convolutional neural networks. Communications of the ACM, 60:84 – 90, 2012. 6, 7
  8. 8.Tsung-Yi Lin, Piotr Dollar, Ross B. Girshick, Kaiming He, Bharath Hariharan, and Serge J. Belongie. Feature pyramid networks for object detection. 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), pages 936–944, 2017. 2, 3, 4
  9. 9.Xin Lu, Poonam Suryanarayan, Reginald B Adams Jr, Jia Li, Michelle G Newman, and James Z Wang. On shape and the computability of emotions. In Proceedings of the 20th ACM international conference on Multimedia, pages 229–238, 2012. 2, 3, 6
  10. 10.J. Machajdik and A. Hanbury. Affective image classification using features inspired by psychology and art theory. Proceedings of the 18th ACM international conference on Multimedia, 2010. 1, 5
  11. 11.Joseph A. Mikels, B. Fredrickson, G. R. Larkin, Casey M. Lindberg, Sam J. Maglio, and P. Reuter-Lorenz. Emotional category data on images from the international affective picture system. Behavior Research Methods, 37:626–630, 2005. 2, 5
  12. 12.R. Panda, Jianming Zhang, Haoxiang Li, Joon-Young Lee, X. Lu, and A. Roy-Chowdhury. Contemplating visual emotions: Understanding and overcoming dataset bias. In ECCV, 2018. 4, 5, 6
  13. 13.W Gerrod Parrott. Emotions in social psychology: Essential readings. psychology press, 2001. 2, 5
  14. 14.Tianrong Rao, Xiaoxu Li, Haimin Zhang, and Min Xu. Multi-level region-based convolutional neural network for image emotion classification. Neurocomputing, 333:429–439, 2019. 6, 7
  15. 15.Andreza Sartori, Dubravko Culibrk, Yan Yan, and N. Sebe. Who's afraid of itten: Using the art theory of color combination to analyze emotions in abstract paintings. Proceedings of the 23rd ACM international conference on Multimedia, 2015. 2, 3, 6
  16. 16.Dongyu She, Jufeng Yang, Ming-Ming Cheng, Yu-Kun Lai, Paul L. Rosin, and Liang Wang. Wscnet: Weakly supervised coupled networks for visual sentiment classification and detection. IEEE Transactions on Multimedia, 22:1358–1371, 2020. 1, 2, 3, 5, 6, 7
  17. 17.K. Simonyan and Andrew Zisserman. Very deep convolutional networks for large-scale image recognition. CoRR, abs/1409.1556, 2015. 6, 7
  18. 18.A. Srinivas, Tsung-Yi Lin, Niki Parmar, Jonathon Shlens, P. Abbeel, and Ashish Vaswani. Bottleneck transformers for visual recognition. ArXiv, abs/2101.11605, 2021. 2, 3
  19. 19.Robin A. M. Strudel, Ricardo Garcia Pinel, Ivan Laptev, and Cordelia Schmid. Segmenter: Transformer for semantic segmentation. ArXiv, abs/2105.05633, 2021. 2, 3
  20. 20.Ming Sun, Jufeng Yang, Kai Wang, and Hui Shen. Discovering affective regions in deep convolutional neural networks for visual sentiment prediction. 2016 IEEE International Conference on Multimedia and Expo (ICME), pages 1–6, 2016. 3
  21. 21.Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Ł ukasz Kaiser, and Illia Polosukhin. Attention is all you need. In I. Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Garnett, editors, Advances in Neural Information Processing Systems, volume 30. Curran Associates, Inc., 2017. 2, 3, 8
  22. 22.X. Wang, Ross B. Girshick, A. Gupta, and Kaiming He. Non-local neural networks. 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 7794–7803, 2018. 2, 3, 8
  23. 23.Jufeng Yang, Dongyu She, Ming Sun, Ming-Ming Cheng, Paul L. Rosin, and Liang Wang. Visual sentiment prediction based on automatic discovery of affective regions. IEEE Transactions on Multimedia, 20(9):2513–2525, 2018. 3, 6
  24. 24.Quanzeng You, Hailin Jin, and Jiebo Luo. Visual sentiment analysis by attending on local image regions. In AAAI, 2017. 3
  25. 25.Quanzeng You, Jiebo Luo, Hailin Jin, and Jianchao Yang. Robust image sentiment analysis using progressively trained and domain transferred deep networks. In AAAI, 2015. 6, 7
  26. 26.Quanzeng You, Jiebo Luo, Hailin Jin, and Jianchao Yang. Building a large scale dataset for image emotion recognition: The fine print and the benchmark. In AAAI, 2016. 5, 6
  27. 27.Quanzeng You, Jiebo Luo, Hailin Jin, and Jianchao Yang. Cross-modality consistent regression for joint visual-textual sentiment analysis of social multimedia. Proceedings of the Ninth ACM International Conference on Web Search and Data Mining, 2016. 1
  28. 28.Haimin Zhang and Min Xu. Weakly supervised emotion intensity prediction for recognition of emotions in images. IEEE Transactions on Multimedia, pages 1–1, 2020. 1, 2, 3, 6, 7
  29. 29.Sicheng Zhao, Yue Gao, Xiaolei Jiang, Hongxun Yao, Tat-Seng Chua, and Xiaoshuai Sun. Exploring principles-of-art features for image emotion recognition. In Proceedings of the 22nd ACM international conference on Multimedia, pages 47–56, 2014. 1, 2, 3, 6
  30. 30.Sicheng Zhao, Zizhou Jia, H. Chen, L. Li, Guiguang Ding, and K. Keutzer. Pdanet: Polarity-consistent deep attention network for fine-grained visual emotion regression. Proceedings of the 27th ACM International Conference on Multimedia, 2019. 1, 2, 3, 5, 6, 7
  31. 31.Sicheng Zhao, H. Yao, Yue Gao, R. Ji, Wenlong Xie, Xiaolei Jiang, and Tat-Seng Chua. Predicting personalized emotion perceptions of social images. Proceedings of the 24th ACM international conference on Multimedia, 2016. 1
  32. 32.Sicheng Zhao, Xingxu Yao, Jufeng Yang, G. Jia, Guiguang Ding, Tat-Seng Chua, B. Schuller, and K. Keutzer. Affective image content analysis: Two decades review and new perspectives. IEEE transactions on pattern analysis and machine intelligence, PP, 2021. 1, 2
  33. 33.B. Zhou, A. Khosla, A. Lapedriza, A. Oliva, and A. Torralba. Learning deep features for discriminative localization. 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), pages 2921–2929, 2016. 2, 5
  34. 34.Xinge Zhu, Liang Li, Weigang Zhang, Tianrong Rao, Min Xu, Qingming Huang, and Dong Xu. Dependency exploitation: A unified cnn-rnn approach for visual emotion recognition. In Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17, pages 3595–3601, 2017. 1, 6, 7

Citation

MLA
Xu, L., et al. “MDAN: Multi-level Dependent Attention Network for Visual Emotion Analysis”. arXiv, 2022, http://arxiv.org/abs/2203.13443v1.
APA
Xu, L., Wang, Z., Wu, B., & Lui, S. (2022). MDAN: Multi-level Dependent Attention Network for Visual Emotion Analysis. arXiv. http://arxiv.org/abs/2203.13443v1
Chicago
Xu, L., Z. Wang, B. Wu, and S. Lui. 2022. “MDAN: Multi-level Dependent Attention Network for Visual Emotion Analysis”. arXiv. http://arxiv.org/abs/2203.13443v1.
Harvard
Xu, L. et al. (2022) “MDAN: Multi-level Dependent Attention Network for Visual Emotion Analysis”, arXiv [Preprint]. Available at: http://arxiv.org/abs/2203.13443v1.
Vancouver
1. Xu L, Wang Z, Wu B, Lui S (2022) MDAN: Multi-level Dependent Attention Network for Visual Emotion Analysis. arXiv

BibTeX

@article{xu2022mdan,
  title = {MDAN: Multi-level Dependent Attention Network for Visual Emotion Analysis},
  author = {Xu, Liwen and Wang, Zhengtao and Wu, Bin and Lui, Simon},
  year = {2022},
  journal = {arXiv},
  url = {http://arxiv.org/abs/2203.13443v1},
  eprint = {2203.13443}
}
Metadata:arXiv

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: IEEE