Understanding Iterative Revision from Human-Written Text

Wanyu DuVipul RahejaDhruv KumarZae Myung KimMelissa LopezDongyeop Kang

article2022ACL83 citations

Presents ITERATER, a multi-domain corpus of iteratively revised text annotated with edit intentions across sentence and paragraph granularities, demonstrating that modeling human revision goals improves automatic text editing systems.

Listen

Writing is inherently an iterative and strategic process where human authors continuously refine their drafts across multiple cycles. However, existing automated text revision systems typically simplify this complex workflow into single-pass, sentence-level paraphrasing or confine their models to narrow, single-domain contexts. This gap between actual human writing behavior and automated tools restricts the practical utility of modern writing assistants.

The article introduces a comprehensive framework and a multi-domain corpus designed to model how humans iteratively revise text across various depths and granularities. The main objective is to evaluate how specific edit intentions affect document quality and demonstrate that incorporating these intentions significantly improves the performance of computational text revision models.

To accomplish this, the authors constructed ITERATER, a dataset comprising 31,631 iterative document revisions containing 196,987 edit actions across Wikipedia articles, ArXiv scientific paper abstracts, and Wikinews stories. The team developed an edit intention taxonomy covering fluency, clarity, coherence, style, and meaning changes. They established a reference set of 4,018 human edit actions annotated through crowdsourcing and expert linguists, trained a classifier to automatically label the remaining full dataset, and benchmarked both edit-based and generative machine learning models against human revisions.

Key findings show that human editors perform the vast majority of edits during initial revision cycles, with editing activity sharply decreasing in deeper iterations. Clarity and fluency edits dominate across all domains, while scientific papers also exhibit high proportions of substantive meaning changes. Evaluators found that clarity, fluency, and coherence edits consistently enhance document quality, whereas subjective style edits slightly degrade it. When automated models are provided with explicit edit intentions, text generation performance improves markedly across evaluation metrics. However, in head-to-head comparisons, human revisions still outperform the best model revisions in overall quality in roughly 83% of evaluated document revisions, though models achieve competitive parity in meaning preservation and basic fluency.

These results demonstrate that automated text revision cannot rely solely on generic paraphrasing; systems must actively incorporate domain context and explicit editing goals to generate high-quality text. The findings also reveal that existing automated evaluation metrics correlate poorly with human judgments of fluency and coherence, indicating a clear operational risk in relying on standard metrics for text quality assurance.

Organizations developing or deploying automated writing assistance should integrate explicit edit-intention controls into their generative architectures rather than relying on unguided revision models. Furthermore, development teams should invest in creating more reliable automated quality metrics tailored to iterative refinement before deploying such models into high-stakes communication workflows.

The findings are currently bounded by the dataset's focus on formal writing domains and the lower reliability observed when predicting nuanced edit categories such as style and coherence. Readers can place high confidence in the positive impact of intent-conditioned modeling, but caution is warranted when automating subjective style adjustments or applying these models to informal communication channels.

Du et al (2022).pdf

No sufficiently relevant recommendations were found.

Cover for Understanding Iterative Revision from Human-Written Text

Table of Contents

  • 1 Introduction
  • 2 Related Work
  • 3 Formulation: Iterative Text Revision
  • 4 ITERATER Dataset
  • 4.1 Raw Data Collection
  • 4.2 Data Annotation
  • 4.2.1 Edit Intention Taxonomy
  • 4.2.2 Manual Annotation
  • 4.2.3 Automatic Annotation
  • 4.3 Data Analysis
  • 5 Understanding Iterative Text Revisions
  • 5.1 Experiment Setups
  • 5.2 Quality Analyses on Revised Texts
  • 6 Modeling Iterative Text Revisions
  • 6.1 Experiment Setups
  • 6.2 Results Analysis
  • 7 Conclusions and Discussions
  • 8 Ethical Considerations
  • Acknowledgments
  • References
  • A Details on Text Processing in ITERATER
  • B Details on Qualification Tests for Human Annotation
  • C Human Annotation Instruction and Interface
  • D Details on Computational Experiments
  • E Justification of Automatic Evaluation Metrics
  • F Details on Human Evaluation for Single Human Revision Quality
  • G Details on Human Evaluation Configuration for Model Revisions
  • H Details on Automatic Evaluation for Model Revisions

Knowls

  1. Knowl 1 — ITERATER provides multi-domain iterative revision histories at two annotation scales

    data/table

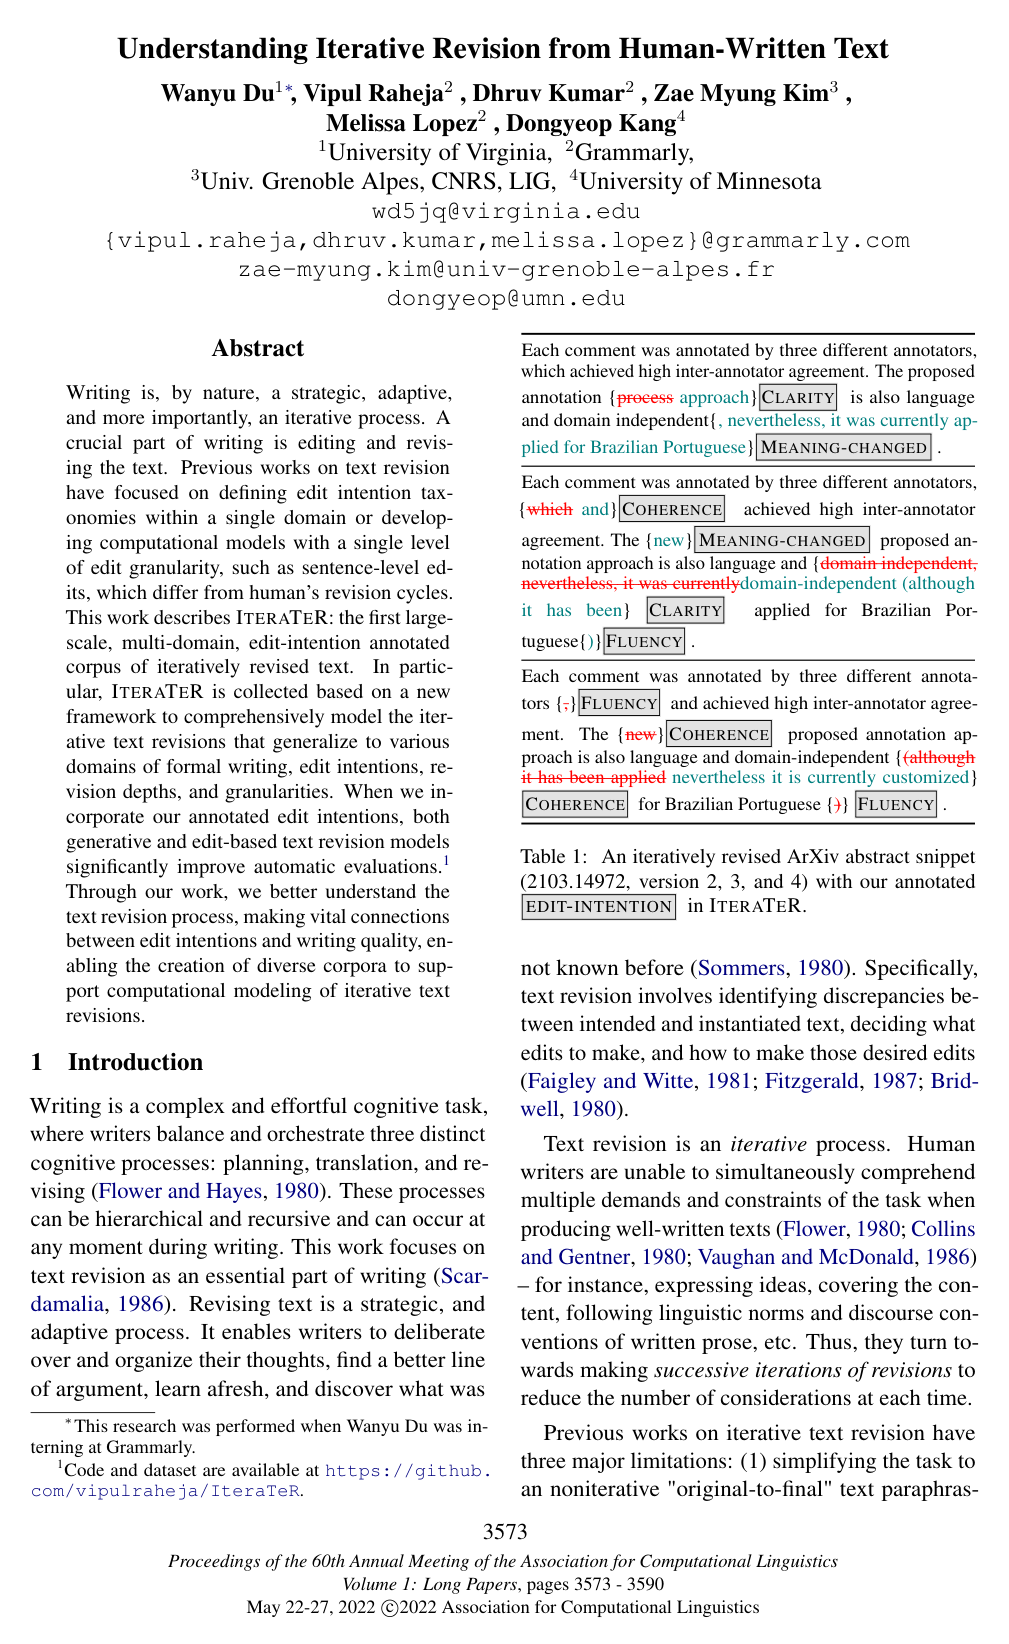
    ITERATER is a corpus of successive revisions of formally written human text from ArXiv abstracts, Wikipedia articles, and Wikinews articles. The collected full corpus contains 31,631 document revisions and 196,987 extracted edit actions; revisions are represented at sentence and paragraph granularity. The manually annotated portion contains 559 document revisions and 4,018 edit actions. For the full corpus, the counts by domain are: ArXiv, 11,443 revisions and 79,468 actions; Wikipedia, 10,674 revisions and 67,719 actions; Wikinews, 9,514 revisions and 49,800 actions. For the manually annotated portion, the corresponding counts are: ArXiv, 178 revisions and 1,177 actions; Wikipedia, 179 revisions and 1,432 actions; Wikinews, 202 revisions and 1,409 actions. The full dataset has automatically predicted intention labels, while the human subset has manually adjudicated labels. The authors collected recent wiki revision histories and ArXiv submission histories, using abstracts rather than full papers for ArXiv. ITERATER is intended for formal writing; informal text such as blogs and emails is outside its current scope.

  2. Knowl 2 — Edit intentions distinguish meaning changes from four kinds of meaning-preserving revision

    definition

    An edit action is a local insertion, deletion, or modification to a text object. Changes to tokens or phrases are sentence-level edits; changes to sentences are paragraph-level edits; and changes to paragraphs are document-level edits. Each edit action receives one intention label. The taxonomy divides intentions into meaning-changing and meaning-preserving edits. MEANING-CHANGED updates or adds information. Meaning-preserving edits are FLUENCY (correct grammatical errors), COHERENCE (improve logical links and consistency), CLARITY (improve formality, concision, readability, or understandability), and STYLE (express a writer’s preferences for tone, voice, or emotion). OTHER covers edits that do not fit the defined categories. Among the 4,018 manually labeled actions, the counts and shares were: CLARITY 1,601 (39.85%), FLUENCY 942 (23.44%), MEANING-CHANGED 896 (22.30%), COHERENCE 393 (9.78%), STYLE 128 (3.19%), and OTHER 58 (1.44%).

  3. Knowl 3 — Iterative text revision models successive document versions and explicit stopping criteria

    definition

    A document revision at depth tt pairs the previous and current document versions, Dt−1D_{t-1} and DtD_t, and contains Kt≥1K_t \geq 1 edit actions, each paired with an intention label: Rt=((Dt−1,Dt),{(akt,ekt)}k=1Kt)R_t = ((D_{t-1},D_t), \{(a_k^t,e_k^t)\}_{k=1}^{K_t}). Here, akta_k^t is the kkth edit action in revision tt, and ekte_k^t is its intention. Iterative text revision starts from a source document and repeatedly generates a new version until a stopping condition is met. In the experiments, revision stopped when depth reached 10 or when consecutive versions had zero edit distance. The general task definition allows stopping conditions based on an automatic or human evaluator of text quality; the experiments did not use an overall-quality threshold.

  4. Knowl 4 — Manual annotation and intention prediction have moderate agreement and uneven class accuracy

    experimental setup

    The 4,018 manually labeled edit actions were annotated by three people each. Qualified Amazon Mechanical Turk annotators provided labels, and expert linguists reannotated actions without a majority decision; the final label was the majority vote among three annotations. Fleiss’ κ\kappa rose from 0.3628 in the first annotation round to 0.5014 after expert reannotation; second-round agreement was 0.4983 for ArXiv, 0.4274 for Wikipedia, and 0.5601 for Wikinews. To label the larger corpus, the authors trained a RoBERTa-based classifier using the original and revised text for each action, with 3,254 training, 400 validation, and 364 test pairs. Test-set precision, recall, and F1 were: CLARITY 0.75, 0.63, 0.69; FLUENCY 0.74, 0.86, 0.80; COHERENCE 0.29, 0.36, 0.32; STYLE 1.00, 0.07, 0.13; and MEANING-CHANGED 0.44, 0.69, 0.53. Thus, performance was strongest for FLUENCY and CLARITY, while STYLE recall and COHERENCE F1 were low.

  5. Knowl 5 — Intention labels improve revision-model SARI, but gains on other metrics are not uniform

    empirical result

    FELIX (edit-based), BART, and PEGASUS (generative) were trained with four data configurations: manually annotated revisions without labels (HUMAN-RAW), the same revisions with manual labels (HUMAN), the full corpus without labels (FULL-RAW), and the full corpus with automatically predicted labels (FULL). The labels were appended to the source text. All models were evaluated on the test set of the manually annotated dataset. The reported scores are SARI, BLEU, ROUGE-L, and their arithmetic mean, respectively:

    • FELIX: HUMAN-RAW 29.23, 49.48, 63.43, 47.38; HUMAN 30.65, 54.35, 59.06, 48.02; FULL-RAW 30.34, 55.10, 56.49, 47.31; FULL 33.48, 61.90, 63.72, 53.03.
    • BART: HUMAN-RAW 33.20, 78.59, 85.20, 65.66; HUMAN 34.77, 74.43, 84.45, 64.55; FULL-RAW 33.88, 78.55, 86.05, 66.16; FULL 37.28, 77.50, 86.14, 66.97.
    • PEGASUS: HUMAN-RAW 33.09, 79.09, 86.77, 66.32; HUMAN 34.43, 78.85, 86.84, 66.71; FULL-RAW 34.67, 78.21, 87.06, 66.65; FULL 37.11, 77.60, 86.84, 67.18.
    • No-edit baseline: SARI 29.47, BLEU 81.25, ROUGE-L 88.04, mean 66.25.

    SARI rises when intention labels are added for each architecture and corresponding data scale. The mean-score effect is not uniformly positive: for example, BART’s HUMAN mean is below its HUMAN-RAW mean, whereas all three models achieve their highest mean with FULL. The results therefore support the value of labels and additional data on some measures and configurations, rather than a uniform improvement on every metric.

  6. Knowl 6 — Revision intentions and depth have different patterns across the three writing domains

    empirical result

    Across ArXiv, Wikipedia, and Wikinews, most edit actions occur at revision depth 1; the number falls sharply at depth 2, with relatively few actions at depths 3 and 4. CLARITY is among the most frequent intentions in all three domains. ArXiv has many MEANING-CHANGED edits, consistent with updates to research information, as well as substantial FLUENCY and COHERENCE editing. In Wikipedia, FLUENCY, COHERENCE, and MEANING-CHANGED edits occur at broadly similar frequencies, suggesting a more varied mix of revision goals. Wikinews gives comparable emphasis to FLUENCY, reflecting attention to grammatical correctness alongside other revision goals.

  7. Knowl 7 — Human revisions improve sampled documents overall, but the measured benefit declines at later depths

    empirical result

    In a manual evaluation of 21 iterative document revisions from seven documents, linguists compared each original version with its revision and scored the revised text as worse (-1), no better or unresolved (0), or better (1). Mean overall scores were 0.4285 at depth 1, 0.4285 at depth 2, and 0.1428 at depth 3: revisions were generally judged beneficial, but the advantage was smaller at the deepest evaluated revision. Automatic metric differences (revised minus original) were, at depths 1, 2, and 3 respectively: BLEURT 0.1982, 0.1368, -0.0224; SLOR -0.0985, -0.1025, -0.0792; Entity Grid (EG) -0.0132, -0.0295, 0.0278; and Flesch–Kincaid Grade Level (FKGL) -1.0718, -2.4973, 1.8131. Lower FKGL indicates easier readability. In a separate correlation analysis of sampled revisions, automatic metrics had weak relationships with human overall judgments: Pearson/Spearman correlations were 0.1139/0.0756 for BLEURT, -0.1239/-0.2218 for change in SLOR, -0.1480/0.0187 for change in EG, and 0.1171/0.2042 for change in FKGL. The authors note that deeper revisions contain fewer meaning-preserving edits, which may contribute to the lower human scores at later depths.

  8. Knowl 8 — Human judgments favor FLUENCY, COHERENCE, and CLARITY edits over STYLE edits

    empirical result

    For 120 sentence pairs, each associated with a single FLUENCY, COHERENCE, CLARITY, or STYLE edit, human evaluators scored whether the revision improved overall quality using -1 for worse, 0 for no improvement or unresolved judgment, and 1 for better. Mean scores were 0.3673 for FLUENCY, 0.1500 for COHERENCE, 0.2800 for CLARITY, and -0.0385 for STYLE. Thus, the sampled FLUENCY, COHERENCE, and CLARITY edits tended to improve judged quality, while STYLE edits did not. The paper interprets the STYLE result in light of its definition as preference-driven: a stylistic change need not improve readability, fluency, or coherence. The result also reinforces the authors’ caution that their automatic fluency and coherence metrics did not reliably track human judgments.

  9. Knowl 9 — Human revisions retain an advantage in overall quality and readability over the best model revisions

    empirical result

    Evaluators compared human revisions with revisions generated by PEGASUS trained on the full automatically labeled corpus. For 30 single-document revisions without meaning-changing edits, the percentages preferring the human revision, choosing a tie, or preferring the model revision were: overall quality 83.33%, 10.00%, 6.67%; content preservation 13.33%, 70.00%, 16.67%; fluency 50.00%, 50.00%, 0.00%; coherence 40.00%, 56.67%, 3.33%; and readability 86.67%, 10.00%, 3.33%. Human revisions therefore had a clear advantage in overall quality and readability; model revisions were preferred more often for content preservation, while fluency was tied and most coherence judgments favored a tie. In a separate comparison of 21 iterative document revisions, human revisions were preferred at depths 1 and 2 (57.14% at each depth; model preference 28.58%, tie 14.28%). At depth 3, evaluators chose a tie 57.15% of the time, preferred human revisions 42.85% of the time, and never preferred the model revisions. The paper notes that human revisions at the deepest level often included meaning changes, whereas models tended to make only FLUENCY or CLARITY edits.

  10. Knowl 10 — Models differ in their ability to stop iterating and in the errors they make at later revisions

    empirical result

    Under an experimental limit of 10 iterations and a stop condition of zero edit distance between consecutive versions, humans made an average of 1.61 revisions per document, PEGASUS made 2.57, and FELIX continued to the maximum cutoff of 10. The authors interpret this as evidence that FELIX can keep editing without effectively deciding when the text is good enough, while PEGASUS more often stops after a limited sequence of changes. In inspected examples, FELIX sometimes inserted out-of-context material that distorted meaning. PEGASUS better preserved the original meaning, but was more likely to delete phrases or tokens at deeper revision depths. These observations qualify the models’ automatic-evaluation gains: repeated edits did not ensure well-controlled revision quality.

Coverage note — Detailed per-intention and per-depth SARI breakdowns and the example revision transcripts are omitted as supplementary diagnostics; the main model comparisons and observed failure patterns are retained.

References

  1. 1.Talita Anthonio, Irshad Bhat, and Michael Roth. 2020. wikiHowToImprove: A resource and analyses on edits in instructional texts. In Proceedings of the 12th Language Resources and Evaluation Conference, pages 5721–5729, Marseille, France. European Language Resources Association.
  2. 2.Satanjeev Banerjee and Alon Lavie. 2005. METEOR: An automatic metric for MT evaluation with improved correlation with human judgments. In Proceedings of the ACL Workshop on Intrinsic and Extrinsic Evaluation Measures for Machine Translation and/or Summarization, pages 65–72, Ann Arbor, Michigan. Association for Computational Linguistics.
  3. 3.Irshad Bhat, Talita Anthonio, and Michael Roth. 2020. Towards modeling revision requirements in wikiHow instructions. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 8407–8414, Online. Association for Computational Linguistics.
  4. 4.Jan A. Botha, Manaal Faruqui, John Alex, Jason Baldridge, and Dipanjan Das. 2018. Learning to split and rephrase from Wikipedia edit history. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing, pages 732–737, Brussels, Belgium. Association for Computational Linguistics.
  5. 5.Lillian S. Bridwell. 1980. Revising strategies in twelfth grade students’ transactional writing. Research in the Teaching of English, 14(3):197–222.
  6. 6.Allan Collins and Dedre Gentner. 1980. A framework for a cognitive theory of writing. In Cognitive processes in writing, pages 51–72. Erlbaum.
  7. 7.Yue Dong, Zichao Li, Mehdi Rezagholizadeh, and Jackie Chi Kit Cheung. 2019. EditNTS: An neural programmer-interpreter model for sentence simplification through explicit editing. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, pages 3393–3402, Florence, Italy. Association for Computational Linguistics.
  8. 8.Micha Elsner and Eugene Charniak. 2008. Coreference-inspired coherence modeling. In Proceedings of ACL-08: HLT, Short Papers, pages 41–44, Columbus, Ohio. Association for Computational Linguistics.
  9. 9.Lester Faigley and Stephen Witte. 1981. Analyzing revision. College composition and communication, 32(4):400–414.
  10. 10.Felix Faltings, Michel Galley, Gerold Hintz, Chris Brockett, Chris Quirk, Jianfeng Gao, and Bill Dolan. 2021. Text editing by command. In Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 5259–5274, Online. Association for Computational Linguistics.
  11. 11.Manaal Faruqui, Ellie Pavlick, Ian Tenney, and Dipanjan Das. 2018. WikiAtomicEdits: A multilingual corpus of Wikipedia edits for modeling language and discourse. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing, pages 305–315, Brussels, Belgium. Association for Computational Linguistics.
  12. 12.Jill Fitzgerald. 1987. Research on revision in writing. Review of educational research, 57(4):481–506.
  13. 13.Joseph L Fleiss. 1971. Measuring nominal scale agreement among many raters. Psychological bulletin, 76(5):378.
  14. 14.Linda Flower. 1980. The dynamics of composing: Making plans and juggling constraints. Cognitive processes in writing, pages 31–50.
  15. 15.Linda Flower and John R. Hayes. 1980. The cognition of discovery: Defining a rhetorical problem. College Composition and Communication, 31(1):21–32.
  16. 16.Han Guo, Ramakanth Pasunuru, and Mohit Bansal. 2018. Dynamic multi-level multi-task learning for sentence simplification. In Proceedings of the 27th International Conference on Computational Linguistics, pages 462–476, Santa Fe, New Mexico, USA. Association for Computational Linguistics.
  17. 17.Robert A Harris. 2017. Writing with clarity and style: A guide to rhetorical devices for contemporary writers. Routledge.
  18. 18.Takumi Ito, Tatsuki Kuribayashi, Hayato Kobayashi, Ana Brassard, Masato Hagiwara, Jun Suzuki, and Kentaro Inui. 2019. Diamonds in the rough: Generating fluent sentences from early-stage drafts for academic writing assistance. In Proceedings of the 12th International Conference on Natural Language Generation, pages 40–53, Tokyo, Japan. Association for Computational Linguistics.
  19. 19.Katharina Kann, Sascha Rothe, and Katja Filippova. 2018. Sentence-level fluency evaluation: References help, but can be spared! In Proceedings of the 22nd Conference on Computational Natural Language Learning, pages 313–323, Brussels, Belgium. Association for Computational Linguistics.
  20. 20.J Peter Kincaid, Robert E Fishburne Jr, Richard L Rogers, and Brad S Chissom. 1975. Derivation of new readability formulas (automated readability index, fog count and flesch reading ease formula) for navy enlisted personnel. Technical report, Naval Technical Training Command Millington TN Research Branch.
  21. 21.Charles J Kowalski. 1972. On the effects of non-normality on the distribution of the sample product-moment correlation coefficient. Journal of the Royal Statistical Society: Series C (Applied Statistics), 21(1):1–12.
  22. 22.Mirella Lapata and Regina Barzilay. 2005. Automatic evaluation of text coherence: Models and representations. In IJCAI, pages 1085–1090.
  23. 23.Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Veselin Stoyanov, and Luke Zettlemoyer. 2020. BART: Denoising sequence-to-sequence pre-training for natural language generation, translation, and comprehension. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 7871–7880, Online. Association for Computational Linguistics.
  24. 24.Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov. 2020. RoBERTa: A robustly optimized BERT pretraining approach. In International Conference on Learning Representations.
  25. 25.Ilya Loshchilov and Frank Hutter. 2018. Decoupled weight decay regularization. In International Conference on Learning Representations.
  26. 26.Annie Louis and Ani Nenkova. 2012. A coherence model based on syntactic patterns. In Proceedings of the 2012 Joint Conference on Empirical Methods in Natural Language Processing and Computational Natural Language Learning, pages 1157–1168, Jeju Island, Korea. Association for Computational Linguistics.
  27. 27.Jonathan Mallinson, Aliaksei Severyn, Eric Malmi, and Guillermo Garrido. 2020. FELIX: Flexible text editing through tagging and insertion. In Findings of the Association for Computational Linguistics: EMNLP 2020, pages 1244–1255, Online. Association for Computational Linguistics.
  28. 28.Eric Malmi, Sebastian Krause, Sascha Rothe, Daniil Mirylenka, and Aliaksei Severyn. 2019. Encode, tag, realize: High-precision text editing. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP), pages 5054–5065, Hong Kong, China. Association for Computational Linguistics.
  29. 29.Islam Nassar, Michelle Ananda-Rajah, and Gholamreza Haffari. 2019. Neural versus non-neural text simplification: A case study. In Proceedings of the The 17th Annual Workshop of the Australasian Language Technology Association, pages 172–177, Sydney, Australia. Australasian Language Technology Association.
  30. 30.Daiki Nishihara, Tomoyuki Kajiwara, and Yuki Arase. 2019. Controllable text simplification with lexical constraint loss. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics: Student Research Workshop, pages 260–266, Florence, Italy. Association for Computational Linguistics.
  31. 31.Adam Pauls and Dan Klein. 2012. Large-scale syntactic language modeling with treelets. In Proceedings of the 50th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 959–968, Jeju Island, Korea. Association for Computational Linguistics.
  32. 32.F. Pedregosa, G. Varoquaux, A. Gramfort, V. Michel, B. Thirion, O. Grisel, M. Blondel, P. Prettenhofer, R. Weiss, V. Dubourg, J. Vanderplas, A. Passos, D. Cournapeau, M. Brucher, M. Perrot, and E. Duchesnay. 2011. Scikit-learn: Machine learning in Python. Journal of Machine Learning Research, 12:2825–2830.
  33. 33.Dietrich Rathjens. 1985. The seven components of clarity in technical writing. IEEE Transactions on Professional Communication, PC-28(4):42–46.
  34. 34.M. Scardamalia. 1986. Research on written composition. Handbook of reserch on teaching.
  35. 35.Thibault Sellam, Dipanjan Das, and Ankur Parikh. 2020. BLEURT: Learning robust metrics for text generation. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 7881–7892, Online. Association for Computational Linguistics.
  36. 36.Marina Solnyshkina, Radif Zamaletdinov, Ludmila Gorodetskaya, and Azat Gabitov. 2017. Evaluating text complexity and flesch-kincaid grade level. Journal of Social Studies Education Research, 8(3):238–248.
  37. 37.Nancy Sommers. 1980. Revision strategies of student writers and experienced adult writers. College composition and communication, 31(4):378–388.
  38. 38.Radu Soricut and Daniel Marcu. 2006. Discourse generation using utility-trained coherence models. In Proceedings of the COLING/ACL 2006 Main Conference Poster Sessions, pages 803–810, Sydney, Australia. Association for Computational Linguistics.
  39. 39.Alexander Spangher and Jonathan May. 2021. NewsEdits: A dataset of revision histories for news articles (technical report: Data processing). https://arxiv.org/abs/2104.09647.
  40. 40.Marie M. Vaughan and David D. McDonald. 1986. A model of revision in natural language generation. In 24th Annual Meeting of the Association for Computational Linguistics, pages 90–96, New York, New York, USA. Association for Computational Linguistics.
  41. 41.Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Clement Delangue, Anthony Moi, Pierric Cistac, Tim Rault, Remi Louf, Morgan Funtowicz, Joe Davison, Sam Shleifer, Patrick von Platen, Clara Ma, Yacine Jernite, Julien Plu, Canwen Xu, Teven Le Scao, Sylvain Gugger, Mariama Drame, Quentin Lhoest, and Alexander Rush. 2020. Transformers: State-of-the-art natural language processing. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations, pages 38–45, Online. Association for Computational Linguistics.
  42. 42.Wei Xu, Courtney Napoles, Ellie Pavlick, Quanze Chen, and Chris Callison-Burch. 2016. Optimizing Statistical Machine Translation for Text Simplification. Transactions of the Association for Computational Linguistics, 4:401–415.
  43. 43.Diyi Yang, Aaron Halfaker, Robert Kraut, and Eduard Hovy. 2016. Who did what: Editor role identification in wikipedia. In Proceedings of the International AAAI Conference on Web and Social Media, volume 10.
  44. 44.Diyi Yang, Aaron Halfaker, Robert Kraut, and Eduard Hovy. 2017. Identifying semantic edit intentions from revisions in Wikipedia. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, pages 2000–2010, Copenhagen, Denmark. Association for Computational Linguistics.
  45. 45.Fan Zhang, Homa B. Hashemi, Rebecca Hwa, and Diane Litman. 2017. A corpus of annotated revisions for studying argumentative writing. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 1568–1578, Vancouver, Canada. Association for Computational Linguistics.
  46. 46.Jingqing Zhang, Yao Zhao, Mohammad Saleh, and Peter Liu. 2020a. Pegasus: Pre-training with extracted gap-sentences for abstractive summarization. In International Conference on Machine Learning, pages 11328–11339. PMLR.
  47. 47.Tianyi Zhang, Varsha Kishore, Felix Wu, Kilian Q. Weinberger, and Yoav Artzi. 2020b. BERTScore: Evaluating text generation with BERT. In International Conference on Learning Representations.
  48. 48.Daniel Zwillinger and Stephen Kokoska. 1999. CRC standard probability and statistics tables and formulae. CRC Press.

Citation

MLA
Du, W., et al. “Understanding Iterative Revision from Human-Written Text”. Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 2022, pp. 3573–90, https://doi.org/10.18653/v1/2022.acl-long.250.
APA
Du, W., Raheja, V., Kumar, D., Kim, Z. M., Lopez, M., & Kang, D. (2022). Understanding Iterative Revision from Human-Written Text. Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 3573–3590. https://doi.org/10.18653/v1/2022.acl-long.250
Chicago
Du, W., V. Raheja, D. Kumar, Z. M. Kim, M. Lopez, and D. Kang. 2022. “Understanding Iterative Revision from Human-Written Text”. Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 3573–90. https://doi.org/10.18653/v1/2022.acl-long.250.
Harvard
Du, W. et al. (2022) “Understanding Iterative Revision from Human-Written Text”, Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). Association for Computational Linguistics, pp. 3573–3590. Available at: https://doi.org/10.18653/v1/2022.acl-long.250.
Vancouver
1. Du W, Raheja V, Kumar D, Kim ZM, Lopez M, Kang D (2022) Understanding Iterative Revision from Human-Written Text. In: Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). Association for Computational Linguistics, pp 3573–3590

BibTeX

@inproceedings{du-etal-2022-understanding-iterative,
    title = "Understanding Iterative Revision from Human-Written Text",
    author = "Du, Wanyu  and
      Raheja, Vipul  and
      Kumar, Dhruv  and
      Kim, Zae Myung  and
      Lopez, Melissa  and
      Kang, Dongyeop",
    editor = "Muresan, Smaranda  and
      Nakov, Preslav  and
      Villavicencio, Aline",
    booktitle = "Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month = may,
    year = "2022",
    address = "Dublin, Ireland",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2022.acl-long.250/",
    doi = "10.18653/v1/2022.acl-long.250",
    pages = "3573--3590"
}
Metadata:ACL Anthology

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: https://creativecommons.org/licenses/by/4.0/