SOOD: Towards Semi-Supervised Oriented Object Detection

Wei HuaDingkang LiangJingyu LiXiaolong LiuZhikang ZouXiaoqing YeXiang Bai

article2023CVPR70 citations

Presents the first semi-supervised oriented object detection framework by introducing rotation-aware adaptive weighting and global layout consistency losses to exploit unlabeled aerial imagery effectively.

Listen

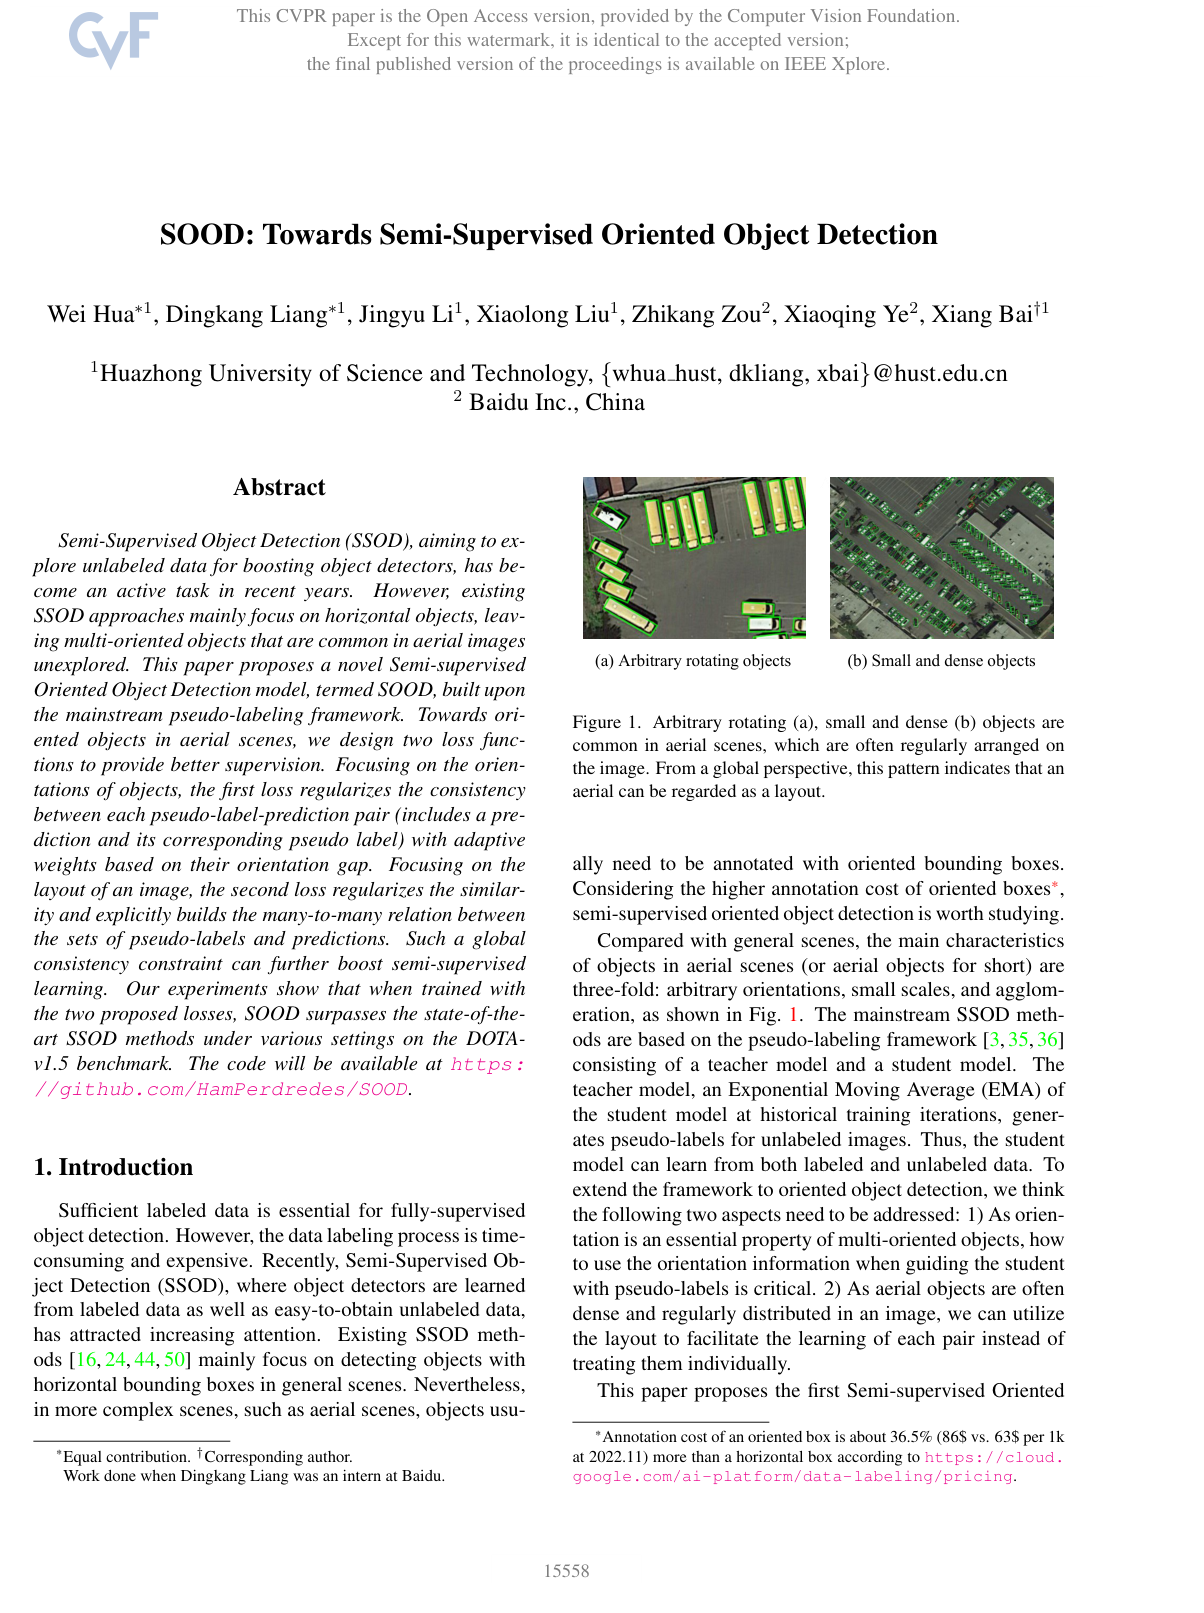
Training computer vision models to identify objects in aerial imagery requires extensive bounding-box annotations. Labeling oriented bounding boxes for objects with arbitrary angles—such as vehicles, ships, and infrastructure—costs roughly 36.5% more than standard horizontal boxes. While semi-supervised learning methods use inexpensive unlabeled images to reduce labeling burdens, existing frameworks focus on horizontal objects and struggle with the unique challenges of aerial scenes, such as dense object clusters, small targets, and arbitrary rotations.

The article introduces and evaluates a semi-supervised oriented object detection framework called SOOD. Its primary objective is to demonstrate that incorporating rotation awareness and scene-level spatial layouts into a teacher-student pseudo-labeling framework enables high-accuracy oriented object detection with minimal labeled data.

The approach builds upon a dense pseudo-labeling architecture where a primary model (the student) learns from both labeled data and guidance generated by an ensemble model (the teacher). The researchers introduced two specialized loss mechanisms: an instance-level loss that dynamically weights training supervision based on the angular difference between predictions and pseudo-labels, and a global consistency loss that uses mathematical transport theory to match spatial distributions and confidence scores across the entire image. The framework was evaluated on the benchmark DOTA-v1.5 dataset, which contains over 400,000 annotated aerial instances across 16 categories, tested under 10%, 20%, 30%, and fully labeled data conditions against leading semi-supervised alternatives.

The experimental findings show that SOOD consistently outperforms existing semi-supervised methods across all evaluated data proportions. When trained on only 10% labeled data, SOOD achieved an accuracy score of 48.63 mAP, improving by +5.85 points over the supervised baseline and outperforming the prior leading method by +1.73 points. Under 20% and 30% labeled data settings, it reached 55.58 and 59.23 mAP, outperforming supervised models by +5.47 and +4.44 points, respectively. In fully labeled settings supplemented by unlabeled data, the framework reached 67.70 mAP, improving the baseline by +2.24 points. Furthermore, the framework generalized effectively to other detector architectures, delivering accuracy gains between +1.32 and +2.41 points.

These results indicate that organizations analyzing aerial and satellite imagery can achieve superior detection accuracy while cutting data labeling costs and operational timelines. By softly weighting rotation differences and enforcing overall layout consistency, the system prevents label noise from accumulating during training, overcoming the primary hurdle that caused some previous semi-supervised methods to degrade when given unlabeled data.

Organizations deploying aerial object detection should adopt rotation-aware semi-supervised frameworks to maximize model performance while controlling annotation budgets. Next operational steps should focus on piloting the framework across enterprise-specific aerial datasets and tuning pseudo-label sampling ratios. Further research is recommended to combine the separate rotation and layout modules into a unified architecture and expand the methodology to related domains such as 3D object detection and multi-oriented text recognition.

Confidence in these findings is strong given the rigorous multi-ratio testing on a standard benchmark and validation across multiple underlying detectors. However, stakeholders should note that the current implementation does not yet explicitly optimize for extreme scale variations or high aspect ratios, which represents the primary limitation when applying the framework to highly specialized imagery.

Cover for SOOD: Towards Semi-Supervised Oriented Object Detection

Abstract

Semi-Supervised Object Detection (SSOD), aiming to explore unlabeled data for boosting object detectors, has become an active task in recent years. However, existing SSOD approaches mainly focus on horizontal objects, leaving multi-oriented objects that are common in aerial images unexplored. This paper proposes a novel Semi-supervised Oriented Object Detection model, termed SOOD, built upon the mainstream pseudo-labeling framework. Towards oriented objects in aerial scenes, we design two loss functions to provide better supervision. Focusing on the orientations of objects, the first loss regularizes the consistency between each pseudo-label-prediction pair (includes a prediction and its corresponding pseudo label) with adaptive weights based on their orientation gap. Focusing on the layout of an image, the second loss regularizes the similarity and explicitly builds the many-to-many relation between the sets of pseudo-labels and predictions. Such a global consistency constraint can further boost semi-supervised learning. Our experiments show that when trained with the two proposed losses, SOOD surpasses the state-of-the-art SSOD methods under various settings on the DOTA-v1.5 benchmark. The code will be available at https://github.com/HamPerdredes/SOOD.

Table of Contents

  • 1. Introduction
  • 2. Related works
  • 3. Preliminary
  • 3.1. Pseudo-labeling Paradigm
  • 3.2. Optimal Transport
  • 4. Method
  • 4.1. The Overall Framework
  • 4.2. Rotation-aware Adaptive Weighting Loss
  • 4.3. Global Consistency Loss
  • 5. Experiments
  • 5.1. Implementation Details
  • 5.2. Main Results
  • 5.3. Ablation Study
  • 5.4. Limitation and Discussion
  • 6. Conclusion
  • References

Knowls

  1. Knowl 1 — SOOD dense pseudo-labeling architecture

    model/method

    SOOD is a semi-supervised oriented object detector built on a dense pseudo-labeling teacher–student framework. The teacher is an exponential moving average of the student and processes a weakly augmented version of each unlabeled aerial image; the student processes a strongly augmented version. The teacher first identifies informative prediction-map locations, after which dense pseudo-labels are randomly sampled from those locations and the student predictions at the same locations are paired with them.

    The student is trained on labeled images with ordinary oriented FCOS supervision and on unlabeled images with two additional constraints: Rotation-aware Adaptive Weighting (RAW) acts on each pseudo-label–prediction pair, while Global Consistency (GC) compares the teacher and student prediction sets as layouts. The pipeline therefore combines one-to-one instance supervision with a many-to-many set-level constraint.

  2. Knowl 2 — Rotation-aware Adaptive Weighting loss

    equation

    For the ii-th pair of an oriented teacher pseudo-label and its corresponding student prediction, let rit,ris∈[−π/2,π/2)r_i^t,r_i^s\in[-\pi/2,\pi/2) be their rotation angles in radians, let α\alpha control the importance of orientation differences, and let LiuL_i^u be the basic unsupervised classification, regression, and centerness loss for that pair. SOOD defines

    σi=α∣rit−ris∣π,ωirot=1+σi,\sigma_i=\alpha\frac{|r_i^t-r_i^s|}{\pi},\qquad \omega_i^{\mathrm{rot}}=1+\sigma_i,

    and uses the weighted unsupervised loss

    LRAW=∑i=1NpωirotLiu,L_{\mathrm{RAW}}=\sum_{i=1}^{N_p}\omega_i^{\mathrm{rot}}L_i^u,

    where NpN_p is the number of sampled pseudo-labels. The paper sets α=50\alpha=50. A pair with identical teacher and student orientations retains the original weight 11; pairs with larger orientation gaps receive larger weights. This is intended to use orientation disagreement as a difficulty signal while avoiding the assumption that every noisy pseudo-label is reliable.

  3. Knowl 3 — Global Consistency loss from optimal transport

    equation

    SOOD compares the teacher and student prediction sets as two discrete layouts rather than enforcing only their corresponding pairs. For NpN_p sampled locations and KK object classes, let sit,sis∈RKs_i^t,s_i^s\in\mathbb{R}^{K} be the teacher and student classification-score vectors at sampled location ii. Define the teacher-selected class

    c(i)=arg⁡max⁡1≤j≤Ksi,jt,c(i)=\arg\max_{1\leq j\leq K}s_{i,j}^t,

    and scalar distributions

    dit=exp⁡(si,c(i)t),dis=exp⁡(si,c(i)s).d_i^t=\exp\left(s_{i,c(i)}^t\right),\qquad d_i^s=\exp\left(s_{i,c(i)}^s\right).

    Let zit,zjs∈R2z_i^t,z_j^s\in\mathbb{R}^{2} be the two-dimensional coordinates of teacher sample ii and student sample jj. For every possible teacher–student matching pair, SOOD uses the cost

    Ci,j=Ci,jdist+Ci,jscore,C_{i,j}=C_{i,j}^{\mathrm{dist}}+C_{i,j}^{\mathrm{score}},

    where

    Ci,jdist=∥zit−zjs∥22max⁡1≤a,b≤Np∥zat−zbs∥22,Ci,jscore=∣si,c(i)t−sj,c(j)s∣max⁡1≤a,b≤Np∣sa,c(a)t−sb,c(b)s∣.C_{i,j}^{\mathrm{dist}}= \frac{\lVert z_i^t-z_j^s\rVert_2^2} {\displaystyle\max_{1\leq a,b\leq N_p}\lVert z_a^t-z_b^s\rVert_2^2}, \qquad C_{i,j}^{\mathrm{score}}= \frac{|s_{i,c(i)}^t-s_{j,c(j)}^s|} {\displaystyle\max_{1\leq a,b\leq N_p}|s_{a,c(a)}^t-s_{b,c(b)}^s|}.

    Here c(k)c(k) is the teacher-selected class at sampled index kk. Let λ∗,μ∗∈RNp\lambda^*,\mu^*\in\mathbb{R}^{N_p} be approximate optimal-transport dual potentials obtained with the Sinkhorn algorithm for transporting the normalized mass vectors dt/∥dt∥1d^t/\lVert d^t\rVert_1 and ds/∥ds∥1d^s/\lVert d^s\rVert_1 under cost matrix CC. The Global Consistency loss is

    LGC(dt,ds)=⟨λ∗,dt∥dt∥1⟩+⟨μ∗,ds∥ds∥1⟩,L_{\mathrm{GC}}(d^t,d^s)= \left\langle\lambda^*,\frac{d^t}{\lVert d^t\rVert_1}\right\rangle+ \left\langle\mu^*,\frac{d^s}{\lVert d^s\rVert_1}\right\rangle,

    where ⟨⋅,⋅⟩\langle\cdot,\cdot\rangle denotes the vector inner product. Combining spatial distance and score difference gives the transport procedure information about both object layout and prediction confidence. The resulting many-to-many matching is deliberately looser than fixed pairwise alignment, reducing sensitivity to noisy pseudo-label assignments and implicitly regularizing relations among student detections.

  4. Knowl 4 — Combined supervised and unsupervised objective

    model/method

    In SOOD, the student’s unsupervised objective for unlabeled images is the sum of the RAW and GC losses, while labeled images use the standard supervised loss of the oriented FCOS detector:

    L=Lu+Ls=LRAW+LGC+Ls.L=L_u+L_s=L_{\mathrm{RAW}}+L_{\mathrm{GC}}+L_s.

    The basic FCOS unsupervised terms consist of smooth-ℓ1\ell_1 regression loss, binary cross-entropy classification loss, and binary cross-entropy centerness loss. The proposed RAW and GC terms modify only the unsupervised branch; the supervised FCOS loss LsL_s is unchanged. The teacher is updated from the student by exponential moving average after each training update, so the teacher supplies progressively changing targets while the student receives both ground-truth and pseudo-label supervision.

  5. Knowl 5 — DOTA-v1.5 semi-supervised evaluation protocol

    experimental setup

    SOOD is evaluated on DOTA-v1.5, an aerial oriented-object dataset containing 2,806 large images and 402,089 annotated oriented objects. The official split has 1,411 training images, 458 validation images, and 937 test images; test annotations are unavailable. The dataset contains 16 object categories and includes more instances smaller than 10 pixels than DOTA-v1.0.

    Two semi-supervised protocols are used. In the partially labeled protocol, 10%, 20%, or 30% of DOTA-v1.5-train images are randomly labeled and the remaining training images are unlabeled. In the fully labeled protocol, all DOTA-v1.5-train images are labeled and DOTA-v1.5-test images are treated as unlabeled. All models are evaluated on DOTA-v1.5-val using mean average precision (mAP).

    The default implementation uses oriented FCOS with a ResNet-50 backbone and FPN. Images are cropped into 1024×10241024\times1024 patches with stride 824, giving 200-pixel overlap. The teacher receives weak augmentation consisting of random flipping; the student receives strong augmentation consisting of random flipping, color jittering, random grayscale conversion, and random Gaussian blur. Models are trained for 180,000 iterations on two RTX 3090 GPUs with SGD, initial learning rate 0.00250.0025, learning-rate drops at 120,000 and 160,000 iterations, momentum 0.90.9, weight decay 0.00010.0001, three images per GPU, and an unlabeled-to-labeled batch ratio of 1:21:2. The default pseudo-label sampling ratio is 0.250.25, and a burn-in phase initializes the teacher.

  6. Knowl 6 — Results with partially labeled aerial data

    data/table

    On DOTA-v1.5 with the same oriented-detector comparison protocol, SOOD achieves the best reported mAP at all three labeled-data proportions. An asterisk denotes the rotated Faster R-CNN implementation and a dagger denotes the rotated FCOS implementation.

    Could not parse LaTeX table

    Relative to the supervised rotated-FCOS baseline, SOOD gains +5.85+5.85, +5.47+5.47, and +4.44+4.44 mAP at 10%, 20%, and 30% labeled data, respectively. Relative to Dense Teacher, the gains are +1.73+1.73, +1.65+1.65, and +1.37+1.37 mAP. These results show that the orientation-aware and layout-aware constraints remain useful as the labeled fraction changes.

  7. Knowl 7 — Results with fully labeled data and other detectors

    data/table

    When all DOTA-v1.5 training images are labeled and the test images are used as additional unlabeled data, SOOD improves over the corresponding supervised baselines and exceeds the compared semi-supervised methods. In the table, the first mAP value is the supervised baseline, the middle value is the change after adding unlabeled data, and the final value is the semi-supervised result.

    Could not parse LaTeX table

    SOOD also transfers to other oriented detectors under the fully labeled protocol. CFA improves from 65.75 mAP with supervised training to 67.07 mAP with SOOD, a +1.32+1.32 gain. KLD, whose supervised implementation is based on RetinaNet, improves from 62.21 to 64.62 mAP, a +2.41+2.41 gain. Thus the proposed losses are not restricted to the rotated-FCOS implementation used for the main SOOD model.

  8. Knowl 8 — Complementarity of RAW and GC

    data/table

    An ablation on DOTA-v1.5 with 10%, 20%, and 30% labeled images evaluates the two proposed losses against the vanilla dense pseudo-labeling baseline. The four configurations and their mAP values are:

    Could not parse LaTeX table

    RAW alone improves the baseline by 0.58, 1.14, and 1.19 mAP at the three label proportions. GC alone improves it by 0.47, 0.65, and 0.96 mAP. Using both losses produces the strongest result, demonstrating that the local orientation-based constraint and the global layout-based constraint provide complementary supervision.

  9. Knowl 9 — Sensitivity to sampling, transport cost, and orientation weight

    data/table

    Several design ablations quantify how SOOD depends on its main hyperparameters and on the two components of the GC transport cost. All results use 10% labeled data. The sampling-ratio study uses both RAW and GC; the cost-map study uses RAW; and the α\alpha study uses GC.

    Could not parse LaTeX table
    Could not parse LaTeX table
    Could not parse LaTeX table

    The default sampling ratio 0.250.25 gives the best reported value; higher ratios introduce more noisy predictions, whereas lower ratios discard useful information. Both spatial distance and score difference are needed for the strongest GC result: using both yields 48.63 mAP, compared with 48.10 using score alone and 47.94 using distance alone. Increasing α\alpha helps from 1 to 50 but slightly hurts at 100, leading SOOD to use α=50\alpha=50.

  10. Knowl 10 — Stated limitations and future directions

    limitation

    SOOD exploits only two aerial-object properties: orientation and global layout. The method does not explicitly address other important characteristics such as scale variation and large aspect ratios. In addition, orientation and layout are imposed through two separate constraints rather than a unified module that could model them jointly. The authors identify integration of these cues, and extension to other settings containing oriented or complex objects such as 3D object detection and scene-text detection, as open directions.

Coverage note — No substantial contributed material was omitted; qualitative visualizations were illustrative, while the preliminary optimal-transport derivation was incorporated only to the extent needed to define the GC loss.

References

  1. 1.Martin Arjovsky, Soumith Chintala, and Leon Bottou. Wasserstein generative adversarial networks. In Proc. of Intl. Conf. on Machine Learning, pages 214–223. PMLR, 2017. 3
  2. 2.David Berthelot, Nicholas Carlini, Ian Goodfellow, Nicolas Papernot, Avital Oliver, and Colin A Raffel. Mixmatch: A holistic approach to semi-supervised learning. Proc. of Advances in Neural Information Processing Systems, 32, 2019. 2
  3. 3.Binghui Chen, Pengyu Li, Xiang Chen, Biao Wang, Lei Zhang, and Xian-Sheng Hua. Dense learning based semi-supervised object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 4815–4824, 2022. 1, 6, 7
  4. 4.Ting Chen, Simon Kornblith, Mohammad Norouzi, and Geoffrey Hinton. A simple framework for contrastive learning of visual representations. In Proc. of Intl. Conf. on Machine Learning, pages 1597–1607. PMLR, 2020. 2
  5. 5.Marco Cuturi. Sinkhorn distances: Lightspeed computation of optimal transport. Proc. of Advances in Neural Information Processing Systems, 26, 2013. 3, 5
  6. 6.Charlie Frogner, Chiyuan Zhang, Hossein Mobahi, Mauricio Araya, and Tomaso A Poggio. Learning with a wasserstein loss. Advances in neural information processing systems, 28, 2015. 5
  7. 7.Zheng Ge, Songtao Liu, Zeming Li, Osamu Yoshie, and Jian Sun. Ota: Optimal transport assignment for object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 303–312, 2021. 3
  8. 8.Ross Girshick. Fast r-cnn. In Porc. of IEEE Intl. Conf. on Computer Vision, pages 1440–1448, 2015. 2
  9. 9.Yves Grandvalet and Yoshua Bengio. Semi-supervised learning by entropy minimization. Proc. of Advances in Neural Information Processing Systems, 17, 2004. 2
  10. 10.Zonghao Guo, Chang Liu, Xiaosong Zhang, Jianbin Jiao, Xiangyang Ji, and Qixiang Ye. Beyond bounding-box: Convex-hull feature adaptation for oriented and densely packed object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 8792–8801, 2021. 6
  11. 11.Jiaming Han, Jian Ding, Jie Li, and Gui-Song Xia. Align deep features for oriented object detection. IEEE Transactions on Geoscience and Remote Sensing, 60:1–11, 2021. 5
  12. 12.Jiaming Han, Jian Ding, Nan Xue, and Gui-Song Xia. Redet: A rotation-equivariant detector for aerial object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 2786–2795, 2021. 2, 5
  13. 13.Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 770–778, 2016. 5
  14. 14.Jisoo Jeong, Seungeui Lee, Jeesoo Kim, and Nojun Kwak. Consistency-based semi-supervised learning for object detection. Proc. of Advances in Neural Information Processing Systems, 32, 2019. 2
  15. 15.Dong-Hyun Lee et al. Pseudo-label: The simple and efficient semi-supervised learning method for deep neural networks. In Proc. of Intl. Conf. on Machine Learning, volume 3, page 896, 2013. 2
  16. 16.Gang Li, Xiang Li, Yujie Wang, Shanshan Zhang, Yichao Wu, and Ding Liang. Pseco: Pseudo labeling and consistency training for semi-supervised object detection. In Proc. of European Conference on Computer Vision, 2022. 1
  17. 17.Jingyu Li, Zhe Liu, Jinghua Hou, and Dingkang Liang. Dds3d: Dense pseudo-labels with dynamic threshold for semi-supervised 3d object detection. Proc. of IEEE Intl. Conf. on Robotics and Automation, 2023. 2
  18. 18.Wentong Li, Yijie Chen, Kaixuan Hu, and Jianke Zhu. Oriented reppoints for aerial object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 1829–1838, 2022. 2
  19. 19.Minghui Liao, Zhaoyi Wan, Cong Yao, Kai Chen, and Xiang Bai. Real-time scene text detection with differentiable binarization. In Proc. of the AAAI Conf. on Artificial Intelligence, volume 34, pages 11474–11481, 2020. 2
  20. 20.Minghui Liao, Zhen Zhu, Baoguang Shi, Gui-song Xia, and Xiang Bai. Rotation-sensitive regression for oriented scene text detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 5909–5918, 2018. 2
  21. 21.Tsung-Yi Lin, Piotr Dollar, Ross Girshick, Kaiming He, Bharath Hariharan, and Serge Belongie. Feature pyramid networks for object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 2117–2125, 2017. 5
  22. 22.Tsung-Yi Lin, Priya Goyal, Ross Girshick, Kaiming He, and Piotr Dollar. Focal loss for dense object detection. In Porc. of IEEE Intl. Conf. on Computer Vision, pages 2980–2988, 2017. 2, 4, 6
  23. 23.Wei Liu, Dragomir Anguelov, Dumitru Erhan, Christian Szegedy, Scott Reed, Cheng-Yang Fu, and Alexander C Berg. Ssd: Single shot multibox detector. In Proc. of European Conference on Computer Vision, pages 21–37. Springer, 2016. 2
  24. 24.Yen-Cheng Liu, Chih-Yao Ma, Zijian He, Chia-Wen Kuo, Kan Chen, Peizhao Zhang, Bichen Wu, Zsolt Kira, and Peter Vajda. Unbiased teacher for semi-supervised object detection. In Proc. of International Conference on Learning Representations, 2021. 1, 2, 6
  25. 25.Yen-Cheng Liu, Chih-Yao Ma, and Zsolt Kira. Unbiased teacher v2: Semi-supervised object detection for anchor-free and anchor-based detectors. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 9819–9828, 2022. 2, 3
  26. 26.Takeru Miyato, Shin-ichi Maeda, Masanori Koyama, and Shin Ishii. Virtual adversarial training: a regularization method for supervised and semi-supervised learning. IEEE Transactions on Pattern Analysis and Machine Intelligence, 41(8):1979–1993, 2018. 2
  27. 27.Gaspard Monge. Memoire sur la théorie des déblais et des remblais. Mem. Math. Phys. Acad. Royale Sci., pages 666–704, 1781. 2, 3
  28. 28.Ilija Radosavovic, Piotr Dollar, Ross Girshick, Georgia Gkioxari, and Kaiming He. Data distillation: Towards omni-supervised learning. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 4119–4128, 2018. 2
  29. 29.Joseph Redmon, Santosh Divvala, Ross Girshick, and Ali Farhadi. You only look once: Unified, real-time object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 779–788, 2016. 2
  30. 30.Shaoqing Ren, Kaiming He, Ross Girshick, and Jian Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. Proc. of Advances in Neural Information Processing Systems, 28, 2015. 2, 6
  31. 31.Mehdi Sajjadi, Mehran Javanmardi, and Tolga Tasdizen. Regularization with stochastic transformations and perturbations for deep semi-supervised learning. Proc. of Advances in Neural Information Processing Systems, 29, 2016. 2
  32. 32.Kihyuk Sohn, David Berthelot, Nicholas Carlini, Zizhao Zhang, Han Zhang, Colin A Raffel, Ekin Dogus Cubuk, Alexey Kurakin, and Chun-Liang Li. Fixmatch: Simplifying semi-supervised learning with consistency and confidence. Proc. of Advances in Neural Information Processing Systems, 33:596–608, 2020. 2
  33. 33.Kihyuk Sohn, Zizhao Zhang, Chun-Liang Li, Han Zhang, Chen-Yu Lee, and Tomas Pfister. A simple semi-supervised learning framework for object detection. arXiv preprint arXiv:2005.04757, 2020. 2
  34. 34.Jingqun Tang, Wenqing Zhang, Hongye Liu, MingKun Yang, Bo Jiang, Guanglong Hu, and Xiang Bai. Few could be better than all: Feature sampling and grouping for scene text detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 4563–4572, 2022. 2
  35. 35.Yihe Tang, Weifeng Chen, Yijun Luo, and Yuting Zhang. Humble teachers teach better students for semi-supervised object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 3132–3141, 2021. 1, 2
  36. 36.Antti Tarvainen and Harri Valpola. Mean teachers are better role models: Weight-averaged consistency targets improve semi-supervised deep learning results. Proc. of Advances in Neural Information Processing Systems, 30, 2017. 1, 2
  37. 37.Zhi Tian, Chunhua Shen, Hao Chen, and Tong He. Fcos: Fully convolutional one-stage object detection. In Porc. of IEEE Intl. Conf. on Computer Vision, pages 9627–9636, 2019. 3, 5, 6, 7
  38. 38.Cedric Villani. Optimal transport: old and new, volume 338. Springer, 2009. 5
  39. 39.Boyu Wang, Huidong Liu, Dimitris Samaras, and Minh Hoai Nguyen. Distribution matching for crowd counting. Proc. of Advances in Neural Information Processing Systems, 33:1595–1607, 2020. 3, 5
  40. 40.Gui-Song Xia, Xiang Bai, Jian Ding, Zhen Zhu, Serge Belongie, Jiebo Luo, Mihai Datcu, Marcello Pelillo, and Liangpei Zhang. Dota: A large-scale dataset for object detection in aerial images. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 3974–3983, 2018. 5
  41. 41.Qizhe Xie, Zihang Dai, Eduard Hovy, Thang Luong, and Quoc Le. Unsupervised data augmentation for consistency training. Proc. of Advances in Neural Information Processing Systems, 33:6256–6268, 2020. 2
  42. 42.Qizhe Xie, Minh-Thang Luong, Eduard Hovy, and Quoc V Le. Self-training with noisy student improves imagenet classification. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 10687–10698, 2020. 2
  43. 43.Xingxing Xie, Gong Cheng, Jiabao Wang, Xiwen Yao, and Junwei Han. Oriented r-cnn for object detection. In Porc. of IEEE Intl. Conf. on Computer Vision, pages 3520–3529, 2021. 2
  44. 44.Mengde Xu, Zheng Zhang, Han Hu, Jianfeng Wang, Lijuan Wang, Fangyun Wei, Xiang Bai, and Zicheng Liu. End-to-end semi-supervised object detection with soft teacher. In Porc. of IEEE Intl. Conf. on Computer Vision, pages 3060–3069, 2021. 1, 2, 3, 6
  45. 45.Qize Yang, Xihan Wei, Biao Wang, Xian-Sheng Hua, and Lei Zhang. Interactive self-training with mean teachers for semi-supervised object detection. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 5941–5950, 2021. 2
  46. 46.Xue Yang and Junchi Yan. On the arbitrary-oriented object detection: Classification based approaches revisited. International Journal of Computer Vision, 130(5):1340–1365, 2022. 2
  47. 47.Xue Yang, Junchi Yan, Ziming Feng, and Tao He. R3det: Refined single-stage detector with feature refinement for rotating object. In Proc. of the AAAI Conf. on Artificial Intelligence, volume 35, pages 3163–3171, 2021. 2
  48. 48.Xue Yang, Xiaojiang Yang, Jirui Yang, Qi Ming, Wentao Wang, Qi Tian, and Junchi Yan. Learning high-precision bounding box for rotated object detection via kullback-leibler divergence. Proc. of Advances in Neural Information Processing Systems, 2021. 6
  49. 49.Fangneng Zhan, Yingchen Yu, Kaiwen Cui, Gongjie Zhang, Shijian Lu, Jianxiong Pan, Changgong Zhang, Feiying Ma, Xuansong Xie, and Chunyan Miao. Unbalanced feature transport for exemplar-based image translation. In Proc. of IEEE Intl. Conf. on Computer Vision and Pattern Recognition, pages 15028–15038, 2021. 3, 5
  50. 50.Hongyu Zhou, Zheng Ge, Songtao Liu, Weixin Mao, Zeming Li, Haiyan Yu, and Jian Sun. Dense teacher: Dense pseudo-labels for semi-supervised object detection. In Proc. of European Conference on Computer Vision, 2022. 1, 2, 3, 6
  51. 51.Barret Zoph, Golnaz Ghiasi, Tsung-Yi Lin, Yin Cui, Hanxiao Liu, Ekin Dogus Cubuk, and Quoc Le. Rethinking pre-training and self-training. Proc. of Advances in Neural Information Processing Systems, 33:3833–3845, 2020. 2

Citation

MLA
Hua, W., et al. “SOOD: Towards Semi-Supervised Oriented Object Detection”. 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023, pp. 15558–67, https://doi.org/10.1109/CVPR52729.2023.01493.
APA
Hua, W., Liang, D., Li, J., Liu, X., Zou, Z., Ye, X., & Bai, X. (2023). SOOD: Towards Semi-Supervised Oriented Object Detection. 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 15558–15567. https://doi.org/10.1109/CVPR52729.2023.01493
Chicago
Hua, W., D. Liang, J. Li, et al. 2023. “SOOD: Towards Semi-Supervised Oriented Object Detection”. 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 15558–67. https://doi.org/10.1109/CVPR52729.2023.01493.
Harvard
Hua, W. et al. (2023) “SOOD: Towards Semi-Supervised Oriented Object Detection”, 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). IEEE, pp. 15558–15567. Available at: https://doi.org/10.1109/CVPR52729.2023.01493.
Vancouver
1. Hua W, Liang D, Li J, Liu X, Zou Z, Ye X, Bai X (2023) SOOD: Towards Semi-Supervised Oriented Object Detection. In: 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). IEEE, pp 15558–15567

BibTeX

@inproceedings{Hua_2023, title={SOOD: Towards Semi-Supervised Oriented Object Detection}, url={http://dx.doi.org/10.1109/CVPR52729.2023.01493}, DOI={10.1109/cvpr52729.2023.01493}, booktitle={2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)}, publisher={IEEE}, author={Hua, Wei and Liang, Dingkang and Li, Jingyu and Liu, Xiaolong and Zou, Zhikang and Ye, Xiaoqing and Bai, Xiang}, year={2023}, month=June, pages={15558–15567} }
Metadata:Crossref

Access the Paper

This paper is available from its original source. Click below to access the PDF.

Open PDF
License: IEEE