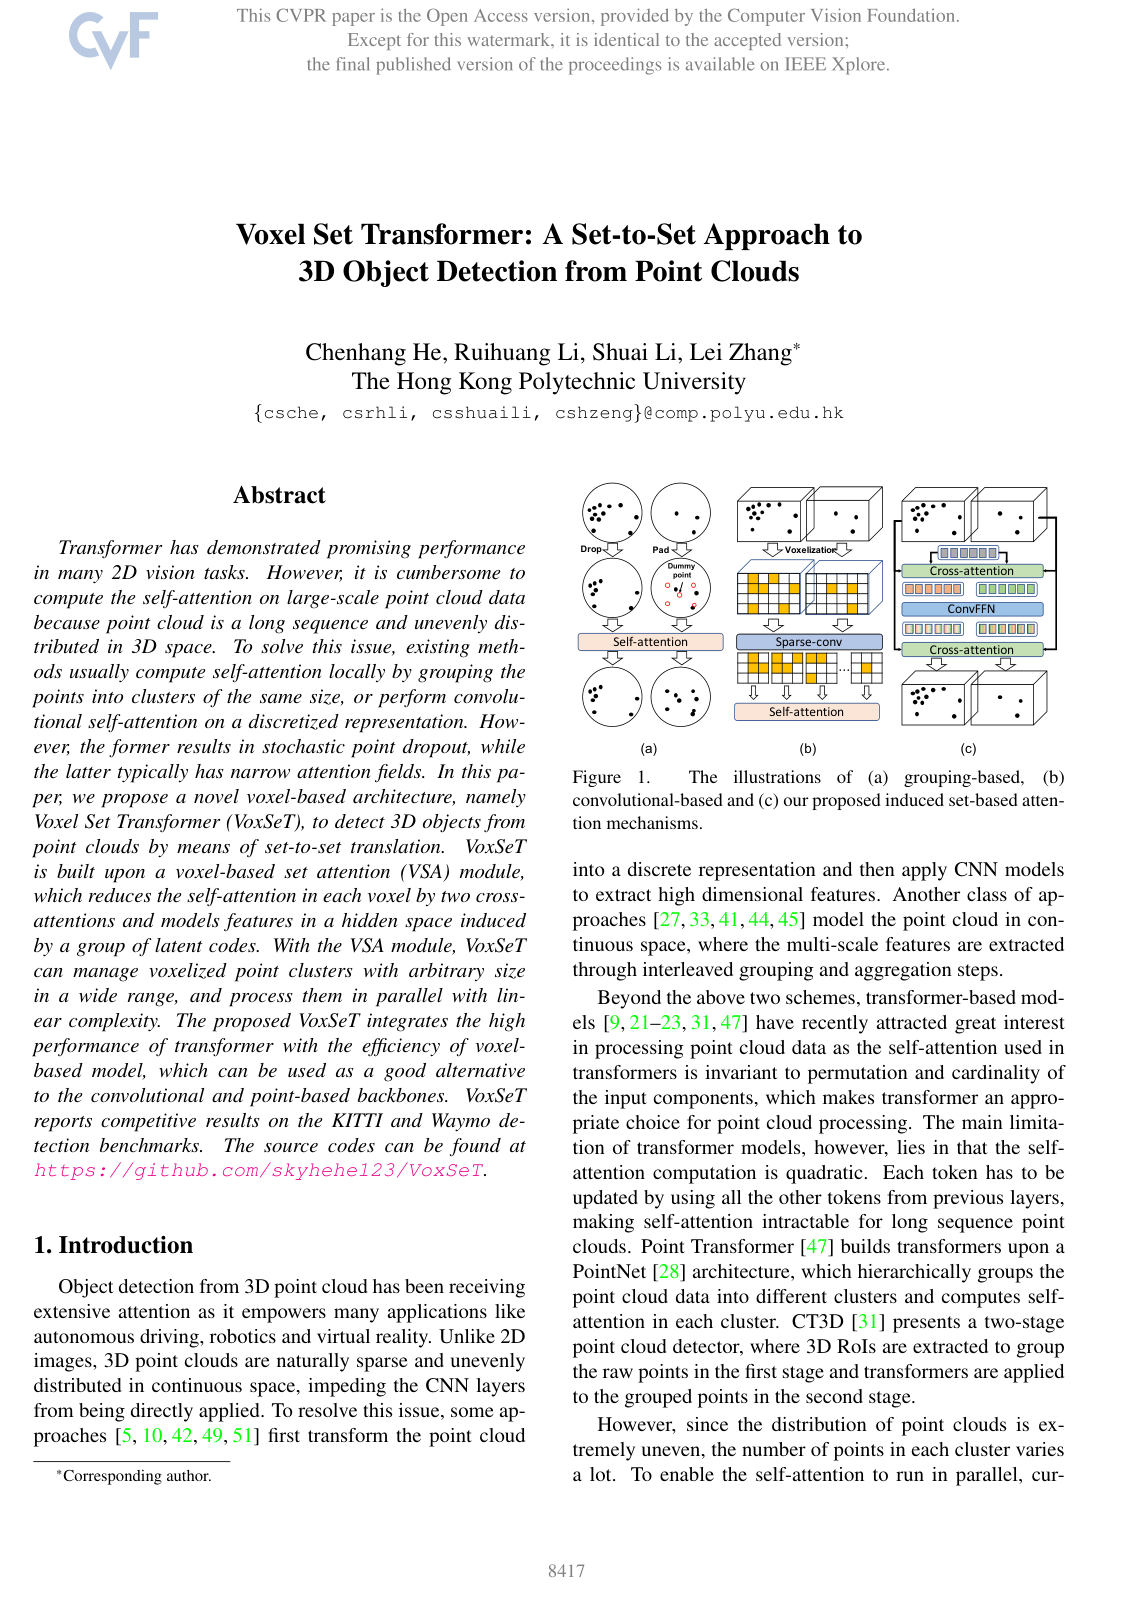
Voxel-based set attention is a deep learning mechanism used in 3D computer vision to efficiently extract geometric features from point clouds partitioned into discrete spatial voxel grids. Rather than calculating full pairwise self-attention among points in each voxel, which scales quadratically with point density, the mechanism decomposes intra-voxel self-attention into two successive cross-attention operations mediated by a set of learnable latent codes. This latent-space formulation allows the network to process point clusters of arbitrary size in parallel with linear computational complexity relative to point count, while preserving permutation invariance and avoiding point dropout. By integrating voxel-based spatial partitioning with set-to-set attention, it effectively captures local 3D geometric interactions while maintaining computational scalability.