Built independently by an author, for readers. Read the story and support ChapterPal

keyword

video object detection

Video object detection is a computer vision task that involves identifying, classifying, and spatially locating target objects across the sequential frames of a video. Unlike static image object detection, which analyzes individual images in isolation, video object detection leverages temporal information and motion continuity between neighboring frames to improve accuracy and consistency. By utilizing this temporal context, models can overcome video-specific challenges such as motion blur, temporary occlusions, defocus, and rapid viewpoint changes, enabling robust bounding box prediction and category classification throughout an entire video sequence.

1 item

Multiscale Vision Transformers

Multiscale Vision Transformers

Haoqi Fan, Bo Xiong, Karttikeya Mangalam, Yanghao Li, Zhicheng Yan, Jitendra Malik, Christoph Feichtenhofer

OrganizationsMetaUniversity of California Berkeley

Why you should read this

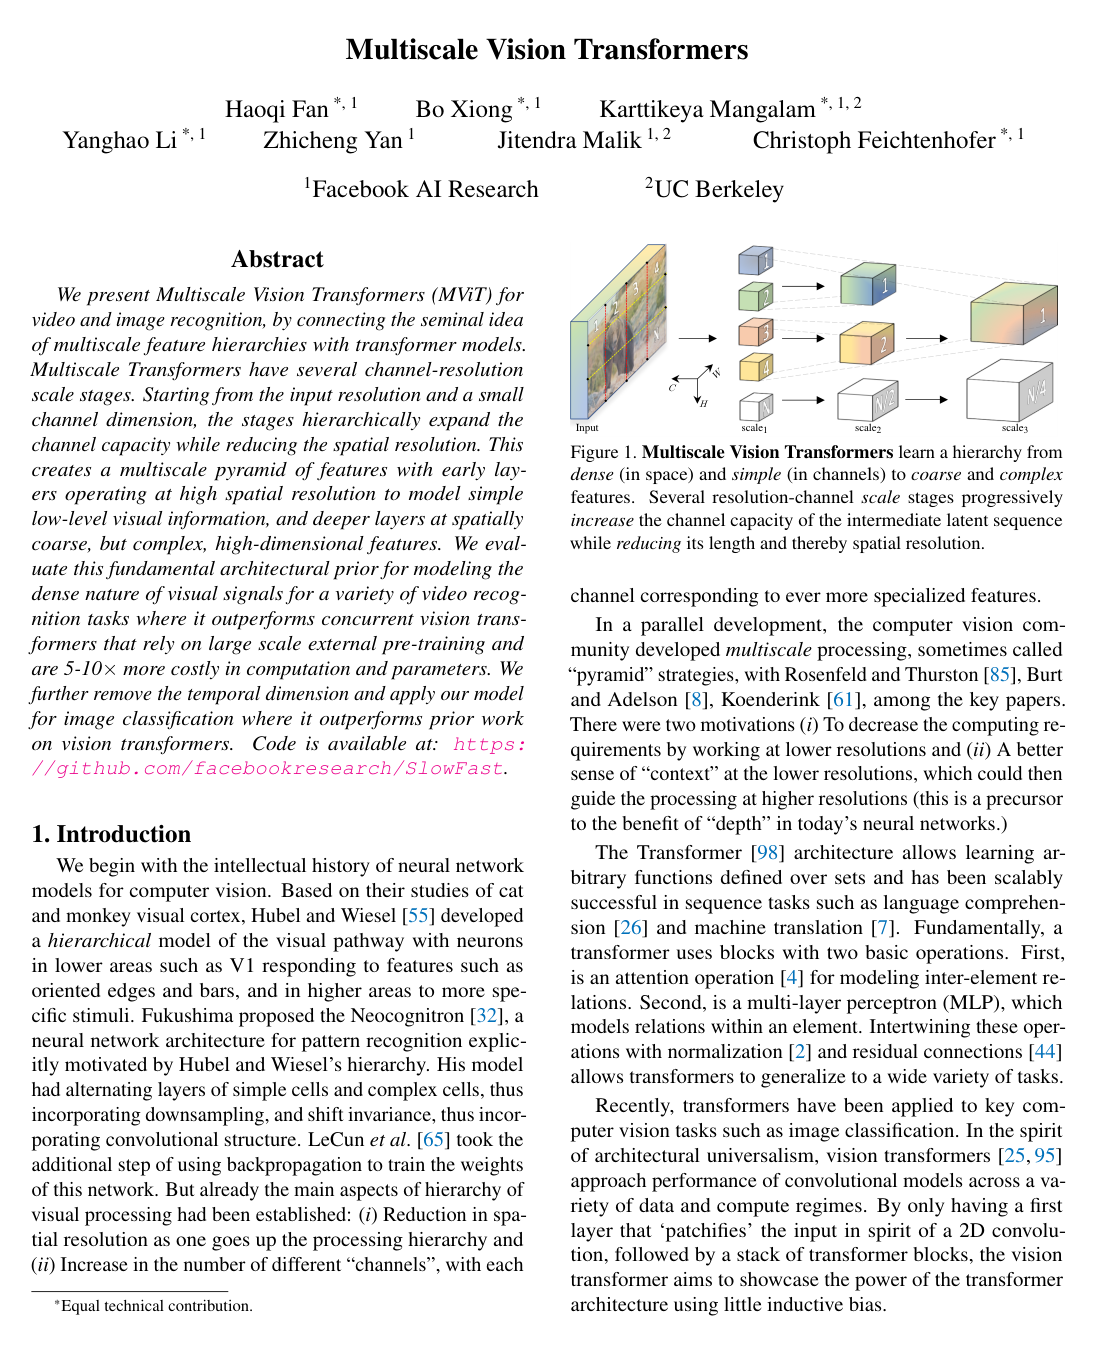
Develops Multiscale Vision Transformers, a hierarchical architecture that incorporates multiscale feature pyramids into visual attention to achieve superior video and image recognition performance with up to ten times less computation and without requiring massive external pre-training.

We present Multiscale Vision Transformers (MViT) for video and image recognition, by connecting the seminal idea of multiscale feature hierarchies with transformer models. Multiscale Transformers have several channel-resolution scale stages. Starting from the input resolution and a small channel dimension, the stages hierarchically expand the channel capacity while reducing the spatial resolution. This creates a multiscale pyramid of features with early layers operating at high spatial resolution to model simple low-level visual information, and deeper layers at spatially coarse, but complex, high-dimensional features. We evaluate this fundamental architectural prior for modeling the dense nature of visual signals for a variety of video recognition tasks where it outperforms concurrent vision transformers that rely on large scale external pre-training and are 5-10x more costly in computation and parameters. We further remove the temporal dimension and apply our model for image classification where it outperforms prior work on vision transformers. Code is available at: this https URL

Added

2026-09-24