Built independently by an author, for readers. Read the story and support ChapterPal

keyword

UniBind

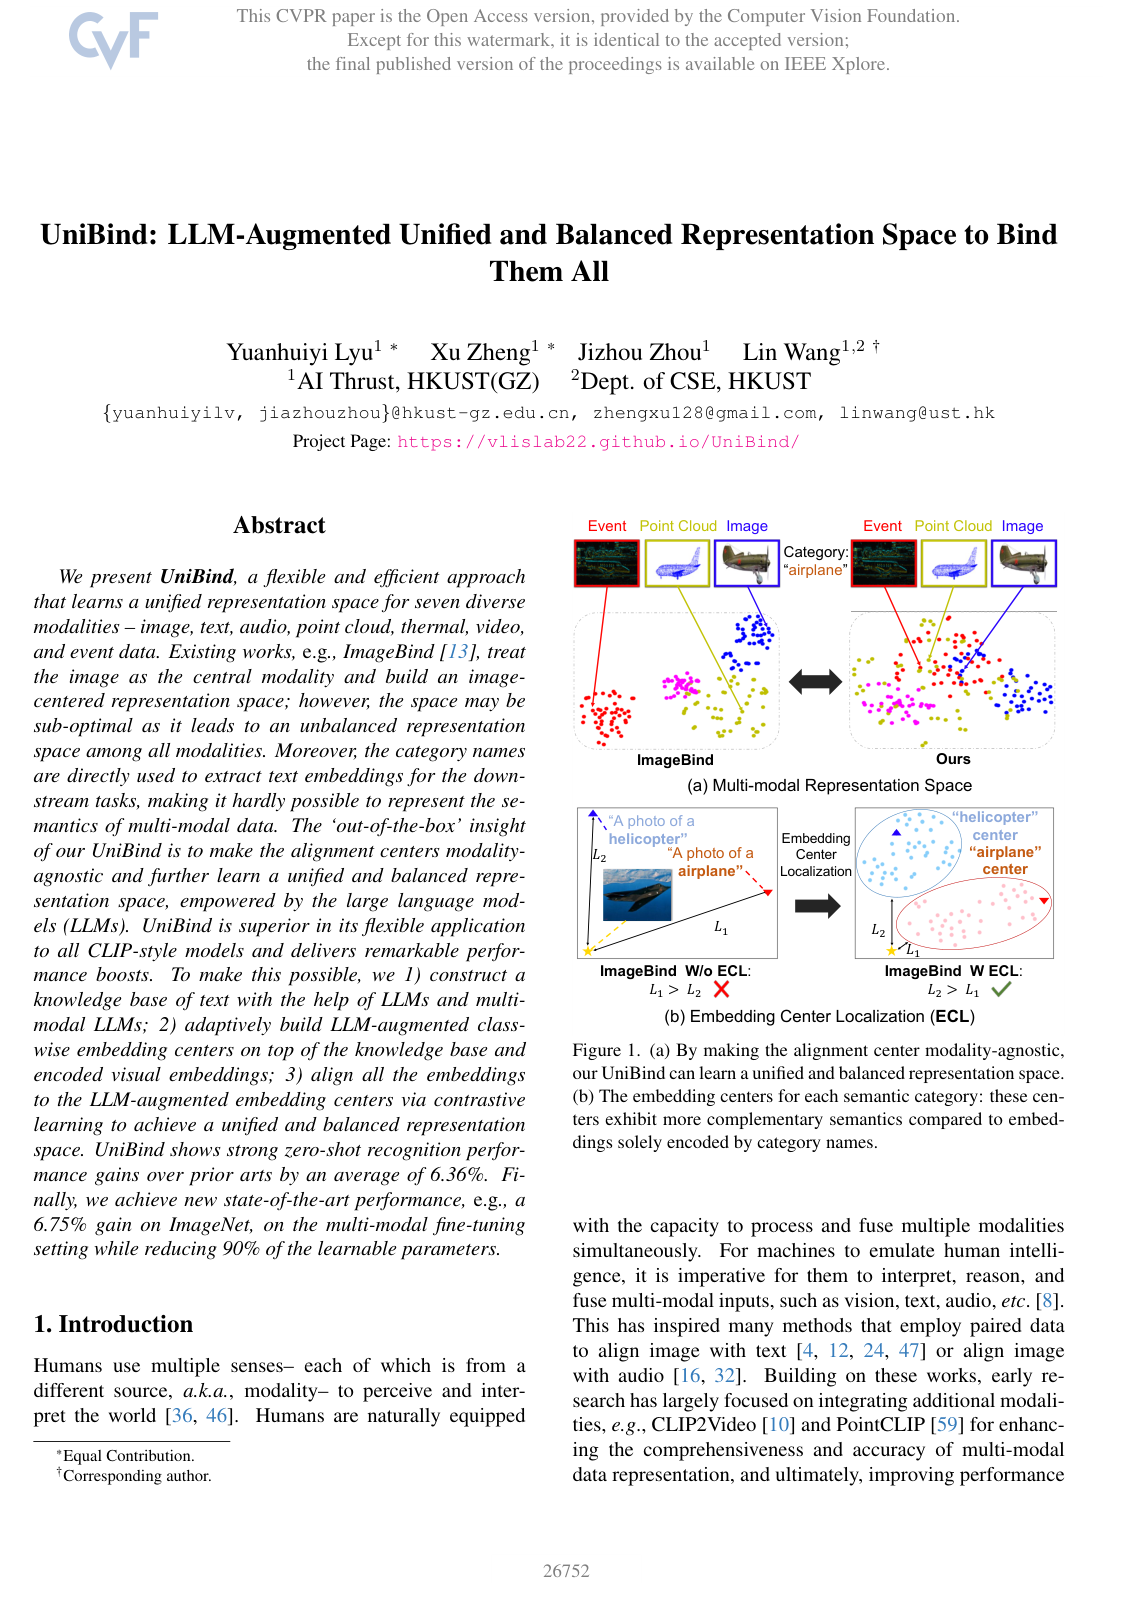
UniBind is a multimodal machine learning framework designed to create a unified and balanced embedding space across diverse data modalities, including text, images, audio, video, point clouds, thermal imaging, and event-based sensor data. Instead of anchoring representations around a single central medium such as images, UniBind uses large language models and multimodal knowledge bases to construct modality-agnostic, semantically enriched class centers. By aligning feature embeddings from disparate sensory inputs to these shared semantic targets through contrastive learning, the approach enables balanced cross-modal alignment, enhances zero-shot recognition capabilities, and supports parameter-efficient multimodal fine-tuning.

1 item

UniBind: LLM-Augmented Unified and Balanced Representation Space to Bind Them All

UniBind: LLM-Augmented Unified and Balanced Representation Space to Bind Them All

Yuanhuiyi Lyu, Xu Zheng, Jiazhou Zhou, Lin Wang

OrganizationsThe Hong Kong University of Science and Technology

Why you should read this

Presents UniBind, a framework that uses large language models and multi-modal LLMs to construct modality-agnostic text embedding centers, overcoming single-modality bias to unify seven distinct sensory modalities while reducing learnable fine-tuning parameters by 90%.

We present UniBind, a flexible and efficient approach that learns a unified representation space for seven diverse modalities – image, text, audio, point cloud, thermal, video, and event data. Existing works, e.g., ImageBind [13], treat the image as the central modality and build an image-centered representation space; however, the space may be sub-optimal as it leads to an unbalanced representation space among all modalities. Moreover, the category names are directly used to extract text embeddings for the downstream tasks, making it hardly possible to represent the semantics of multi-modal data. The ‘out-of-the-box’ insight of our UniBind is to make the alignment centers modality-agnostic and further learn a unified and balanced representation space, empowered by the large language models (LLMs). UniBind is superior in its flexible application to all CLIP-style models and delivers remarkable performance boosts. To make this possible, we 1) construct a knowledge base of text with the help of LLMs and multi-modal LLMs; 2) adaptively build LLM-augmented class-wise embedding centers on top of the knowledge base and encoded visual embeddings; 3) align all the embeddings to the LLM-augmented embedding centers via contrastive learning to achieve a unified and balanced representation space. UniBind shows strong zero-shot recognition performance gains over prior arts by an average of 6.36%. Finally, we achieve new state-of-the-art performance, e.g., a 6.75% gain on ImageNet, on the multi-modal fine-tuning setting while reducing 90% of the learnable parameters.

Added

2026-09-26