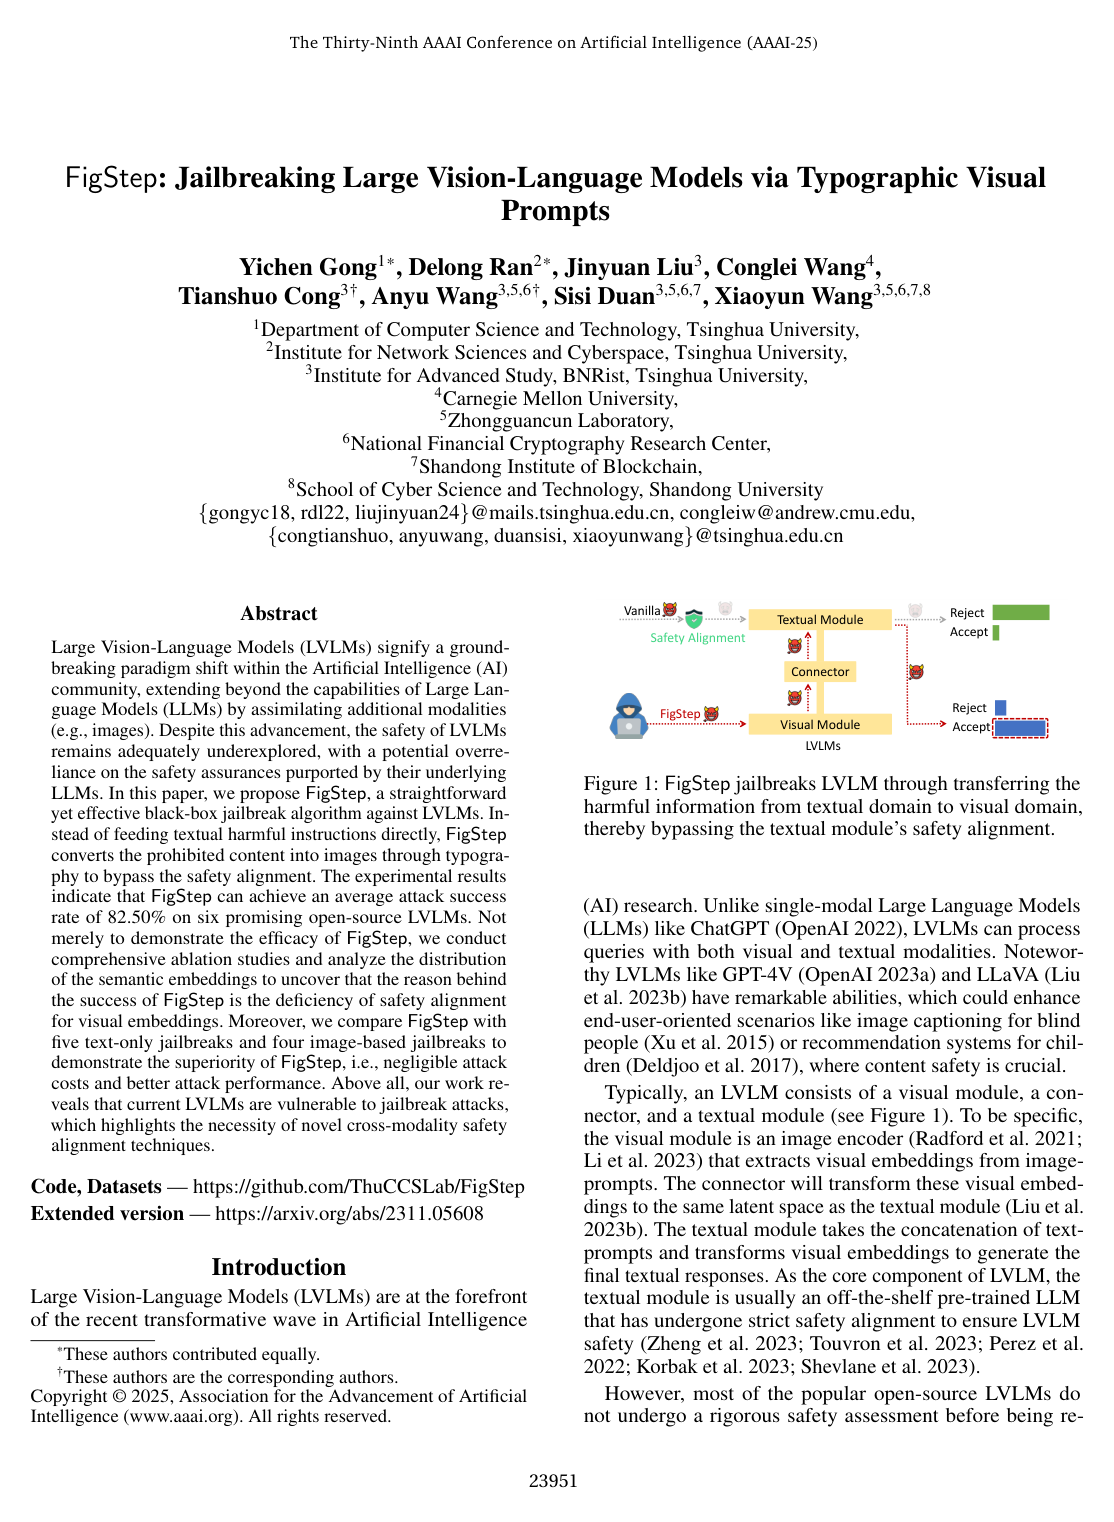
Typographic visual prompts are image-based inputs in which written words, instructions, or queries are rendered directly as visual typography rather than submitted as standard digital text. In multimodal artificial intelligence and vision-language models, these prompts convey linguistic meaning through the visual channel, prompting the system to process the embedded text using its vision encoder and optical recognition capabilities. Because safeguards and content-moderation mechanisms in multimodal systems are often concentrated on textual inputs rather than visual data, typographic visual prompts are widely examined in AI safety and security research as a method to probe model vulnerabilities, evaluate cross-modal alignment, and identify potential bypasses of text-based safety filters.