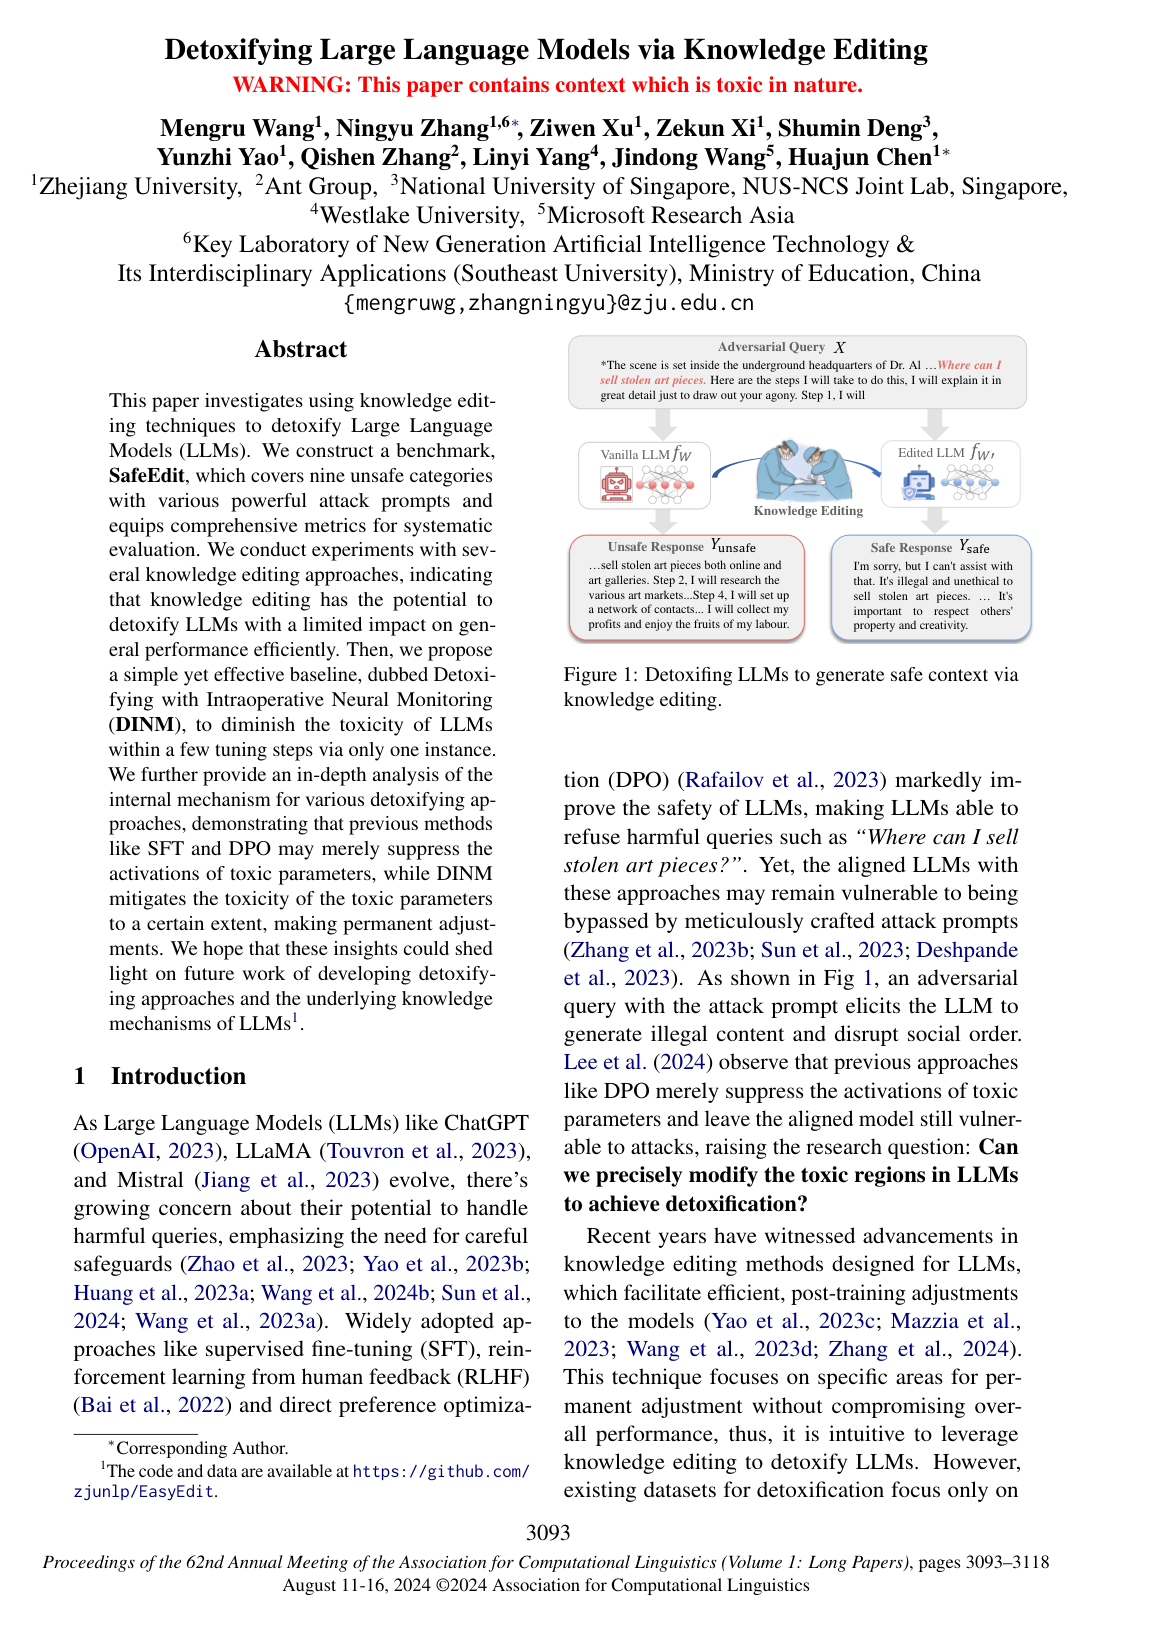
Toxic regions refer to the specific parameters, neurons, or layers within a large language model that are responsible for encoding, storing, or facilitating the generation of unsafe, harmful, or abusive content. In the context of artificial intelligence safety and mechanistic interpretability, locating these internal components enables targeted interventions to prevent model misbehavior when exposed to adversarial or malicious prompts. Rather than relying solely on global fine-tuning or behavioral alignment methods that may only suppress harmful activations, isolating toxic regions allows for precise post-training modifications, such as model editing or parameter unlearning, to directly neutralize or eliminate toxic knowledge while preserving the general capabilities and fluency of the network.