keyword
TextVQA dataset
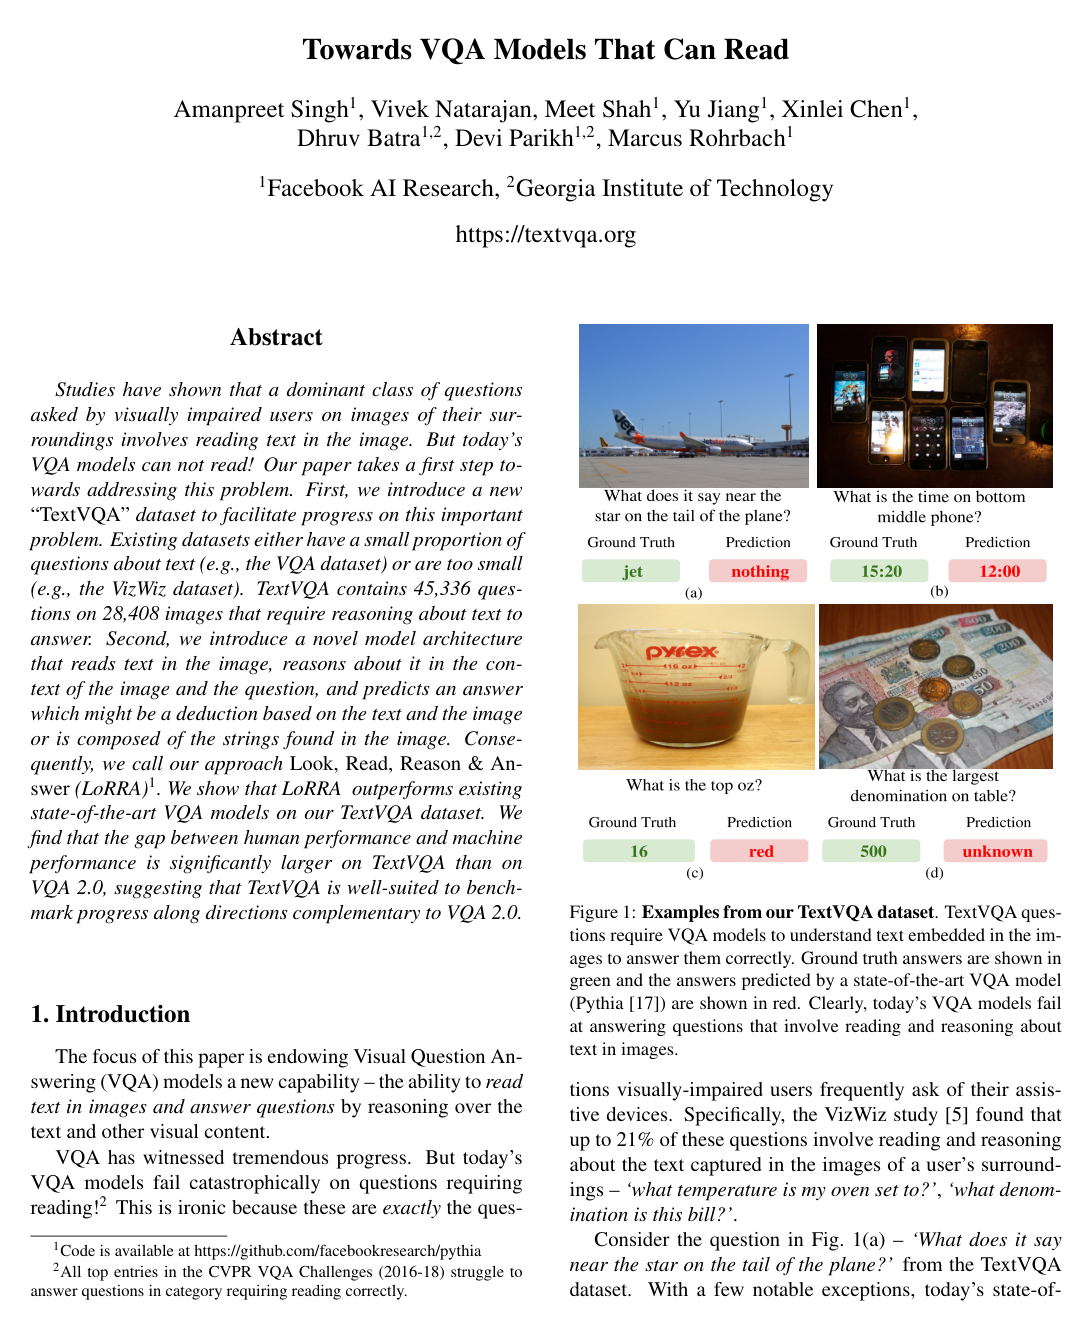
The TextVQA dataset is a benchmark dataset designed for visual question answering that requires artificial intelligence models to read and reason about text present within images. Consisting of tens of thousands of natural language questions paired with natural scene images, the dataset challenges models to detect visual text, interpret it in the context of the surrounding image and question, and produce answers derived directly from the scene text or through visual reasoning. By emphasizing text-centric questions, it addresses scenarios where conventional computer vision systems fail to process embedded linguistic information, serving as a standard resource for training and evaluating multimodal architectures that integrate computer vision, natural language processing, and optical character recognition.
1 item