
keyword
text simplification
Text simplification is a natural language processing task that involves modifying, rewriting, and restructuring complex text to make it easier to read and understand while preserving its original meaning and factual content. This process typically encompasses lexical simplification, which replaces obscure or technical vocabulary with more common synonyms, and syntactic simplification, which shortens lengthy sentences, reduces complex grammatical structures, and removes nonessential information. By lowering linguistic barriers, text simplification helps make dense or specialized materials accessible to broader audiences, including language learners, children, and individuals with reading or cognitive difficulties.
2 items
EditEval: An Instruction-Based Benchmark for Text Improvements
Jane Dwivedi-Yu, Timo Schick, Zhengbao Jiang, Maria Lomeli, Patrick Lewis, Gautier Izacard, Edouard Grave, Sebastian Riedel, Fabio Petroni
Why you should read this
Introduces EditEval, an instruction-based benchmark to assess how language models perform modular text-editing tasks like factual updates and tone neutralization, exposing critical performance gaps and metric inconsistencies in iterative text revision.
Evaluation of text generation to date has primarily focused on content created sequentially, rather than improvements on a piece of text. Writing, however, is naturally an iterative and incremental process that requires expertise in different modular skills such as fixing outdated information or making the style more consistent. Even so, comprehensive evaluation of a model's capacity to perform these skills and the ability to edit remains sparse. This work presents EditEval: An instruction-based, benchmark and evaluation suite that leverages high-quality existing and new datasets for automatic evaluation of editing capabilities such as making text more cohesive and paraphrasing. We evaluate several pre-trained models, which shows that InstructGPT and PEER perform the best, but that most baselines fall below the supervised SOTA, particularly when neutralizing and updating information. Our analysis also shows that commonly used metrics for editing tasks do not always correlate well, and that optimization for prompts with the highest performance does not necessarily entail the strongest robustness to different models. Through the release of this benchmark and a publicly available leaderboard challenge, we hope to unlock future research in developing models capable of iterative and more controllable editing.
Added
2026-10-05

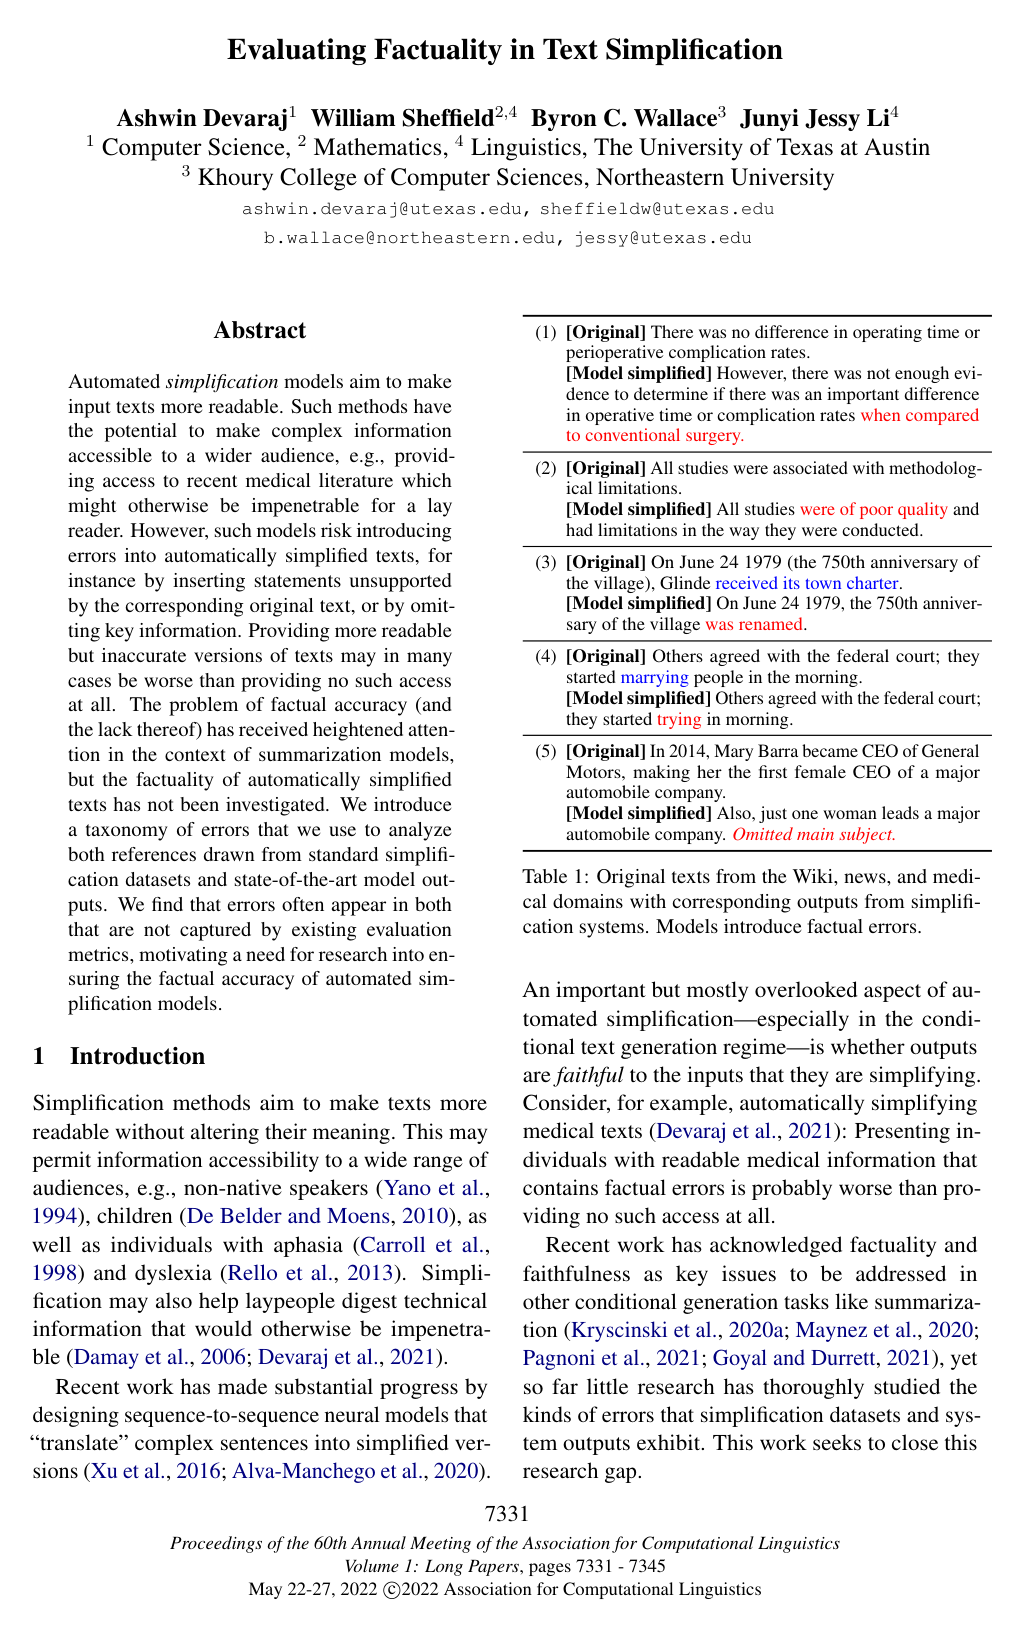
Evaluating Factuality in Text Simplification
Ashwin Devaraj, William Sheffield, Byron C. Wallace, Junyi Jessy Li
Why you should read this
Presents a taxonomy of factual errors in text simplification, revealing that standard evaluation metrics fail to detect frequent information insertions, deletions, and substitutions in both benchmark datasets and model outputs.
Automated simplification models aim to make input texts more readable. Such methods have the potential to make complex information accessible to a wider audience, e.g., providing access to recent medical literature which might otherwise be impenetrable for a lay reader. However, such models risk introducing errors into automatically simplified texts, for instance by inserting statements unsupported by the corresponding original text, or by omitting key information. Providing more readable but inaccurate versions of texts may in many cases be worse than providing no such access at all. The problem of factual accuracy (and the lack thereof) has received heightened attention in the context of summarization models, but the factuality of automatically simplified texts has not been investigated. We introduce a taxonomy of errors that we use to analyze both references drawn from standard simplification datasets and state-of-the-art model outputs. We find that errors often appear in both that are not captured by existing evaluation metrics, motivating a need for research into ensuring the factual accuracy of automated simplification models.
Added
2026-10-03