
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

text-driven video generation

Text-driven video generation is an artificial intelligence task that automatically synthesizes coherent video sequences from natural language text descriptions. Building upon text-to-image synthesis principles, this process interprets input prompts detailing specific subjects, environments, motions, and temporal events to generate dynamic visual content. The underlying generative models, such as diffusion frameworks and transformer architectures, are trained on paired text and video data to ensure both spatial visual fidelity within individual frames and temporal consistency across the entire video. By mapping descriptive static and dynamic attributes to corresponding visual elements and motion trajectories, text-driven video generation enables automated media production, video editing, and digital content creation directly from written instructions.

1 item
CelebV-Text: A Large-Scale Facial Text-Video Dataset

CelebV-Text: A Large-Scale Facial Text-Video Dataset

Jianhui Yu, Hao Zhu, Liming Jiang, Chen Change Loy, Weidong Cai, Wayne Wu

Why you should read this

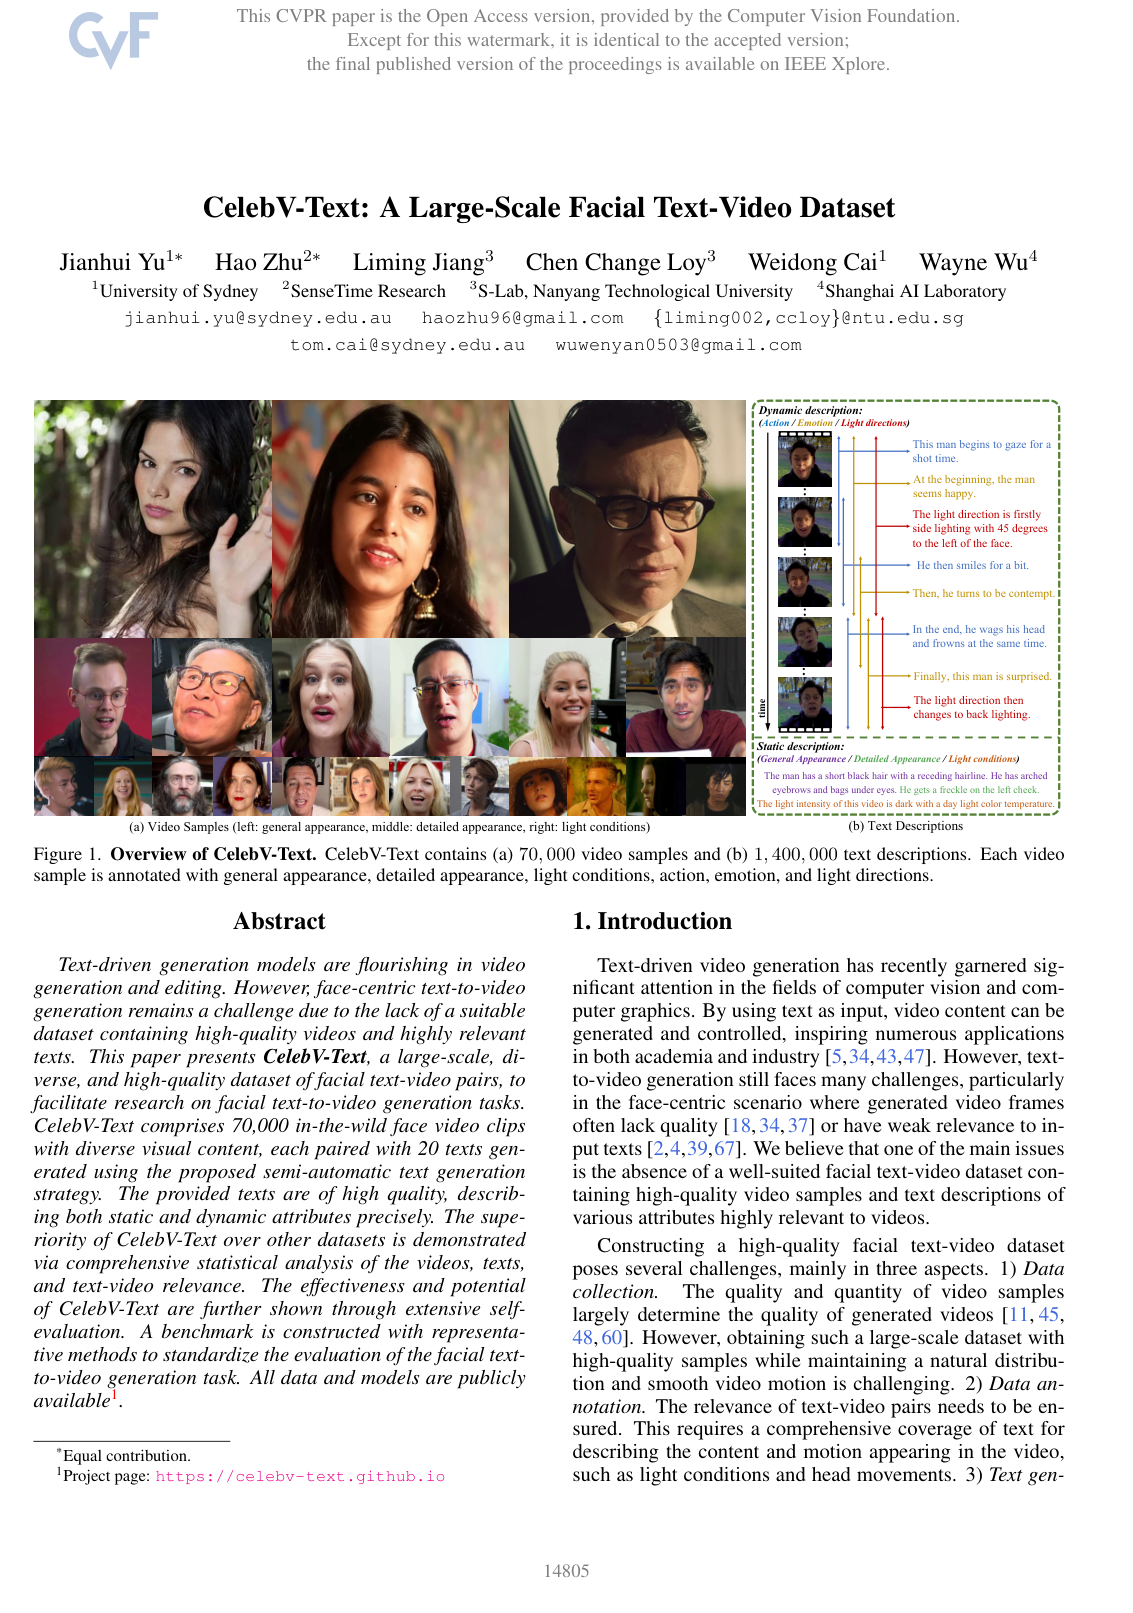
Presents a large-scale dataset of 70,000 in-the-wild facial video clips paired with 1.4 million detailed static and dynamic text descriptions to advance and standardize face-centric text-to-video generation.

Text-driven generation models are flourishing in video generation and editing. However, face-centric text-to-video generation remains a challenge due to the lack of a suitable dataset containing high-quality videos and highly relevant texts. This paper presents CelebV-Text, a large-scale, diverse, and high-quality dataset of facial text-video pairs, to facilitate research on facial text-to-video generation tasks. CelebV-Text comprises 70,000 in-the-wild face video clips with diverse visual content, each paired with 20 texts generated using the proposed semi-automatic text generation strategy. The provided texts are of high quality, describing both static and dynamic attributes precisely. The superiority of CelebV-Text over other datasets is demonstrated via comprehensive statistical analysis of the videos, texts, and text-video relevance. The effectiveness and potential of CelebV-Text are further shown through extensive self-evaluation. A benchmark is constructed with representative methods to standardize the evaluation of the facial text-to-video generation task. All data and models are publicly available^1.

Added

2026-09-26