keyword
StreamingT2V
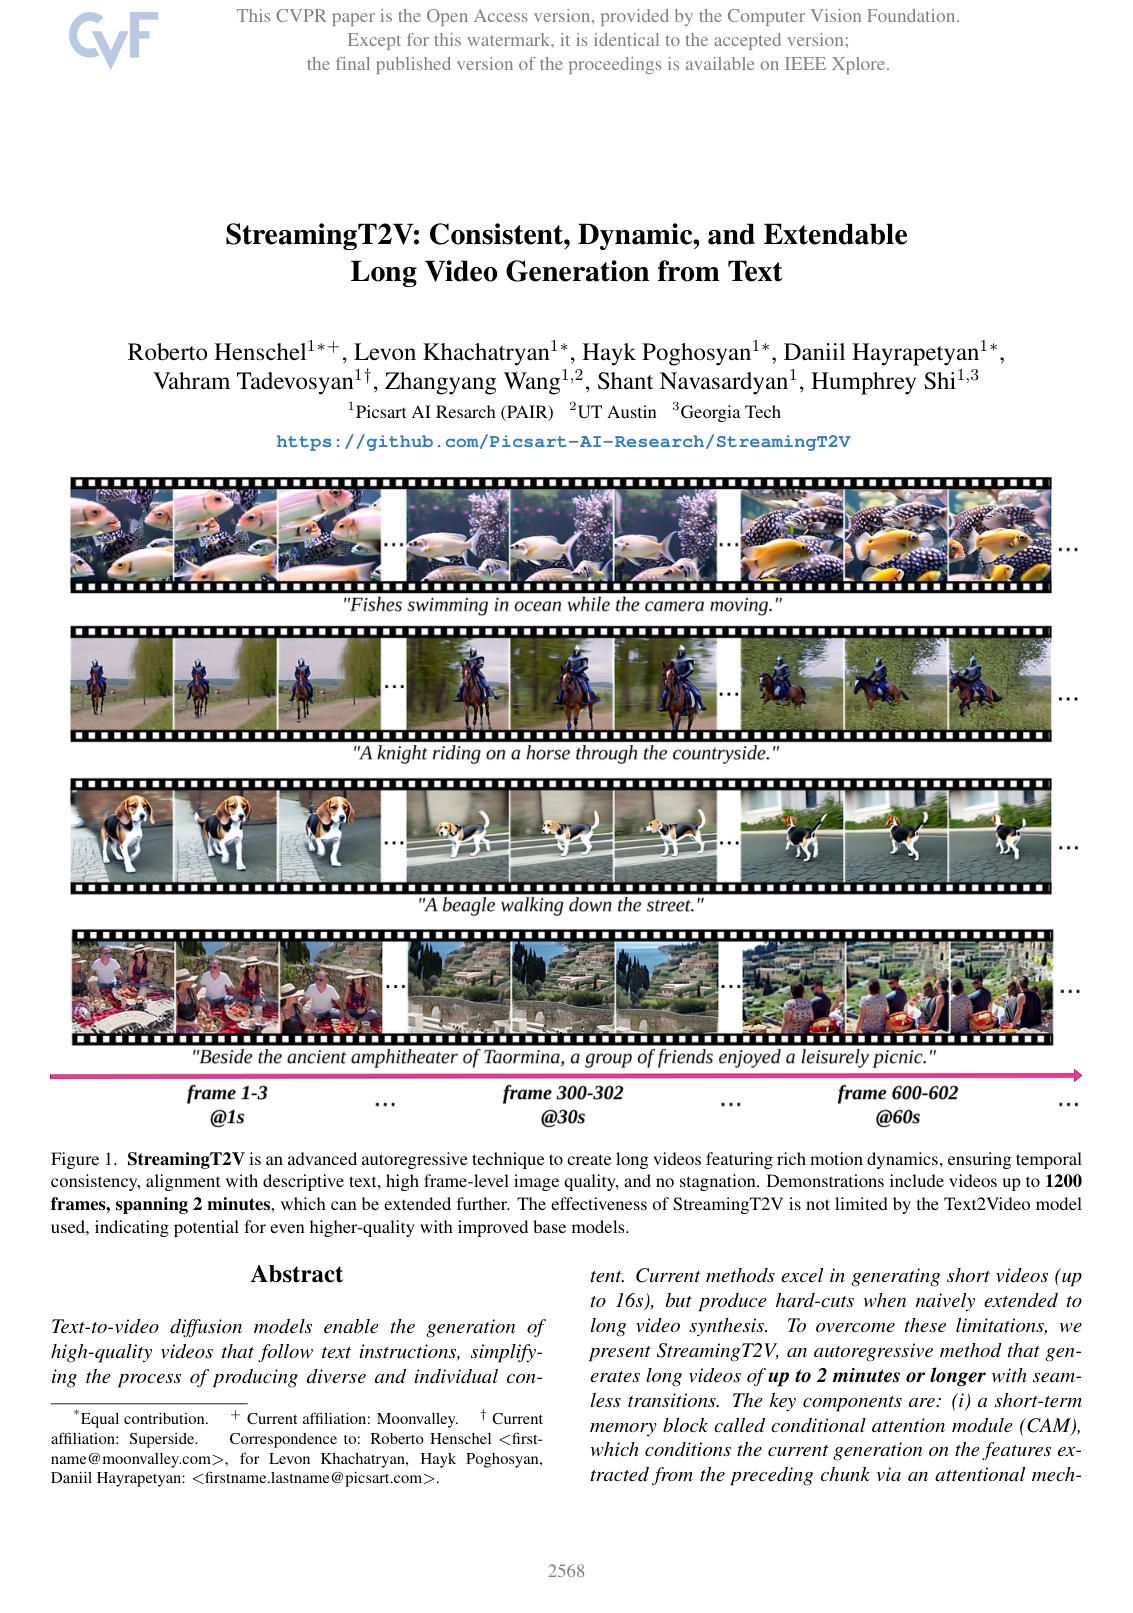
StreamingT2V is an autoregressive framework for text-to-video generation designed to synthesize extended, high-quality videos from natural language descriptions while preserving motion dynamics and temporal consistency. While conventional text-to-video diffusion models are typically limited to short clips and often produce abrupt cuts or visual stagnation when extended, StreamingT2V generates videos sequentially chunk by chunk. By incorporating memory mechanisms that condition each newly generated segment on visual features from preceding frames, it facilitates seamless transitions and continuous motion across long video sequences without drifting from the original text prompt.
1 item