
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

spatial context model

A spatial context model is a mechanism in learned data and image compression that estimates the probability distribution of a target symbol or latent feature based on the values of its neighboring elements across spatial dimensions. By analyzing adjacent positions along the height and width of a feature representation, the model captures local statistical correlations and spatial redundancies that persist after initial feature transforms. These models typically employ autoregressive structures, masked convolutions, or multi-pass schemes such as checkerboard patterns to ensure that conditional predictions rely strictly on previously reconstructed spatial neighbors. By supplying these refined conditional probability distributions to an entropy coder, a spatial context model minimizes the required bit rate and significantly improves overall rate-distortion performance.

1 item
ELIC: Efficient Learned Image Compression with Unevenly Grouped Space-Channel Contextual Adaptive Coding

ELIC: Efficient Learned Image Compression with Unevenly Grouped Space-Channel Contextual Adaptive Coding

Dailan He, Ziming Yang, Weikun Peng, Rui Ma, Hongwei Qin, Yan Wang

OrganizationsSenseTimeTsinghua University

Why you should read this

Presents ELIC, a learned image compression architecture that combines uneven space-channel contextual coding with efficient transform design to achieve state-of-the-art rate-distortion performance alongside fast inference, preview decoding, and progressive decoding.

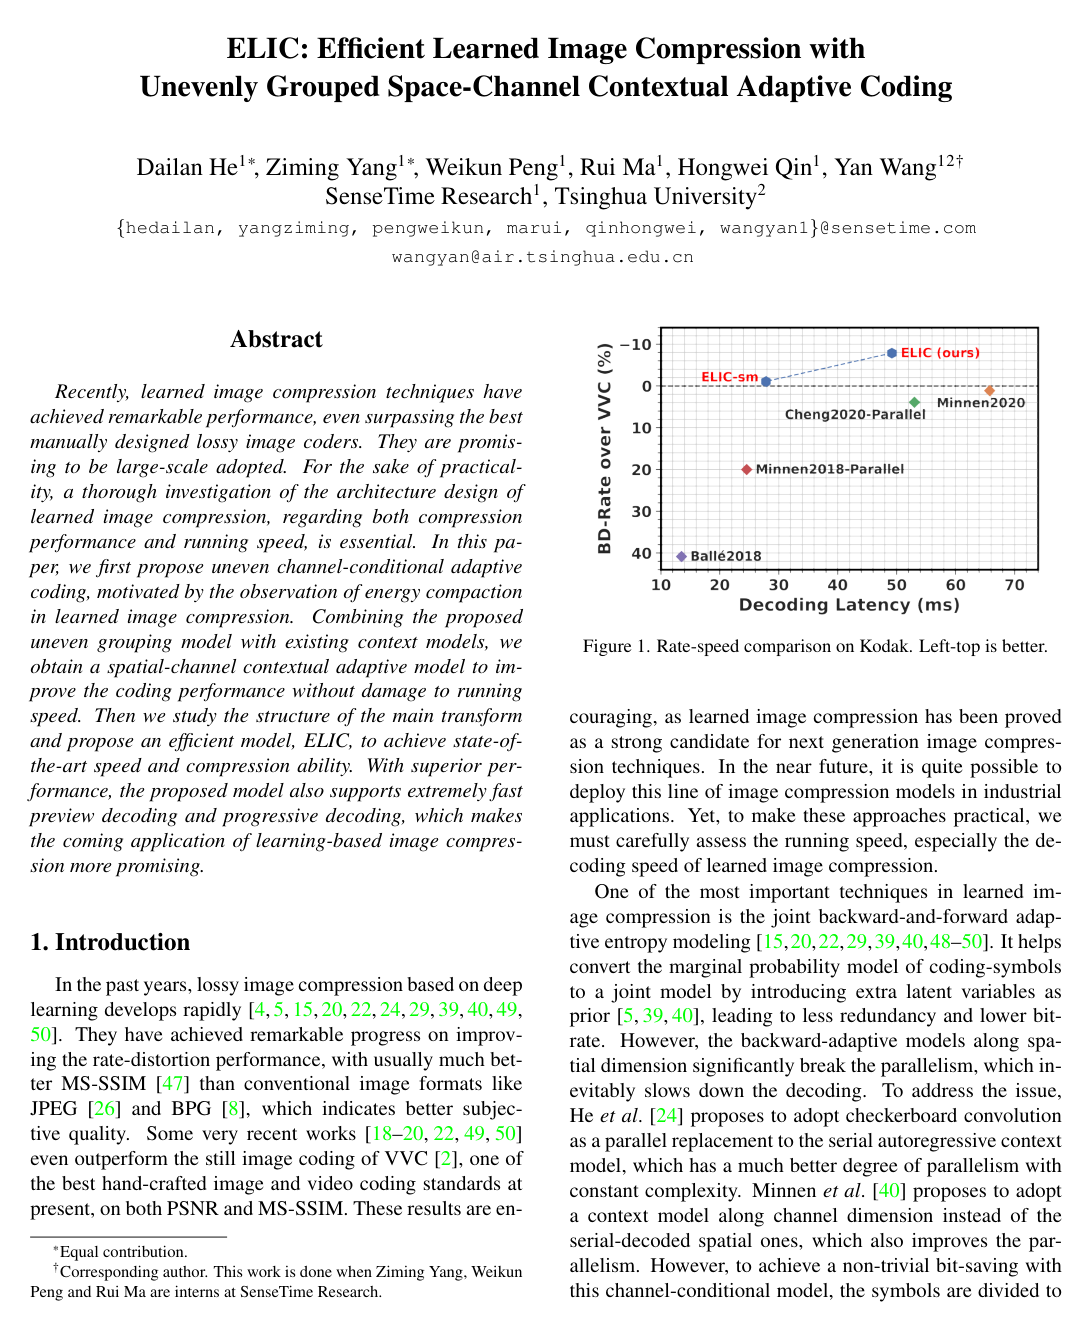
Recently, learned image compression techniques have achieved remarkable performance, even surpassing the best manually designed lossy image coders. They are promising to be large-scale adopted. For the sake of practicality, a thorough investigation of the architecture design of learned image compression, regarding both compression performance and running speed, is essential. In this paper, we first propose uneven channel-conditional adaptive coding, motivated by the observation of energy compaction in learned image compression. Combining the proposed uneven grouping model with existing context models, we obtain a spatial-channel contextual adaptive model to improve the coding performance without damage to running speed. Then we study the structure of the main transform and propose an efficient model, ELIC, to achieve state-of-the-art speed and compression ability. With superior performance, the proposed model also supports extremely fast preview decoding and progressive decoding, which makes the coming application of learning-based image compression more promising.

Added

2026-09-26