Built independently by an author, for readers. Read the story and support ChapterPal

keyword

sparse CNN

A sparse convolutional neural network is a specialized deep learning architecture designed to process spatially sparse data, such as 3D point clouds and discretized voxel representations, where the vast majority of grid coordinates are empty. Unlike conventional convolutional networks that compute features across an entire dense grid, sparse convolutional networks store data using coordinate indices or hash tables and restrict mathematical operations solely to active, non-empty locations. By employing specialized operations such as submanifold sparse convolutions to prevent feature dilation into empty regions across successive layers, these networks significantly reduce memory consumption and computational complexity, enabling efficient and scalable processing of high-resolution geometric data for spatial recognition and 3D perception tasks.

1 item

Voxel Set Transformer: A Set-to-Set Approach to 3D Object Detection from Point Clouds

Voxel Set Transformer: A Set-to-Set Approach to 3D Object Detection from Point Clouds

Chenhang He, Ruihuang Li, Shuai Li, Lei Zhang

Why you should read this

Proposes Voxel Set Transformer, a linear-complexity backbone that processes arbitrary-sized 3D point clusters in parallel through latent-code induced cross-attentions to achieve efficient and competitive 3D object detection on large-scale point clouds.

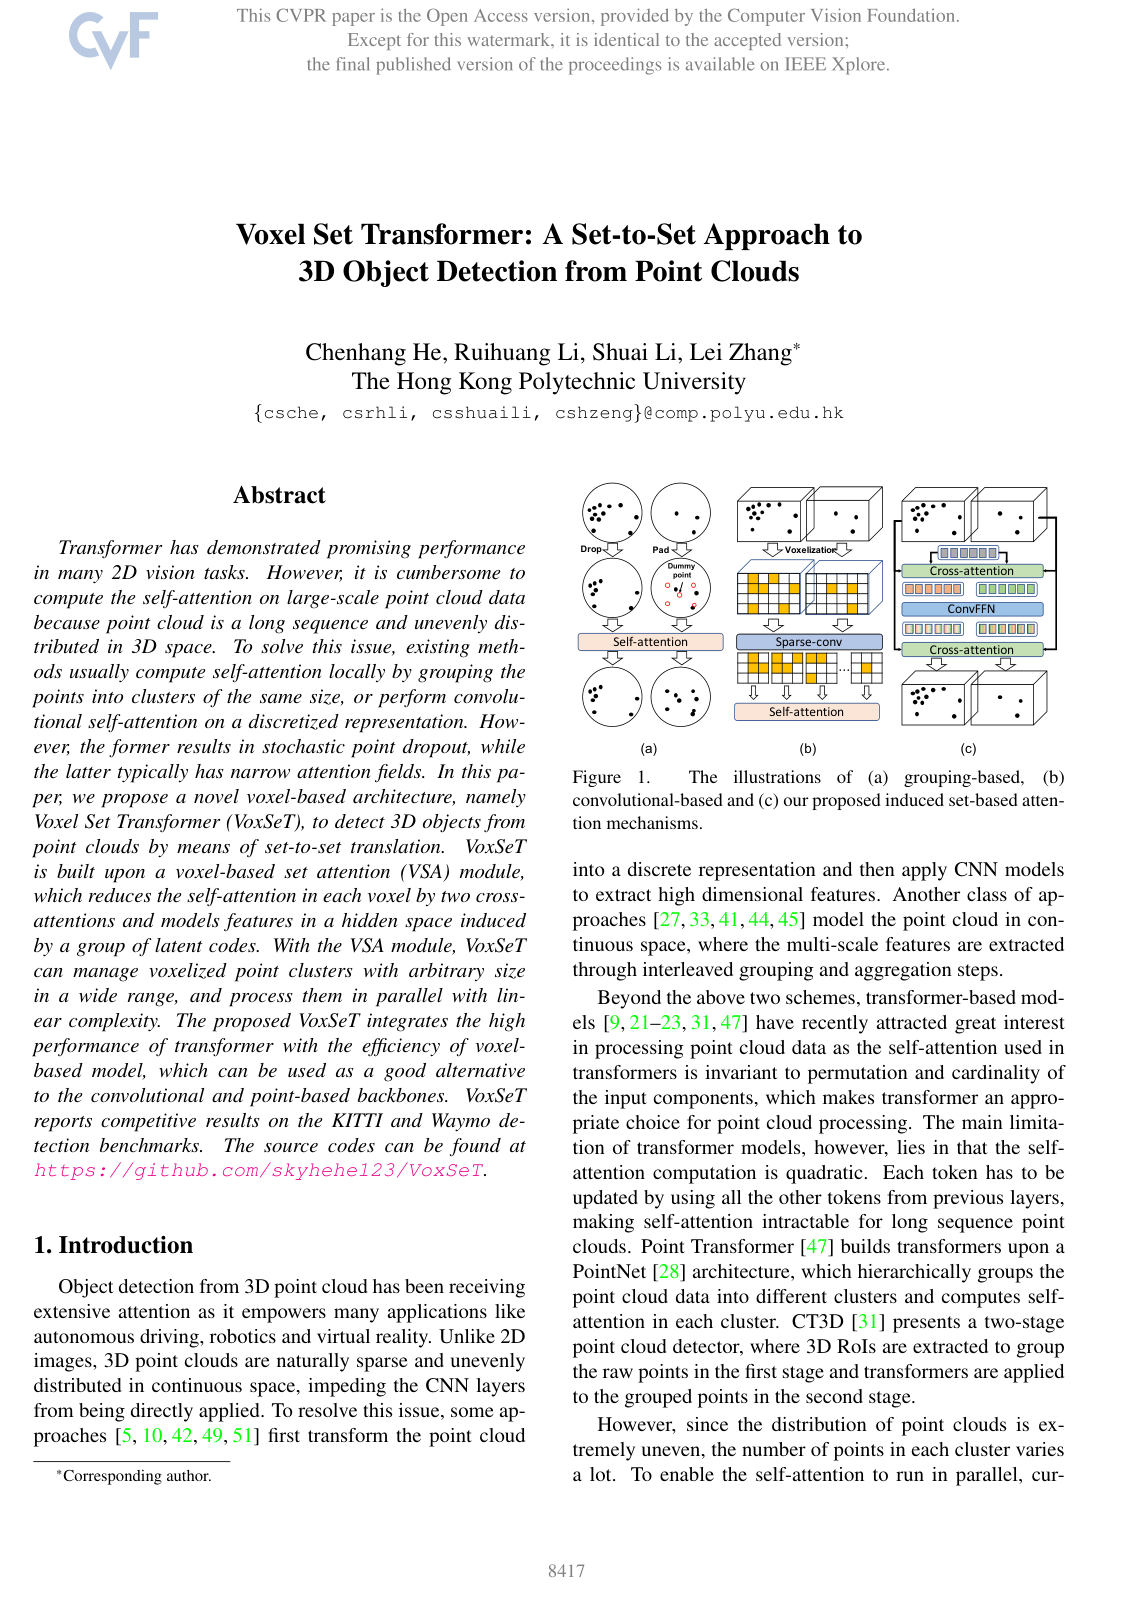
Transformer has demonstrated promising performance in many 2D vision tasks. However, it is cumbersome to compute the self-attention on large-scale point cloud data because point cloud is a long sequence and unevenly distributed in 3D space. To solve this issue, existing methods usually compute self-attention locally by grouping the points into clusters of the same size, or perform convolutional self-attention on a discretized representation. However, the former results in stochastic point dropout, while the latter typically has narrow attention fields. In this paper, we propose a novel voxel-based architecture, namely Voxel Set Transformer (VoxSeT), to detect 3D objects from point clouds by means of set-to-set translation. VoxSeT is built upon a voxel-based set attention (VSA) module, which reduces the self-attention in each voxel by two cross-attentions and models features in a hidden space induced by a group of latent codes. With the VSA module, VoxSeT can manage voxelized point clusters with arbitrary size in a wide range, and process them in parallel with linear complexity. The proposed VoxSeT integrates the high performance of transformer with the efficiency of voxel-based model, which can be used as a good alternative to the convolutional and point-based backbones. VoxSeT reports competitive results on the KITTI and Waymo detection benchmarks. The source codes can be found at https://github.com/skyhehe123/VoxSeT.

Added

2026-10-05