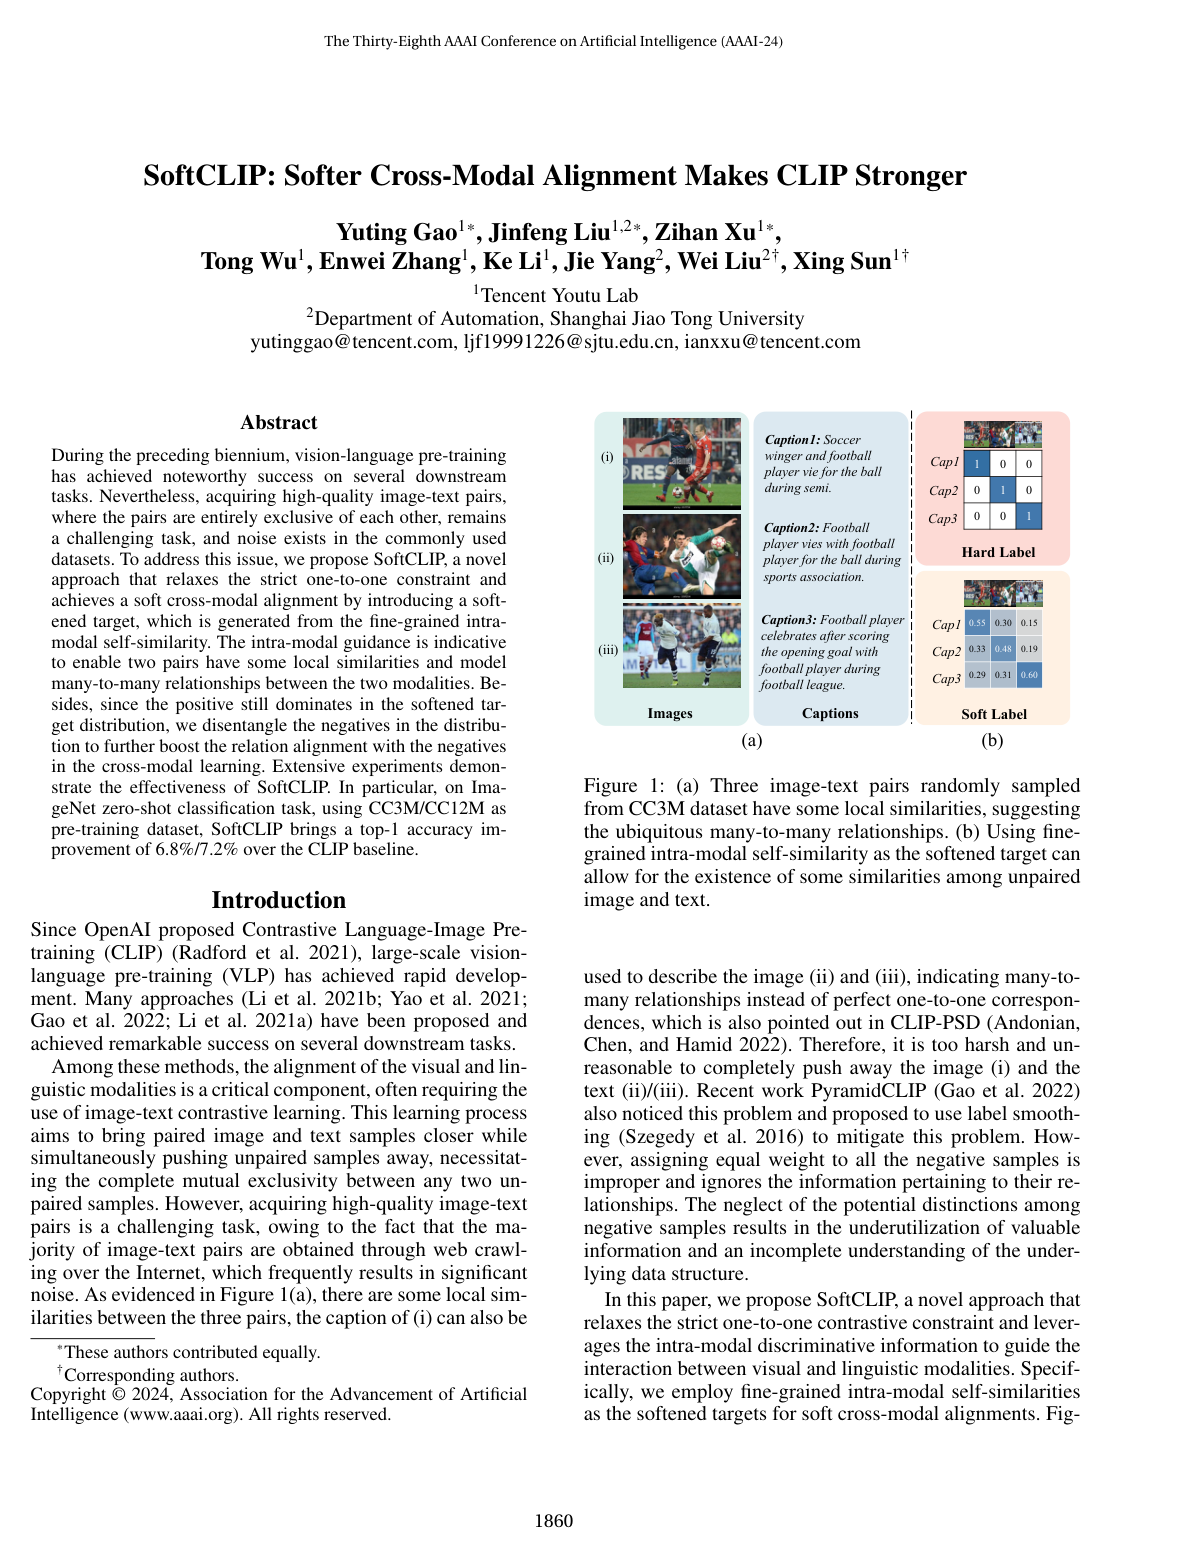
SoftCLIP is a vision-language pre-training framework that enhances contrastive learning by relaxing the strict one-to-one alignment typically enforced between paired image and text data. Unlike traditional contrastive models that treat all unpaired cross-modal instances as entirely negative, SoftCLIP models flexible many-to-many relationships across modalities by generating softened training targets derived from intra-modal self-similarity. This approach enables the model to effectively handle noise, partial semantic overlap, and ambiguous associations in web-scale datasets while refining cross-modal representations through the disentanglement of negative relationships within the target distribution.