
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

short-term temporal learning

Short-term temporal learning is a machine learning approach that focuses on capturing immediate motion dynamics, fine-grained transitions, and local dependencies across closely adjacent time steps or brief sequences, such as consecutive video frames. Typically implemented through mechanisms such as three-dimensional convolutional neural networks, optical flow modules, or localized temporal filters operating over compact time windows, this method extracts subtle spatial-temporal patterns and rapid physical changes. By modeling these immediate temporal correlations within short intervals, systems can generate detailed representations of localized actions and state transitions, which can serve on their own or provide the baseline features necessary for broader, long-term sequence modeling.

1 item
Rethinking the Learning Paradigm for Dynamic Facial Expression Recognition

Rethinking the Learning Paradigm for Dynamic Facial Expression Recognition

Hanyang Wang, Bo Li, Shuang Wu, Siyuan Shen, Feng Liu, Shouhong Ding, Aimin Zhou

OrganizationsEast China Normal UniversityTencent

Why you should read this

Proposes a multi-instance learning framework for dynamic facial expression recognition that treats non-target video frames as weakly supervised data and balances short- and long-term temporal dependencies to achieve state-of-the-art accuracy using a standard 3D CNN backbone.

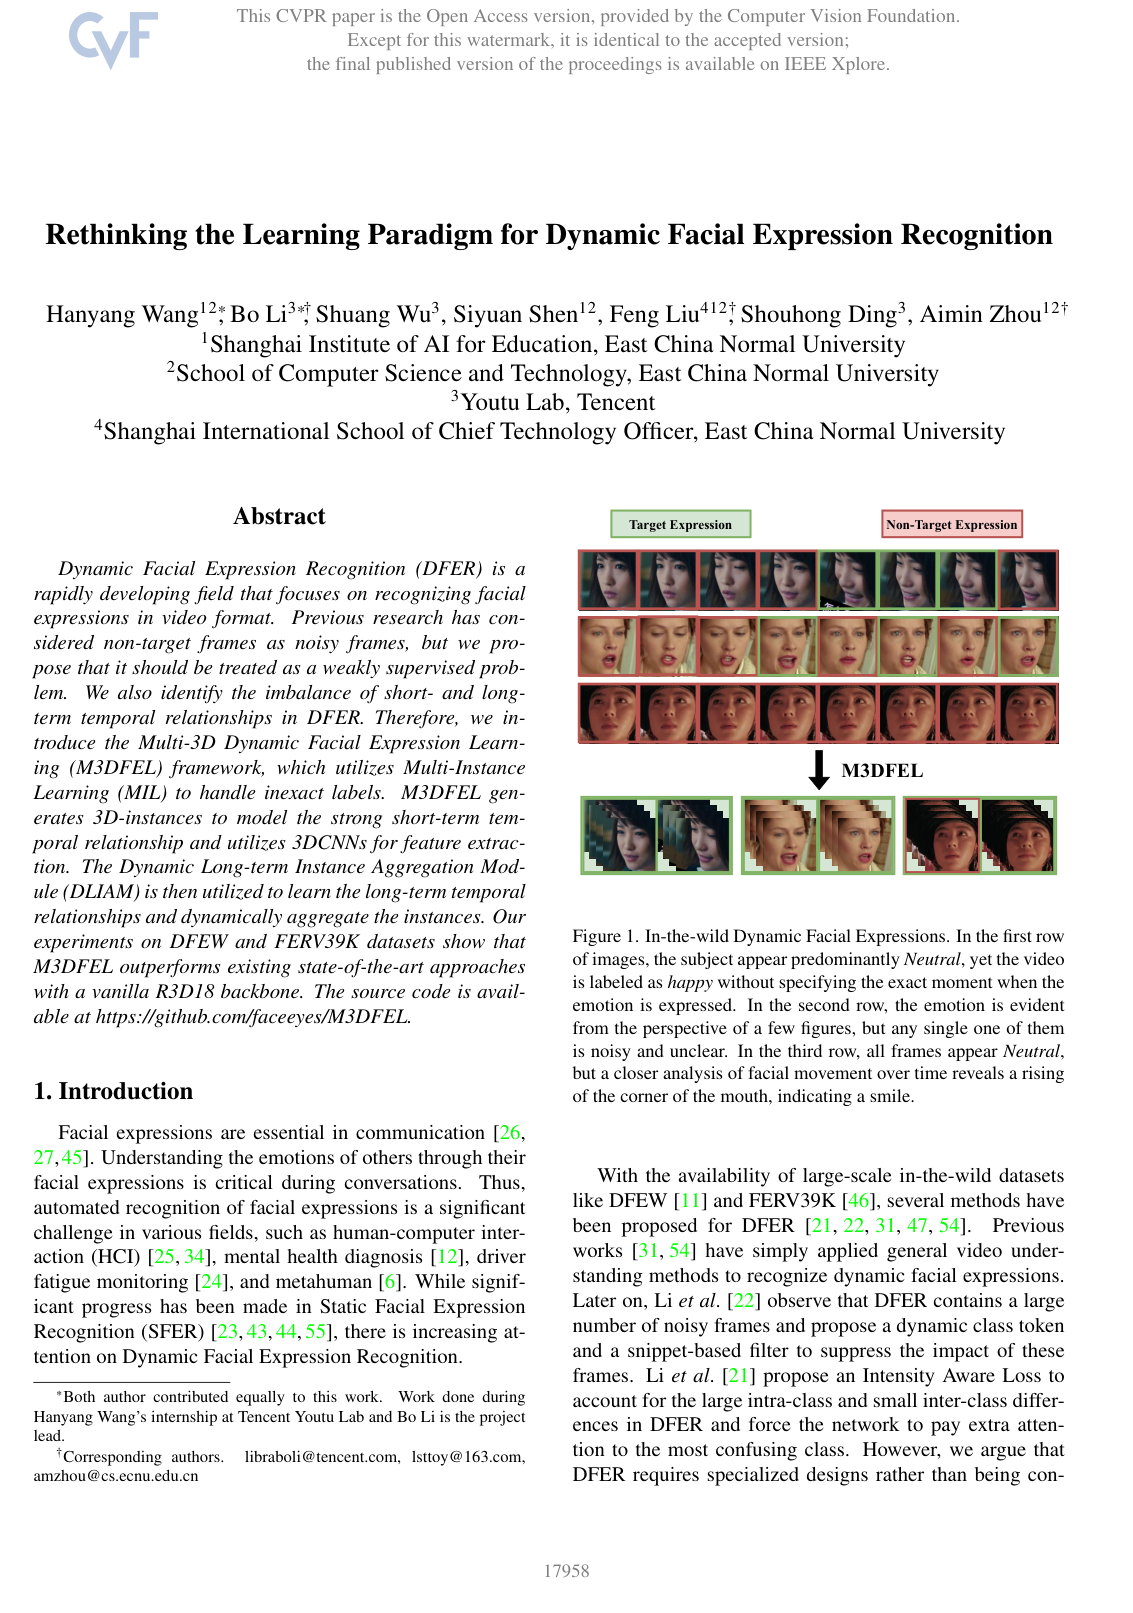
Dynamic Facial Expression Recognition (DFER) is a rapidly developing field that focuses on recognizing facial expressions in video format. Previous research has considered non-target frames as noisy frames, but we propose that it should be treated as a weakly supervised problem. We also identify the imbalance of short- and long-term temporal relationships in DFER. Therefore, we introduce the Multi-3D Dynamic Facial Expression Learning (M3DFEL) framework, which utilizes Multi-Instance Learning (MIL) to handle inexact labels. M3DFEL generates 3D-instances to model the strong short-term temporal relationship and utilizes 3DCNNs for feature extraction. The Dynamic Long-term Instance Aggregation Module (DLIAM) is then utilized to learn the long-term temporal relationships and dynamically aggregate the instances. Our experiments on DFEW and FERV39K datasets show that M3DFEL outperforms existing state-of-the-art approaches with a vanilla R3D18 backbone. The source code is available at https://github.com/faceeyes/M3DFEL.

Added

2026-09-26