
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

semantic-preserving generative warping

Semantic-preserving generative warping is a computer vision framework used in novel view synthesis to generate realistic target viewpoints from a source image while maintaining semantic content and visual fidelity. Rather than relying on a separate pipeline that geometrically warps an image using estimated depth maps and then inpaints missing areas, this technique integrates geometric warping signals directly into a generative model. By leveraging combined attention mechanisms, such as augmented self-attention and cross-view attention, the system learns to differentiate between regions that can be reliably mapped from the source perspective and regions that must be newly synthesized due to occlusions or depth errors. This unified approach prevents the loss of fine structural details and suppresses distortions commonly introduced by imperfect geometry, resulting in consistent and plausible scene generation from new camera angles.

1 item
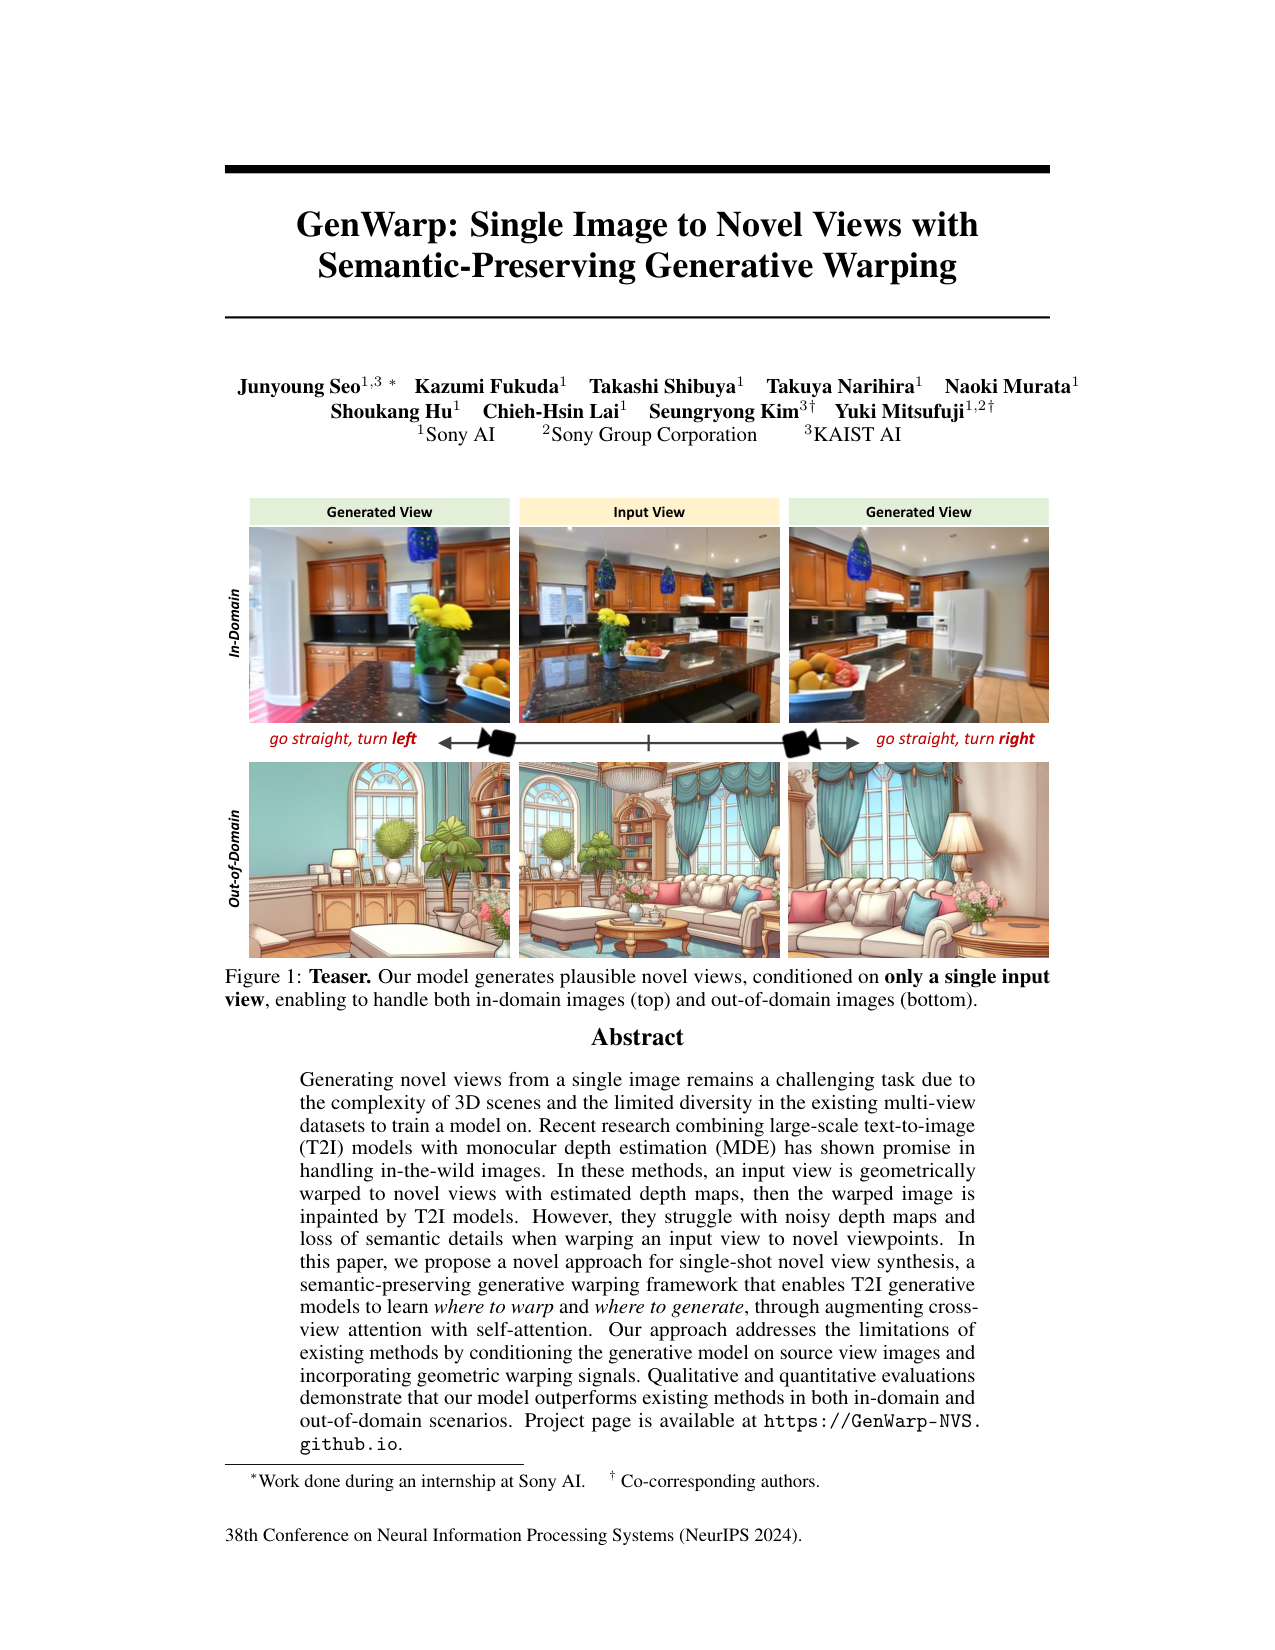
GenWarp: Single Image to Novel Views with Semantic-Preserving Generative Warping

GenWarp: Single Image to Novel Views with Semantic-Preserving Generative Warping

Junyoung Seo, Kazumi Fukuda, Takashi Shibuya, Takuya Narihira, Naoki Murata, Shoukang Hu, Chieh-Hsin Lai, Seungryong Kim, Yuki Mitsufuji

OrganizationsKorea Advanced Institute of Science and TechnologySony Corporation

Why you should read this

Proposes a single-image novel view synthesis framework that unifies geometric warping and occlusion inpainting via cross-view attention mechanisms to prevent visual artifacts caused by noisy monocular depth estimation.

Generating novel views from a single image remains a challenging task due to the complexity of 3D scenes and the limited diversity in the existing multi-view datasets to train a model on. Recent research combining large-scale text-to-image (T2I) models with monocular depth estimation (MDE) has shown promise in handling in-the-wild images. In these methods, an input view is geometrically warped to novel views with estimated depth maps, then the warped image is inpainted by T2I models. However, they struggle with noisy depth maps and loss of semantic details when warping an input view to novel viewpoints. In this paper, we propose a novel approach for single-shot novel view synthesis, a semantic-preserving generative warping framework that enables T2I generative models to learn where to warp and where to generate, through augmenting cross-view attention with self-attention. Our approach addresses the limitations of existing methods by conditioning the generative model on source view images and incorporating geometric warping signals. Qualitative and quantitative evaluations demonstrate that our model outperforms existing methods in both in-domain and out-of-domain scenarios. Project page is available at https://GenWarp-NVS.github.io.

Added

2026-09-26