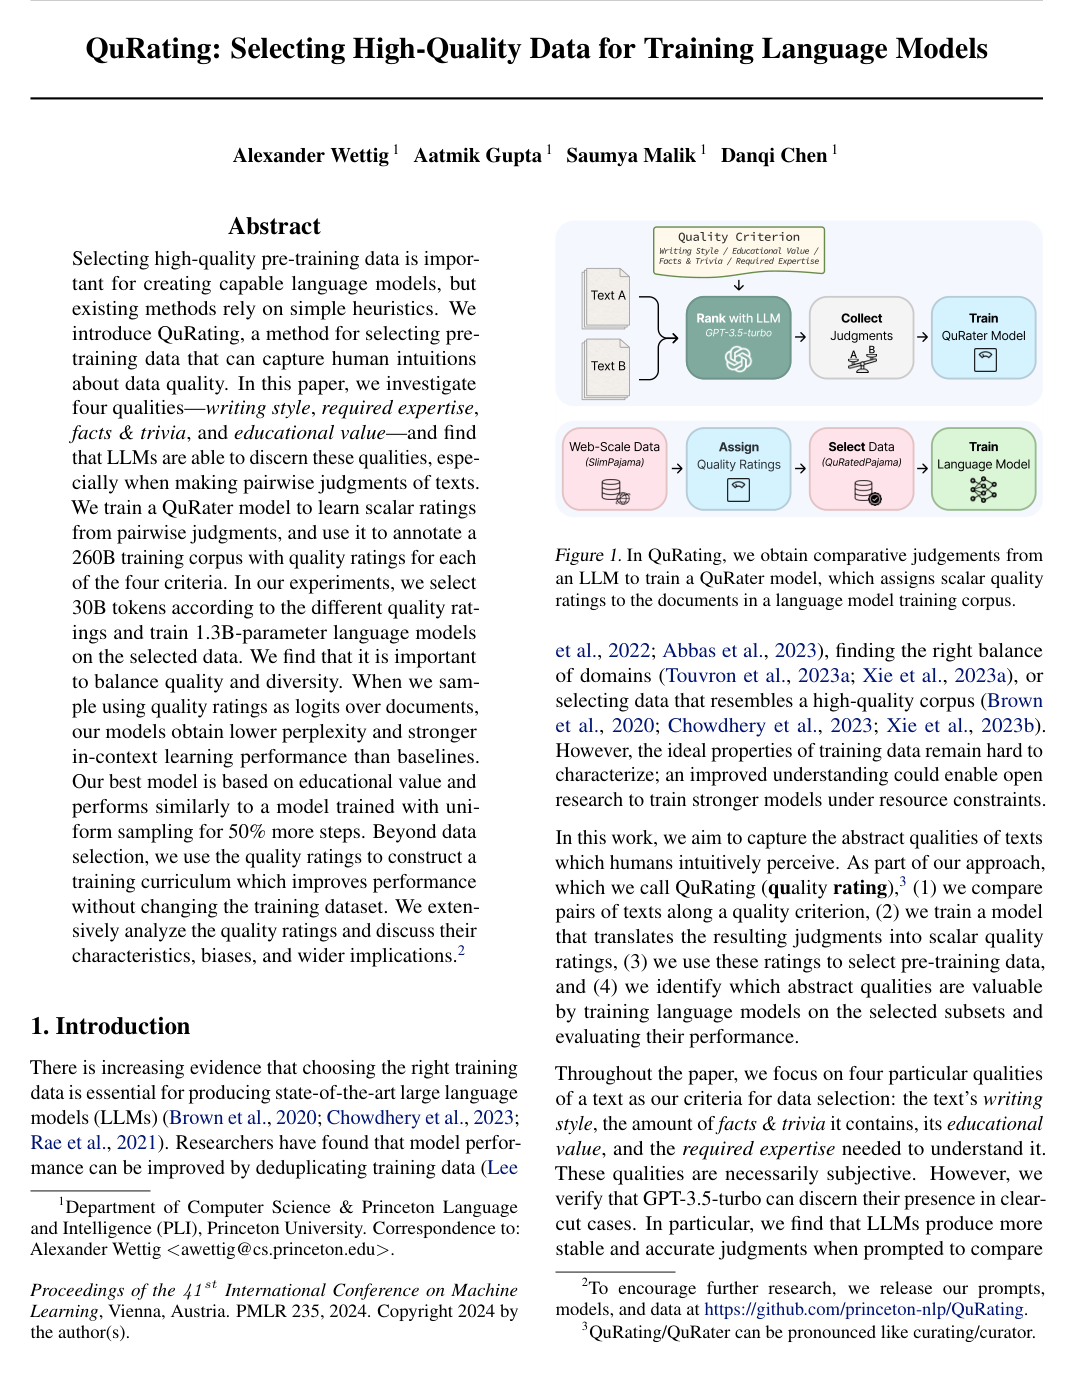
The QuRatedPajama dataset is a large-scale text corpus designed for pre-training language models, consisting of approximately 260 billion tokens annotated with fine-grained quality scores. Derived from the SlimPajama corpus, the dataset provides scalar ratings across four distinct textual criteria: educational value, facts and trivia, writing style, and required expertise. These annotations, generated by a learned quality-rating model trained on pairwise comparisons, enable targeted data selection, balanced sampling, and curriculum learning to improve language model performance and training efficiency.