Built independently by an author, for readers. Read the story and support ChapterPal

keyword

prompt sensitive tasks

Prompt sensitive tasks are natural language processing tasks for which a language model's predictions or performance vary significantly when presented with minor rephrasings, perturbations, or stylistic variations in the input instructions. On such tasks, the model exhibits high output disagreement and uncertainty across semantically equivalent prompts, reflecting fragile or ambiguous comprehension rather than complete mastery or definitive failure. In machine learning paradigms such as active instruction tuning, identifying and prioritizing prompt sensitive tasks allows practitioners to select highly informative training data, helping the model resolve instructional ambiguities, achieve greater robustness to prompt variation, and improve generalizability across unseen tasks with higher data efficiency.

1 item

Active Instruction Tuning: Improving Cross-Task Generalization by Training on Prompt Sensitive Tasks

Active Instruction Tuning: Improving Cross-Task Generalization by Training on Prompt Sensitive Tasks

Po-Nien Kung, Fan Yin, Di Wu, Kai-Wei Chang, Nanyun Peng

OrganizationsUniversity of California, Los Angeles

Why you should read this

Proposes an active instruction tuning framework that quantifies prompt uncertainty to identify and train on the most informative tasks, achieving superior cross-task generalization with substantially fewer training datasets.

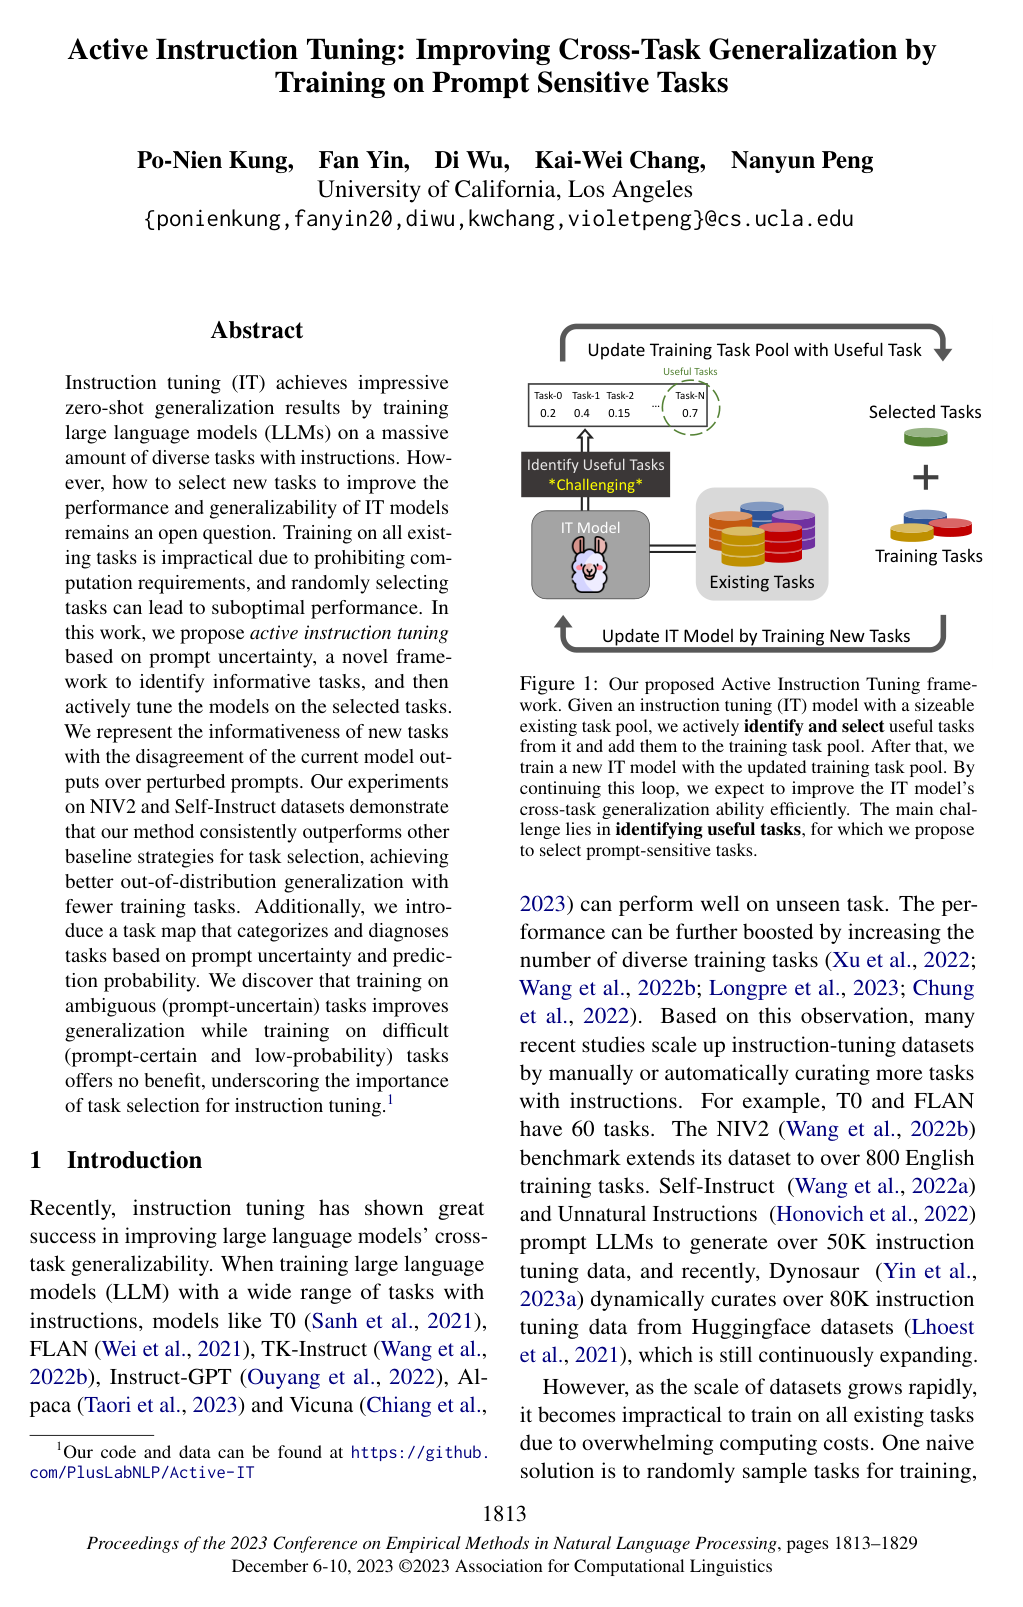
Instruction tuning (IT) achieves impressive zero-shot generalization results by training large language models (LLMs) on a massive amount of diverse tasks with instructions. However, how to select new tasks to improve the performance and generalizability of IT models remains an open question. Training on all existing tasks is impractical due to prohibiting computation requirements, and randomly selecting tasks can lead to suboptimal performance. In this work, we propose active instruction tuning based on prompt uncertainty, a novel framework to identify informative tasks, and then actively tune the models on the selected tasks. We represent the informativeness of new tasks with the disagreement of the current model outputs over perturbed prompts. Our experiments on NIV2 and Self-Instruct datasets demonstrate that our method consistently outperforms other baseline strategies for task selection, achieving better out-of-distribution generalization with fewer training tasks. Additionally, we introduce a task map that categorizes and diagnoses tasks based on prompt uncertainty and prediction probability. We discover that training on ambiguous (prompt-uncertain) tasks improves generalization while training on difficult (prompt-certain and low-probability) tasks offers no benefit, underscoring the importance of task selection for instruction tuning.¹

Added

2026-09-26